Providing Out-of-Band Connectivity to Mission-Critical IT Resources

3 Gaps That Will Leave IT Teams Scrambling

Today’s IT teams must maintain a growing infrastructure of on-prem and cloud solutions. These range from physical routers, out-of-band devices, and firewalls, to Zero Trust Security solutions, micro-segmentation tools, and network automation integrations. Despite an abundance of physical and virtual solutions meant to help keep digital services online, many organizations face an overwhelming number of tasks just to sustain everyday operations. 

With the rising risk of recession, organizations will be forced to cut back on resources including staff, training, and tools. This will only worsen the existing challenges teams face in their efforts to maintain their distributed infrastructure. 

In this blog, we’ll explore three gaps that will leave IT teams scrambling and show you several practical approaches to cope during recession. 

Gap 1: Lack of staff

IT teams have been historically understaffed, and most people can remember at least one significant tech worker hiring campaign from the past decade. Today’s CIOs may in fact be facing the biggest talent gap since 2008. For example, in the cybersecurity sector alone, the 2021 (ISC)2 Cybersecurity Workforce Study reported that despite adding 700,000 cybersecurity professionals to the workforce in 2021, there’s still a gap of more than 2.7 million workers globally, 377,000 of which are needed in the United States. 

Trained staff are a must for managing an organization’s distributed sites, especially as team silos disappear and workers are required to have a breadth of skills. Business leaders increasingly need people who are proficient in networking and programming, so they can maintain normal operations while progressing their digital transformation initiatives such as hyperautomation. It’s a challenge that often comes down to hiring new talent or increasing the skills of existing employees, and both of these approaches require plenty of time and money. 

This issue will only worsen with the coming recession as companies begin to tighten their belts and slash budgets. Major brands have already shed thousands of workers this year, leaving IT teams to make due with existing staff numbers or even reduced headcounts. In the simplest terms, the coming recession will leave companies much less willing or able to invest in staff. 

Gap 2: Lack of tools to reduce workloads

Today’s infrastructure incorporates solutions from many different vendors, but the problem is these often come with their own unique tools that are meant to serve only a specific function. Managing SD-WAN, SASE, ZTNA, orchestration, and out-of-band solutions means jumping between disparate tools, many of which lack integration with one another. This complexity leaves operational teams stuck in a reactionary break/fix posture trying to climb mountains of never-ending support tickets. 

To address this challenge, many Big Tech companies empower their IT teams through digital transformation initiatives, such as using automation to achieve a proactive approach. But this requires additional investments in upskilling staff and acquiring adequate automation infrastructure/tools. For many organizations, a lack of money and resources makes this difficult during normal economic conditions, and will only become exacerbated with the coming recession. IT teams will continue scrambling with their inflated workloads.

Gap 3: Lack of trust in automation

Automation can greatly reduce the risk of human error (and subsequent outages) by handling simple workloads, such as device provisioning and firmware updates. However, companies that do have the resources to implement automation also recognize its limitations. Automation solutions that aren’t optimized leave IT teams with mundane tasks like managing, scheduling, and restarting bots. But to even reach this level of automation requires training staff who typically don’t have a background in programming or development. 

These teams will be unfamiliar with NetOps/DevOps concepts. In order to develop essential automation practices, these employees will need to learn through trial and error. This is a problem because most organizations lack the proper automation infrastructure and tools that allow their IT teams to recover from mistakes. Operational teams in charge of keeping infrastructure running often fear automation for this exact reason — if they make one error, there’s the potential that it will bring down the network, lead to unhappy customers, and cost them their job. 


BlueprintPDF

Close these gaps with the Network Automation Blueprint

You can close these gaps for good using out-of-band, jump boxes, and tools you already have. After years of working directly with tech giants, we’ve created a best practice reference architecture any company can use to automate their network. This Network Automation Blueprint has been proven by global enterprises to increase capabilities and reduce workloads through trustworthy automation.

A Guide to SD-WAN Deployment Models

SD-WAN

Software-defined wide area networking, or SD-WAN, uses software abstraction to create a virtual overlay network that sits on top of the underlying WAN infrastructure. This gives organizations greater control over distributed network architectures and enables a high degree of automation. SD-WAN can be deployed in a hub-and-spoke model or a variety of mesh topologies depending on the organization’s requirements and capabilities.

In this guide are the most common SD-WAN deployment models with diagrams, pros and cons, and best practices to help organizations choose the right topology.

Hub-and-spoke SD-WAN deployment models

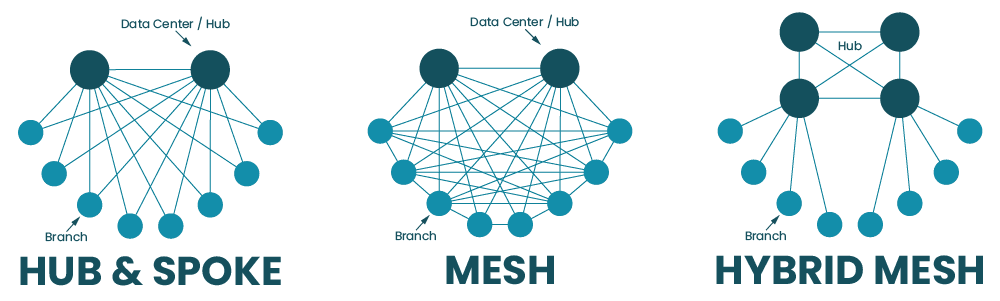
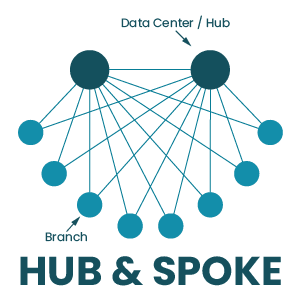
In the hub-and-spoke model, large data centers serve as centralized hubs that all SD-WAN traffic must flow through. The spokes are the campuses, branch offices, and edge sites that connect to each hub in order to access the enterprise WAN.

Hub & Spoke

The hub-and-spoke SD-WAN deployment model can be executed in a couple of different ways:

Spoke-to-hub only

In this SD-WAN deployment model, the spokes for a particular hub are unable to communicate with each other, they can only interact with the central hub. The networking logic for this deployment model is relatively simple compared to the others. It’s also useful when spoke sites need to be isolated from each other for security, privacy, or regulatory reasons.

Spoke-to-spoke via hub

In this deployment, spoke sites can communicate with each other, but all of their traffic must pass through the central hub first. Again, this makes SD-WAN networking logic a little simpler than allowing direct communication between sites. It also allows spoke traffic to pass through a centralized firewall first so that traffic can be inspected and security policies can be applied without needing to deploy firewall appliances at each spoke site.

Hub-and-spoke pros and cons

The hub-and-spoke approach is relatively easy to deploy and manage because all SD-WAN traffic must flow through a limited number of hub data centers. There’s no need to configure, secure, and load-balance network traffic between the numerous spoke sites that comprise an enterprise network, so organizations that are adopting SD-WAN for the first time tend to favor this approach.

However, since all spoke traffic needs to pass through a centralized hub, this creates bottlenecks that can impact network performance for all connected sites. Centralized hubs also represent single points of failure for the spokes that rely on them for enterprise network access – if a hub goes down due to a cybersecurity breach, ISP outage, or equipment failure, then spokes will lose their ability to communicate with each other or access enterprise network resources. Plus, since all traffic and data are aggregated in centralized hubs, they present attractive targets to cybercriminals, who can easily get all the valuable data they want in a single location instead of needing to move around the network.

Hub-and-spoke best practices

If you’re considering the hub-and-spoke approach, it’s important to have a business continuity plan that accounts for hub failures. For example, you should have some sort of network failover option (such as cellular LTE) in case the ISP connection goes down. You should also be able to redirect traffic from one hub to another if the first hub gets overloaded or experiences a failure. In addition, hubs should be deployed with out-of-band (OOB) management so network admins have 24/7 management access even if the SD-WAN connection goes down.

Learn more about Out-of-band (OOB) management.

Mesh SD-WAN deployment models

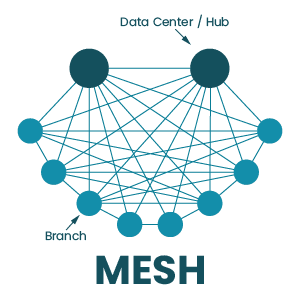
In the mesh deployment model, campuses, branch offices, and edge sites have some ability to communicate with each other directly, without their traffic needing to pass through a hub first. The degree to which sites can interact with each other depends on the type of mesh topology that’s deployed.

Full mesh deployment

In a full mesh deployment, there is any-to-any communication between edge and branch sites using overlay tunnels. There are often still hub data centers to handle requests for centralized enterprise resources, but most other requests are handled by services deployed at the network edge (either at the sites themselves or in the cloud).

Mesh

Full mesh pros and cons

The full mesh topology enables faster communication between sites. It also allows organizations to deploy applications and services at the edge of the network where data is being generated and used, which is known as edge computing. There are also no single points of failure in the full mesh SD-WAN architecture, which reduces the risk of an outage and shortens the duration of outages that do occur. In addition, data and applications are distributed across many different locations, which can limit the damage caused by security breaches – instead of finding all your valuable data in a single server, cybercriminals have to jump around the network, increasing the chances they’ll be caught.

However, the full mesh topology is the most challenging to implement, manage, and optimize because there are so many moving parts involved. Each site needs a full stack of networking and security solutions because they aren’t relying on a centralized hub. Increasing the complexity of the SD-WAN architecture also increases the risk that mistakes will be made during configurations, deployments, and updates.

Partial mesh deployment

In this topology, some spokes can directly communicate with each other, and some services are deployed at the edge. However, there isn’t a full decentralization of applications and security, so some traffic still needs to pass through a hub.

Partial mesh pros and cons

Many organizations arrive at a partial mesh deployment on their journey from a hub-and-spoke deployment to a full mesh. A partial mesh topology reduces some of the load on centralized hubs and firewalls by moving certain services to the edge and allowing some direct site-to-site communications, which can improve performance. The organization can still rely on some centralized security functionality, reducing the number of security appliances or cloud-based services needed to protect the edge.

However, a partial mesh doesn’t completely address the limitations of a more centralized hub-and-spoke deployment. Hubs still represent potential bottlenecks and points of failure in the SD-WAN architecture. Plus, there’s still a lot of data centralization, meaning that storage and data processing servers in hubs will make attractive targets to hackers.

Hybrid mesh deployment

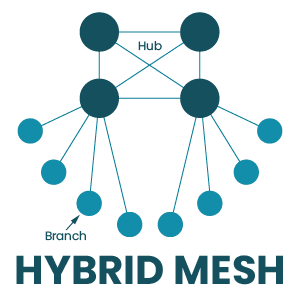
In a hybrid mesh, many hubs are deployed in a mesh topology, which means there is frequent communication and a high level of redundancy. However, branch and edge sites are still deployed as spokes, which means all their traffic goes through the hub mesh.

Hybrid Mesh

Hybrid mesh pros and cons

A hybrid mesh deployment ensures that no single hub acts as a single point of failure, enabling a high degree of redundancy and load balancing. Spoke sites can’t directly interact with each other, which reduces the complexity of the SD-WAN topology and decreases the number of security appliances to purchase and manage. Bottlenecking is also less of an issue because traffic from spokes doesn’t have to pass through a single designated hub, and can instead be distributed across multiple hubs.

However, a hybrid mesh topology is still fairly centralized, so you don’t get all the security and performance benefits of a decentralized full mesh deployment. Hubs are still valuable targets for cybercriminals, edge sites still need to send data to hubs for processing, and spokes cannot access enterprise network resources without going through the hub mesh. If that hub mesh is unavailable for any reason, spoke sites will be completely cut off.

Regional mesh

A regional mesh allows organizations to implement different deployment models for different regions. For instance, one region may have a spoke-to-spoke deployment, while another has a partial mesh. When traffic from one region needs to go to another, it must pass through a regional hub first.

Regional mesh pros and cons

The regional mesh model gives large or highly distributed organizations the flexibility to use deployments that meet the specific requirements of each region. For example, there may be a cluster of branch offices that process classified data for the defense industry, so the organization uses the spoke-to-hub-only deployment to isolate those sites from the rest of the enterprise network. In another region, the org may run a lot of edge computing for machine learning applications and need there to be fast and seamless communication between edge data centers. In that case, they might deploy a full mesh topology in that specific region.

However, this flexibility can also create a lot of management complexity. Admins need to learn, manage, and troubleshoot different configurations, network logic, and security rules for different regions. Plus, each region is subject to the downsides and limitations of whichever deployment model is used there. In addition, regional hubs often still act as potential bottlenecks and points of failure between each region and the enterprise network.

Mesh best practices

All of the best practices for the hub-and-spoke model also apply to mesh SD-WAN deployments. There are a couple of additional considerations for organizations considering a more decentralized deployment, including:

Cloud-delivered security – Mesh deployments typically require security solutions deployed at the edge, so that traffic doesn’t need to pass through a centralized firewall. However, purchasing appliances for each location is expensive and adds to the complexity of the architecture. Solutions like SSE (Security Service Edge) allow you to use your SD-WAN technology to send edge traffic through security services in the cloud. SSE takes many of the capabilities of traditional security appliances and combines them into a cloud-delivered stack, so organizations can get enterprise-level protection without needing to deploy additional hardware or route traffic through a central bottleneck.

Network automation – Manually configuring and controlling a complex mesh network increases the risk of human error. Luckily, SD-WAN’s software abstraction makes it easier to use automated scripts and playbooks to handle a lot of the tedious, repetitive tasks that are prone to mistakes such as device configurations and ACL (access control list) updates. Automation also means that work can get done faster and without putting additional pressure on overworked network teams.

Centralized orchestration – Mesh topologies have so many moving parts, and needing to manage each one of them separately makes it impossible to holistically control, optimize, and secure the deployment. Centralized orchestration gives network teams a common interface they can use to create, organize, deploy, monitor, and troubleshoot automated and manual SD-WAN workflows. That means the orchestrator should be vendor-neutral so it can dig its hooks into every device, application, and service in every SD-WAN site in your deployment.

Vendor neutrality – On that note, vendor neutrality is also a best practice because of how it simplifies and strengthens automation infrastructure. Many vendors lock you into using specific tools, applications, and devices, which makes automation pipelines more complicated and brittle — if one component breaks, the whole infrastructure goes down. Using vendor-neutral tools and orchestration platforms means you don’t have to inflate your toolkit or overcomplicate your automation pipeline, improving resiliency.

Choosing the right SD-WAN deployment model

Every SD-WAN topology comes with its own advantages and limitations, so organizations must assess their requirements and capabilities to determine which one to deploy. For example, if your team doesn’t have any SD-WAN experience, then jumping right into a full mesh deployment may not be practical. If you need your edge sites to have real-time data processing abilities (for example, in healthcare applications), then you may want to consider a less centralized mesh topology.

  Pros Cons
Hub-and-spoke
  • Easy to deploy
  • Reduced management complexity
  • Creates bottlenecks
  • Hubs are single points of failure
  • Centralized data is a target for hackers
Full mesh
  • Enables edge computing
  • No single points of failure
  • Decentralized data limits the blast radius of breaches
  • Complex implementation and management
  • Increases risk of human error
  • Requires edge or cloud-delivered security solutions
Partial mesh
  • Reduces some load on centralized hubs
  • Easier to deploy than a full mesh
  • Enables edge computing
  • Hubs can still create bottlenecks
  • Hubs are still potential points of failure
  • There is still some data centralization
Hybrid mesh
  • Enables a high degree of redundancy among hubs
  • Not as complex as a full mesh
  • Reduces bottlenecks
  • There is still some data centralization
  • There is still some bottlenecking
  • Hub mesh is still a point of failure
Regional mesh
  • Flexible and customizable
  • Addresses specific needs of individual sites and regions
  • Each regional hub is a potential point of failure
  • Variety of topologies creates a lot of management complexity
  • Subject to the downsides and limitations of all the deployment models in use

Ready to learn more about SD-WAN deployment models?

For more guidance on how to choose and implement SD-WAN deployment models, contact the experts at ZPE Systems. Contact Us

How to build a secure isolated recovery environment (SIRE)

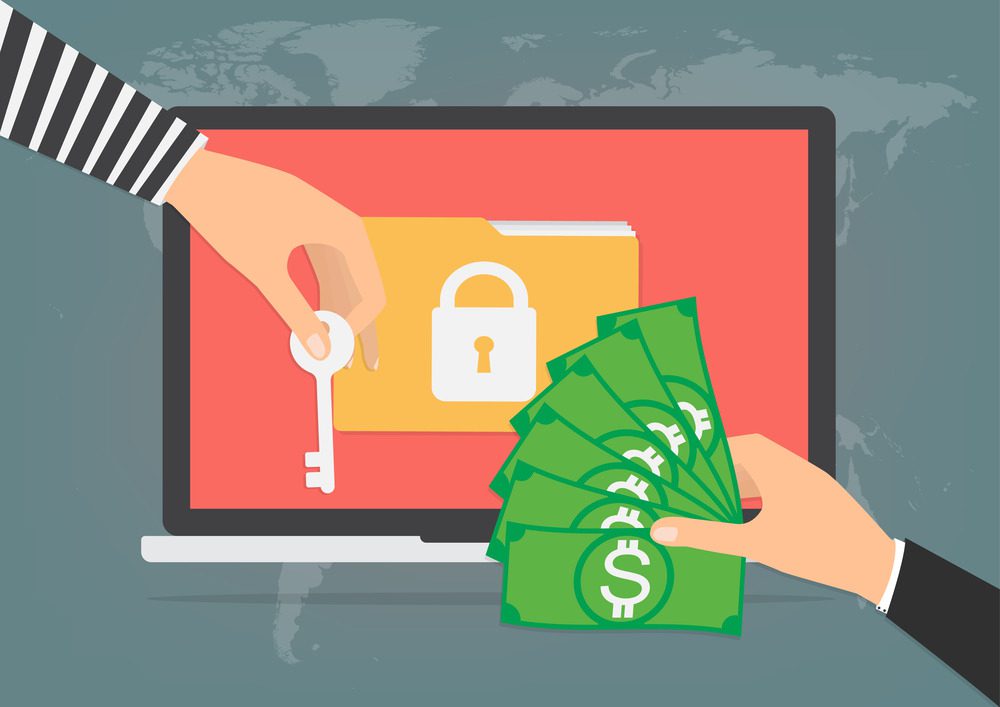
An illustration of someone paying a ransom for their encrypted data, showing what can happen if an organization does not implement an isolated recovery environment (IRE).

Ransomware is one of the biggest cybersecurity threats to enterprises. Sophos reports that in 2024, 59% of organizations suffered a ransomware attack, and the average cost to recover (excluding ransom payment) was $2.73 million. The frequency of ransomware attacks is so high that it’s no longer a question of ‘if,’ but ‘when’ an organization will be hit. Since ransomware encrypts critical data, applications, and systems, an attack can be extremely disruptive to business. During prolonged downtime, revenue slows or stops altogether, recovery costs skyrocket, and the company’s reputation and customers’ trust are severely damaged.

To reduce ransomware recovery times, companies must shift their focus away from prevention and detection and instead invest more time and money into recovery strategies. Ransomware recovery is especially challenging because of how easily its malicious code can spread from production into backup data and systems. What’s needed, according to the experts at Gartner, is a designated, secure isolated recovery environment (SIRE) that’s fully separated from the production infrastructure.

What is a secure isolated recovery environment (SIRE)?

A recovery environment is made up of systems and network resources that are dedicated to recovering from ransomware and other cybersecurity breaches. The recovery environment is where teams work to restore data and rebuild applications before they’re pushed back to the production network.

Many organizations implement a recovery environment by creating an isolated VLAN on the enterprise network. However, if the recovery environment has any dependencies on the production network, there’s a risk that ransomware will cut off access. For example, if malware infects authentication systems, routers, or switches, then admins might lose access to the recovery VLAN. In addition, production dependencies provide a way for ransomware to jump to the recovery environment, reinfecting systems and spoiling recovery efforts.

A secure isolated recovery environment (SIRE) uses a designated network infrastructure that’s completely separate from the production environment. The SIRE uses tools like Retention Lock, role-based access control (RBAC), and out-of-band (OOB) management to ensure that admins can quickly recover critical business services without the risk of reinfection. Let’s discuss these components in greater detail, as well as how to implement them to create an IRE.

How to build a secure isolated recovery environment

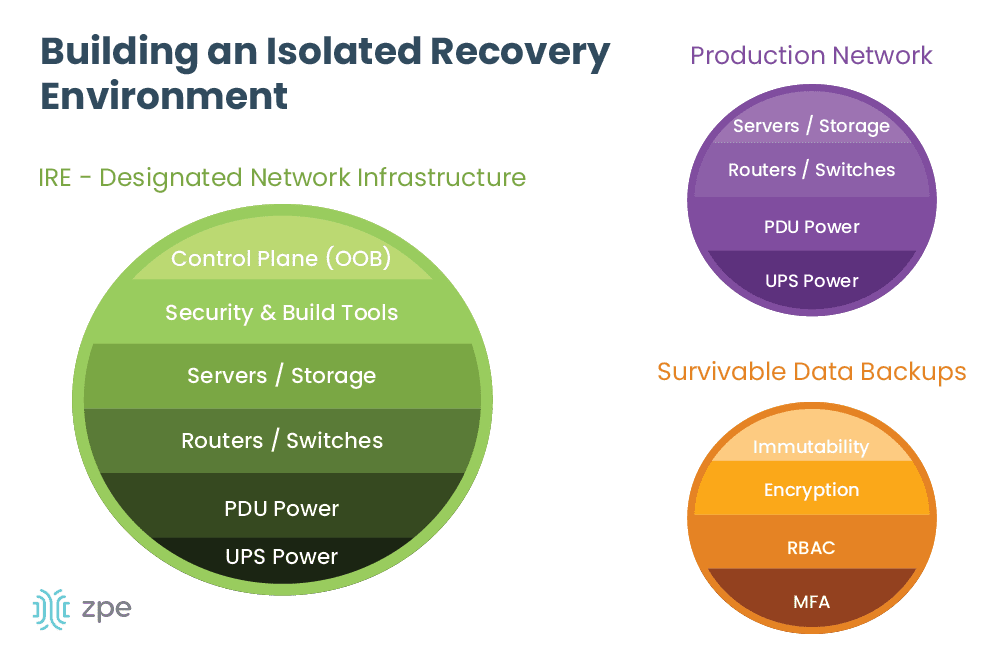
The ideal SIRE is built around three concepts: survivable data, separation and isolation, and designated infrastructure.

build an isolated recovery environment

Survivable data

Ransomware earned its name because it encrypts data and systems and demands a ransom (typically in the form of cryptocurrency) to get the decryption key. However, there’s no guarantee that the attackers will provide a valid decryption key upon receiving their bounty, so it’s best to avoid the cost and risk altogether by ensuring you have clean backup data. These backups are known as survivable data – data that can’t be removed or encrypted by attackers.

To ensure your backup data is survivable, you should implement:

  • Immutability: Something is considered immutable if it can’t be changed in any way, such as immutable infrastructure. Immutable data backups can’t be modified once they’re in place, which makes it impossible for ransomware and other malware to encrypt or corrupt the files. Data immutability can be enforced with tools such as Retention Lock.
  • Encryption: For backup data to be survivable, it must be encrypted both in transit and at rest. This is sort of like fighting fire with fire – if your data is already encrypted, it will be much harder for ransomware to apply its own encryption. Plus, encrypting data in transit makes it harder for attackers to intercept and steal it as it’s moving between your production, backup, and recovery environments.
  • RBAC: Role-based access control, or RBAC, refers to policies that restrict access based on an account’s role or function (e.g., ‘administrators,’ or ‘human resources’). Ideally, only the key personnel involved in recovery operations (their role may be ‘recovery engineers,’ for example) will have access to backup systems, which limits the risk that over-privileged accounts will be compromised and used to exfiltrate data.
  • MFA: Multi-factor authentication, or MFA, forces users to prove their identity in multiple ways before they can access a system or application. For example, an admin may need to provide their username and password, plus a six-digit code sent to their authorized mobile device or email address, to prove that they are who they say they are. If an attacker steals an admin’s username and password, MFA prevents them from being able to access, steal, or encrypt backup systems.

Separation and isolation

Recovery efforts need to take place in an isolated environment so there’s no risk that malware will cross over from the production network. Newly recovered systems, applications, and data also need to be scanned and verified to ensure they’re clean before they’re reintegrated into production. The only way to achieve this is by building a completely isolated environment using a designated network infrastructure.

Designated infrastructure

The SIRE needs to be both physically and logically separated from the production network to ensure there’s a completely clean environment in which to perform system, application, and data restoration. That means the SIRE should have its own routers, switches, storage devices, compute options, and power. In addition, the SIRE needs its own out-of-band (OOB) control plane that’s accessible via a dedicated network interface (such as 4G or 5G cellular). This will ensure that admins have continuous remote access to the SIRE even if the LAN or WAN goes down due to configuration errors or other problems.

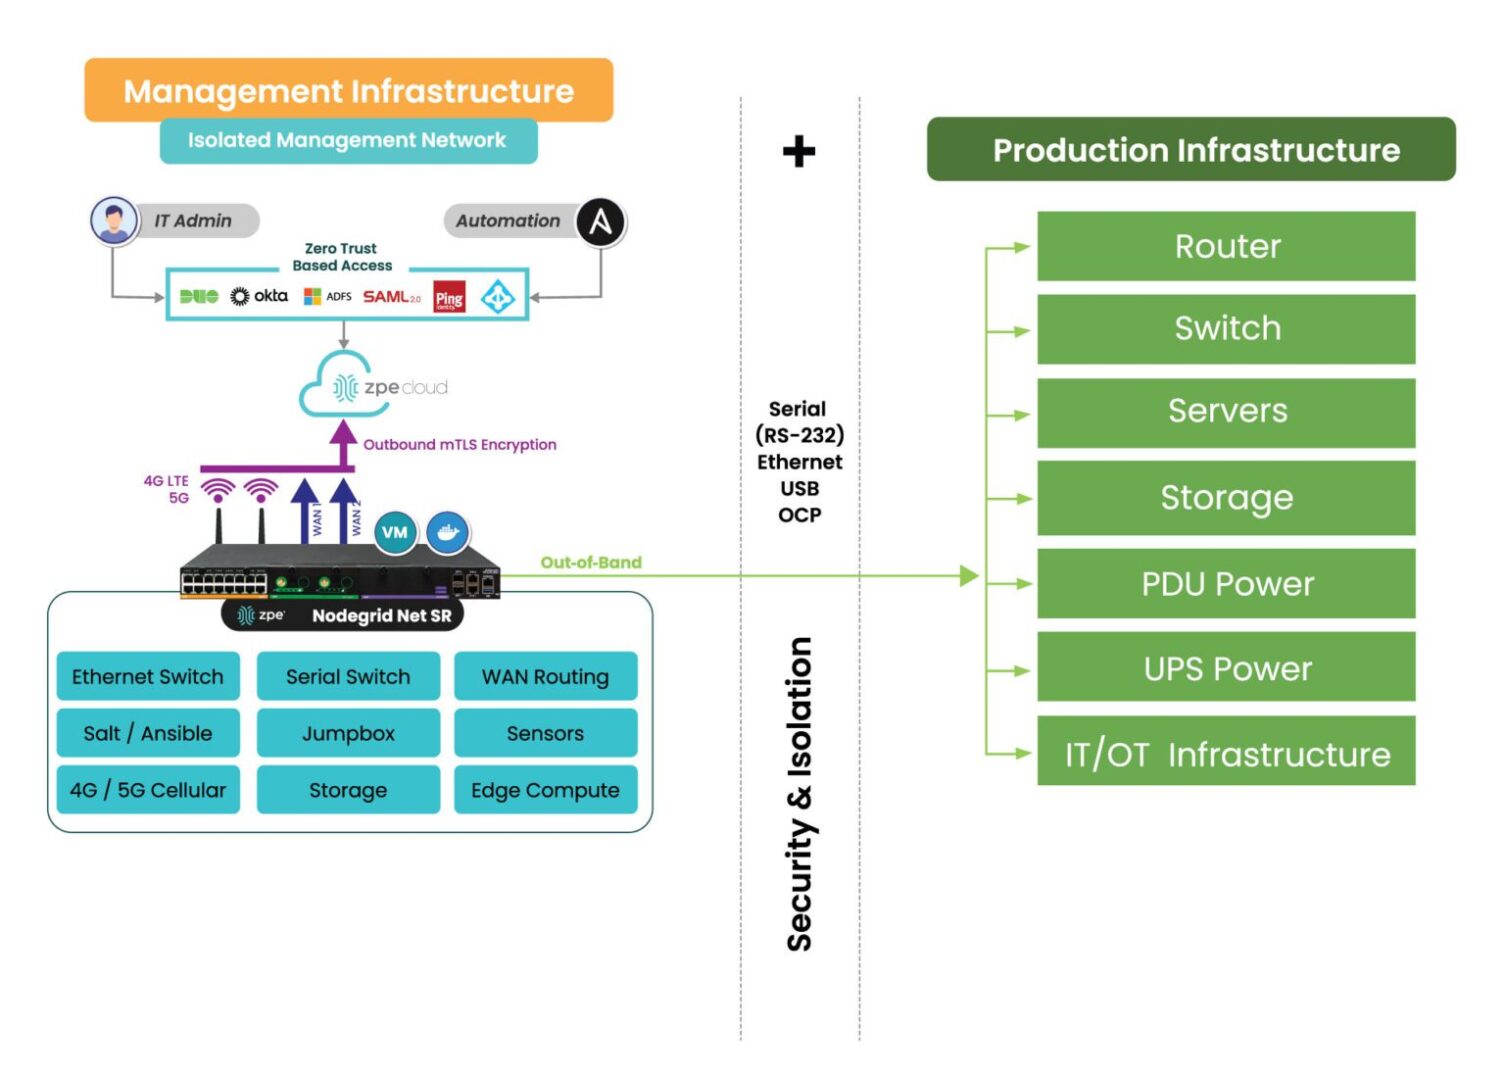
How the Nodegrid Net SR isolates and protects the management network.

Image: Deploying a SIRE is only possible through the use of a dedicated control plane, or Isolated Management Infrastructure shown here.

Teams will also need access to their security and build tools in the SIRE, so these need to be configured and ready to go before an attack occurs. Organizations also must ensure the secure isolated recovery environment has enough storage to handle all of the backup data and server rebuilds.

Additional resources for building a secure isolated recovery environment (SIRE)

A secure isolated recovery environment (SIRE) ensures that admins have a dedicated environment in which to rebuild and restore critical business services during a ransomware attack. Survivable data backups, complete isolation, and designated infrastructure are needed to maintain the integrity of recovery operations and prevent reinfection.

For more information about how to recover from ransomware using a secure isolated recovery environment, download our whitepaper, 3 Steps to Ransomware Recovery.

Implementing and using a SIRE requires Isolated Management Infrastructure. IMI provides the management foundation and is a best practice recommended by CISA, because it fully separates admin access from relying on production infrastructure. Through IMI, teams gain a host of capabilities including out-of-band management and remote access, which not only help with ransomware recovery, but also for break/fix troubleshooting, device monitoring, and outage recovery. The ZPE Systems team created the blueprint that organizations can use to implement this crucial IMI foundation.

To get the blueprint for building Isolated Management Infrastructure, download the Network Automation Blueprint.

Want to see the Secure Isolated Recovery Environment in action?

Our engineers are ready to show you what it takes to recover from ransomware. Click the button to get in touch, and we’ll walk you through IMI, out-of-band, and the Secure Isolated Recovery Environment.

Contact Us

SD-WAN Benefits: Your Definitive Guide

Illustration of a variety of devices connected to a complex enterprise WAN that needs SD-WAN benefits like centralized orchestration and enhanced security.
SD-WAN, or software-defined wide area networking, is on the rise as organizations grow more distributed and networks get more complicated. SD-WAN’s market share was an estimated $3.4 billion in 2022 and is predicted to increase to $13.7 billion by 2027. Orgs leverage SD-WAN to reduce MPLS costs, improve WAN performance, facilitate greater automation and orchestration capabilities, and improve their security posture. This post explains how SD-WAN works in addition to its benefits.

How does SD-WAN work?

SD-WAN uses software abstraction to decouple WAN control functions from the underlying hardware. When possible, it leverages traditional MPLS to handle requests for enterprise resources in the data center, but it can also use less-expensive cellular and public internet links to handle cloud-destined traffic. SD-WAN uses virtualized and cloud-based security technologies to securely connect remote sites to SaaS, web, and cloud resources, reducing MPLS bandwidth and eliminating the need for VPNs.

SDWan Gateway
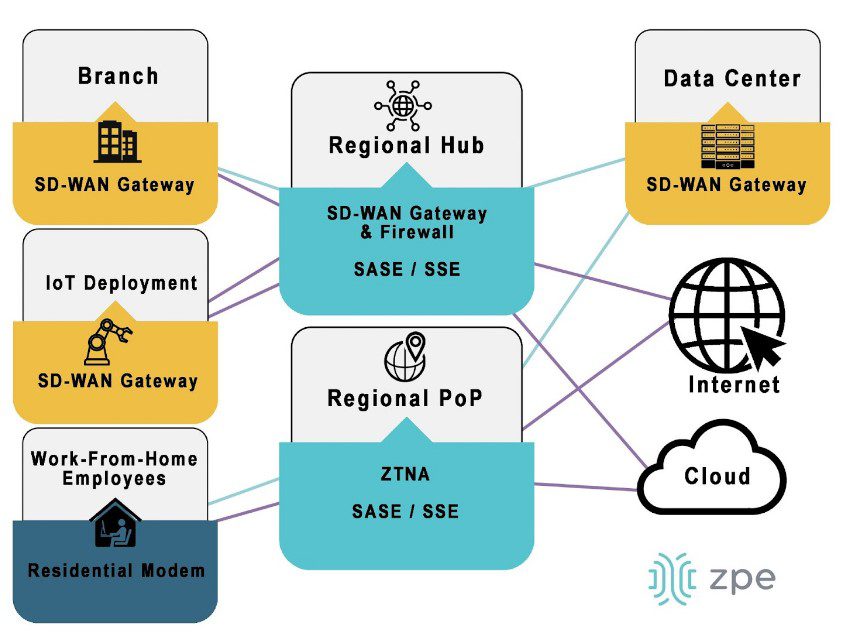
Organizations install SD-WAN gateways at campuses, branches, data centers, and any other business locations accessing the WAN architecture. These gateways virtualize WAN management at their sites, giving admins control via centralized software (which is often cloud-based).

Regional points-of-presence (PoPs) act as SD-WAN gateways for employees working from home, giving them access to enterprise network resources without a VPN. Often, major SD-WAN providers have an existing network of regional PoPs to take advantage of, but large or especially geographically diverse organizations may also wish to deploy their own PoPs in specific areas.

There are several different SD-WAN deployment architectures for companies to choose from depending on their specific requirements and capabilities. Learn more in A Guide to SD-WAN Deployment Models.

SD-WAN benefits guide

SD-WAN benefits organizations with complex and highly-distributed networks in the following ways:

SD-WAN Benefits

Reduces costs

  • MPLS bandwidth reduction
  • Fewer circuit installations
  • Faster branch deployments

Improves performance

  • Fewer data center bottlenecks
  • Faster issue response
  • Holistic performance monitoring

Enables automation & orchestration

  • Automated configurations
  • Policy-based workflow automation
  • Centralized orchestration

Enhances branch security capabilities

  • On-ramp to SSE technology
  • Enterprise policy extension
  • Secure access for remote users

SD-WAN reduces costs

MPLS bandwidth is far more expensive than standard broadband, fiber, or cellular, often hundreds of dollars per megabit per month. For branches with existing MPLS circuits installed, SD-WAN reduces bandwidth costs by redirecting traffic that’s destined for the cloud or internet across less-expensive channels, reserving the MPLS for enterprise traffic alone.

For some branch networking use cases, such as IoT (internet of things) deployments relying entirely on cloud-based software and data processing, organizations may opt to forgo a new MPLS installation and rely solely on SD-WAN and cloud-based security solutions. Not only does this save money on installation costs and bandwidth, but it significantly reduces the time it takes to spin up a new branch, enabling that branch to generate revenue sooner.

SD-WAN improves performance

SD-WAN uses technologies like application awareness and guaranteed minimum bandwidth to provide efficient, intelligent routing for improved performance. For example, in organizations with SASE (secure access service edge) deployments, SD-WAN automatically separates cloud- and SaaS-destined traffic to flow through the cloud-based SASE stack instead of the central firewall. This reduces the load on the firewall and ensures improved performance for users who do need to access enterprise resources, while at the same time providing a “shortcut” for remote users trying to reach the cloud.

SD-WAN also responds to availability and performance issues much faster than human admins are capable of, automatically redirecting traffic to avoid bottlenecks or downed nodes to ensure a seamless end-user experience. In addition, SD-WAN’s software abstraction makes it easier to centralize WAN management, giving admins full visibility into every part of the WAN architecture for holistic performance monitoring.

SD-WAN enables automation & orchestration

SD-WAN’s software abstraction opens up many automation opportunities because WAN configurations and workflows are no longer tied to the underlying hardware. For example, device, system, and service configurations can be written as scripts or playbooks and deployed automatically to reduce the time and effort required to spin up a new branch. Policy-based automation can handle additional tasks such as load balancing and failover, and route automation faster and more efficiently than human beings can.

SD-WAN also makes it possible to bring the WAN under one management platform for holistic monitoring and centralized orchestration. This gives admins control over large, distributed, and complex WAN architectures. For example, a centralized SD-WAN platform makes it easier to orchestrate traffic across hybrid cloud architectures because admins can monitor and manage WAN workflows across their various branches, private clouds, and public clouds.

SD-WAN automation and orchestration reduce the number of tedious, manual workflows that fall on overworked networking teams. This helps to decrease the rate of human error in device and security configurations, which in turn decreases the risk that mistakes will cause outages or be exploited by cybercriminals. Centralized SD-WAN orchestration also helps organizations improve their security posture by providing more holistic visibility into things like patch statuses, system changes, and traffic patterns.

SD-WAN enhances branch security capabilities

Another way SD-WAN improves network security is by making it easier to enforce security policies at branches and edge sites without deploying additional hardware or backhauling traffic through a central firewall. Since the SD-WAN control plane is decoupled from the underlying WAN hardware, organizations can also deploy advanced security technologies with fewer device compatibility issues.

SD-WAN enables organizations to use cloud-based security solutions like SSE (security service edge). SD-WAN’s intelligent, application-aware routing can automatically separate traffic from branches and other remote sites based on whether it’s destined for enterprise data center resources or resources that live in the cloud. Cloud-destined traffic is then diverted through the SSE stack, bypassing the main firewall and reducing bottlenecks at the data center.

SSE’s security stack typically includes Firewall-as-a-Service (FWaaS) technology which provides the same (or better) capabilities as a hardware appliance. SSE is also used to extend enterprise security and access control policies to traffic between remote sites and the cloud.

In addition, the SSE stack supports Zero Trust Network Access (ZTNA), which provides secure remote access to enterprise and cloud resources to WFH employees and other systems outside the WAN. In this way, ZTNA is similar to a VPN, only more secure. ZTNA only lets remote users see and interact with one specific resource at a time, and makes them re-authenticate if they wish to access something else. If a remote user account is compromised, this re-authentication step increases the chances that unusual behavior or failed multi-factor authentication (MFA) attempts will trigger an account lock, decreasing the blast radius of an attack.

When SD-WAN and SSE are married together under a single orchestration platform, the result is SASE (secure access service edge). Organizations can purchase a complete SASE solution, or use a vendor-neutral platform to combine the SD-WAN and SSE solutions of their choice for greater customization.

Learn more about SD-WAN benefits

SD-WAN helps organizations reduce MPLS-related costs, improve WAN performance, enable greater automation and orchestration capabilities, and improve overall network security. Learn more about SD-WAN from the branch networking experts at ZPE Systems.

SD-WAN Learning center

Ready to learn more about SD-WAN benefits?

To see how a vendor-neutral orchestration platform simplifies branch management and accelerates SD-WAN benefits, request a free demo of the Nodegrid solution from ZPE Systems.

Contact Us

Simplifying Retail Network Management

Retail network management is visualized with interconnecting icons of networked retail services displayed in front of a retail warehouse

Fast and reliable networks are critical to the success of retail operations. Without network access, stores can’t process payments, handle customer data, or update inventory, which makes outages highly disruptive. According to a recent study, downtime could cost over $300,000 per hour in lost business, which is why it’s crucial that admins have the necessary tools to effectively monitor, manage, and optimize retail networks. This blog discusses some of the specific challenges involved in retail network management and how the right edge gateway solution can help overcome these difficulties.

Retail network management challenges

Managing a retail network comes with unique challenges, especially as the size and geographical distribution of the organization grows. Examples of these challenges include:

  1. Extending fast, reliable connectivity to the entire store for payment processing machines, inventory scanners, and other crucial devices. This is especially challenging in big box stores and other locations with large footprints as well as service-based chains with mechanics’ bays, drive-thrus, and other outdoor or semi-outdoor devices.
    .
  2. Maintaining optimal environmental conditions for networking equipment that’s often installed in closets, storage rooms, warehouses, and other out-of-the-way locations. The priority is typically to keep these devices hidden from customers, so they’re kept in areas that may not be climate controlled and may not have staff physically checking them every day. This increases the risk of environmental issues (like heat and humidity) causing a device failure and means no one is likely to notice the issue until it’s too late.
    .
  3. Remotely troubleshooting and recovering from issues without any on-site technicians. If the ISP connection, WAN, or LAN go down, there’s often no way to remotely access on-site equipment to diagnose and fix the problem. That means network outages require truck rolls to solve, with stores losing money waiting for technicians to travel on-site.
    .
  4. Efficiently monitoring and managing a distributed retail network architecture made up of many different network solutions and platforms. The lack of centralized management increases the risk of human error and makes it difficult to preemptively address potential problems or optimize the speed and performance of the network.

Retail network management teams need a robust solution that addresses these particular challenges. For example, they need small and powerful network devices that use centralized management to reduce management complexity. They also need a way to monitor environmental conditions and recover from outages without having to be on-site.

Simplifying retail network management

Now, let’s discuss how a robust branch gateway solution can help organizations address these challenges.

Compact, all-in-one networking

The layout of a retail store is carefully planned to ensure an optimal experience for customers, which means networking devices need to be as unobtrusive as possible. The ideal branch gateway for retail is compact and combines multiple networking functions, reducing the number of devices that need to be installed. Retail notoriously operates on a small profit margin, so the branch gateway also needs to be affordable without sacrificing performance.

Environmental monitoring

Environmental monitoring sensors collect data on conditions like temperature, humidity, and air quality in the location where networking equipment is installed. These sensors typically connect to the retail branch gateway via USB and report back to the management platform, giving admins the ability to remotely monitor the environment. This is crucial when most retail networks are managed by admins in a centralized office which may be hundreds or thousands of miles away from the stores themselves. Environmental monitoring allows them to identify and resolve potential problems before they cause device failures and outages. For example, if environmental sensors detect high temperatures, admins can get on-site personnel to turn up the air conditioning or call in an HVAC repair before devices overheat and bring down the network.

Out-of-band (OOB) management

Out-of-band (OOB) management uses redundant network interfaces (often cellular) to provide an alternative path to remote infrastructure. A branch gateway with OOB allows admins to remotely connect to devices in the store without relying on an IP address from the LAN, which means they’ll always have access even if the production network goes down. Without OOB management, the retail location goes offline for hours or even days waiting for a technician to arrive on-site, diagnose, and repair the issue. With OOB, admins can remotely access the infrastructure to restore services, often so fast that customers don’t even notice. That means they can remotely recover from more outages without truck rolls, saving time and money.

Vendor-neutral orchestration

A vendor-neutral branch gateway can interface with all the other devices in a retail network infrastructure, even if they’re from a different vendor’s ecosystem. This gives admins a single platform from which to monitor and manage every device in the store. Even better is when all of the branch gateways in the entire retail network architecture hook into a single, centralized, cloud-based orchestration platform. Admins can then monitor, control, and optimize network infrastructure for all the retail locations from one place for ultimate efficiency.

In addition, a vendor-neutral retail network management platform enables the use of third-party automation solutions. Automation reduces the risk of human error and makes it easier for teams to effectively manage and optimize even complex retail network architectures.

Retail network management with Nodegrid

Compact, all-in-one branch gateways like Nodegrid use environmental monitoring, OOB management, and vendor-neutral platforms to simplify retail network management. The Nodegrid Mini SR, for example, is an inexpensive retail branch gateway that’s roughly the size of an iPhone, so you can easily deploy them anywhere in your store without disrupting the customer experience. Despite its small size and low price point, the MSR still delivers Gen 3 OOB management capabilities while supporting Nodegrid environmental monitoring sensors and third-party automation. The Nodegrid platform is also completely vendor-neutral, giving retail network admins a single pane of glass from which to monitor, orchestrate, and optimize the entire distributed network architecture.

Ready to learn more about Nodegrid?

To learn more about about simplifying retail network management with Nodegrid, click here to download the Mini SR datasheet, or contact ZPE Systems today.

Contact Us

Network Automation Tools To Offset the Tech Talent Shortage

network automation tools
As enterprise networks grow more complex, there’s a rising need for highly-specialized engineers to implement and maintain these complicated architectures. However, due to the Covid-19 pandemic, a global recession, and other world events beyond an organization’s control, it can be very difficult to recruit and retain these specialists. In fact, many companies are currently relying on smaller IT teams than usual to manage their vital network infrastructure. According to Gartner research, the tech talent shortage is one of the biggest barriers to the adoption of emerging technology like network automation.

However, network automation tools can actually help understaffed organizations ensure the continued availability and performance of enterprise networks by streamlining workflows and reducing manual intervention. In this blog, we’ll discuss how four different types of network automation tools can be used to solve major problems caused by the tech talent shortage.

Problem Solution
You lack the staff required to efficiently deploy, monitor, and manage network configurations. Automated network configuration management solutions like SolarWinds Network Configuration Manager (NCM) and Micro Focus Network Automation Software.
You need to extend DevOps automation to networking without purchasing additional solutions or hiring network automation experts. DevOps configuration management solutions that can be used for server and network automation like RedHat Ansible and Puppet.
You want to improve network reliability and performance while reducing management complexity. Software-defined networking (SDN) and software-defined wide area networking (SD-WAN) solutions like Palo Alto Prisma and Cisco Meraki.
You lack full-coverage network security, so you’re unsure where your vulnerabilities are or how efficiently you can respond to incidents. Network security automation solutions like Palo Alto’s Next-Generation Firewall (NGFW) and Datadog AIOps security and monitoring.


To learn more about using automation technology to ensure network resilience, click here to download the Network Automation Blueprint from ZPE Systems.


Network automation tools to offset the tech talent shortage

The following categories of network automation tools are designed to simplify network management workflows to ensure optimal performance and 24/7 availability.

Automated network configuration management

Network configuration management refers to the ongoing process of creating, deploying, and maintaining configurations for network devices and logic. Some of the tasks involved in network configuration management include device discovery, provisioning, and software and firmware updates. In addition, network configurations are monitored to ensure they don’t drift away from documented standards (configuration shift), and if needed, unauthorized changes are rolled back. This reduces the risk that an undocumented configuration tweak will introduce an unnoticed security vulnerability (such as the recent Fortinet authentication bypass exploit) and ensures consistent quality across the entire network architecture.

However, manual network configuration management is complicated and time-consuming, especially when so many network operations teams are overworked and understaffed. An automated network configuration management solution handles many of these tasks without the need for human intervention. Admins can create network configuration policies and playbooks which are used to automatically deploy new devices and update network dependencies, saving time and reducing human error. In addition, automated configuration management uses these policies to continuously monitor for and correct configuration drift. In the case of the Fortinet CVE, for example, automatic configuration management could have helped teams instantly roll back to the last known good config to close the vulnerability.

Examples of network automation tools for network configuration management include SolarWinds Network Configuration Manager and Micro Focus Network Automation.

DevOps IaC configuration management

Many organizations have adopted the DevOps methodology, which seeks to dissolve the barriers between the software development and IT operations teams to improve efficiency. On the Ops side, this often involves a practice called IaC, or Infrastructure as Code. IaC uses software code and machine-readable definition files to automatically provision servers and manage configurations. IaC enables Ops teams to spin up resources at the velocity required for fast-paced DevOps software projects. It also means that infrastructure configuration code can be stored, managed, and deployed from the same platform as software code, facilitating easy collaboration between developers and sysadmins.

With the recession forcing many IT teams to downsize, organizations are looking for ways to extend the efficiency provided by DevOps automation tools to the networking side of the house without purchasing additional solutions. Plus, many network admins lack the expertise required to operate network automation solutions, and the tech talent shortage makes recruiting such specialized engineers difficult. Luckily, some IaC configuration management tools like RedHat Ansible and Puppet can also be used for network configurations, which helps teams automate without any special programming skills.

That also means admins can deploy, monitor, and manage configurations for network devices and systems across the entire architecture from a single platform, saving money and reducing operational complexity. This convergence of DevOps and network management is known as NetDevOps or NetOps, and it’s empowering organizations to improve efficiency even during the recession and talent shortage.

Software-defined networking and SD-WAN

Enterprise networks are typically highly distributed and very complex. An organization could have 500 branch offices around the world, each of which uses slightly different networking hardware and software solutions. Each of these vendor solutions might have its own management platform for admins to configure, manage, and continuously monitor. Things grow more challenging when an organization uses a hybrid cloud infrastructure, which requires WAN (wide area networking) orchestration across multiple public and private clouds. This complexity makes it challenging for overworked network administrators to maintain optimal performance and 24/7 availability.

Software-defined networking (SDN) and software-defined wide area networking (SD-WAN) help to reduce the complexity of enterprise networks by abstracting network configurations and workflows as software code that’s decoupled from the underlying hardware. Codifying network configurations makes it easier to use technology like automated configuration management, which reduces the burden on overworked admins and reduces human error. SDN and SD-WAN also facilitate the use of centralized network orchestration platforms, which give admins a single pane of glass from which to control the entire network architecture.

This holistic coverage makes it possible for small teams to efficiently monitor and manage large, complex networks, reducing the risk of fatigue, human error, or negligence affecting performance. Plus, SDN and SD-WAN solutions employ automation to continuously monitor and adjust routing configurations as needed to ensure optimal performance. That means these solutions are often able to detect and remediate issues with latency and site availability much faster than a human admin could, ensuring optimal performance and reliability.

Examples of SDN and SD-WAN solutions include Cisco Meraki SDN and Palo Alto Prisma SD-WAN.

Network security automation

With the quantity, sophistication, and cost of cybersecurity attacks rising every year, network security is more important than ever. According to the Sophos State of Ransomware 2022 survey, 66% of organizations were hit by ransomware, a massive increase from 2020 in which only 37% of organizations were attacked.

However, the tech talent shortage and ongoing recession have left many organizations with gaps that increase both the risk that a breach will occur and the time it will take to recover. For example, IBM estimated in 2021 that unpatched vulnerabilities accounted for at least one-third of all data breaches. However, staying on top of patch management for large, diverse, and distributed network infrastructures is difficult when teams are overworked and understaffed.

Plus, when networking and security teams are spread so thin, it can take them much longer to detect a breach that has already occurred, even if the hacker is actively exfiltrating data or changing system configurations. Remediation is also slowed down by the need to manually investigate logs, isolate affected systems, and implement fixes.

Network security automation can help bridge these gaps by reducing the need for human analysts to perform the more tedious and repetitive – but highly vital – tasks involved in ongoing cybersecurity management. Automated security solutions use technology like AIOps and machine learning to manage software and firmware updates, analyze network traffic for threats, and even perform remediation steps like quarantining infected systems and blocking compromised accounts.

Popular examples of network security automation tools include Palo Alto Network’s Next Generation Firewall (NGFW) and Datadog AIOps Security and Monitoring.

Using a vendor-neutral platform to deploy network automation tools

The goal of automation is to make it easier for network admins to maintain and optimize the enterprise network. However, if admins need to learn, configure, deploy, and manage a bunch of additional automation solutions, you could end up increasing the complexity of their jobs rather than reducing it.

The Nodegrid platform can help by directly hosting all of the network automation tools listed above, reducing the need for additional hardware to manage. Deploying Nodegrid boxes in all your data centers and remote sites gives you the ability to extend automation to every corner of your network and manage it all from behind a single pane of glass. Hosting your network automation on a vendor-neutral platform like Nodegrid gives your team an easy way to orchestrate automated workflows across your entire enterprise architecture.

Network automation tools help to bridge the gaps caused by the tech talent shortage, ensuring the reliability and resilience of enterprise networks. To get step-by-step instructions for how to implement the network automation solutions mentioned above, click here to download the Network Automation Blueprint from ZPE Systems.

Ready to learn more?

To learn more about deploying network automation tools with Nodegrid, contact ZPE Systems today.

Contact Us