The WAN Is the Single Point of Failure Nobody Talks About
Modern IT infrastructure depends on the wide area network (WAN) to connect everything together. Data centers, branch offices, cloud environments, edge locations, and remote sites all rely on WAN connectivity to exchange data, run applications, and maintain centralized operations.
But the WAN also provides the connectivity required to operate the infrastructure itself (think device troubleshooting, config updates, etc.). This creates a problem: when the WAN fails, organizations lose their production services and their ability to manage the infrastructure responsible for restoring them. It’s like walking a tightrope without having a safety net below.
If your remote management capabilities depend on your production network, the WAN can easily become a single point of failure that’ll leave you battling long outages.
What is the WAN?
Unlike a local area network (LAN), which connects devices within a location, the wide area network is the connectivity layer that links geographically distributed networks and infrastructure across cities, regions, or countries. This includes everything from data centers and corporate HQs, to industrial sites, edge kiosks, and remote infrastructure.
Common WAN link types include MPLS, dedicated circuits, broadband, SD-WAN, and Internet connections.
The WAN is the connective tissue between distributed infrastructure. But its importance goes beyond just moving application traffic. That’s because it touches all three network planes.
The WAN Touches Every Network Plane
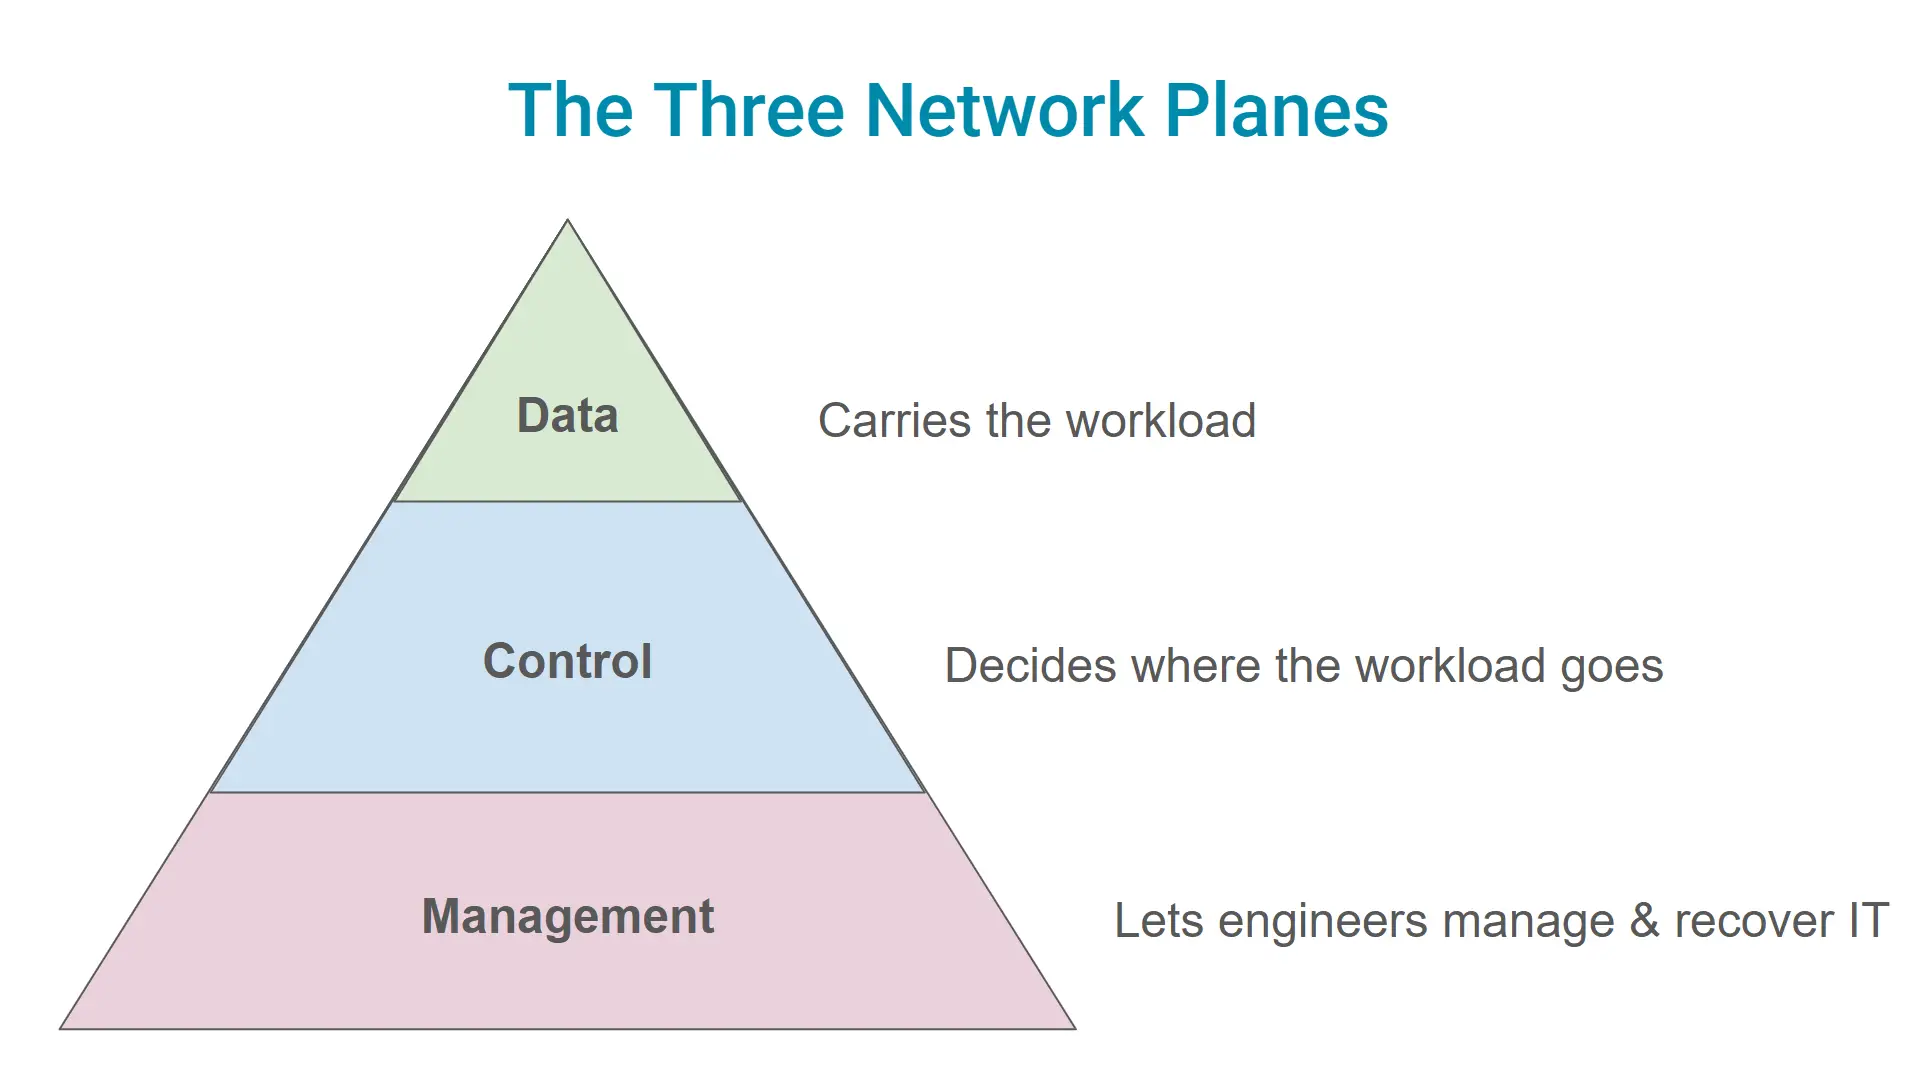
Modern networks have three primary planes that each serve a different purpose. We broke these down in a previous article, but here are the basics:
- Production/data plane: Carries the traffic (app workloads, voice, video, etc.)
- Control plane: Determines how traffic moves (think BGP, OSPF, VXLAN, EVPN)
- Management plane: How engineers access, troubleshoot, configure, and monitor infrastructure
The management plane is especially important when it comes to the WAN and the production network. That’s because this plane is vulnerable in traditional network architectures.
How The WAN Becomes a Single Point of Failure
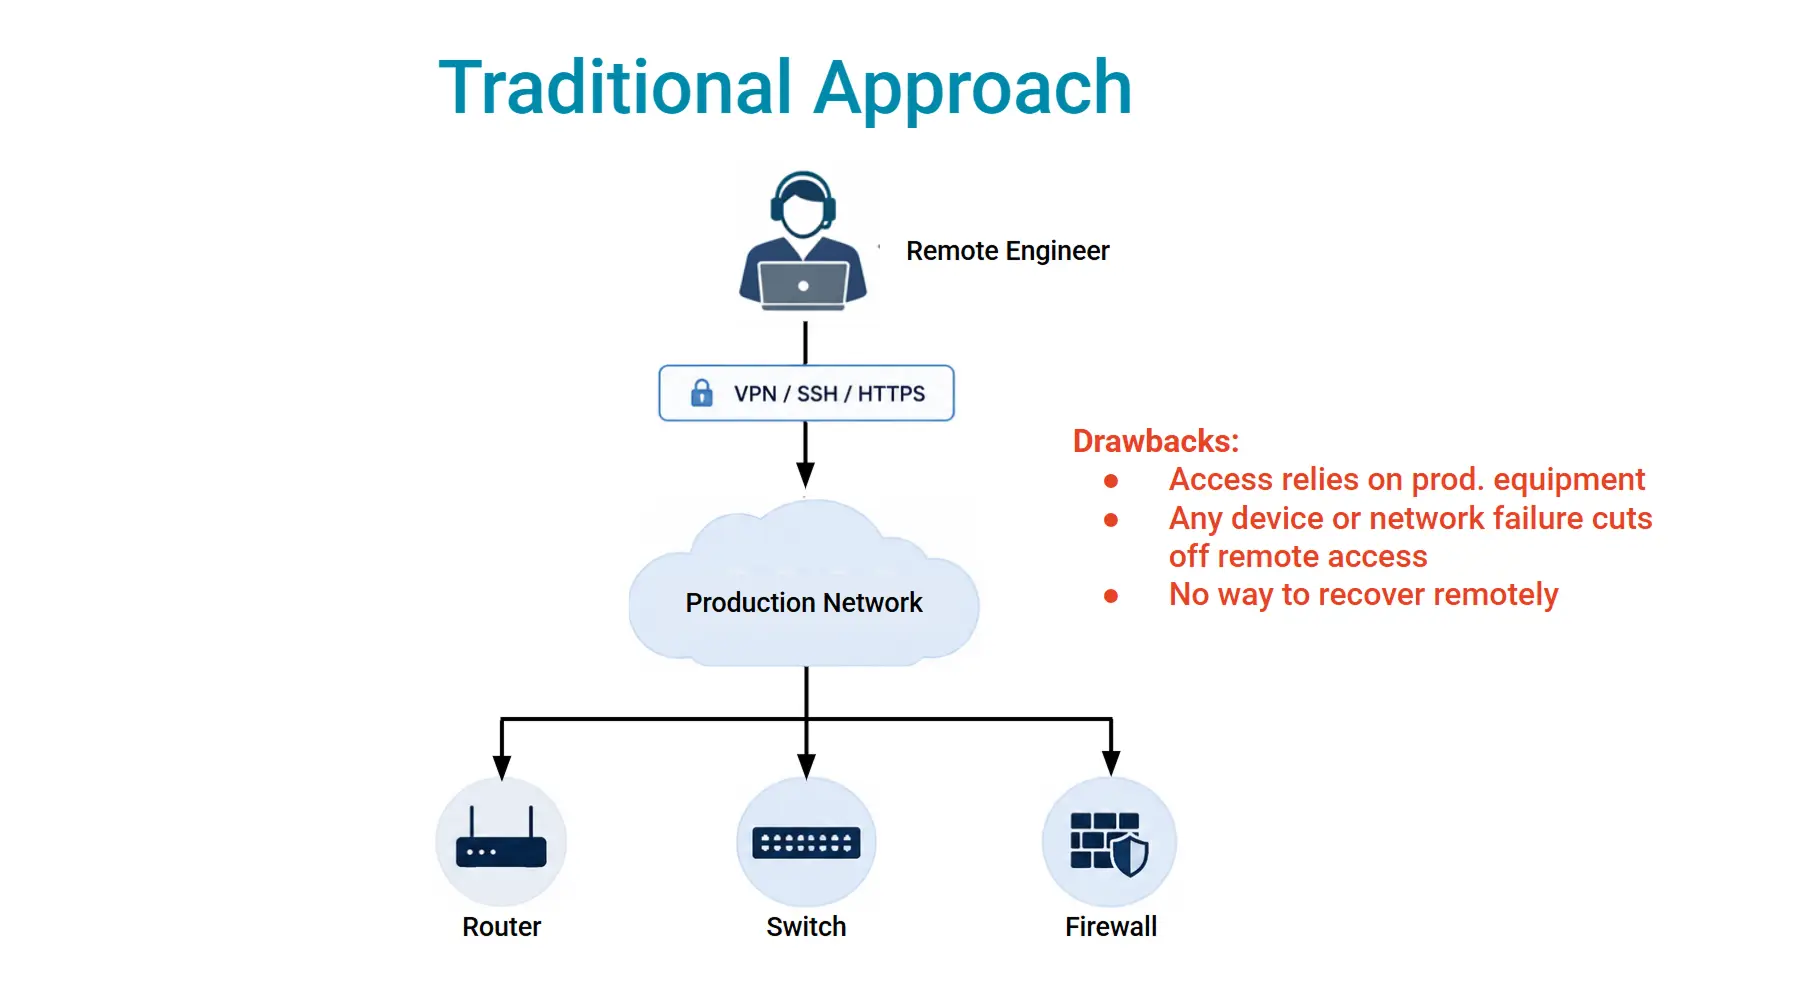
When everything is working fine, management access is like air: you don’t even need to think about it. You can SSH into a router, change a firewall config, or restart a hanging server. It’s very straightforward because of one thing: the WAN is what connects you to the infrastructure.
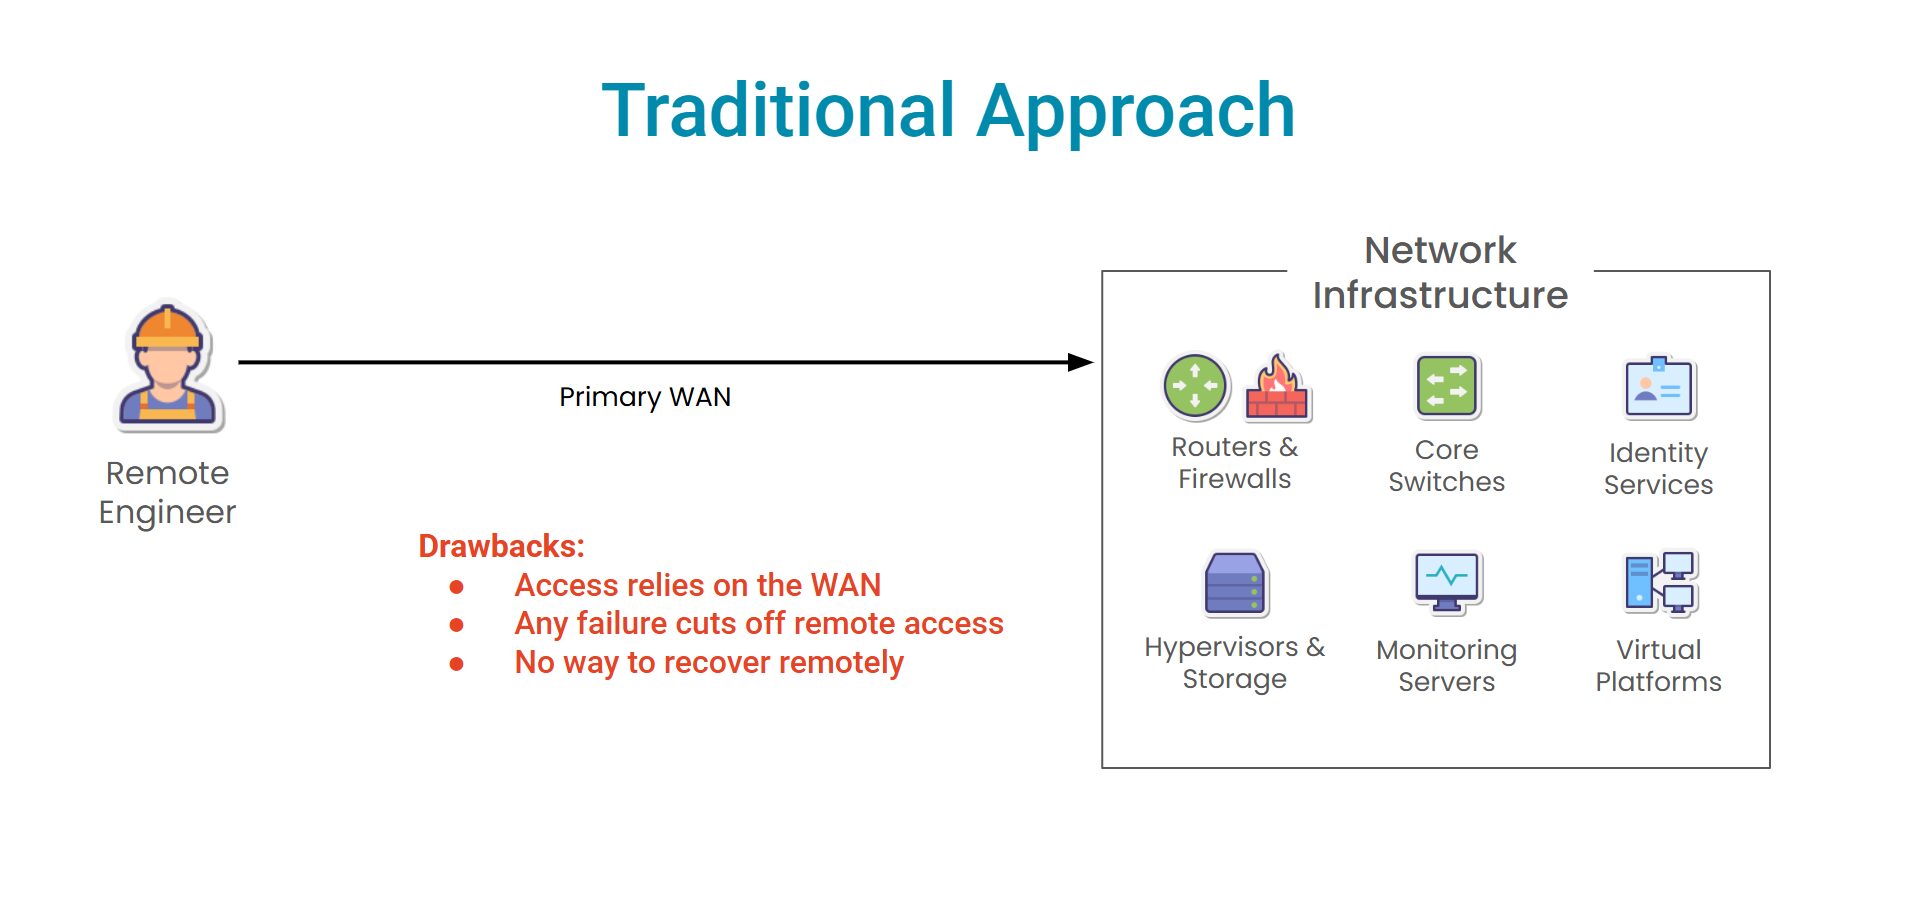
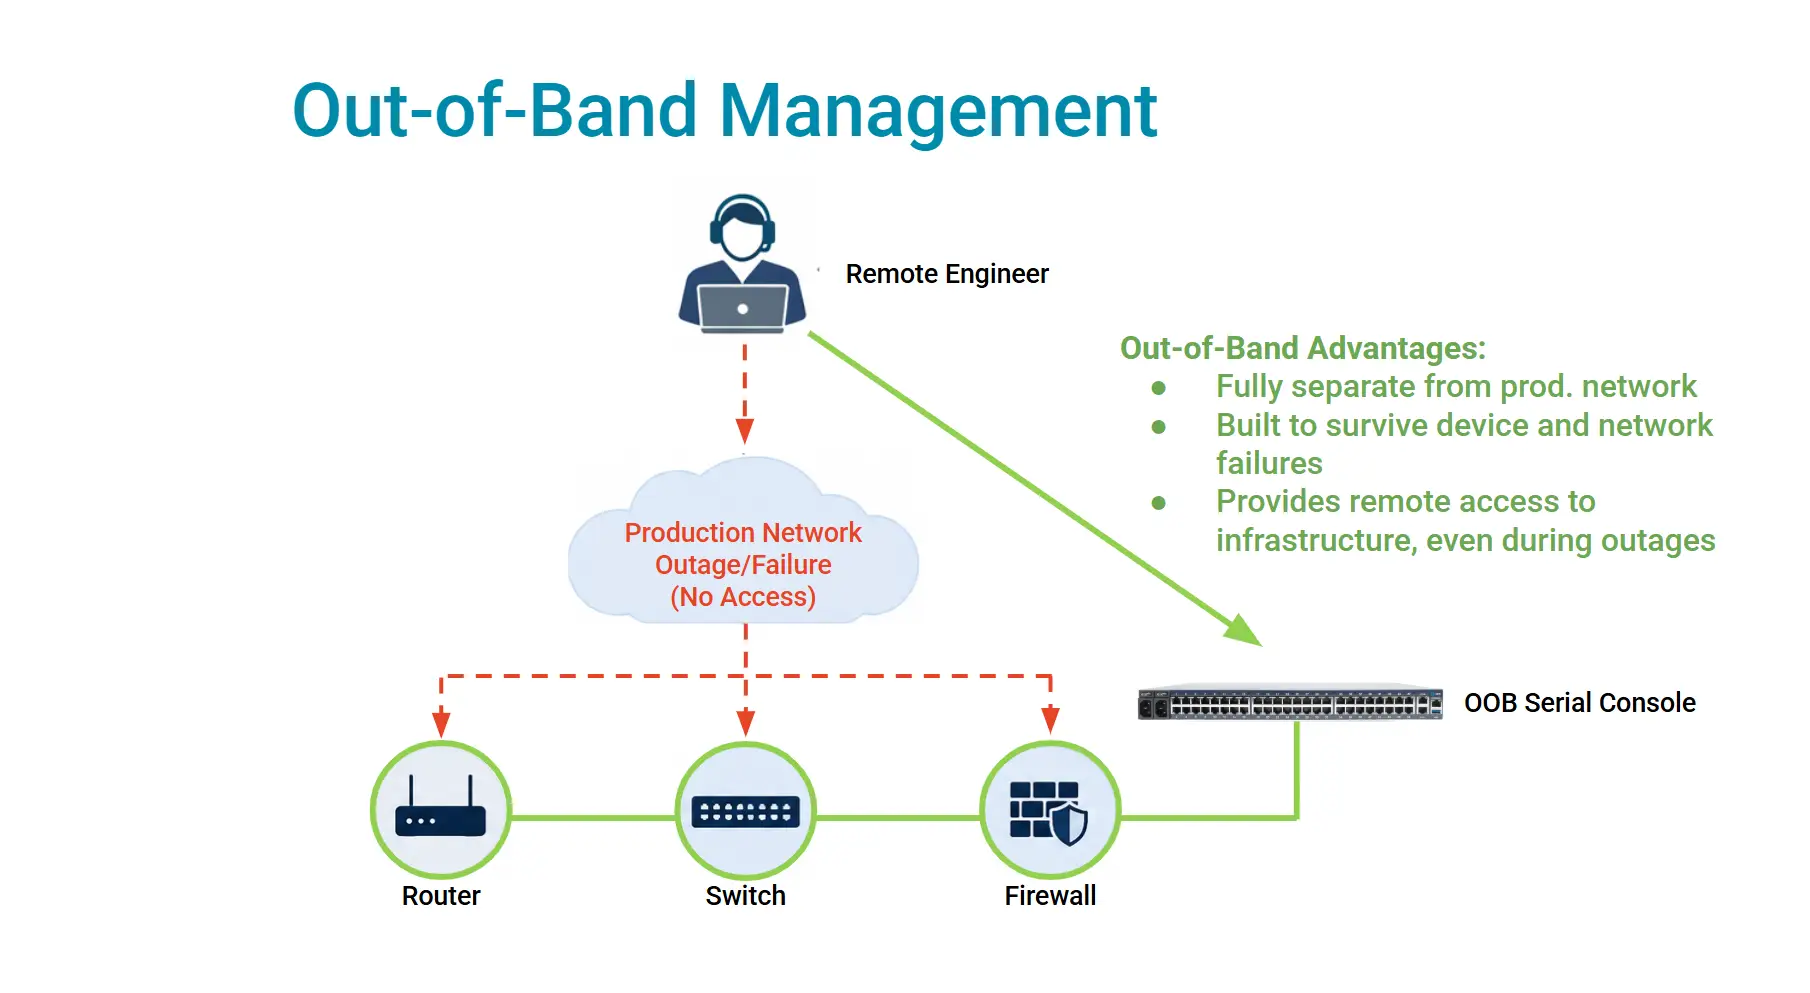
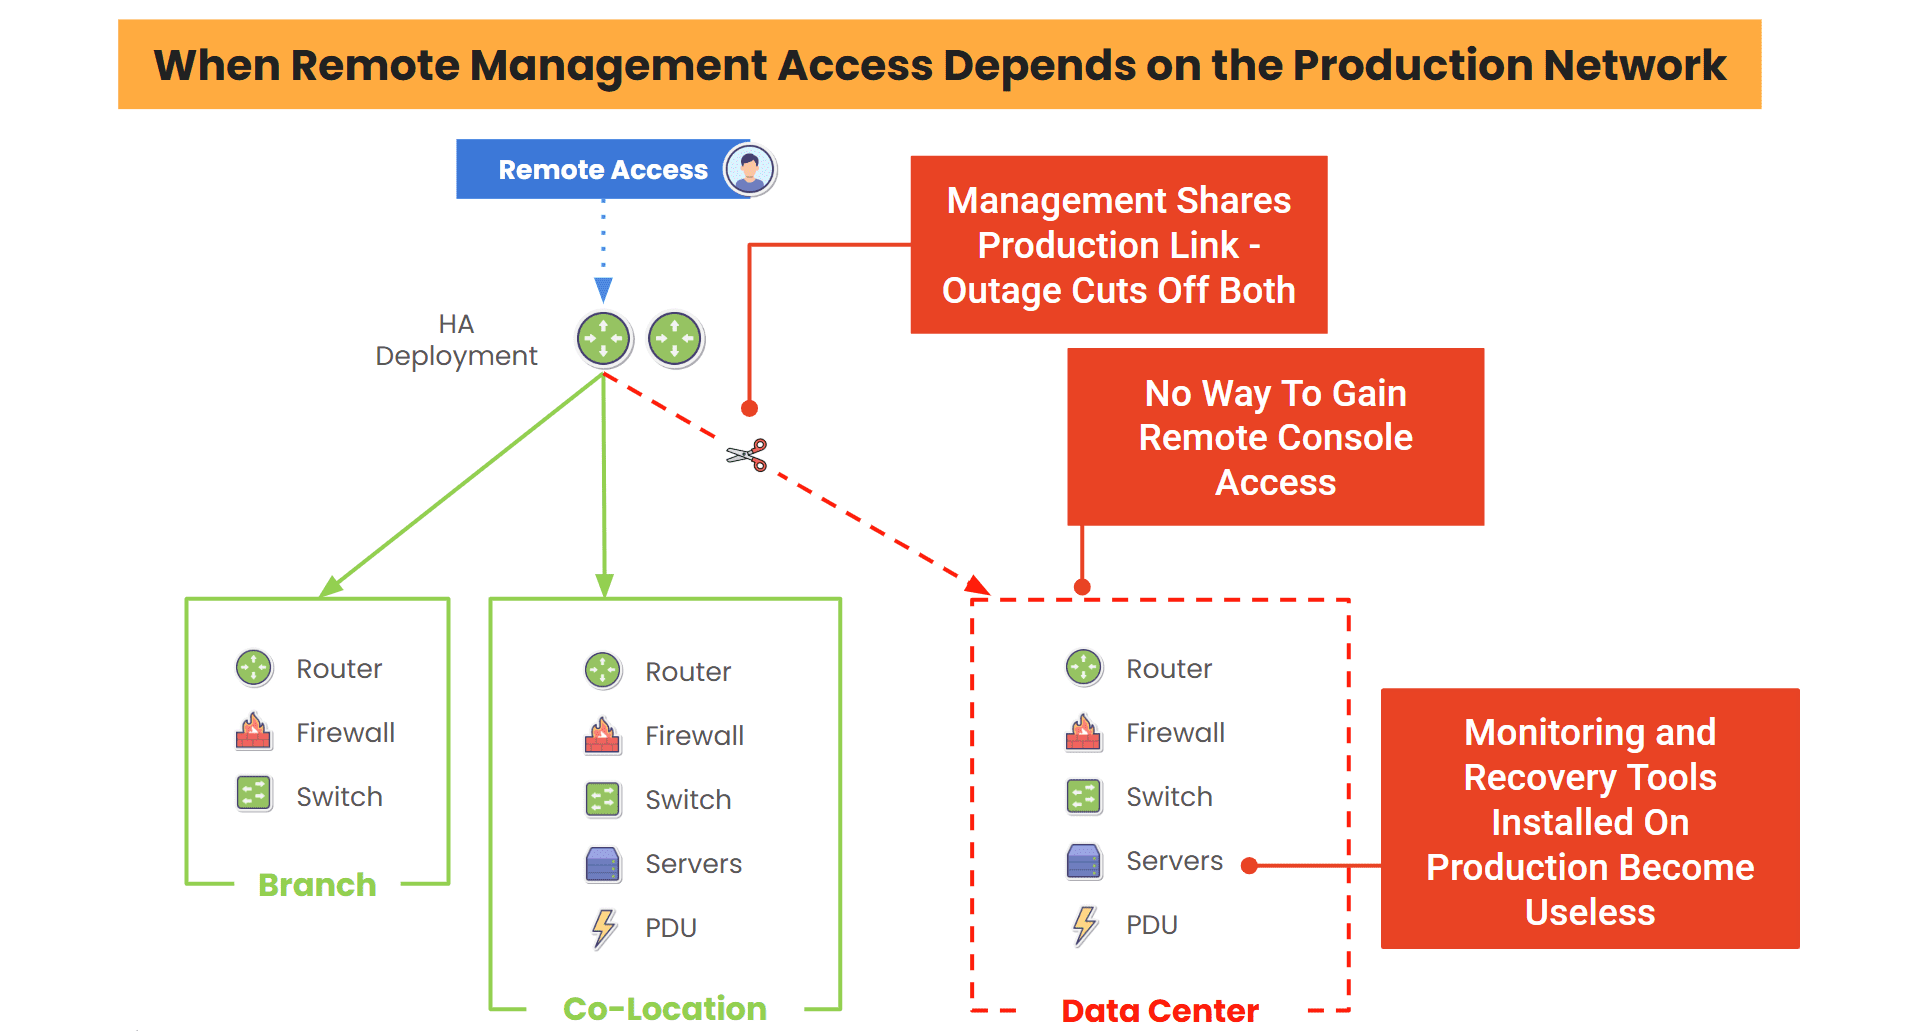
But this is a problem. This means that you really don’t have a dedicated management plane, since management access relies on the production network. When the WAN fails, the production network is what you need to fix — but you no longer have access to it.
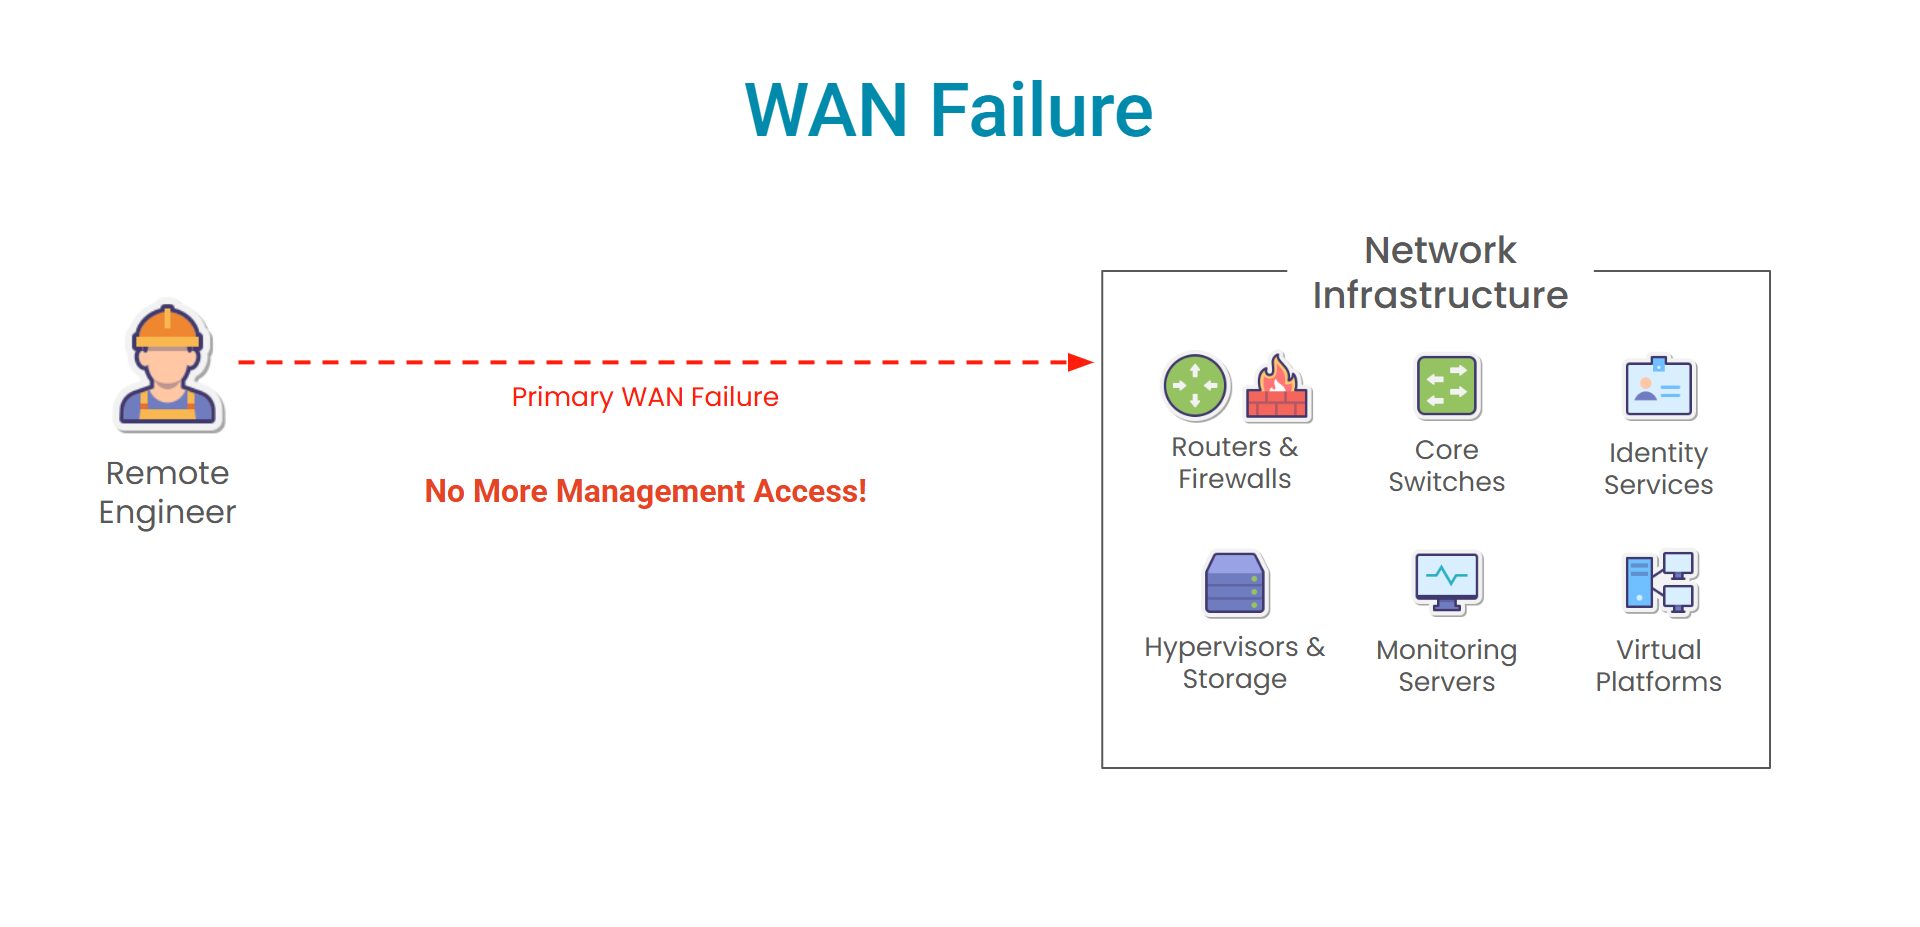
Here’s what happens when the WAN fails:
- Data plane disruption: Applications and users lose connectivity.
- Control plane disruption: Routing and network operations are jeopardized.
- Management plane disruption: Engineers lose remote access to the devices they need to troubleshoot.
When you can’t reach the equipment you need to fix, a production outage turns into an entirely different issue.
What Actually Goes Wrong When the WAN Fails?
ISP and Carrier Outages
Sometimes, the service provider itself has an outage and there’s not much you can do about it. Recent data from Cisco ThousandEyes shows just how often these events occur. During the week of August 24-30, 2026, ThousandEyes observed 297 global ISP outage events, 203 of which were in the United States alone.
Outages instantly become a remote-management problem in these cases when the WAN is the only path back to a site that’s gone offline. You’re left with two options: Wait for your provider to restore the connection, or send an engineer to the affected site(s). Both can easily take hours, sometimes days, before normal operations are restored.
Fiber Cuts and Physical Disruptions
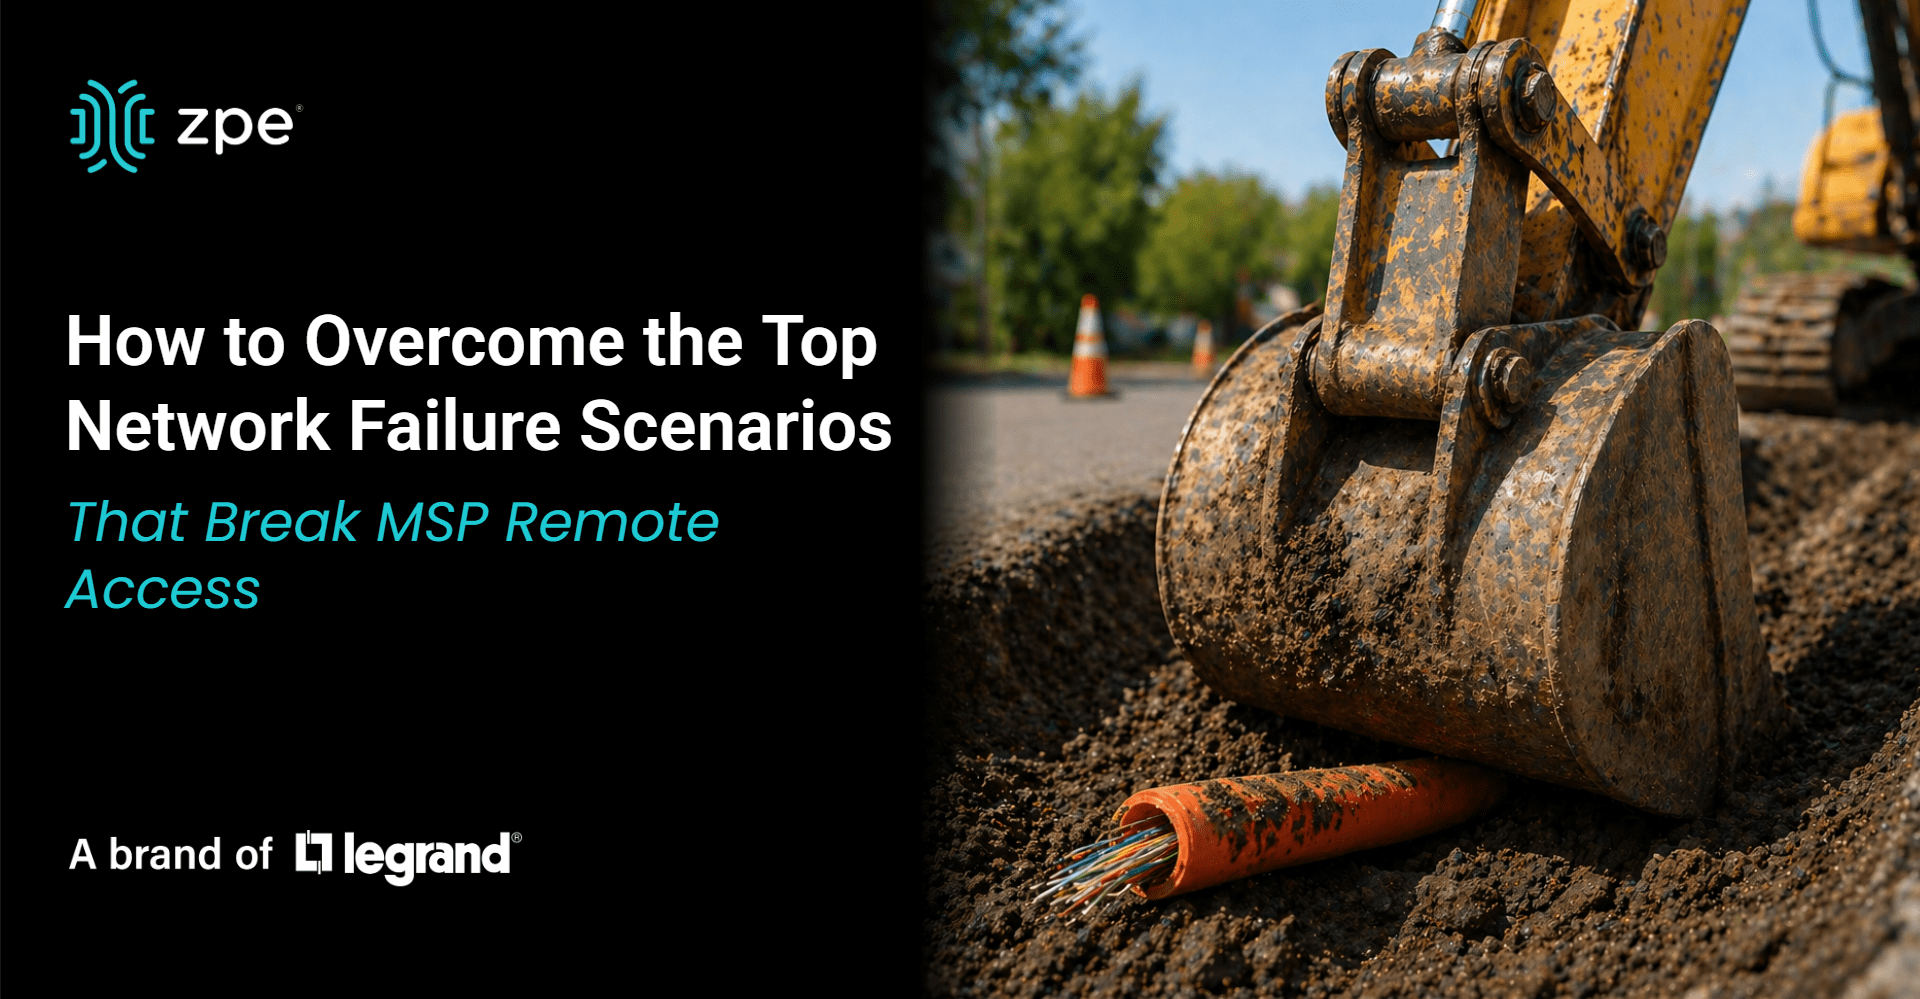
What happens when a construction crew accidentally sends a backhoe bucket or an auger straight through an underground fiber run? If you rely on the WAN for management access, physical disruptions like these could have you waiting for days before they’re fixed.
Cloudflare tracked more than 180 Internet disruptions during 2025, including those caused by cable cuts, power outages, and extreme weather. Some were brief, but others lasted for days. These failures are especially difficult (and frustrating) because you could be hundreds of miles away, and your devices could be perfectly healthy, but the path you use to reach them is physically broken.
Routing and Configuration Errors
Increasing network complexity directly contributes to configuration and change-management problems. Uptime Institute’s 2025 analysis found that 23% of impactful outages were attributed to IT and networking issues, like routing errors, incorrect configs, and firmware problems.
The network equipment is exactly what you need to fix, but a configuration error has eliminated the path you need to access it.
Third-Party Network Failures
There’s an entire ecosystem of ISPs, carriers, cloud providers, colocations, and other third party networks. If any part of this ecosystem fails, it can affect your ability to reach remote infrastructure.
Uptime Institute reports that 39% of those surveyed experienced an outage caused by a third-party networking issue. Essentially, you can lose access to your own infrastructure because of a failure you don’t control.
That’s the common thread with all these outage scenarios. When a WAN failure takes down your production network, your management access goes down with it.
How To Stay Operational During WAN Failures
Build an Isolated Management Infrastructure
Adding redundancy seems like the logical solution. But having true operational resilience means going beyond having a second WAN circuit. You need to be able to confidently answer this question:
Can you still reach the infrastructure if the primary network fails?
If the answer is no, you still have a shared-fate problem: your management access depends on the same infrastructure you’re trying to recover.
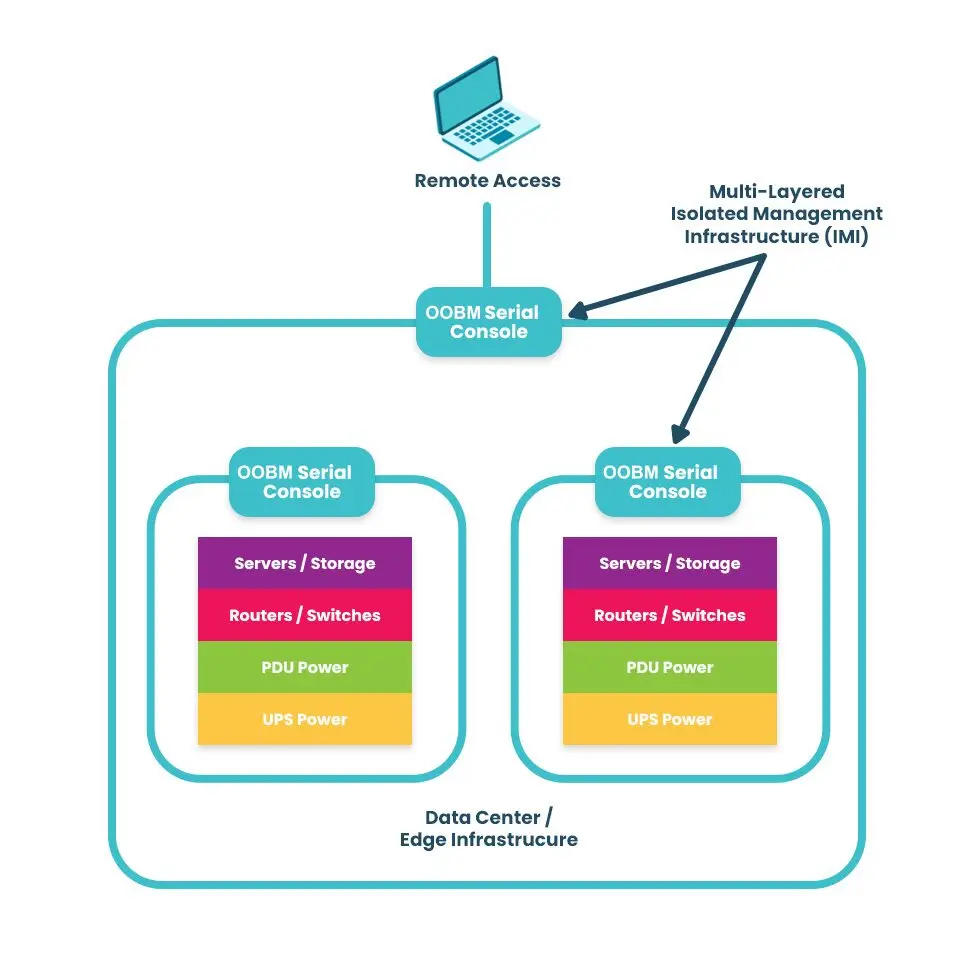
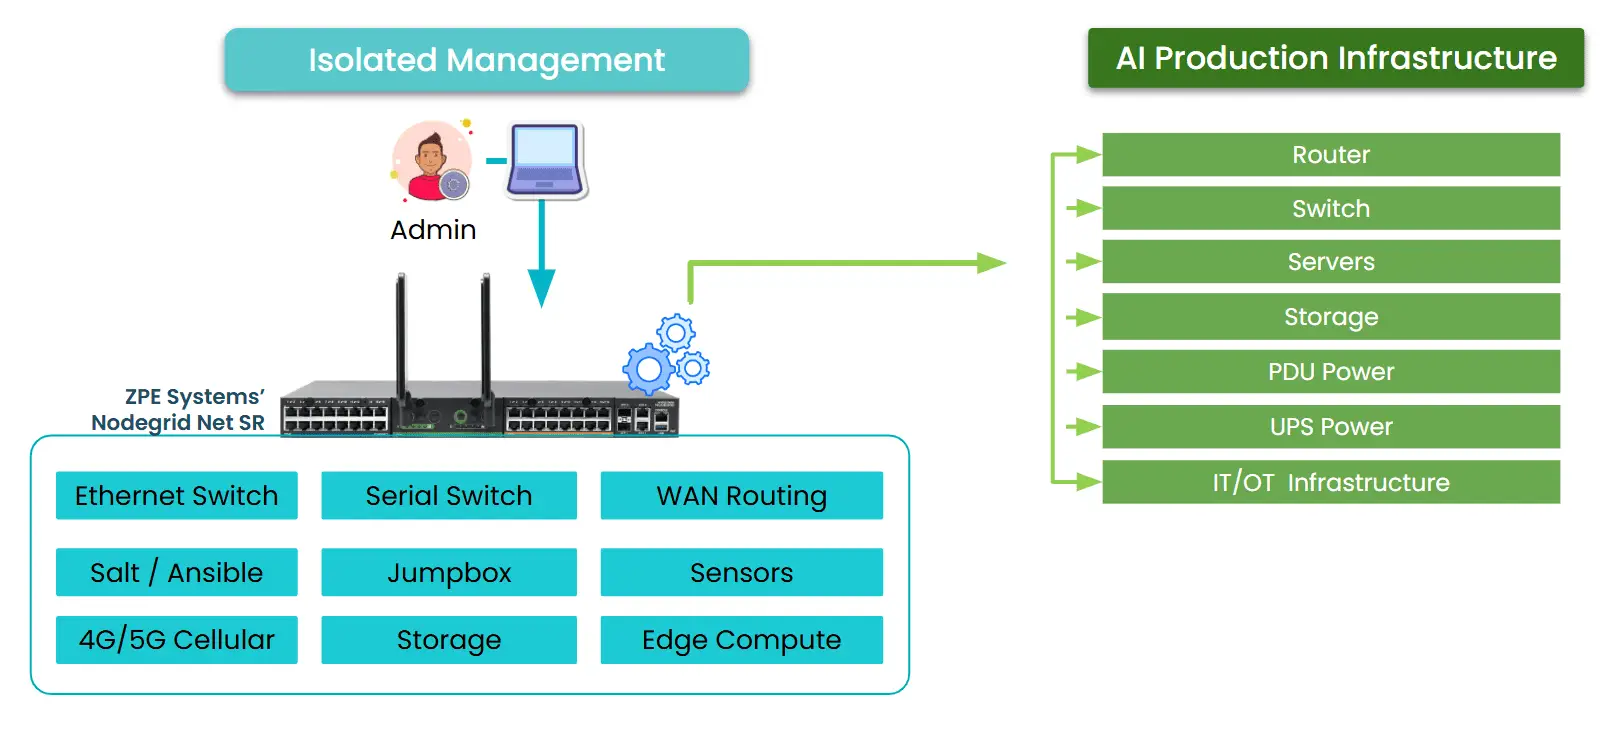
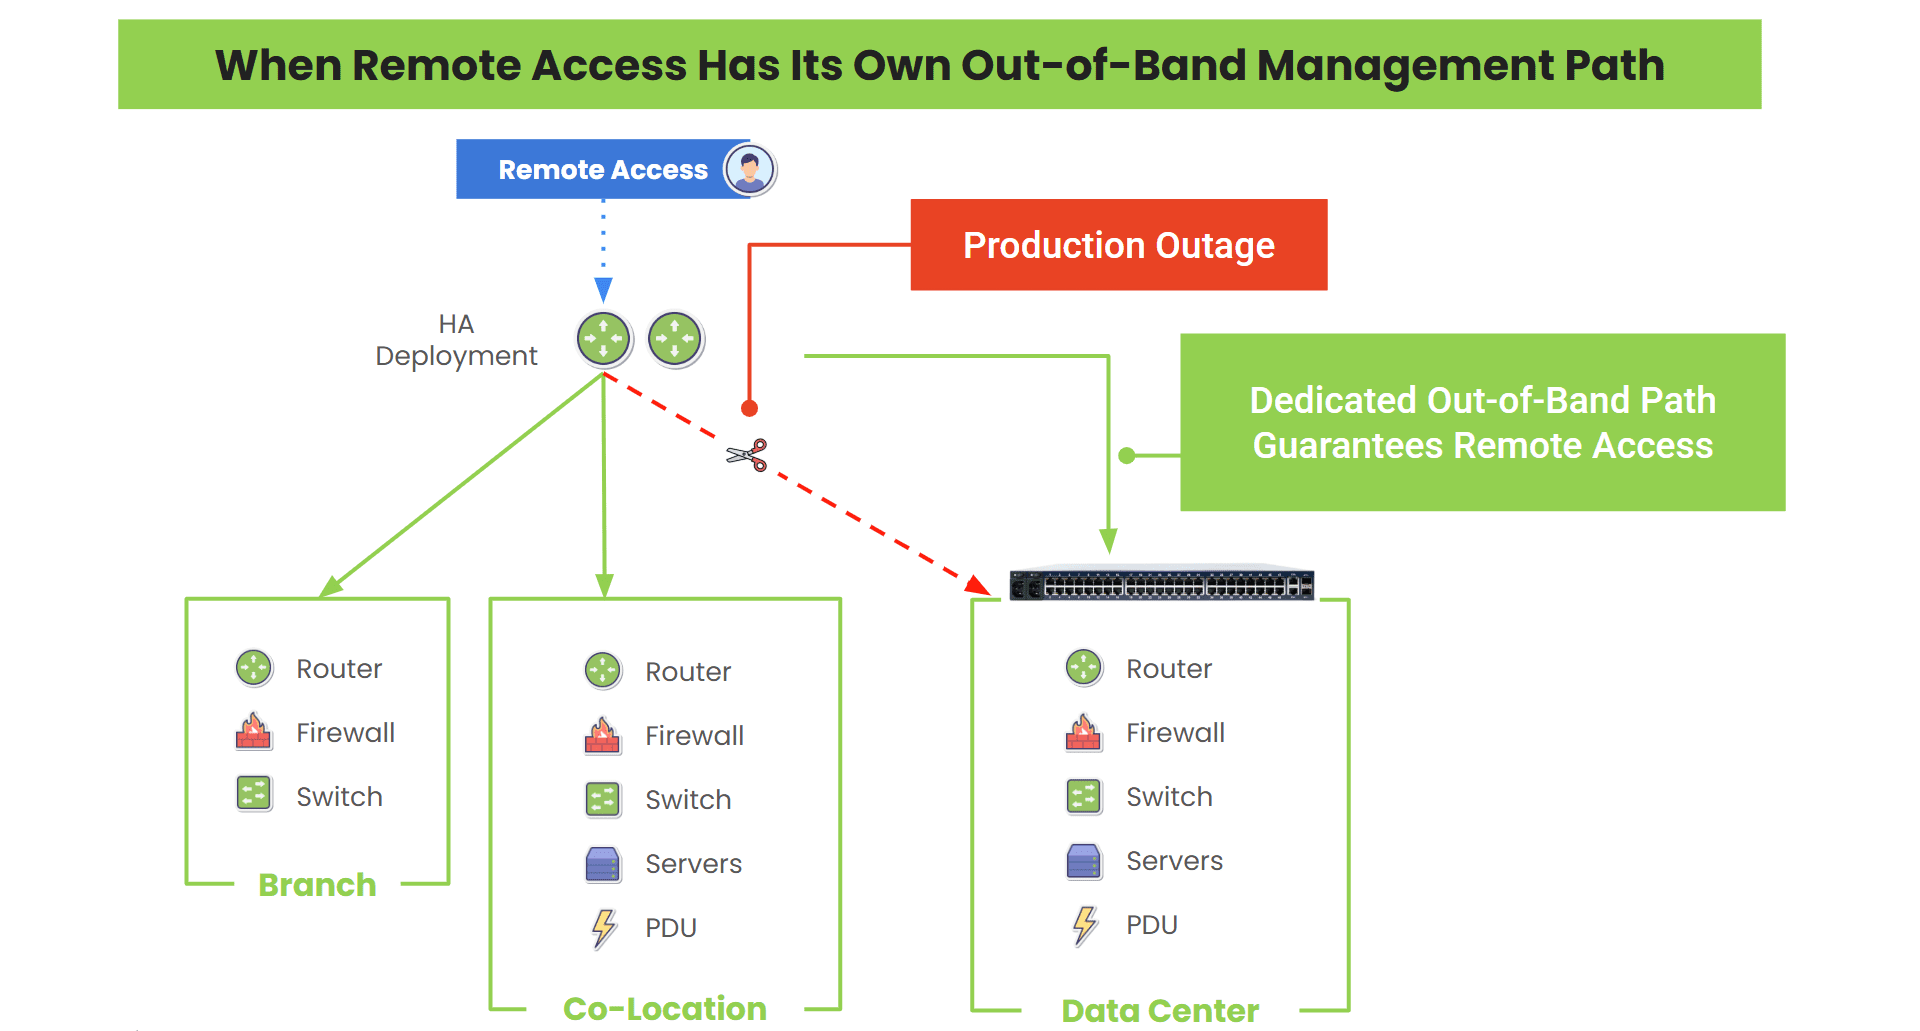
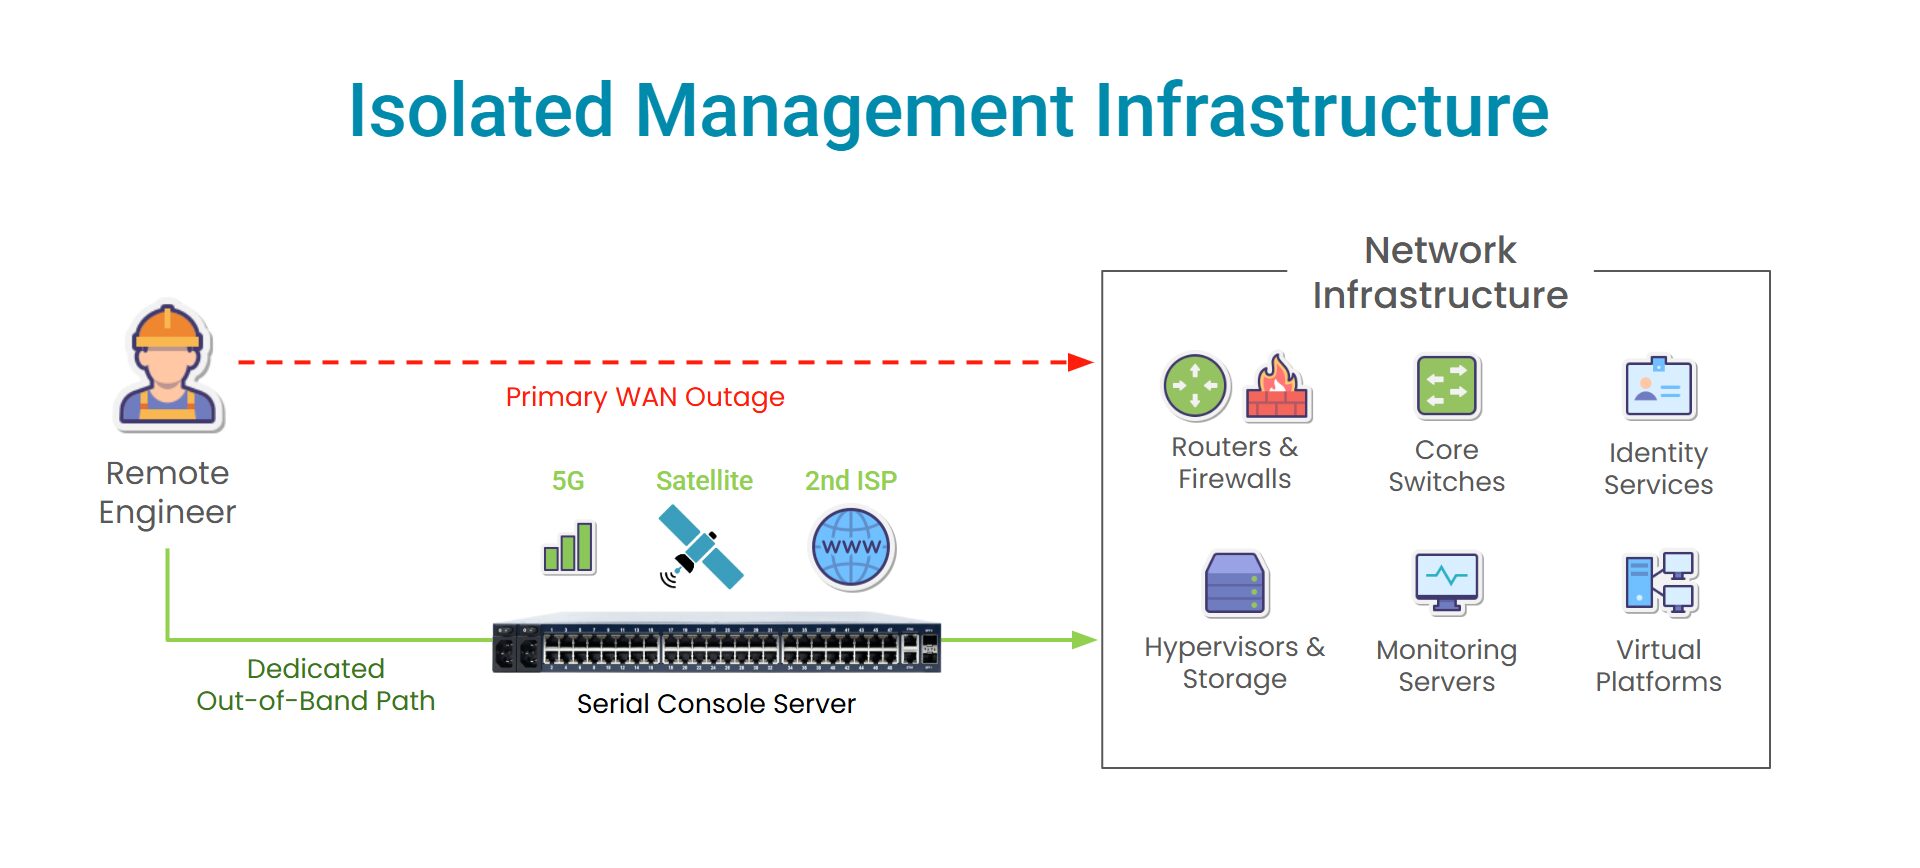
An Isolated Management Infrastructure (IMI) solves this by creating a dedicated management layer that is completely independent of the production network. IMI does not rely on the WAN, routers, switches, or other infrastructure that carry production traffic. Instead, IMI provides a separate path that’s purpose-built for maintaining and recovering production infrastructure. Think of it as a safety net that keeps business from crashing down if there’s a primary network outage.
What Does IMI Look Like?
Isolated Management Infrastructure is made up of several components:
- A separate management network that is logically and physically isolated from production infrastructure. This is created by deploying out-of-band serial consoles.
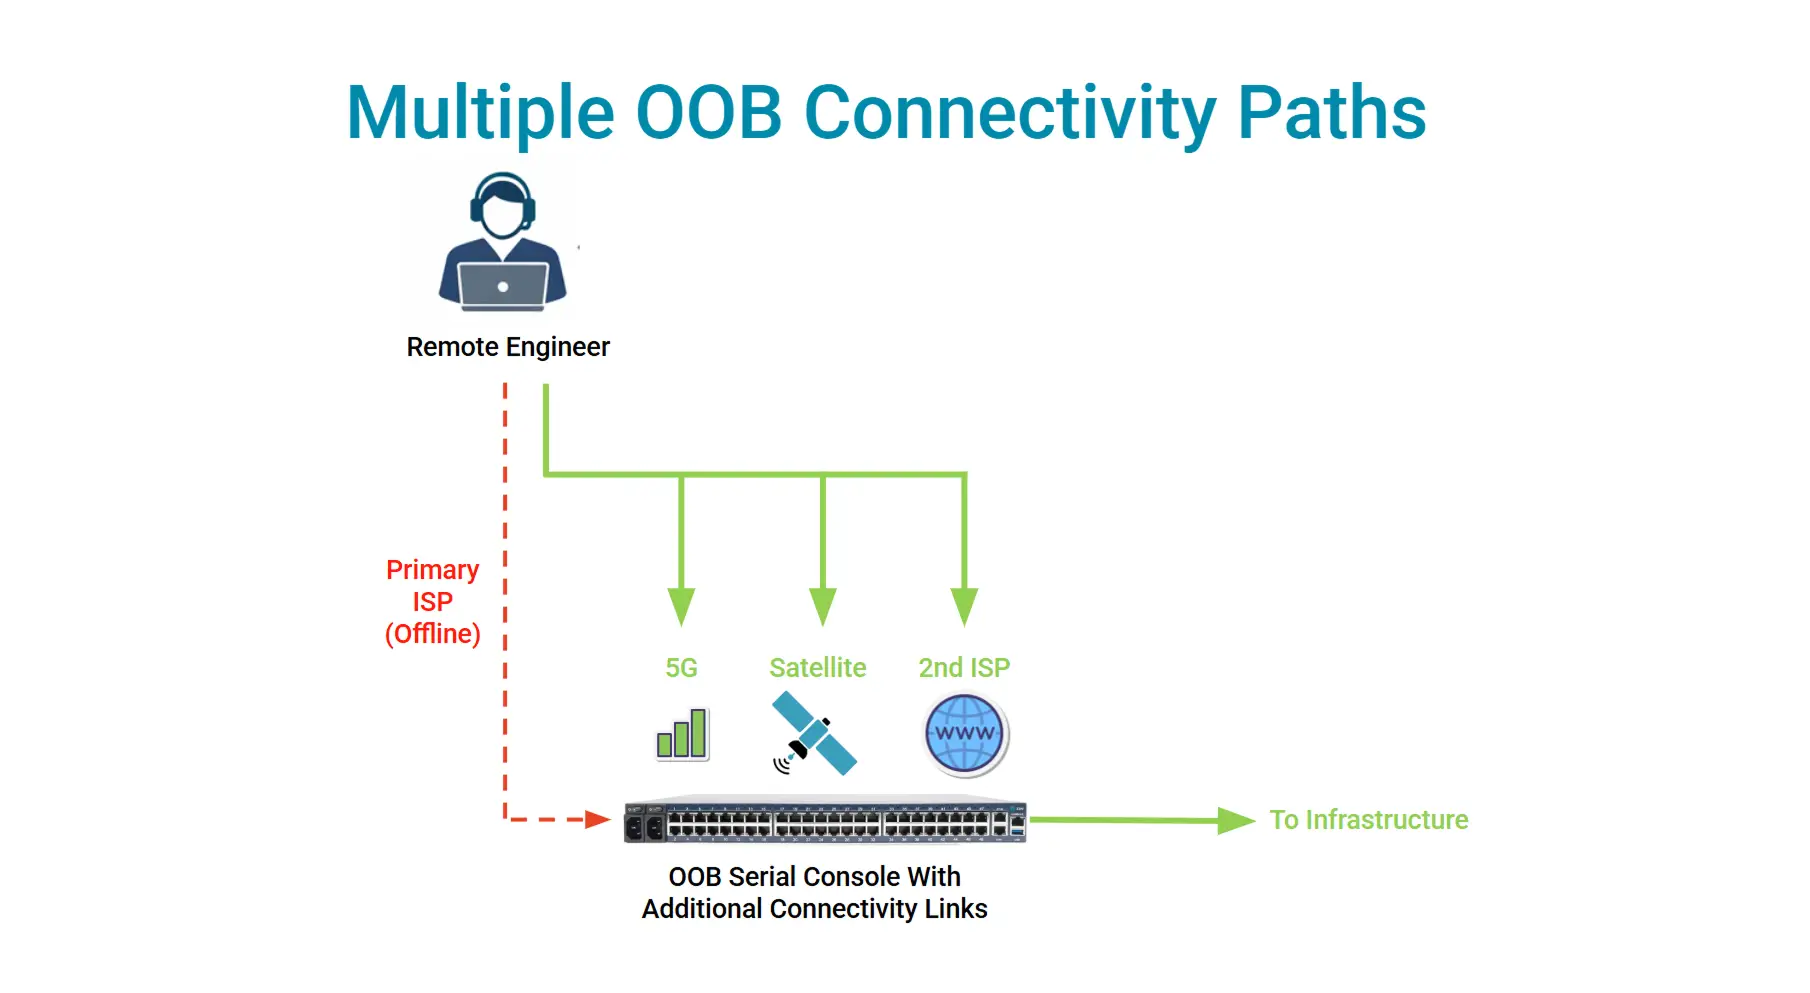
- Independent connectivity using 5G, satellite, and/or other link types that don’t rely on terrestrial infrastructure. These provide access to your OOB serial consoles, and thus your production equipment.
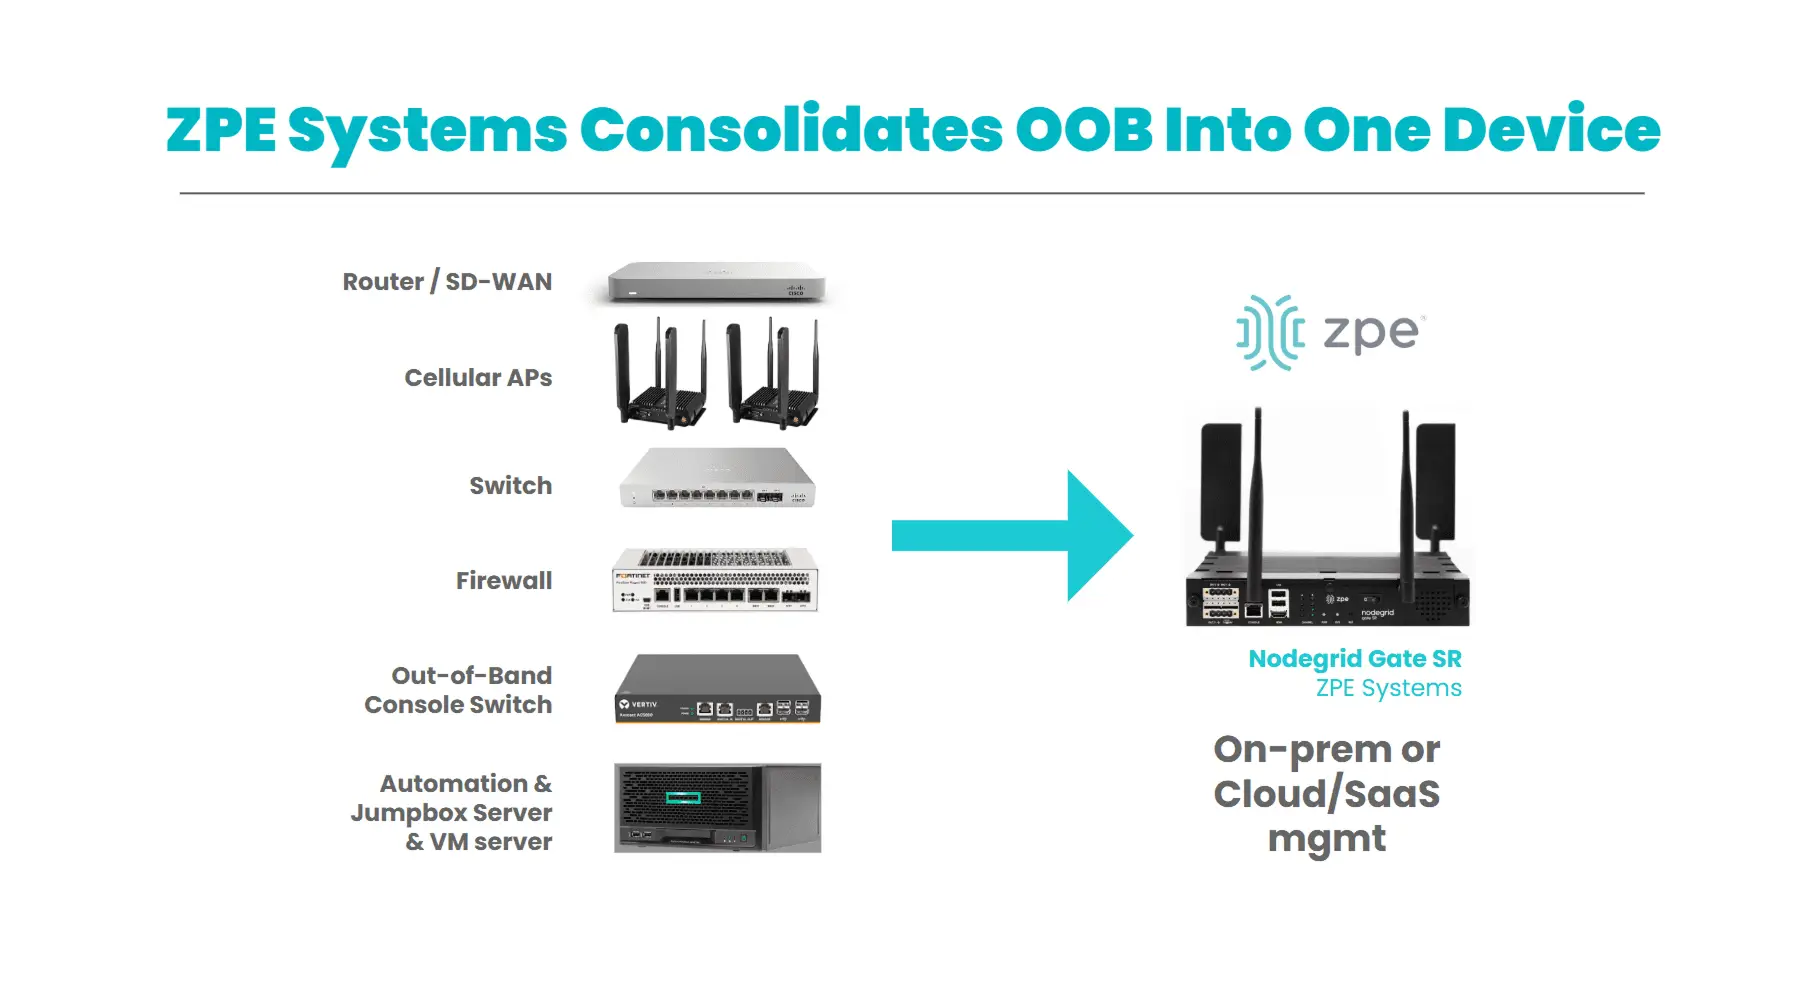
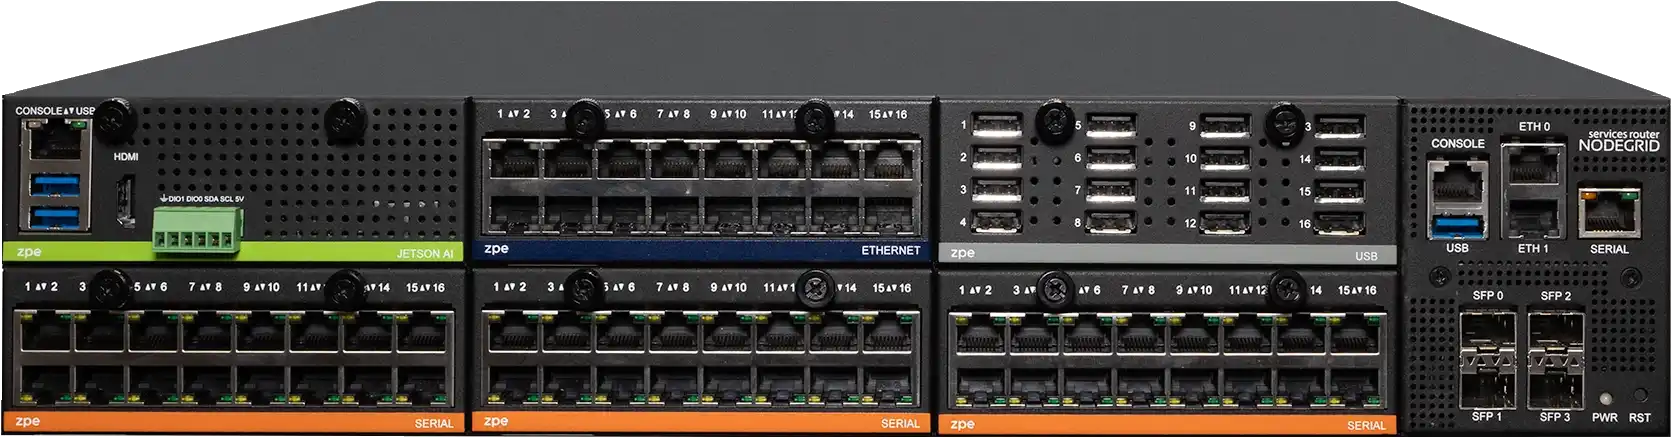
- Direct access to the variety of critical IT, including via serial, Ethernet, USB, KVM, and power interfaces. This gives you management access to your entire equipment stack.
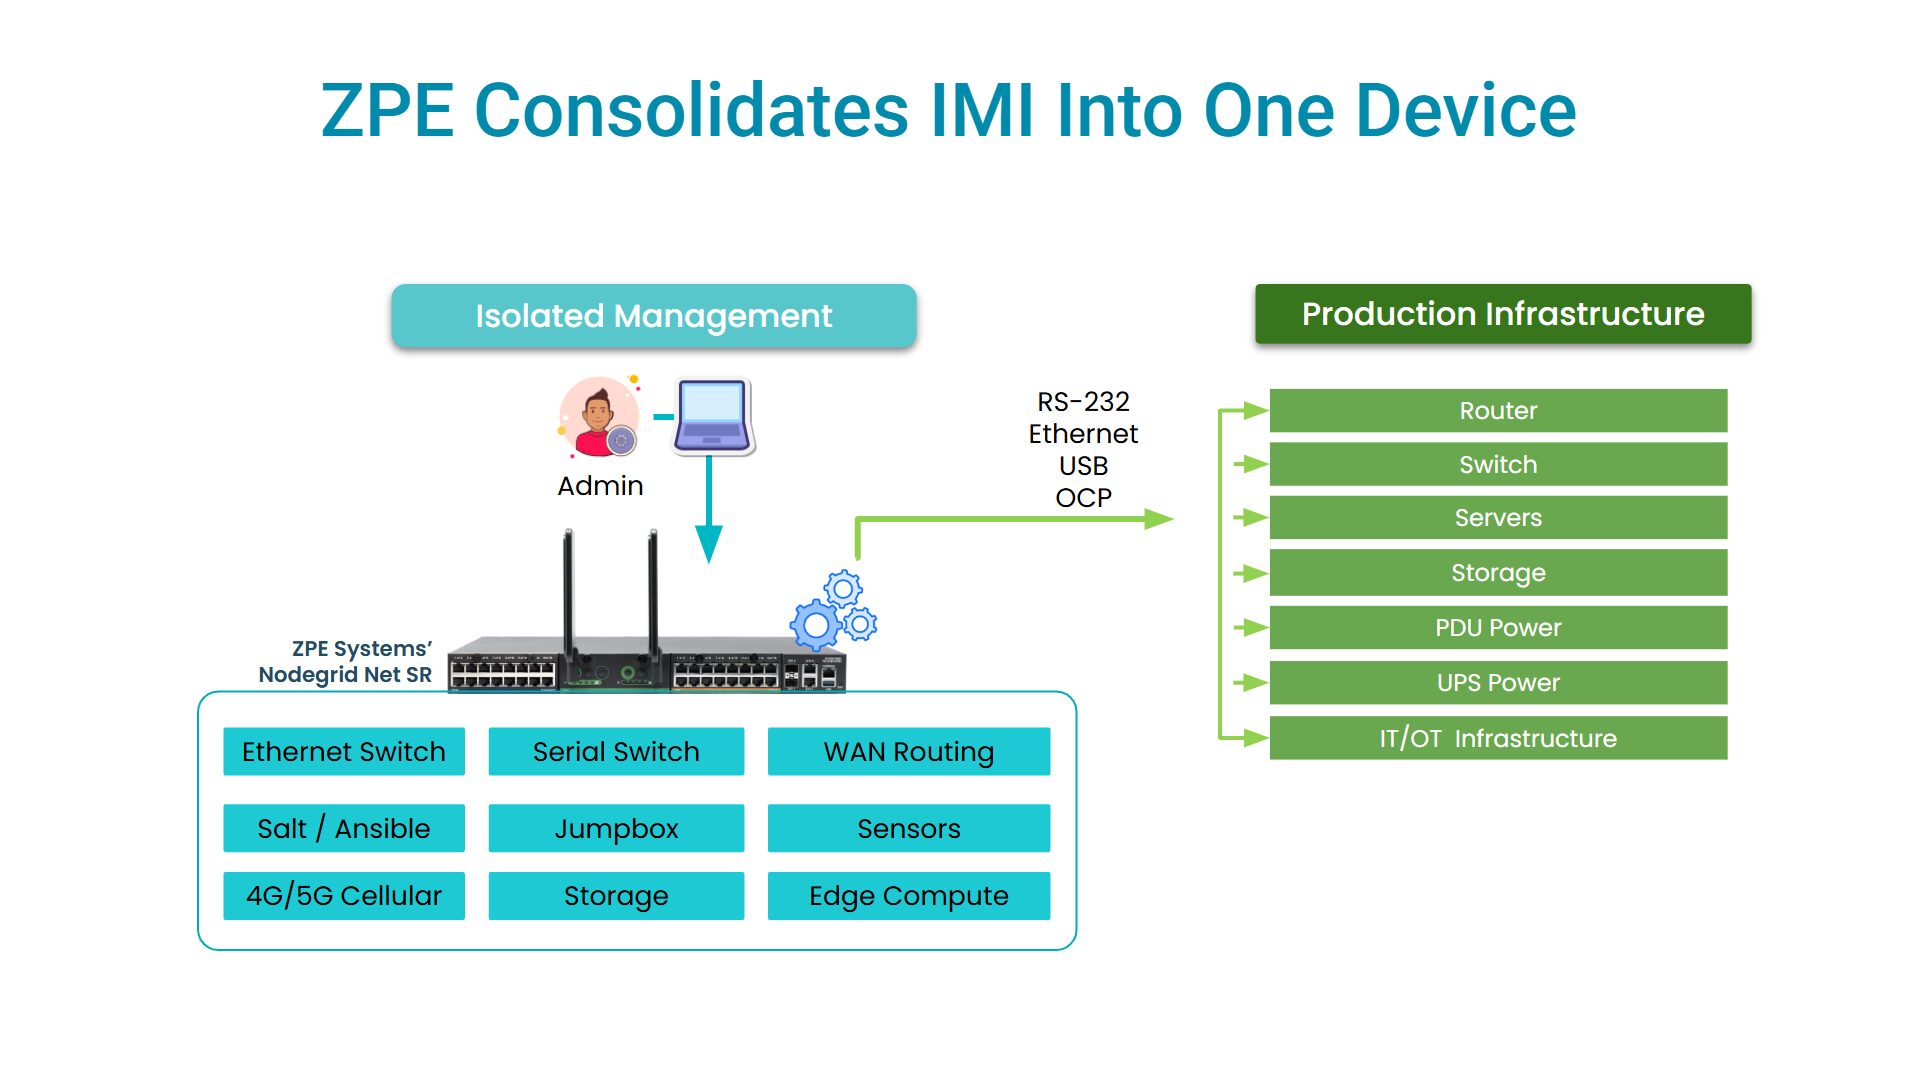
This completely changes the recovery process. There’s no more waiting for the WAN to come back or dispatching an engineer to the site. Engineers can use the IMI to pinpoint affected equipment, make config changes, and/or completely rebuild systems.
Take Mercado Libre for example. This Latin America e-commerce giant experienced an unexpected outage at one of their distribution hubs. But because they had installed ZPE Systems’ Nodegrid as their IMI, they were able to keep operating as if nothing happened. “The solution paid for itself with just this one outage,” they said. Read the full Mercado Libre case study here.
Don’t Let WAN Failures Take Down Your Network
Download The Network Resilience Blueprint
The WAN will always be a critical component, and you can’t eliminate every carrier outage, fiber cut, or config error. But you can eliminate your management network’s dependency on the WAN.
The Network Resilience Blueprint is a practical framework for putting IMI into practice. It walks you through five architectural steps to build an infrastructure that’s easy to manage, fast to recover, and most importantly, resilient against WAN failures. Download the blueprint now and keep your critical IT reachable even when the network is down.
Get in Touch For a Demo of AI Resilience
Our engineers will walk you through the best practices and show you Nodegrid’s capabilities first-hand. See how easy it is to point, click, and manage your distributed AI fleet. Fill out the form to get started.