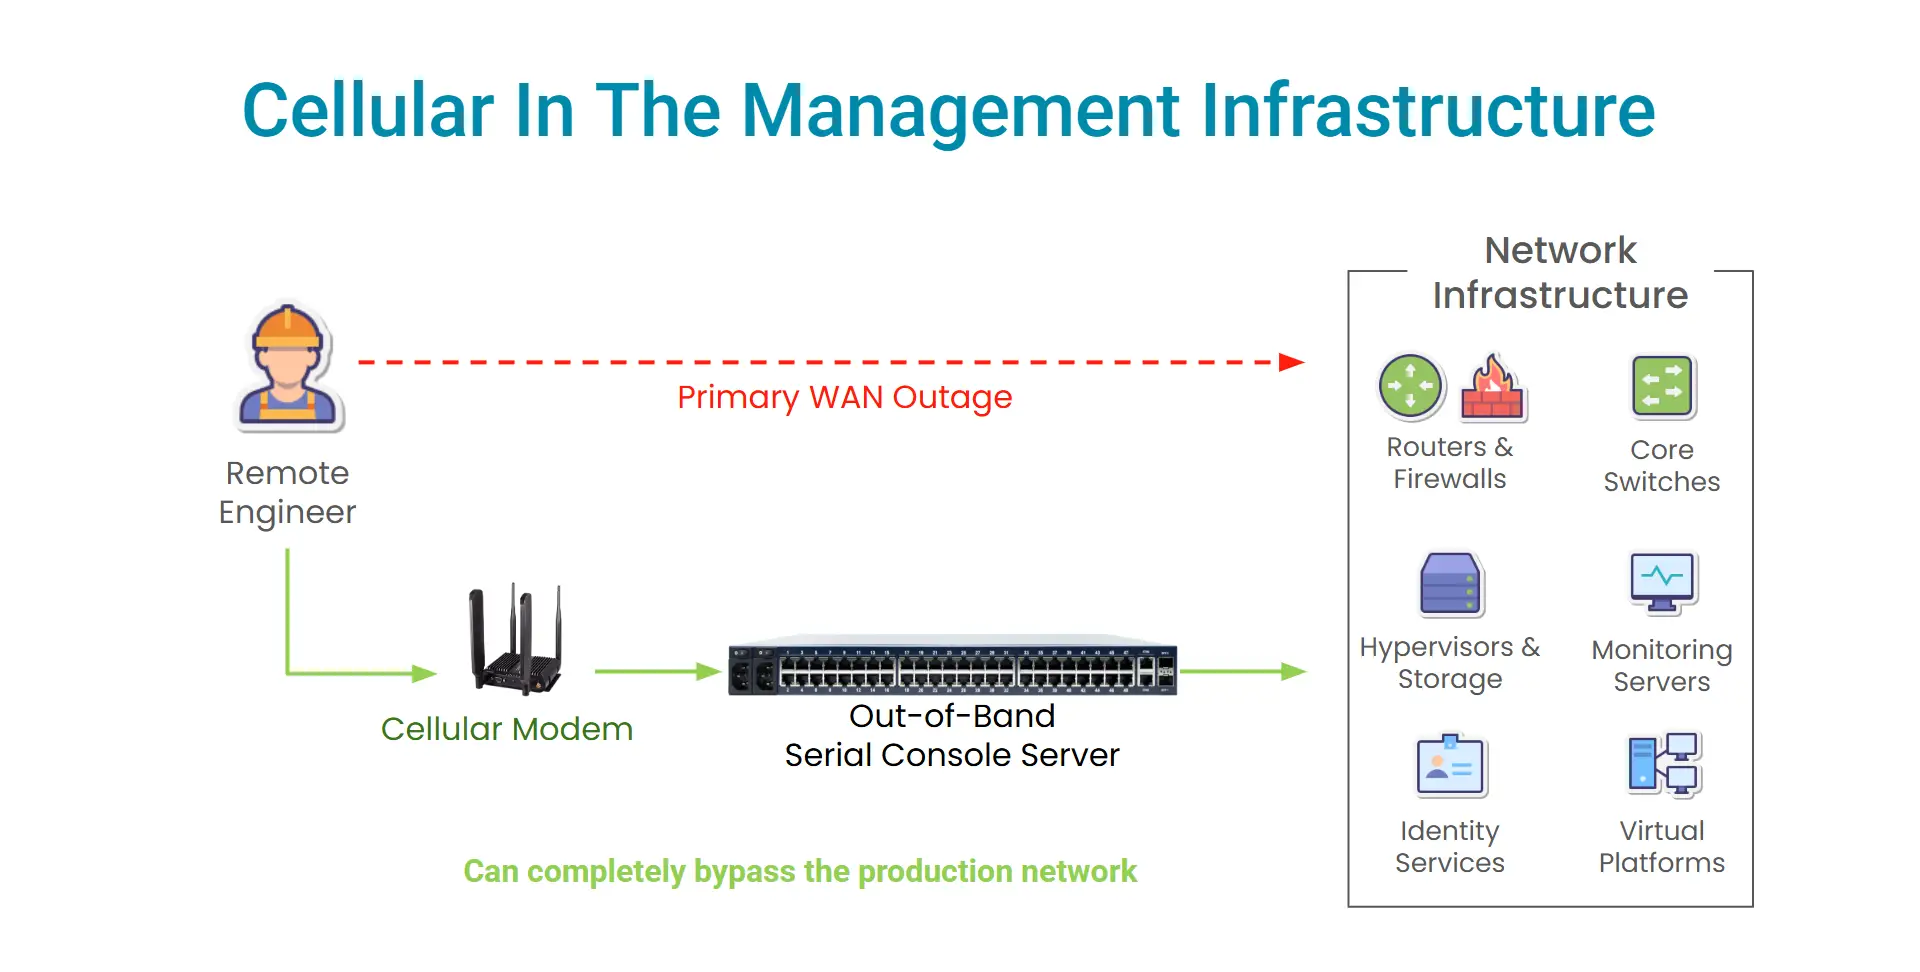
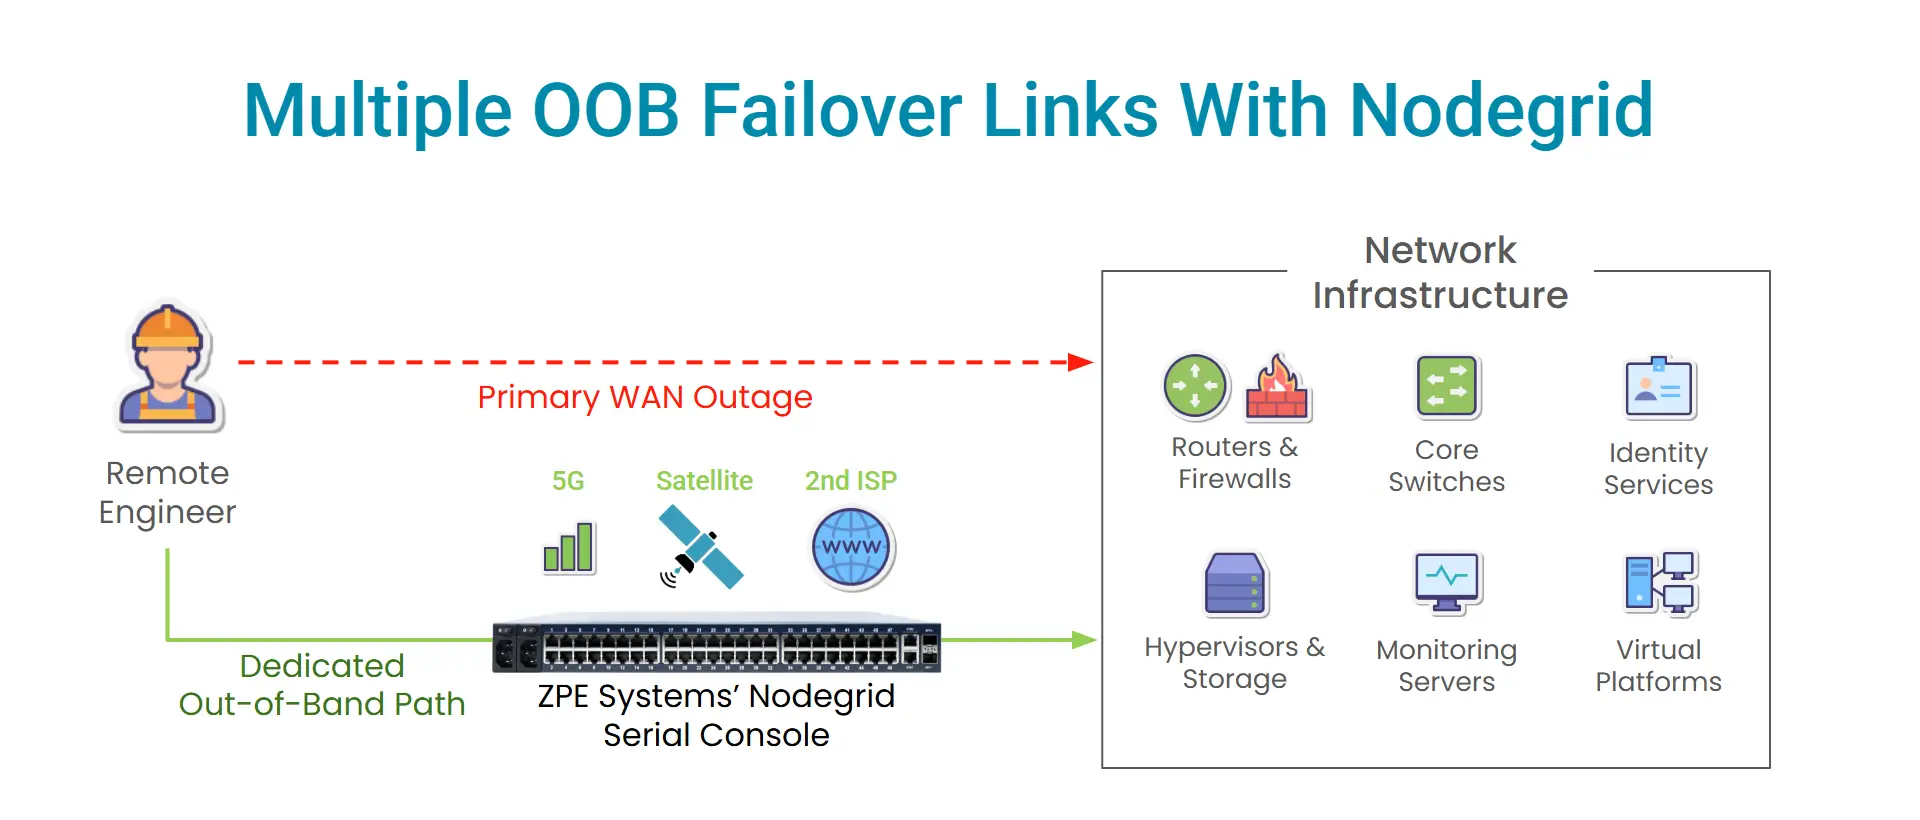
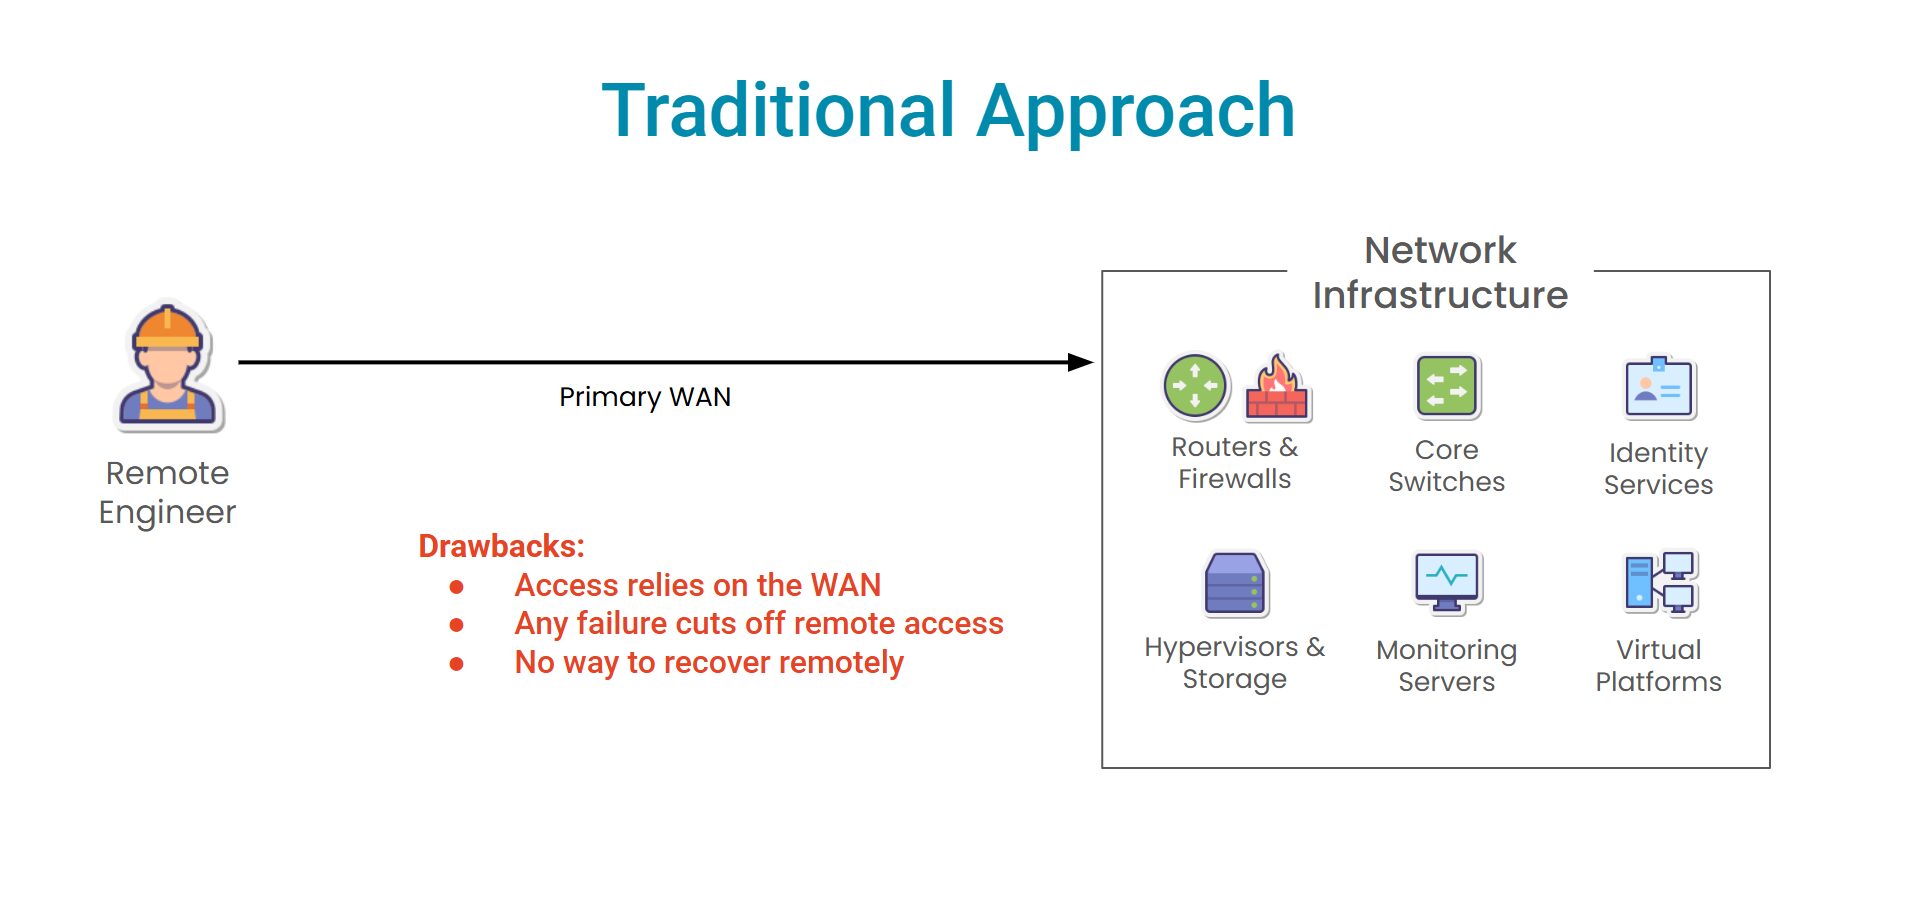
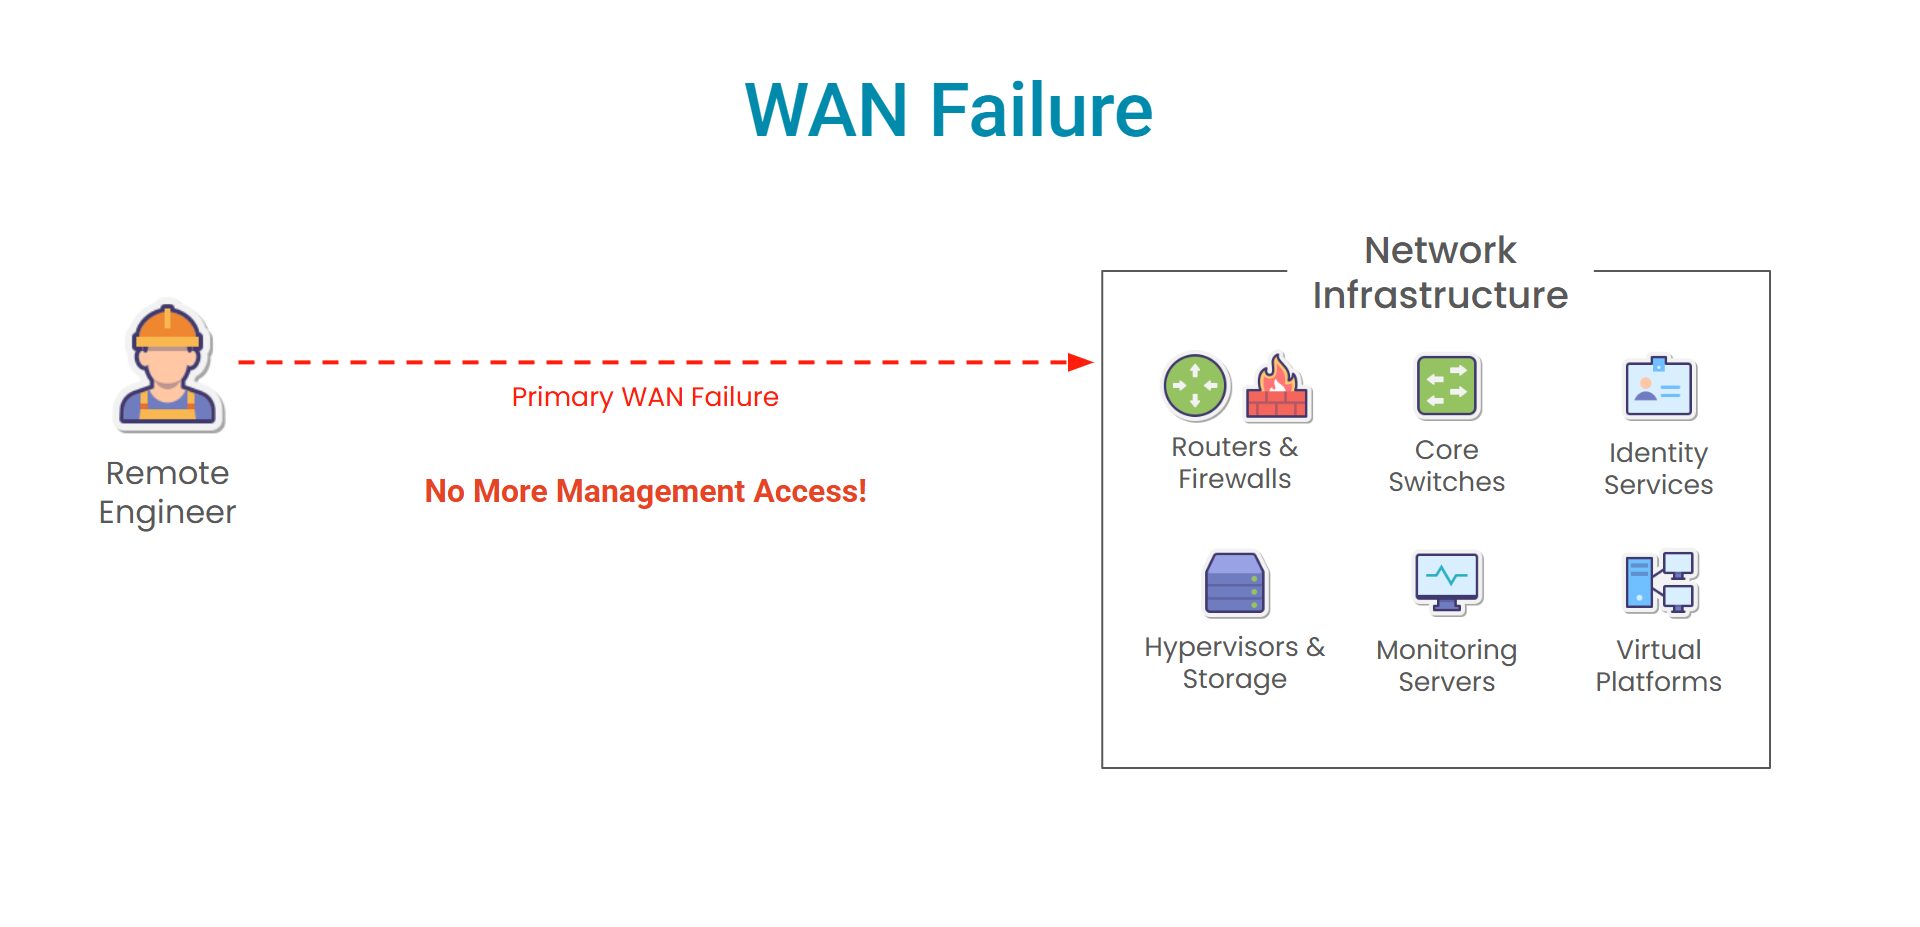
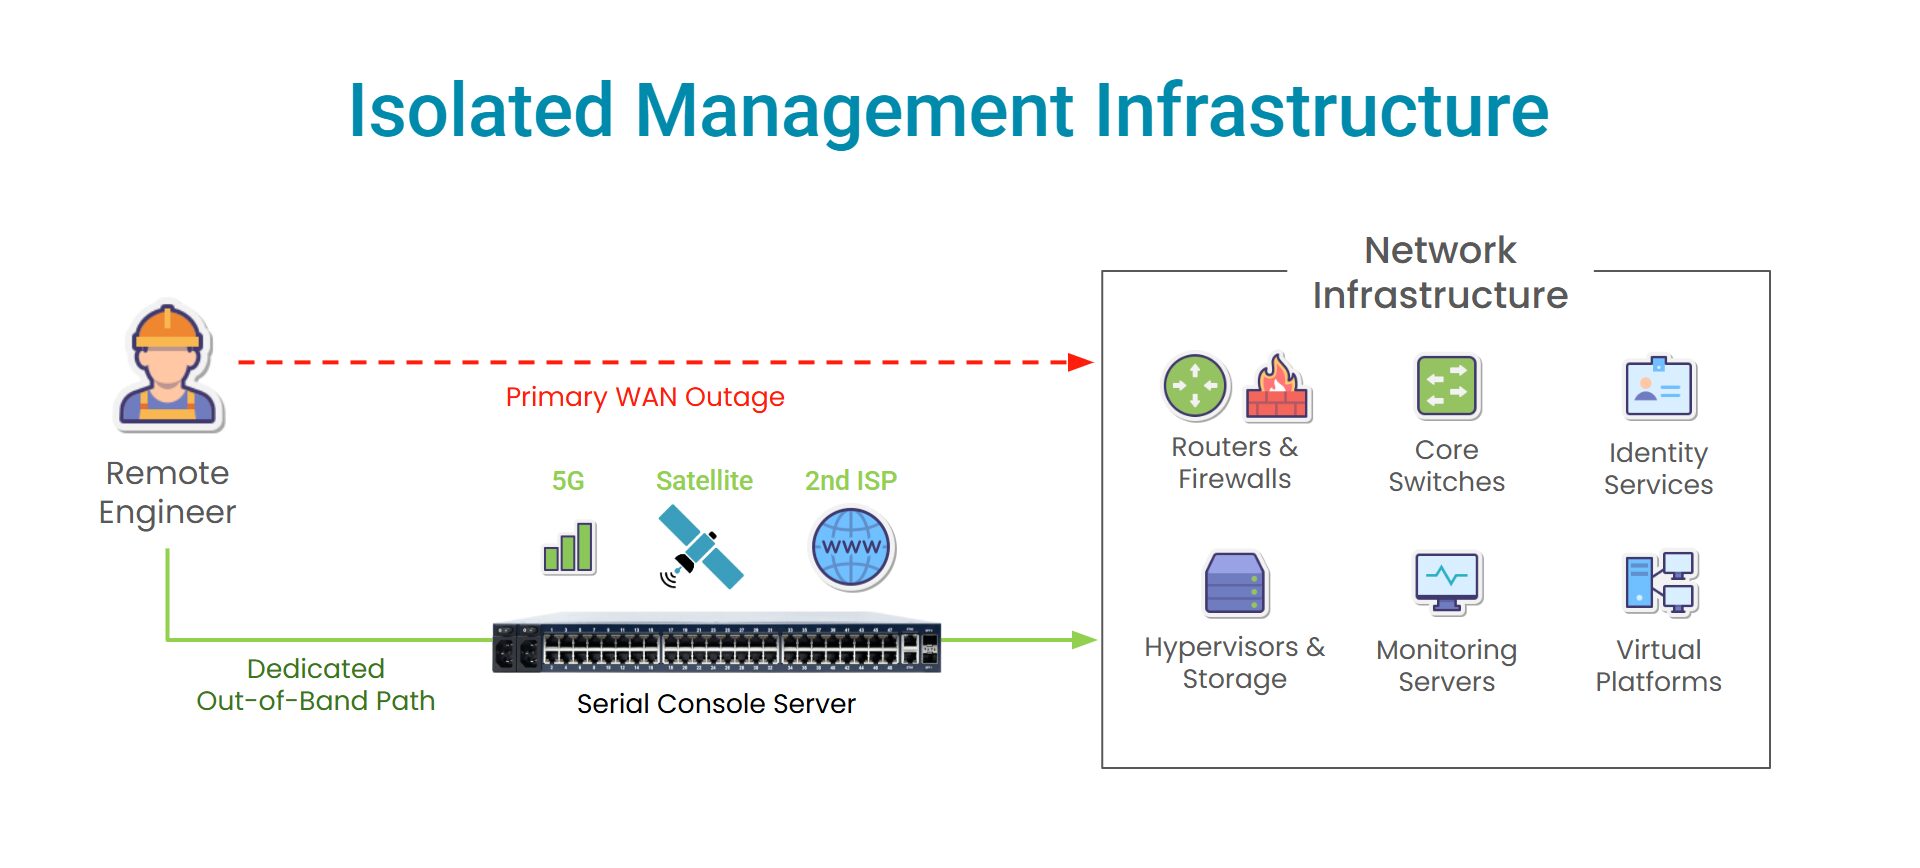
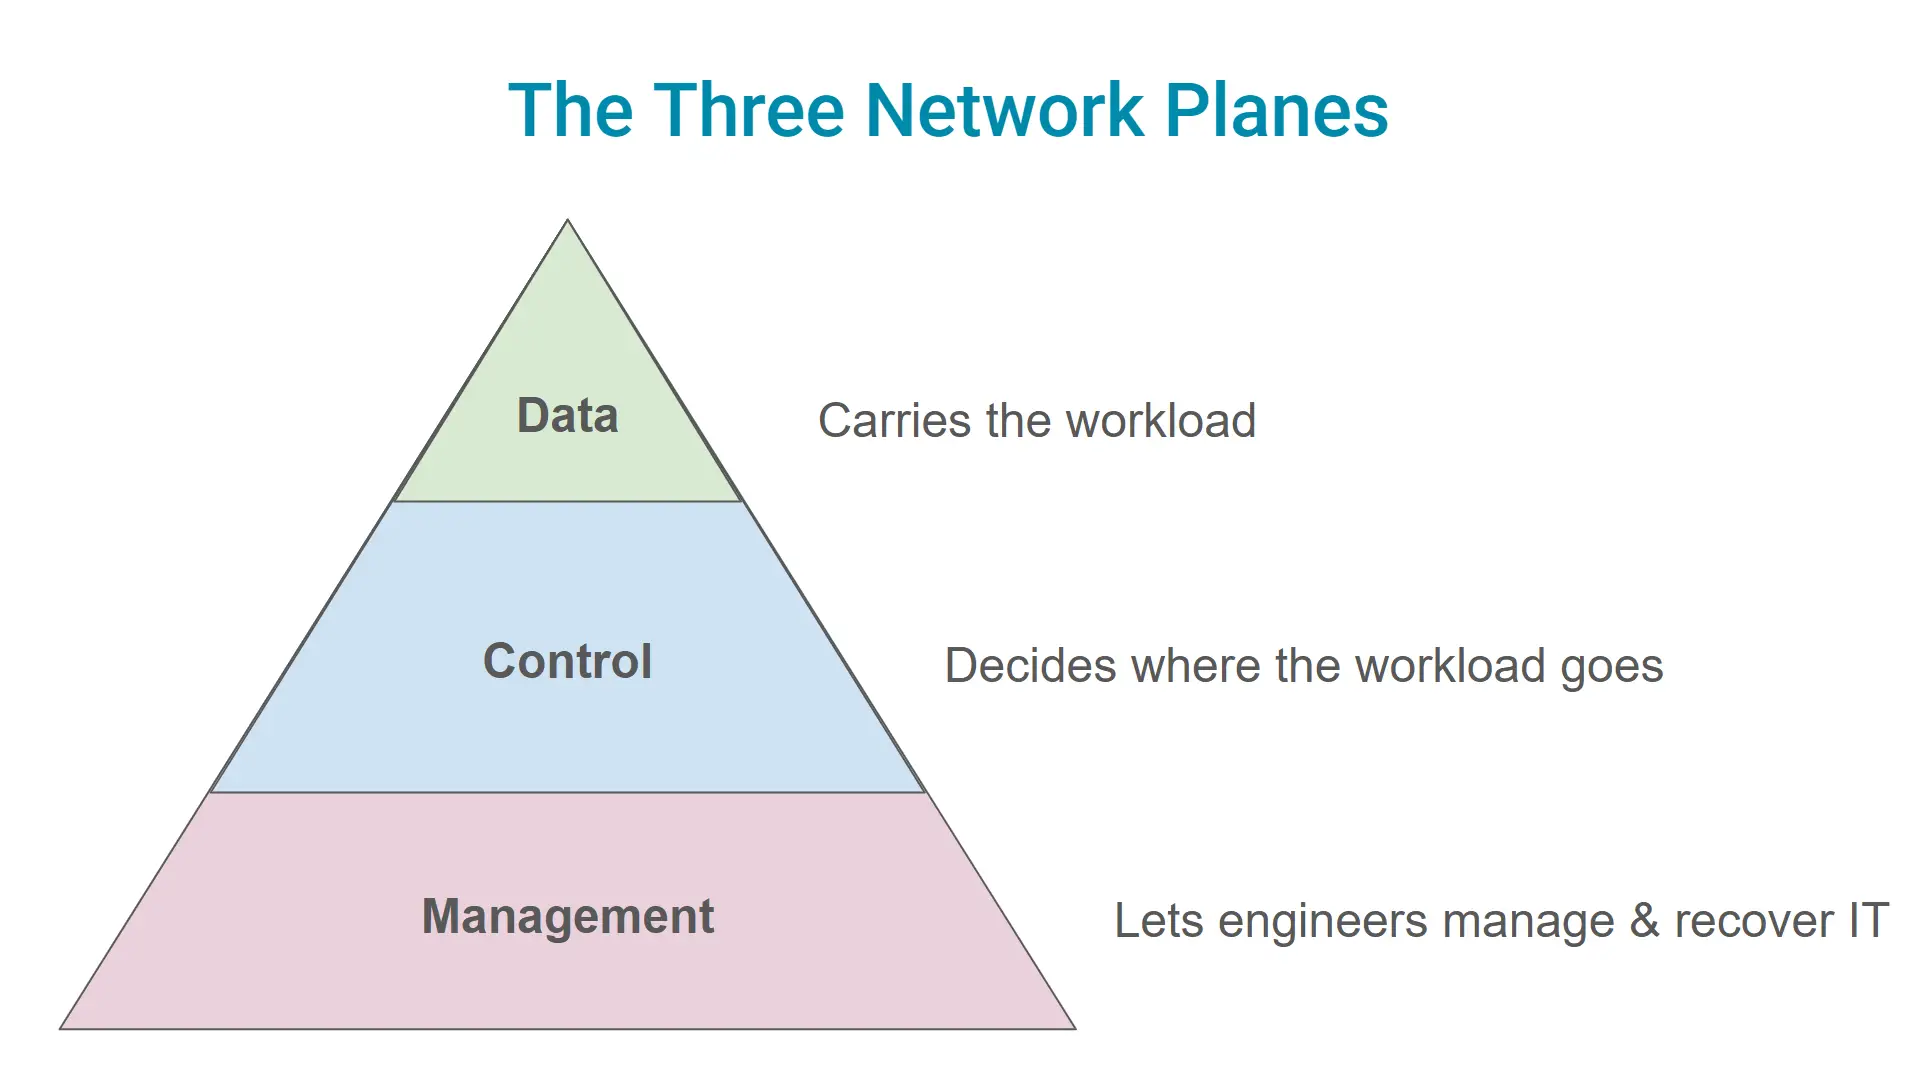
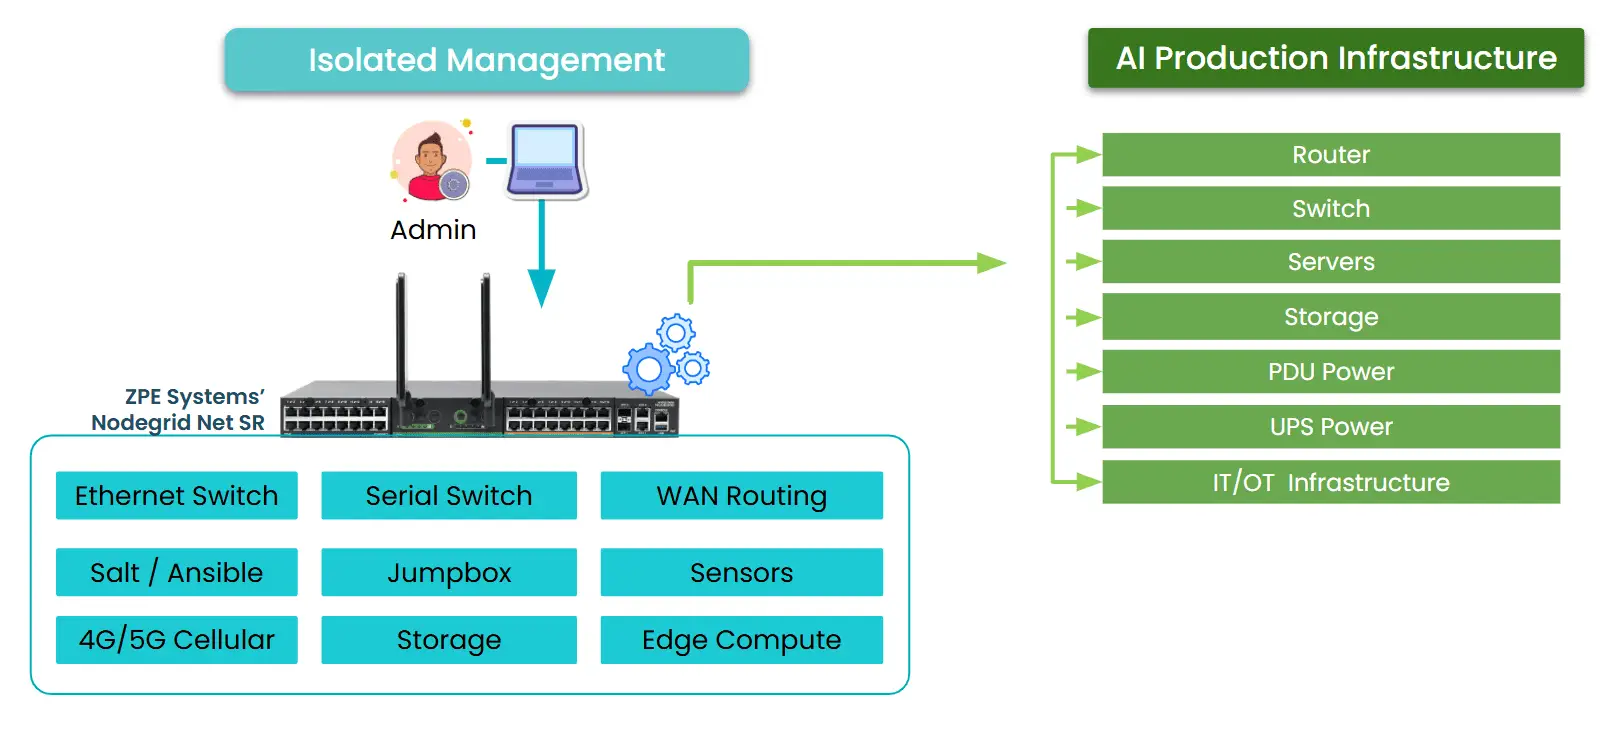
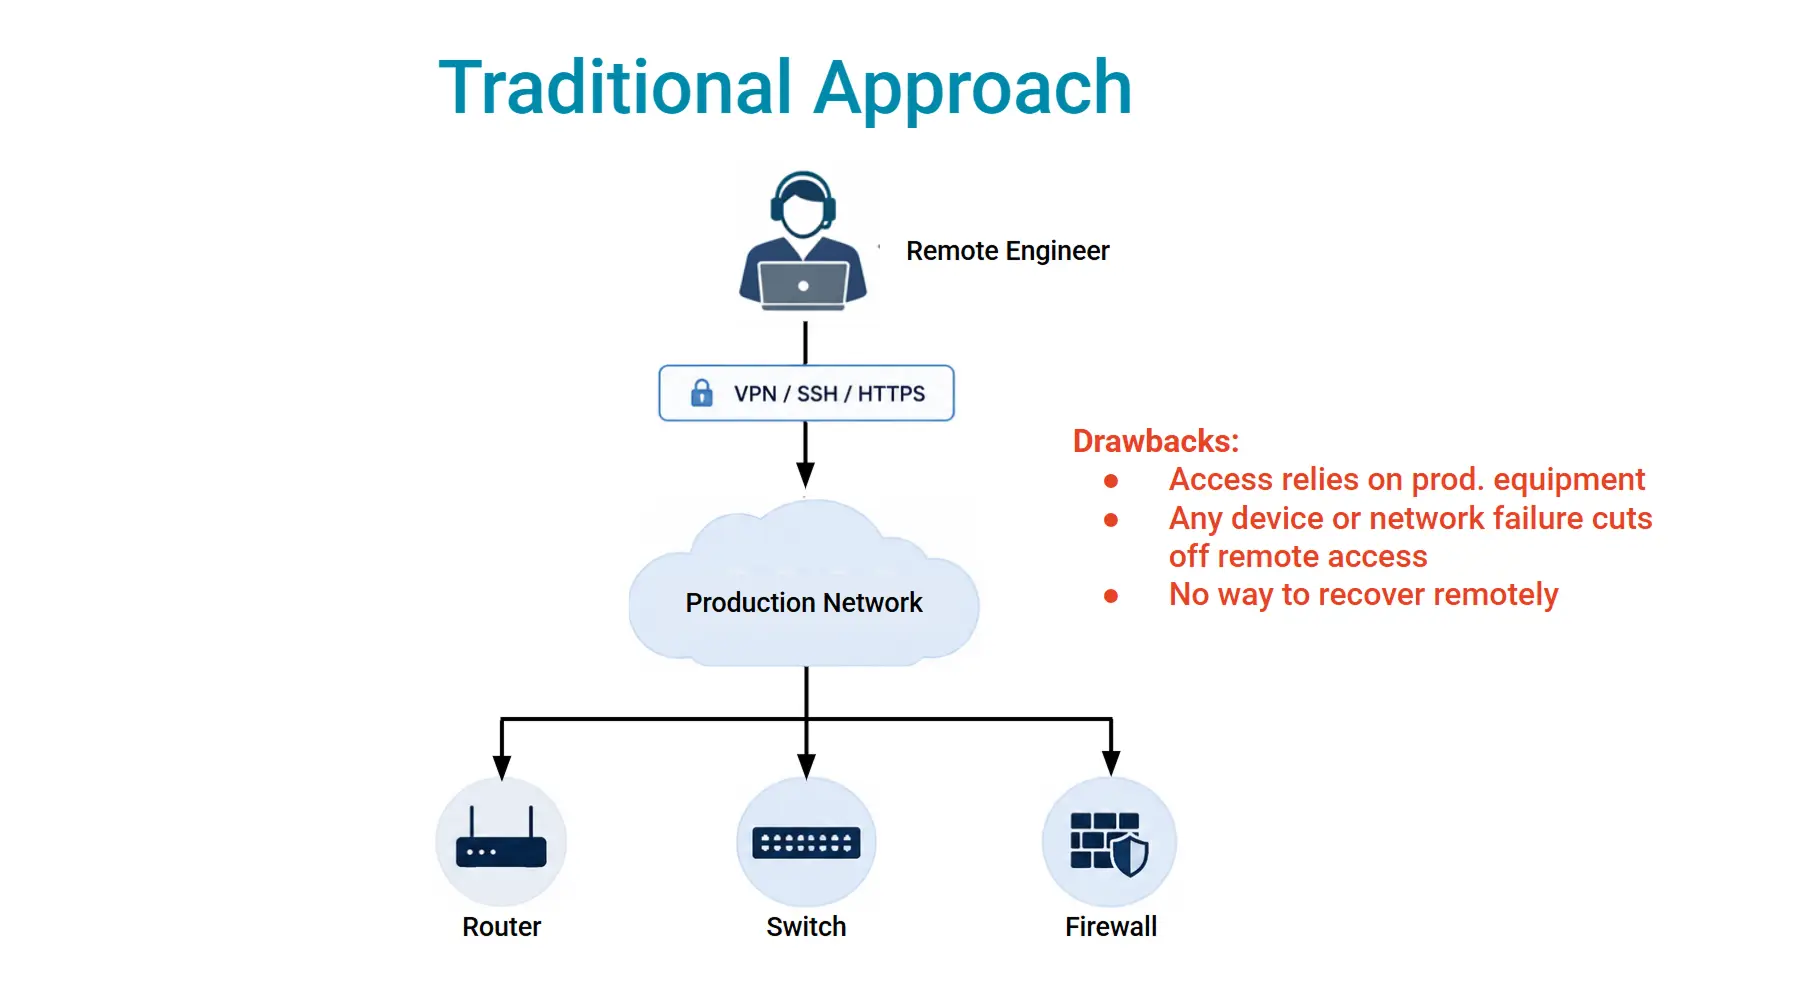
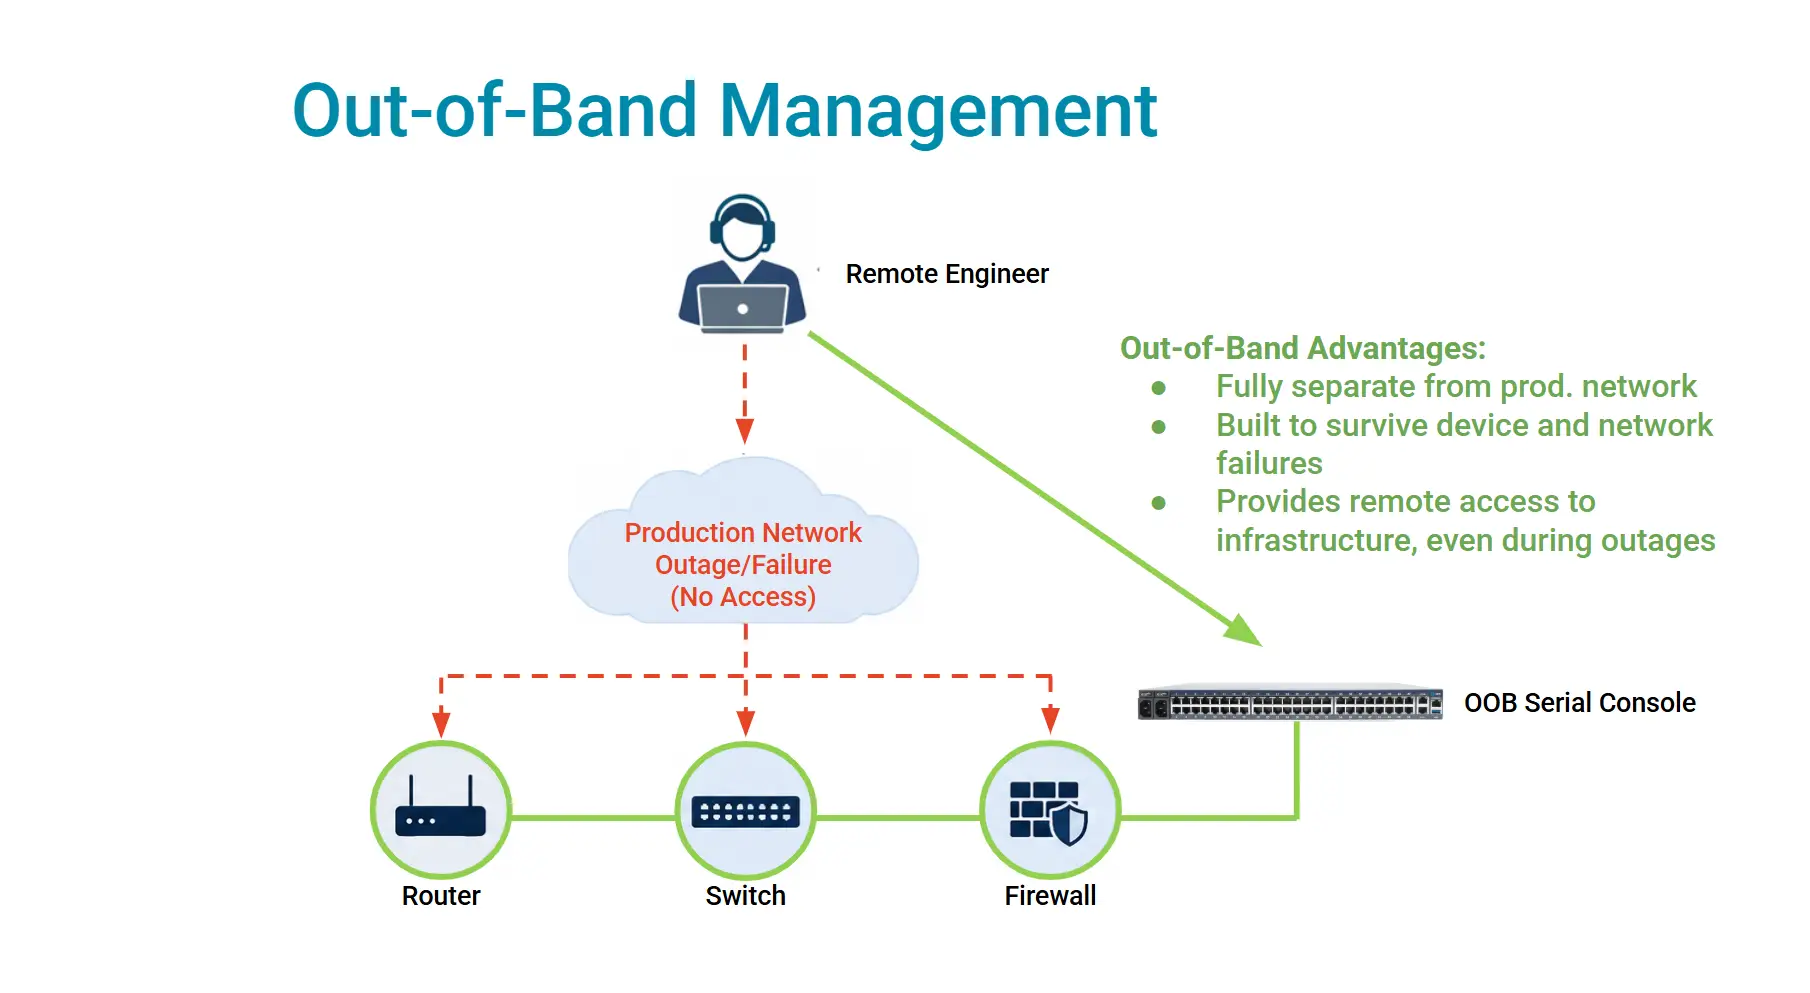
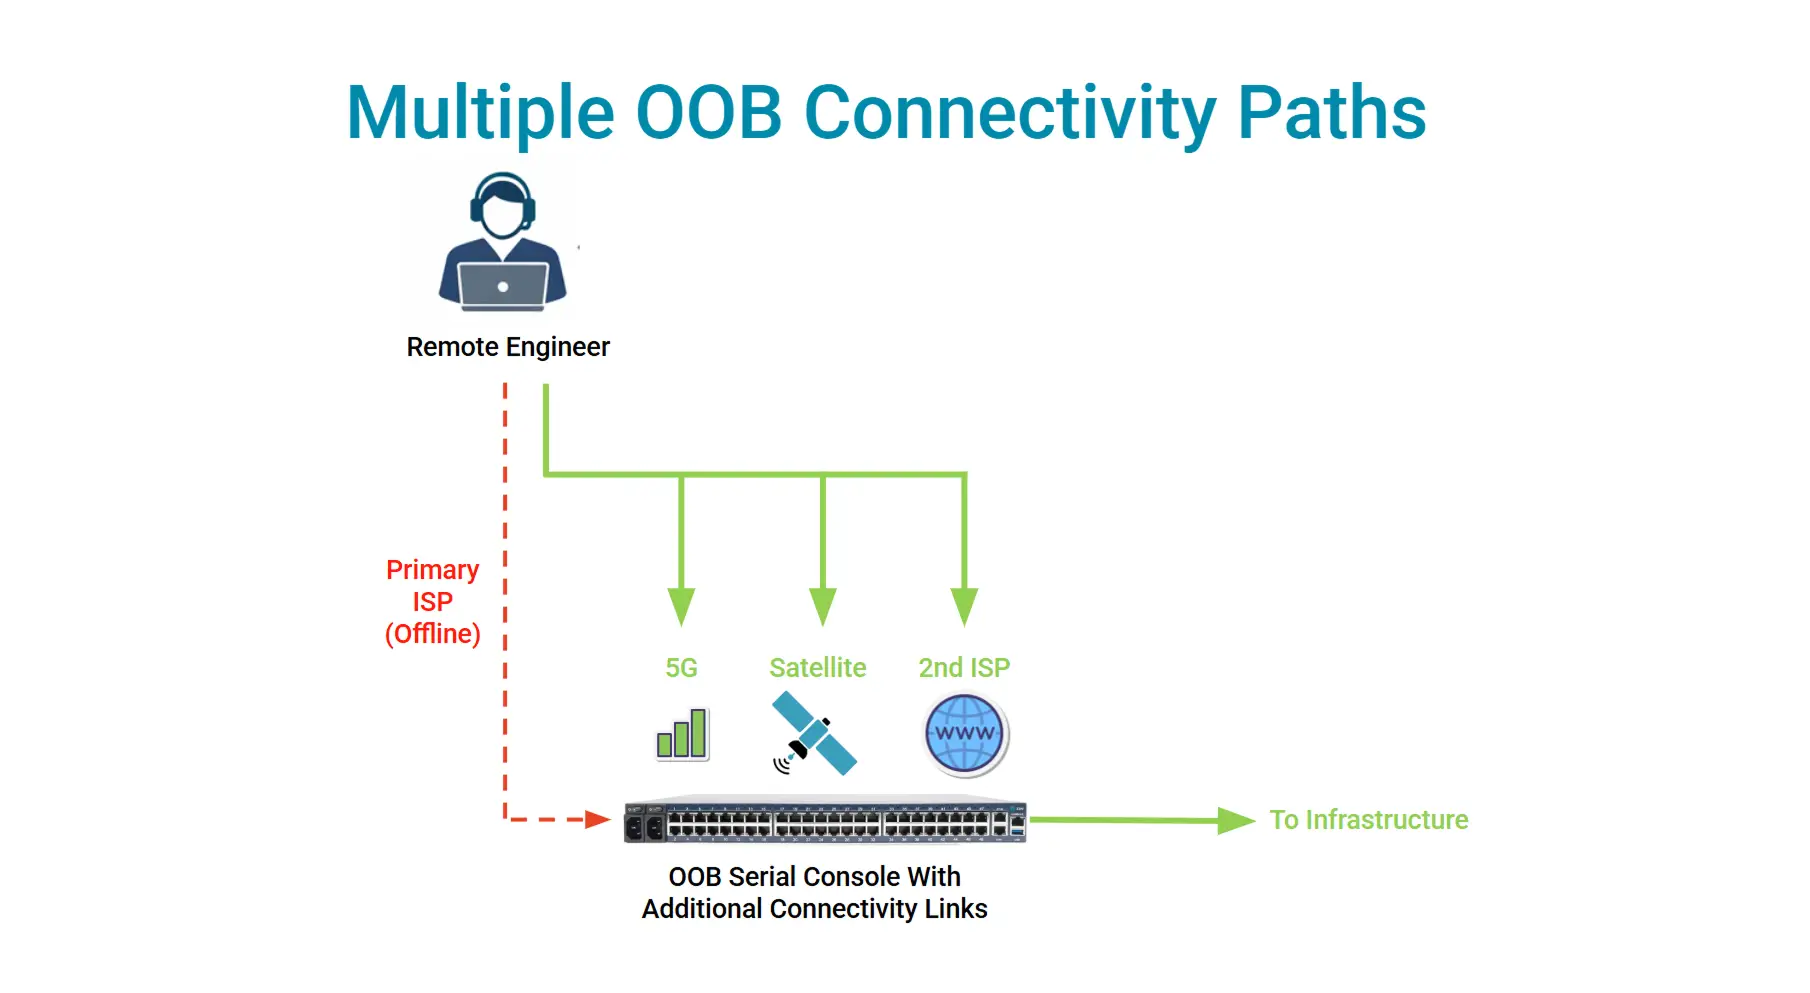
Image: The three network planes: The data plane, which carries the workload; the control plane, which decides where the workload goes; and the management plane, which gives engineers access to manage and recover equipment.
Where AI Infrastructure Failures Actually Happen
Control Plane Failures That Disrupt The Management Plane
Not every outage begins with a hardware failure. In fact, a lot of incidents originate in the control plane with:
- BGP policy mistakes
- OSPF adjacency failures
- EVPN/VXLAN configuration errors
- VLAN or VRF misconfigurations
- ACL changes that unintentionally block management traffic
These issues may leave routers, switches, and servers fully operational but unreachable over the production network. If management traffic shares the same infrastructure as application traffic, engineers lose SSH, API, and monitoring access right when they need it most.
This is why it’s important to completely separate the management network from the production network (more on this below).
Automation Mistakes That Create a Big Blast Radius
Infrastructure-as-Code (IaC) and network automation are great for improving consistency, but they also increase the blast radius of configuration errors. A single Ansible playbook, Terraform deployment, or automation workflow can unintentionally affect hundreds of devices simultaneously.
When that happens, engineers need a recovery path that does not depend on the production network remaining operational. This is one of the reasons out-of-band management continues to be standard practice in hyperscale and service provider environments.
GPU Clusters That Are Left Idle
AI infrastructure is built around the most expensive compute resources in the data center. Experts project global AI investments to exceed $1 trillion in 2026, and it’s easy to see why. A single GPU server can cost hundreds of thousands of dollars, and production AI clusters often consist of dozens or hundreds of these systems working together.
Model training requires GPUs to operate as a coordinated cluster. If a network issue isolates part of the cluster or prevents nodes from communicating with storage or orchestration platforms, the training job stalls or fails altogether. Even though the GPUs are powered on, they’re no longer doing productive work.
In inference environments, the impact is different but just as significant. An unreachable edge AI node that stops processing camera feeds, sensor data, or real-time transactions reduces application performance or forces workloads to fail over to other locations.
Idle hardware is just the beginning of the costs. Organizations also lose productive compute time, delay model development, miss service-level objectives (SLOs), and increase operational overhead while engineers work to restore connectivity.
No infrastructure is immune to failures, so eliminating every outage isn’t realistic. The goal instead is to minimize Mean Time to Recovery (MTTR) by giving engineers immediate access to diagnose and recover systems, so expensive GPU resources spend more time running workloads and less time waiting for someone to restore the network.
Addressing a Common Question About AI
One common response to conversations about AI resilience is: “Our AI infrastructure is already working fine. Why do we need to change anything?”
It’s a valid question. After all, if it ain’t broke…
But this underscores something we’ve been talking about for years. It’s not about redesigning networks that already work just fine. It’s about building the ultimate safety net that’ll save you from the growing operational risks of scaling your infrastructure.
Managing a GPU cluster inside a data center is completely different than managing a fleet of AI systems spread across hundreds of remote sites. Engineers need to retain visibility and control when the inevitable routing mistake, WAN outage, or misconfig happens. Resilience needs to be built into the architecture.
Resilience Should Be Built Into AI Architecture
The networking industry has spent decades designing highly available production networks through redundant links, resilient routing protocols, and fault-tolerant hardware. AI infrastructure deserves the same level of attention, but redundancy alone isn’t enough.
Traditional high-availability designs focus on strengthening the production and control planes. Equally important is strengthening the management plane and being able to confidently answer this question: “When an engineer loses connectivity to a remote GPU cluster at 2am, what path do they have to recover it?”
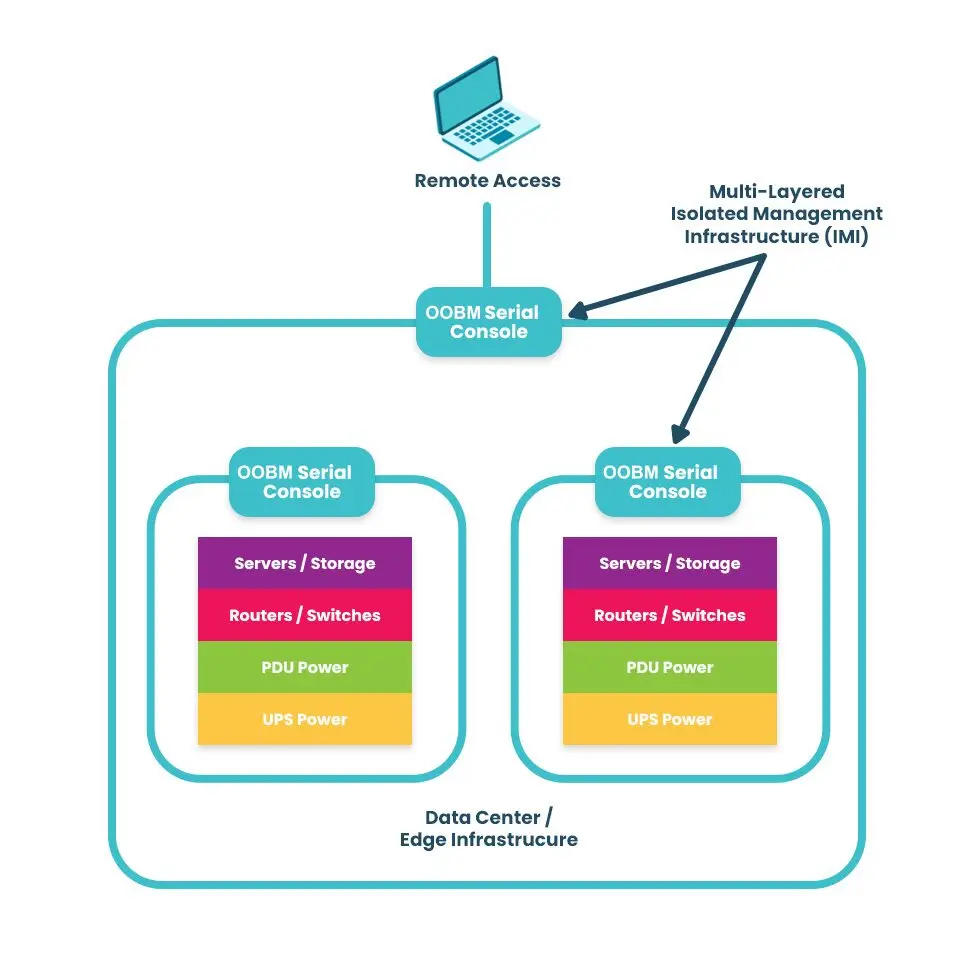
If the answer depends on the production network coming back first, the architecture still has a single point of failure. This is why it’s key to fully separate management from production. This isolation lets engineers diagnose, control, and recover AI infrastructure exactly when it matters most.
So, “Why do we need to change anything?” It’s not really about changing the architecture. It’s more about adding an alternate management path that lets you recover systems even if the production network is down.
That’s where out-of-band and IMI come in.
IMI: The Evolution of Out-of-Band
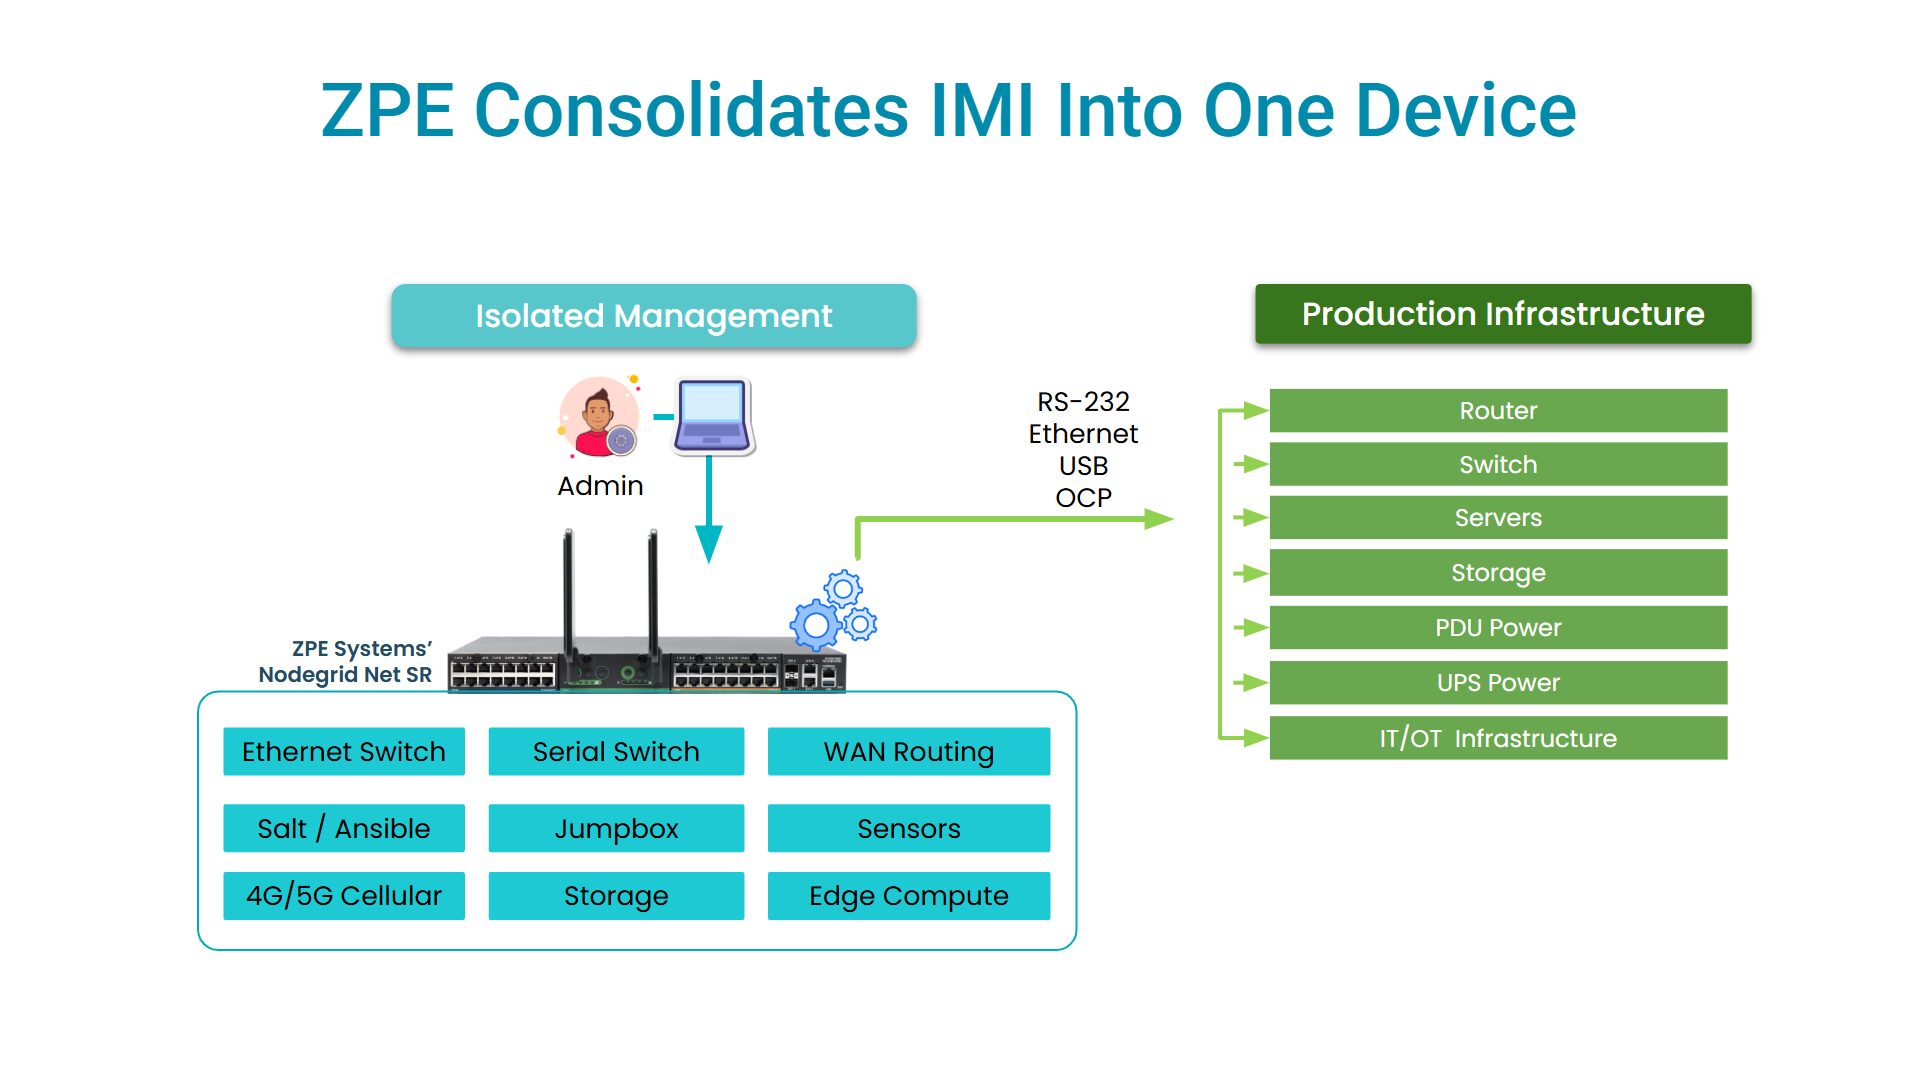
Out-of-band management is usually thought of as a console server attached to a few routers, meant to give engineers backup access in case the main network goes down. But modern out-of-band — what’s called Isolated Management Infrastructure (IMI) — has much more operational capability, including the ability to fully rebuild systems.
An IMI includes:
- Serial console access to routers, switches, firewalls, storage arrays, and GPU servers
- Independent Ethernet management interfaces
- 5G/LTE or satellite connectivity for WAN independence
- Remote power management through intelligent PDUs
- Secure jump-host capabilities with centralized authentication
- Automated recovery workflows triggered by monitoring platforms