Providing Out-of-Band Connectivity to Mission-Critical IT Resources

Why network resilience requires Isolated Management Infrastructure

Isolated Management Infrastructure

Summary

Business relies on network resilience. But network management now requires more than a ‘break/fix’ approach. Decentralized and growing architectures are spread across cloud, premises, and large IoT footprints. For shrinking IT teams, this presents resilience problems, as many are unaware of the best practice to help them care for their vast digital estate, maintain complex and delicate architecture, and recover quickly in case of attack. This gap means the network is a source of anxiety.

Big Tech solved these problems 10+ years ago, by doubling down on their management architectures. This best practice, which is now recommended by CISA, involves fully separating management networks from production networks into what’s called Isolated Management Infrastructure. IMI goes far beyond serial console and out-of-band access, providing the management and service delivery capabilities teams need to reduce on-site upkeep, stabilize delicate architecture, and accelerate ransomware recovery.

Big Tech’s network resilience secret lies in ZPE Systems’ Nodegrid hardware and software. Nodegrid is the only network resilience platform, delivering the Gen 3 capabilities that are required to build IMI. Now, organizations in every industry benefit from the best practices that have been trusted to run the public cloud for over a decade. Download the solution guide to get your step-by-step walkthrough on building IMI for network resilience.

Network Resilience Doesn’t Mean What it Did 20 Years Ago

Network resilience requirements have changed

Enterprise networks are like air. When they’re running smoothly, it’s easy to take them for granted, as business users and customers are able to go about their normal activities. But when customer service reps are suddenly cut off from their ticketing system, or family movie night turns into a game of “Is it my router, or the network?”, everyone notices. This is why network resilience is critical.

But, what exactly does resilience mean today? Let’s find out by looking at some recent real-world examples, the history of network architectures, and why network resilience doesn’t mean what it did 20 years ago.

Why does network resilience matter?

There’s no shortage of real-world examples showing why network resilience matters. The takeaway is that network resilience is directly tied to business, which means that it impacts revenue, costs, and risks. Here is a brief list of resilience-related incidents that occurred in 2023 alone:

  • FAA (Federal Aviation Administration) – An overworked contractor unintentionally deleted files, which delayed flights nationwide for an entire day.
  • Southwest Airlines – A firewall configuration change caused 16,000 flight cancellations and cost the company about $1 billion.
  • MOVEit FTP exploit – Thousands of global organizations fell victim to a MOVEit vulnerability, which allowed attackers to steal personal data for millions.
  • MGM Resorts – A human exploit and lack of recovery systems let an attack persist for weeks, causing millions in losses per day.
  • Ragnar Locker attacks – Several large organizations were locked out of IT systems for days, which slowed or halted customer operations worldwide.

What does network resilience mean?

Based on the examples above, it might seem that network resilience could mean different things. It might mean having backups of golden configs that you could easily restore in case of a mistake. It might mean beefing up your security and/or replacing outdated systems. It might mean having recovery processes in place.

So, which is it?

The answer is, it’s all of these and more.

Donald Firesmith (Carnegie Mellon) defines resilience this way: “A system is resilient if it continues to carry out its mission in the face of adversity (i.e., if it provides required capabilities despite excessive stresses that can cause disruptions).”

Network resilience means having a network that continues to serve its essential functions despite adversity. Adversity can stem from human error, system outages, cyberattacks, and even natural disasters that threaten to degrade or completely halt normal network operations. Achieving network resilience requires the ability to quickly address issues ranging from device failures and misconfigurations, to full-blown ISP outages and ransomware attacks.

The problem is, this is now much more difficult than it used to be.

How did network resilience become so complicated?

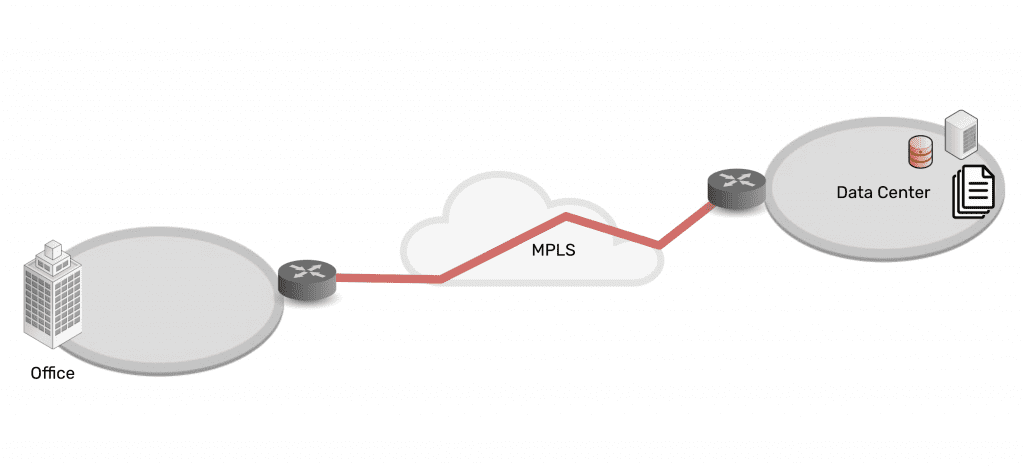
Twenty years ago, IT teams managed a centralized architecture. The data center was able to serve end-users and customers with the minimal services they needed. Being “constantly connected” wasn’t a concern for most people. For the business, achieving resilience was as simple as going on-site or remoting-in via serial console to fix issues at the data center.

Network architecture showing simplicity of data center connected via MPLS to branch office

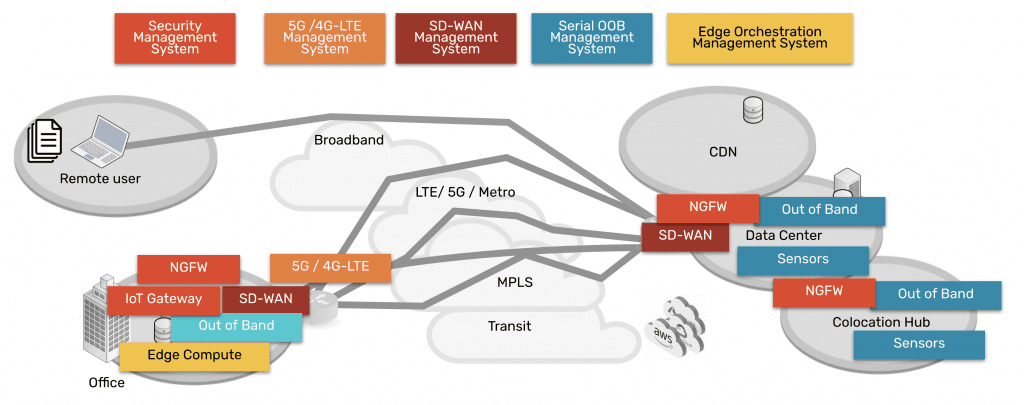
Then in the mid-2000s, the advent of the cloud changed everything. Infrastructure, data, and computing became decentralized into a distributed mix of on-prem and cloud solutions. Users could connect from anywhere, and on-demand services allowed people to be plugged in around-the-clock. Services for work, school, and entertainment could be delivered anytime, no matter where users were.

Network architecture showing complexity of data center, CDN, remote user, branch office, all connected via many paths

Behind the scenes, this explosion of architecture created three problems for achieving network resilience, which a simple serial could no longer fix:

Too Much Work

Infrastructure, data, and computing are widely distributed. Systems inevitably break and require work, but teams don’t have the staff to keep up.

Too Much Complexity

Pairing cloud and box-based stacks creates complex networks. Teams leave systems outdated, because they don’t want to break this delicate architecture.

Too Much Risk

Unpatched, outdated systems are prime targets for packaged attacks that move at machine speed. Defense requires recovery tools that teams don’t have.

Enabling businesses to be resilient in the modern age requires an approach that’s different than simply deploying a serial console for remote troubleshooting. Gen 1 and 2 serial consoles, which have dominated the market for 20 years, were designed to solve basic issues by offering limited remote access and some automation. The problem is, these still leave teams lacking the confidence to answer questions like:

  • “How can we guarantee access to fix stuff that breaks, without rolling trucks?”
  • “Can we automate change management, without fear of breaking the network?”
  • “Attacks are inevitable — How do we stop hackers from cutting off our access?”

Hyperscalers, Internet Service Providers, Big Tech, and even the military have a resilience model that they’ve proven over the last decade. Their approach involves fully isolating command and control from data and user environments. This allows them to not only gain low-level remote access to maintain and fix systems, but also to “defend the hill” and maintain control if systems are compromised or destroyed.

This approach uses something called Isolated Management Infrastructure (IMI).

Isolated Management Infrastructure is the best practice for network resilience

Isolated Management Infrastructure is the practice of creating a management network that is completely separate from the production network. Most IT teams are familiar with out-of-band management as this network; IMI, however, provides many capabilities that can’t be hosted on a traditional serial console or OOB network. And with increasing vulnerabilities, CISA issued a binding directive specifically calling for organizations to implement IMI.

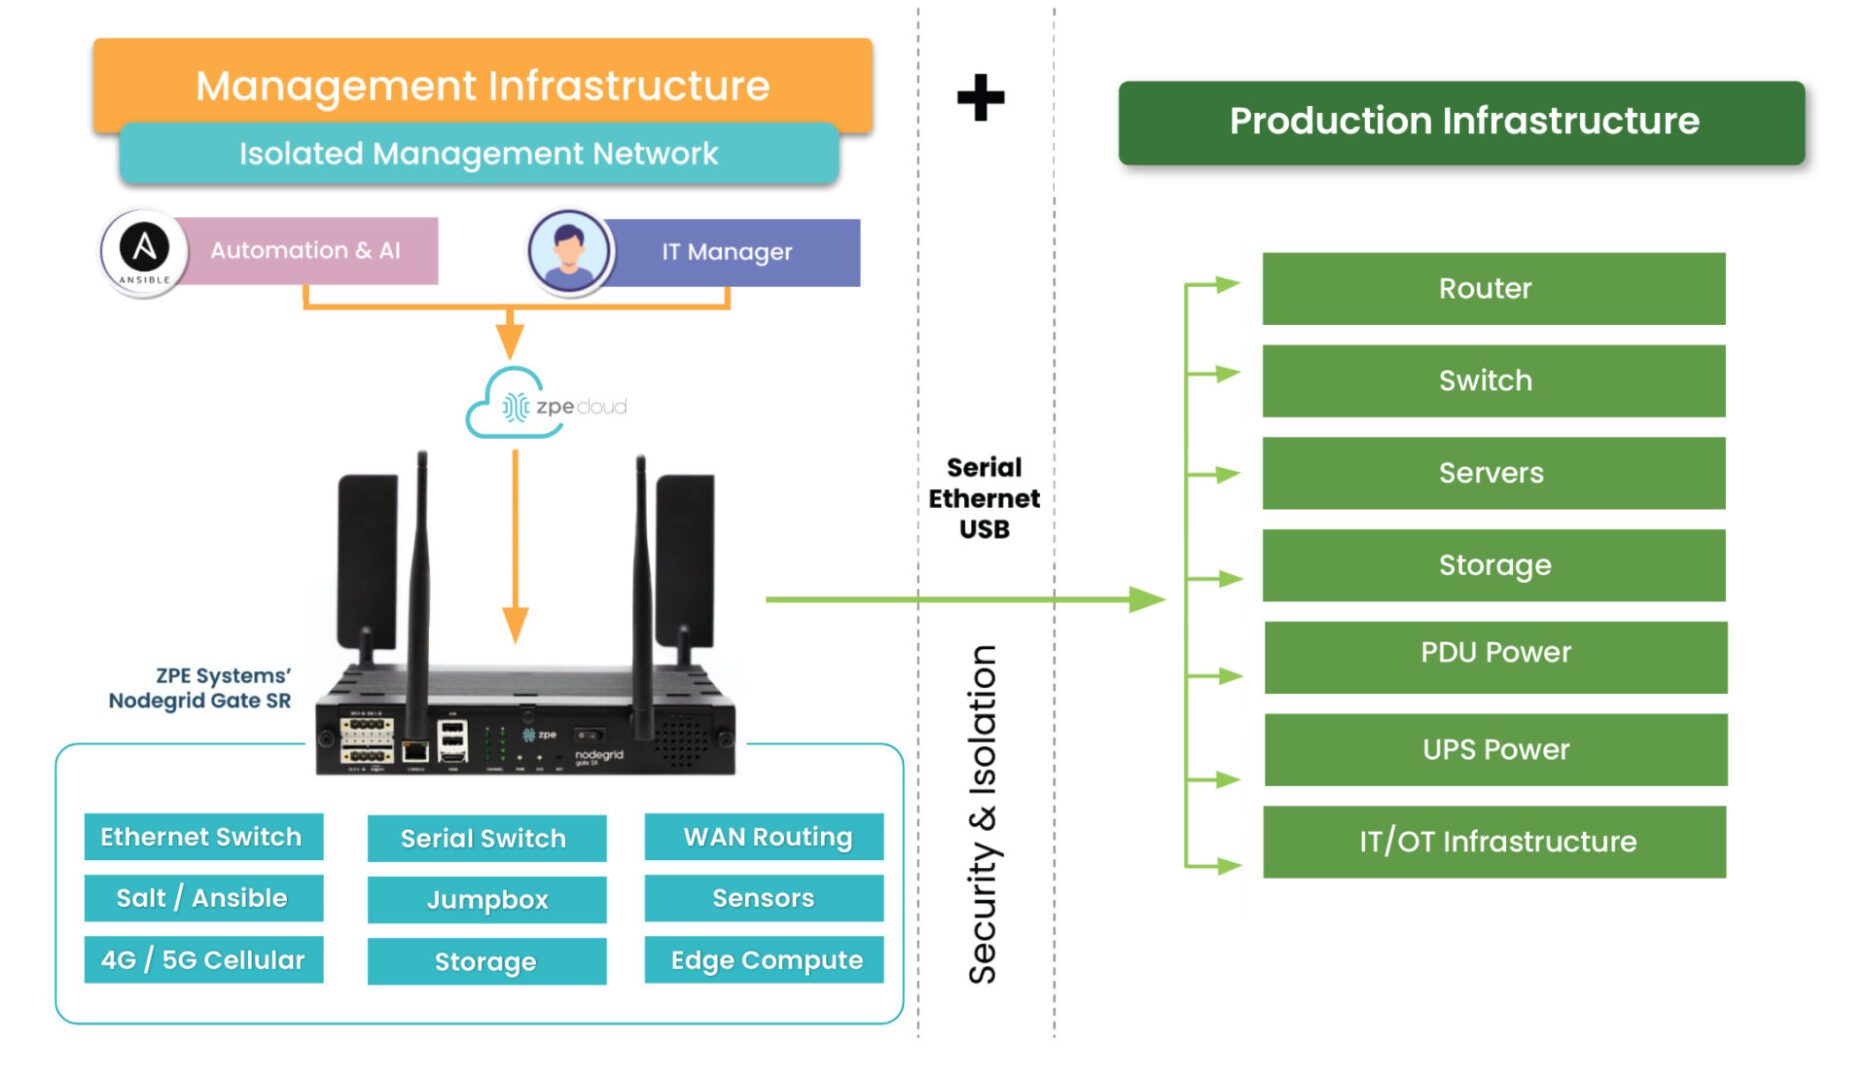
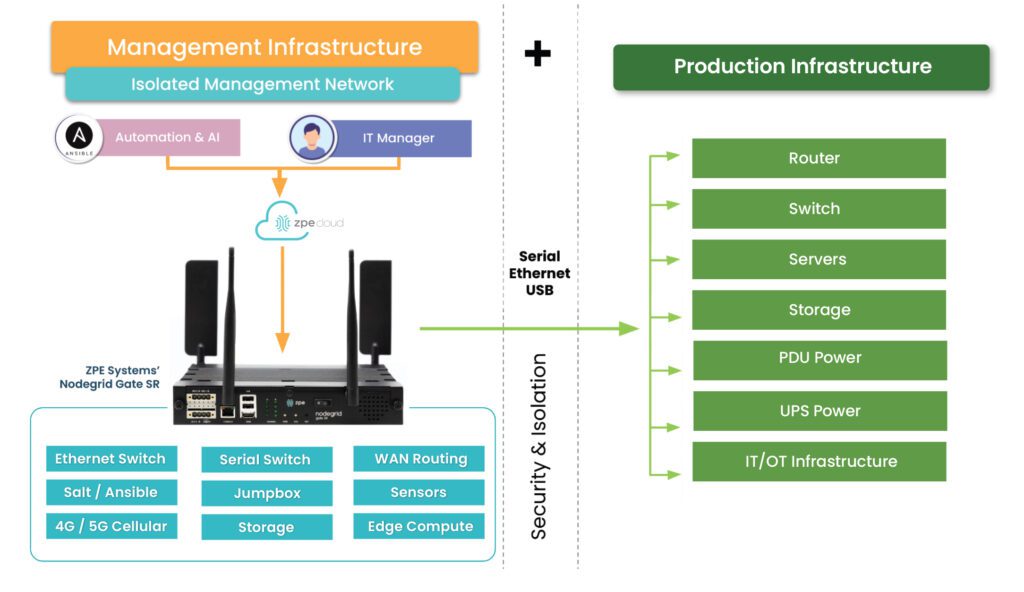
Isolated Management Infrastructure using Gen 3 serial consoles, like ZPE Systems’ Nodegrid devices, provides more than simple remote access and automation. Similar to a proper out-of-band network, IMI is completely isolated from production assets. This means there are no dependencies on production devices or connections, and management interfaces are not exposed to the internet or production gear. In the event of an outage or attack, teams retain management access, and this is just the beginning of the benefits of having IMI.

A network architecture diagram showing Isolated Management Infrastructure next to production infrastructure

IMI includes more than nine functions that are required for teams to fully service their production assets. These include:

  • Low-level access to all management interfaces, including serial, Ethernet, USB, IPMI, and others, to guarantee remote access to the entire environment
  • Open, edge-native automation to ensure services can continue operating in the event of outages or change errors
  • Computing, storage, and jumpbox capabilities that can natively host the apps and tools to deploy an IRE, to ensure fast, effective recovery from attacks

Get the guide to build IMI

ZPE Systems has worked alongside Big Tech to fulfill their requirements for IMI. In doing so, we created the Network Automation blueprint as a technical guide to help any organization build their own Isolated Management Infrastructure. Download the blueprint now to get started.

Edge Computing Requirements

Edge computing requirements displayed in a digital interface wheel.

The Internet of Things (IoT) and remote work capabilities have allowed many organizations to conduct critical business operations at the enterprise network’s edges. Wearable medical sensors, automated industrial machinery, self-service kiosks, and other edge devices must transmit data to and from software applications, machine learning training systems, and data warehouses in centralized data centers or the cloud. Those transmissions eat up valuable MPLS bandwidth and are attractive targets for cybercriminals.

Edge computing involves moving data processing systems and applications closer to the devices that generate the data at the network’s edges. Edge computing can reduce WAN traffic to save on bandwidth costs and improve latency. It can also reduce the attack surface by keeping edge data on the local network or, in some cases, on the same device.

Running powerful data analytics and artificial intelligence applications outside the data center creates specific challenges. For example, space is usually limited at the edge, and devices might be outdoors where power and climate control are more complex. This guide discusses the edge computing requirements for hardware, networking, availability, security, and visibility to address these concerns.

Edge computing requirements

The primary requirements for edge computing are:

1. Compute

As the name implies, edge computing requires enough computing power to run the applications that process edge data. The three primary concerns are:

  • Processing power: CPUs (central processing units), GPUs (graphics processing units), or SoCs (systems on chips)
  • Memory: RAM (random access memory)
  • Storage: SSDs (solid state drives), SCM (storage class memory), or Flash memory
  • Coprocessors: Supplemental processing power needed for specific tasks, such as DPUs (data processing units) for AI

The specific edge computing requirements for each will vary, as it’s essential to match the available compute resources with the needs of the edge applications.

2. Small, ruggedized chassis

Space is often quite limited in edge sites, and devices may not be treated as delicately as they would be in a data center. Edge computing devices must be small enough to squeeze into tight spaces and rugged enough to handle the conditions they’ll be deployed in. For example, smart cities connect public infrastructure and services using IoT and networking devices installed in roadside cabinets, on top of streetlights, and in other challenging deployment sites. Edge computing devices in other applications might be subject to constant vibrations from industrial machinery, the humidity of an offshore oil rig, or even the vacuum of outer space.

3. Power

In some cases, edge deployments can use the same PDUs (power distribution units) and UPSes (uninterruptible power supplies) as a data center deployment. Non-traditional implementations, which might be outdoors, underground, or underwater, may require energy-efficient edge computing devices using alternative power sources like batteries or solar.

4. Wired & wireless connectivity

Edge computing systems must have both wired and wireless network connectivity options because organizations might deploy them somewhere without access to an Ethernet wall jack. Cellular connectivity via 4G/5G adds more flexibility and ideally provides network failover/out-of-band capabilities.

5. Out-of-band (OOB) management

Many edge deployment sites don’t have any IT staff on hand, so teams manage the devices and infrastructure remotely. If something happens to take down the network, such as an equipment failure or ransomware attack, IT is completely cut off and must dispatch a costly and time-consuming truck roll to recover. Out-of-band (OOB) management creates an alternative path to remote systems that doesn’t rely on any production infrastructure, ensuring teams have continuous access to edge computing sites even during outages.

6. Security

Edge computing reduces some security risks but can create new ones. Security teams carefully monitor and control data center solutions, but systems at the edge are often left out. Edge-centric security platforms such as SSE (Security Service Edge) help by applying enterprise Zero Trust policies and controls to edge applications, devices, and users. Edge security solutions often need hardware to host agent-based software, which should be factored into edge computing requirements and budgets. Additionally, edge devices should have secure Roots of Trust (RoTs) that provide cryptographic functions, key management, and other features that harden device security.

7. Visibility

Because of a lack of IT presence at the edge, it’s often difficult to catch problems like high humidity, overheating fans, or physical tampering until they affect the performance or availability of edge computing systems. This leads to a break/fix approach to edge management, where teams spend all their time fixing issues after they occur rather than focusing on improvements and innovations. Teams need visibility into environmental conditions, device health, and security at the edge to fix issues before they cause outages or breaches.

Streamlining edge computing requirements

An edge computing deployment designed around these seven requirements will be more cost-effective while avoiding some of the biggest edge hurdles. Another way to streamline edge deployments is with consolidated, vendor-neutral devices that combine core networking and computing capabilities with the ability to integrate and unify third-party edge solutions. For example, the Nodegrid platform from ZPE Systems delivers computing power, wired & wireless connectivity, OOB management, environmental monitoring, and more in a single, small device. ZPE’s integrated edge routers use the open, Linux-based Nodegrid OS capable of running Guest OSes and Docker containers for your choice of third-party AI/ML, data analytics, SSE, and more. Nodegrid also allows you to extend automated control to the edge with Gen 3 out-of-band management for greater efficiency and resilience.

Want to learn more about how Nodegrid makes edge computing easier and more cost-effective?

To learn more about consolidating your edge computing requirements with the vendor-neutral Nodegrid platform, schedule a free demo!

Request a Demo

IT Infrastructure Management Best Practices

A small team uses IT infrastructure management best practices to manage an enterprise network

A single hour of downtime costs organizations more than $300,000 in lost business, making network and service reliability critical to revenue. The biggest challenge facing IT infrastructure teams is ensuring network resilience, which is the ability to continue operating and delivering services during equipment failures, ransomware attacks, and other emergencies. This guide discusses IT infrastructure management best practices for creating and maintaining more resilient enterprise networks.
.

What is IT infrastructure management? It’s a collection of all the workflows involved in deploying and maintaining an organization’s network infrastructure. 

IT infrastructure management best practices

The following IT infrastructure management best practices help improve network resilience while streamlining operations. Click the links on the left for a more detailed look at the technologies and processes involved with each.

Isolated Management Infrastructure (IMI)

• Protects management interfaces in case attackers hack the production network

• Ensures continuous access using OOB (out-of-band) management

• Provides a safe environment to fight through and recover from ransomware

Network and Infrastructure Automation

• Reduces the risk of human error in network configurations and workflows

• Enables faster deployments so new business sites generate revenue sooner

• Accelerates recovery by automating device provisioning and deployment

• Allows small IT infrastructure teams to effectively manage enterprise networks

Vendor-Neutral Platforms

• Reduces technical debt by allowing the use of familiar tools

• Extends OOB, automation, AIOps, etc. to legacy/mixed-vendor infrastructure

• Consolidates network infrastructure to reduce complexity and human error

• Eliminates device sprawl and the need to sacrifice features

AIOps

• Improves security detection to defend against novel attacks

• Provides insights and recommendations to improve network health for a better end-user experience

• Accelerates incident resolution with automatic triaging and root-cause analysis (RCA)

Isolated management infrastructure (IMI)

Management interfaces provide the crucial path to monitoring and controlling critical infrastructure, like servers and switches, as well as crown-jewel digital assets like intellectual property (IP). If management interfaces are exposed to the internet or rely on the production network, attackers can easily hijack your critical infrastructure, access valuable resources, and take down the entire network. This is why CISA released a binding directive that instructs organizations to move management interfaces to a separate network, a practice known as isolated management infrastructure (IMI).

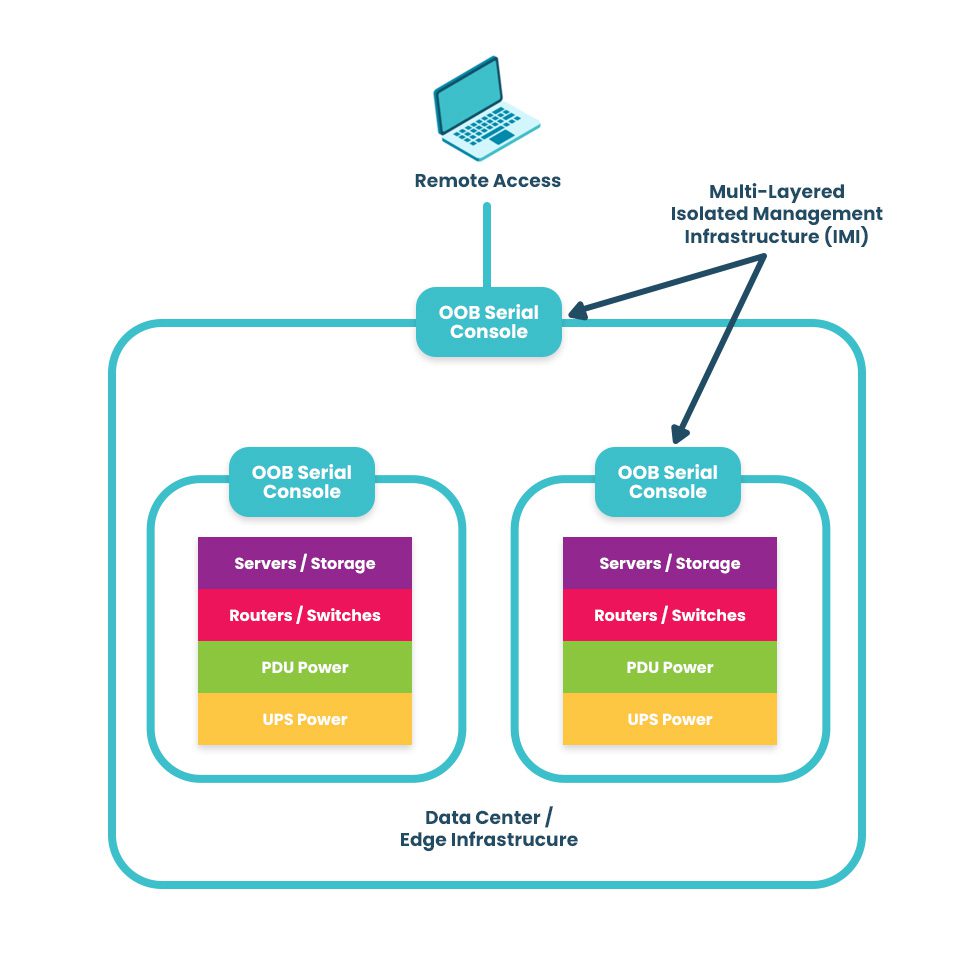
The best practice for building an IMI is to use Gen 3 out-of-band (OOB) serial consoles, which unify the management of all connected devices and ensure continuous remote access via alternative network interfaces (such as 4G/5G cellular). OOB management gives IT teams a lifeline to troubleshoot and recover remote infrastructure during equipment failures and outages on the production network. The key is to ensure that OOB serial consoles are fully isolated from production and can run the applications, tools, and services needed to fight through a ransomware attack or outage without taking critical infrastructure offline for extended periods. This essentially allows you to instantly create a virtual War Room for coordinated recovery efforts to get you back online in a matter of hours instead of days or weeks. A diagram showing a multi-layered isolated management infrastructure. An IMI using out-of-band serial consoles also provides a safe environment to recover from ransomware attacks. The pervasive nature of ransomware and its tendency to re-infect cleaned systems mean it can take companies between 1 and 6 months to fully recover from an attack, with costs and revenue losses mounting with every day of downtime. The best practice is to use OOB serial consoles to create an isolated recovery environment (IRE) where teams can restore and rebuild without risking reinfection.
.

Network and infrastructure automation

As enterprise network architectures grow more complex to support technologies like microservices applications, edge computing, and artificial intelligence, teams find it increasingly difficult to manually monitor and manage all the moving parts. Complexity increases the risk of configuration mistakes, which cause up to 35% of cybersecurity incidents. Network and infrastructure automation handles many tedious, repetitive tasks prone to human error, improving resilience and giving admins more time to focus on revenue-generating projects.

Additionally, automated device provisioning tools like zero-touch provisioning (ZTP) and configuration management tools like RedHat Ansible make it easier for teams to recover critical infrastructure after a failure or attack. Network and infrastructure automation help organizations reduce the duration of outages and allow small IT infrastructure teams to manage large enterprise networks effectively, improving resilience and reducing costs.

For an in-depth look at network and infrastructure automation, read the Best Network Automation Tools and What to Use Them For

Vendor-neutral platforms

Most enterprise networks bring together devices and solutions from many providers, and they often don’t interoperate easily. This box-based approach creates vendor lock-in and technical debt by preventing admins from using the tools or scripting languages they’re familiar with, and it makes a fragmented, complex architecture of management solutions that are difficult to operate efficiently. Organizations also end up compromising on features, ending up with a lot of stuff they don’t need and too little of what they do need.

A vendor-neutral IT infrastructure management platform allows teams to unify all their workflows and solutions. It integrates your administrators’ favorite tools to reduce technical debt and provides a centralized place to deploy, orchestrate, and monitor the entire network. It also extends technologies like OOB, automation, and AIOps to otherwise unsupported legacy and mixed-vendor solutions. Such a platform is revolutionary in the same way smartphones were – instead of needing a separate calculator, watch, pager, phone, etc., everything was combined in a single device. A vendor-neutral management platform allows you to run all the apps, services, and tools you need without buying a bunch of extra hardware. It’s a crucial IT infrastructure management best practice for resilience because it consolidates and unifies network architectures to reduce complexity and prevent human error.

Learn more about the benefits of a vendor-neutral IT infrastructure management platform by reading How To Ensure Network Scalability, Reliability, and Security With a Single Platform

AIOps

AIOps applies artificial intelligence technologies to IT operations to maximize resilience and efficiency. Some AIOps use cases include:

  • Security detection: AIOps security monitoring solutions are better at catching novel attacks (those using methods never encountered or documented before) than traditional, signature-based detection methods that rely on a database of known attack vectors.
  • Data analysis: AIOps can analyze all the gigabytes of logs generated by network infrastructure and provide health visualizations and recommendations for preventing potential issues or optimizing performance.
  • Root-cause analysis (RCA): Ingesting infrastructure logs allows AIOps to identify problems on the network, perform root-cause analysis to determine the source of the issues, and create & prioritize service incidents to accelerate remediation.

AIOps is often thought of as “intelligent automation” because, while most automation follows a predetermined script or playbook of actions, AIOps can make decisions on-the-fly in response to analyzed data. AIOps and automation work together to reduce management complexity and improve network resilience.

Want to find out more about using AIOps and automation to create a more resilient network? Read Using AIOps and Machine Learning To Manage Automated Network Infrastructure

IT infrastructure management best practices for maximum resilience

Network resilience is one of the top IT infrastructure management challenges facing modern enterprises. These IT infrastructure management best practices ensure resilience by isolating management infrastructure from attackers, reducing the risk of human error during configurations and other tedious workflows, breaking vendor lock-in to decrease network complexity, and applying artificial intelligence to the defense and maintenance of critical infrastructure.

Need help getting started with these practices and technologies? ZPE Systems can help simplify IT infrastructure management with the vendor-neutral Nodegrid platform. Nodegrid’s OOB serial consoles and integrated branch routers allow you to build an isolated management infrastructure that supports your choice of third-party solutions for automation, AIOps, and more.

Want to learn how to make IT infrastructure management easier with Nodegrid?

To learn more about implementing IT infrastructure management best practices for resilience with Nodegrid, download our Network Automation Blueprint. 

Request a Demo

Legrand Acquires ZPE Systems, Inc.

Legrand acquires ZPE Systems

Legrand Acquires Data Center, Branch, and Edge Management Infrastructure Market Leader ZPE Systems, Inc.

Customers Benefit from Enhanced and Diversified Product Development and Expanded Customer-focused, Infrastructure Solutions and Services Delivery from the Data Center to the Edge

WEST HARTFORD, CT (January 12, 2024) Legrand®, a global specialist in electrical and digital building infrastructures, including data center solutions, has announced its acquisition is complete of ZPE Systems, Inc., a Fremont, California-based company that offers critical solutions and services to deliver resilience and security for customers’ business critical infrastructure. This includes serial console servers, sensors, and services routers that enable remote access and management of network IT equipment from data centers to the edge. The acquisition brings together ZPE’s secure and open management infrastructure and services delivery platform for data center, branch, and edge environments to Legrand’s comprehensive data center solutions of overhead busway, custom cabinets, intelligent PDUs, KVM switches, and advanced fiber solutions.

ZPE Systems will become a business unit of Legrand’s Data, Power, and Control (DPC) Division. Arnaldo Zimmermann will continue to serve as Vice President and General Manager of ZPE Systems, reporting to Brian DiBella, President of Legrand’s DPC Division.

“ZPE Systems leads the fast growing and profitable data center and edge management infrastructure market. This acquisition allows Legrand to enter a promising new segment whose strong growth is expected to accelerate further with the development of artificial intelligence and associated needs,” said John Selldorff, President and CEO, Legrand, North and Central America. “Edge computing, AI and operational technology will require more complex data centers and edge infrastructure with intelligent IT needs to be built in disparate remote geographies. This makes remote management and operation a critical requirement. ZPE Systems is well positioned to address this need through high performance automation infrastructure solutions, which are complementary to our current data center offerings.”

“By joining forces with Legrand, ZPE Systems is advancing our leadership position in management infrastructure and propelling our technology and solutions to further support existing and new market opportunities,” said Zimmermann.

About Legrand and Legrand, North and Central America

Legrand is the global specialist in electrical and digital building infrastructures. Its comprehensive offering of solutions for commercial, industrial, and residential markets makes it a benchmark for customers worldwide. The Group harnesses technological and societal trends with lasting impacts on buildings with the purpose of improving lives by transforming the spaces where people live, work, and meet with electrical, digital infrastructures and connected solutions that are simple, innovative, and sustainable. Drawing on an approach that involves all teams and stakeholders, Legrand is pursuing its strategy of profitable and responsible growth driven by acquisitions and innovation, with a steady flow of new offerings—including products with enhanced value in use (faster expanding segments: data centers, connected offerings and energy efficiency programs). Legrand reported sales of €8.0 billion in 2022. The company is listed on Euronext Paris and is notably a component stock of the CAC 40 and CAC 40 ESG indexes. (code ISIN FR0010307819). https://www.legrand.us/

Read the press release on Legrand’s official site