Providing Out-of-Band Connectivity to Mission-Critical IT Resources

What the FAA Outage Teaches Us About Network Resilience

What The FAA Outage Teaches Us About Network Resilience

What happens when your primary network fails and your backup isn’t there to save you?

That was the question on September 21, when a communications failure disrupted flights across the Northeast. A telecom circuit serving an FAA facility in Philadelphia failed, and when the system attempted to use its backup, officials discovered that the backup fiber connection had also been cut during construction in New Jersey. The resulting outage led to ground stops and significant delays at major airports including Newark, Philadelphia, JFK, and LaGuardia.

This is the perfect reminder that redundancy doesn’t equal resilience.

Truly resilient architecture needs independent paths that can survive failures and give engineers a way to reach critical infrastructure when the primary network goes down. That’s where out-of-band (OOB) management becomes part of the failover strategy.

But before getting into how OOB could have helped, let’s clarify what it does – and what it doesn’t do.


Production Failover Protects Operations. OOB Failover Protects Recovery.

Let’s get one thing out of the way: out-of-band management failover wouldn’t have prevented the FAA incident. It would not have carried the radar data or controller-to-pilot communications, because these require their own separately engineered, certified, and capable (in terms of performance) production failover architecture.

OOB failover solves a different problem:
How do engineers reach the infrastructure when the network they normally use is down?


Why This Matters

During a production failure, the immediate priority is to restore connectivity. But there’s an entire recovery process that needs to happen. Engineers need to be able to access the routers, switches, firewalls, etc. to determine what failed and what they need to do to restore service.

This is the value of OOB. It doesn’t replace or take over for the production network. It gives engineers a separate path to the equipment that can help diagnose the failure, reconfigure the network, activate any available backup path, and prepare the infrastructure to resume service as soon as connectivity is restored.

Otherwise, coming back online after connectivity is restored means waiting hours for someone to physically reach the equipment, which leads to:

  • Longer recovery times
  • Additional truck rolls
  • More operational disruptions
  • Dependence on local personnel
  • Reduced visibility during an outage

In the case of the FAA, out-of-band wouldn’t have kept the network online, but it would have given engineers a way to work on the infrastructure while the production paths were unavailable. This makes all the difference for a fast recovery, and it’s why redundancy alone doesn’t provide real resilience.


Do You Have Two Connections, Or Two Paths?

There’s an adage in preparedness: two is one, one is none. But in networking, this basic redundancy doesn’t necessarily provide a buffer against outages.

If the primary and backup connections share the same carrier, physical route, or infrastructure, one incident (like a fiber cut) affects both. That’s exactly what happened in the FAA incident and left engineers unable to reach the infrastructure. It’s important to understand the difference between redundancy and resilience:

  • Redundancy asks: “Do we have a backup connection?”
  • Resilience asks: “If there’s a failure, can we still reach the infrastructure without going on-site?”

Imagine the FAA had set up a different backup, like 5G, that was immune to the fiber cut. They could have still remotely reached their infrastructure to accelerate recovery. The key to making out-of-band truly “out-of-band” is to have its own dedicated links that are completely isolated, both logically and physically, from the production network.

But what does it look like?


Building a Resilient Recovery Path

Out-of-band can use separate ISP providers (if available), MPLS, or link types that don’t rely on traditional terrestrial infrastructure, like 5G/LTE or satellite. Building this resilient out-of-band management path involves deploying serial console servers that connect to the production infrastructure, and using cellular modems, satellite connectivity, etc. that are dedicated to giving remote access to these serial console servers.
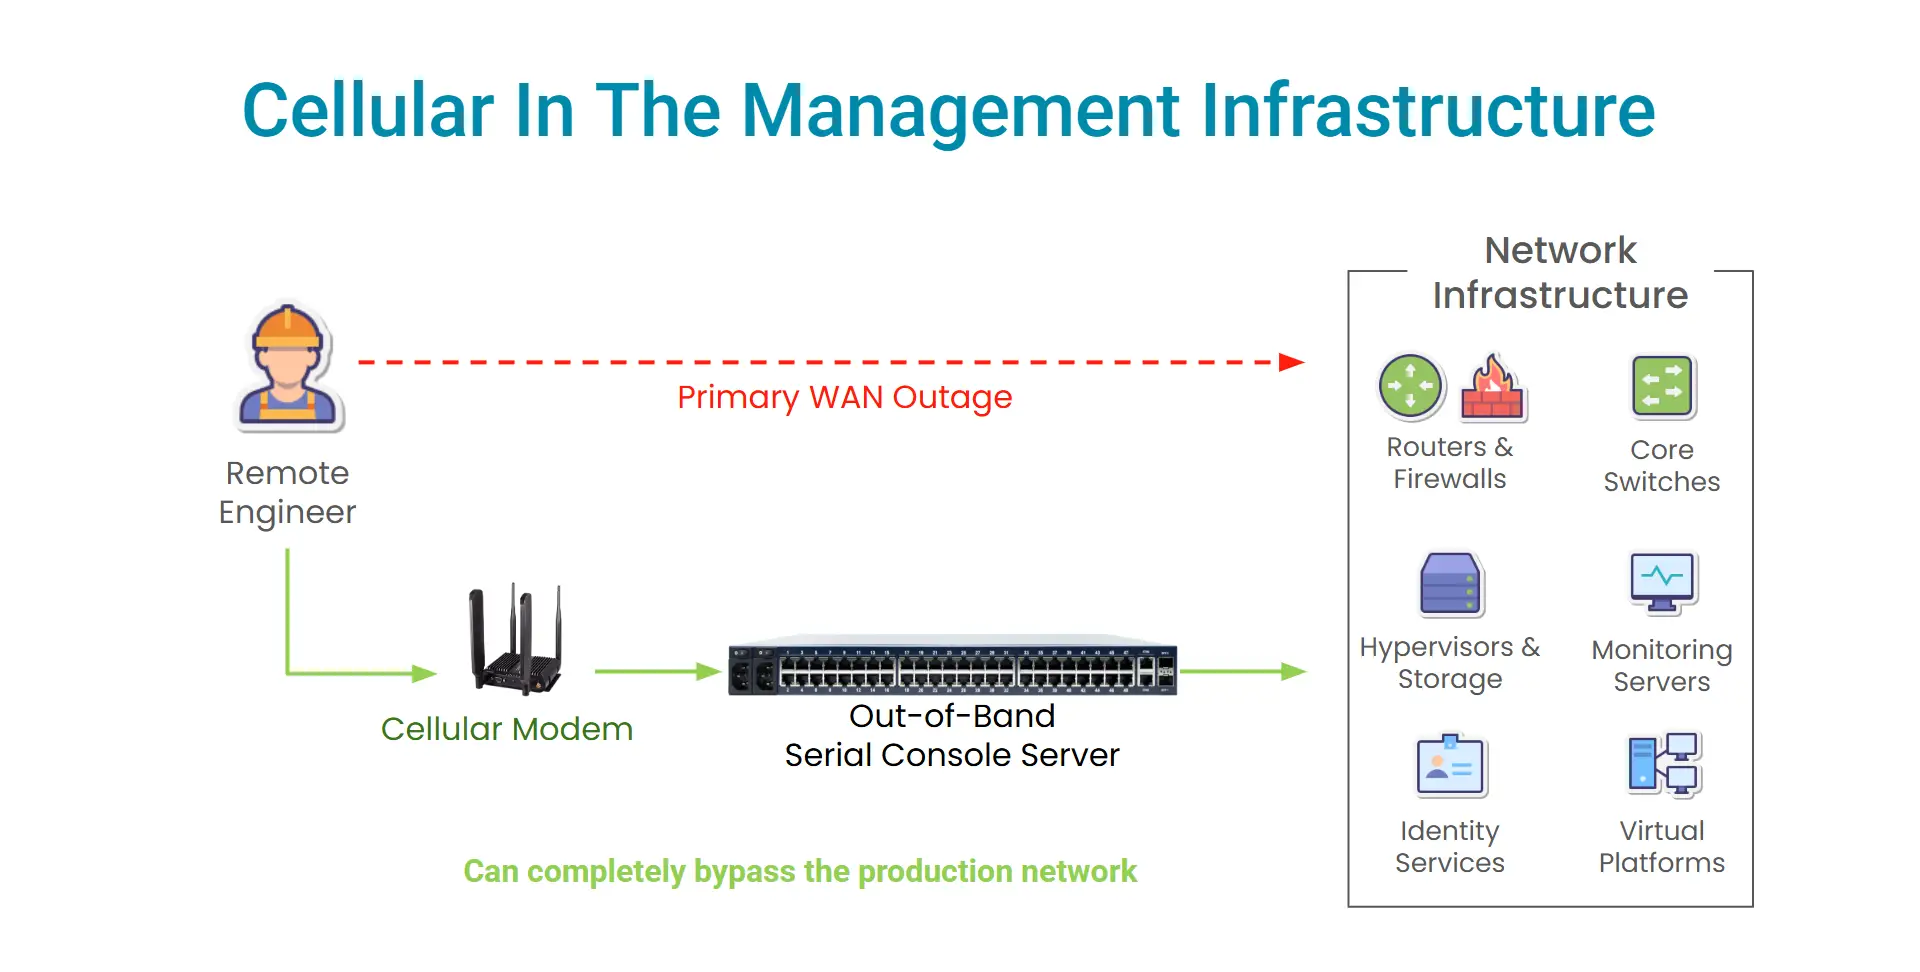
Cellular In The Management Infrastructure

This gives engineers the ability to completely bypass the production network and still remotely access all of their production infrastructure. From there, they can:

  • Diagnose failed infrastructure
  • Access device consoles
  • Change routing
  • Activate backup circuits
  • Roll back configurations
  • Restart equipment
  • Coordinate recovery across distributed sites

Think of the primary WAN as a single point of failure, and out-of-band is the safety net. When the WAN fails and operations falls apart, out-of-band catches all the pieces and makes it easier (and faster) to put everything back together.

Once your OOB path is set up and fully isolated, there’s one more crucial step to take…


Test The OOB Path

Putting the OOB infrastructure in place is a great start, but you need to make sure everything works so you don’t have a false sense of resilience. There’s nothing like trying to use your safety net in a real scenario, only to find out your SIM or APN settings aren’t configured properly.

Here are some tips:

  • Verify that your SIM cards are properly provisioned and activated, and ensure your APN settings are correct.
  • Make sure your system can detect loss of the primary connection and can automatically fail over to the backup link.
  • Test your complete recovery workflow, from failover, to troubleshooting and failback.


The Takeaway: Protect Your Recovery Path

The FAA outage showed us that a backup is only useful if it survives the failure you’re trying to protect against. But even if your backup is available, you still need a dedicated management path. This is crucial to a fast recovery because it allows you to maintain secure remote access and get your infrastructure ready for when connectivity is restored.

This is exactly why organizations are deploying the next generation of out-of-band – something called Isolated Management Infrastructure – using ZPE Systems’ Nodegrid. Nodegrid combines out-of-band, multiple failover links, centralized management, and remote recovery into a streamlined architecture.
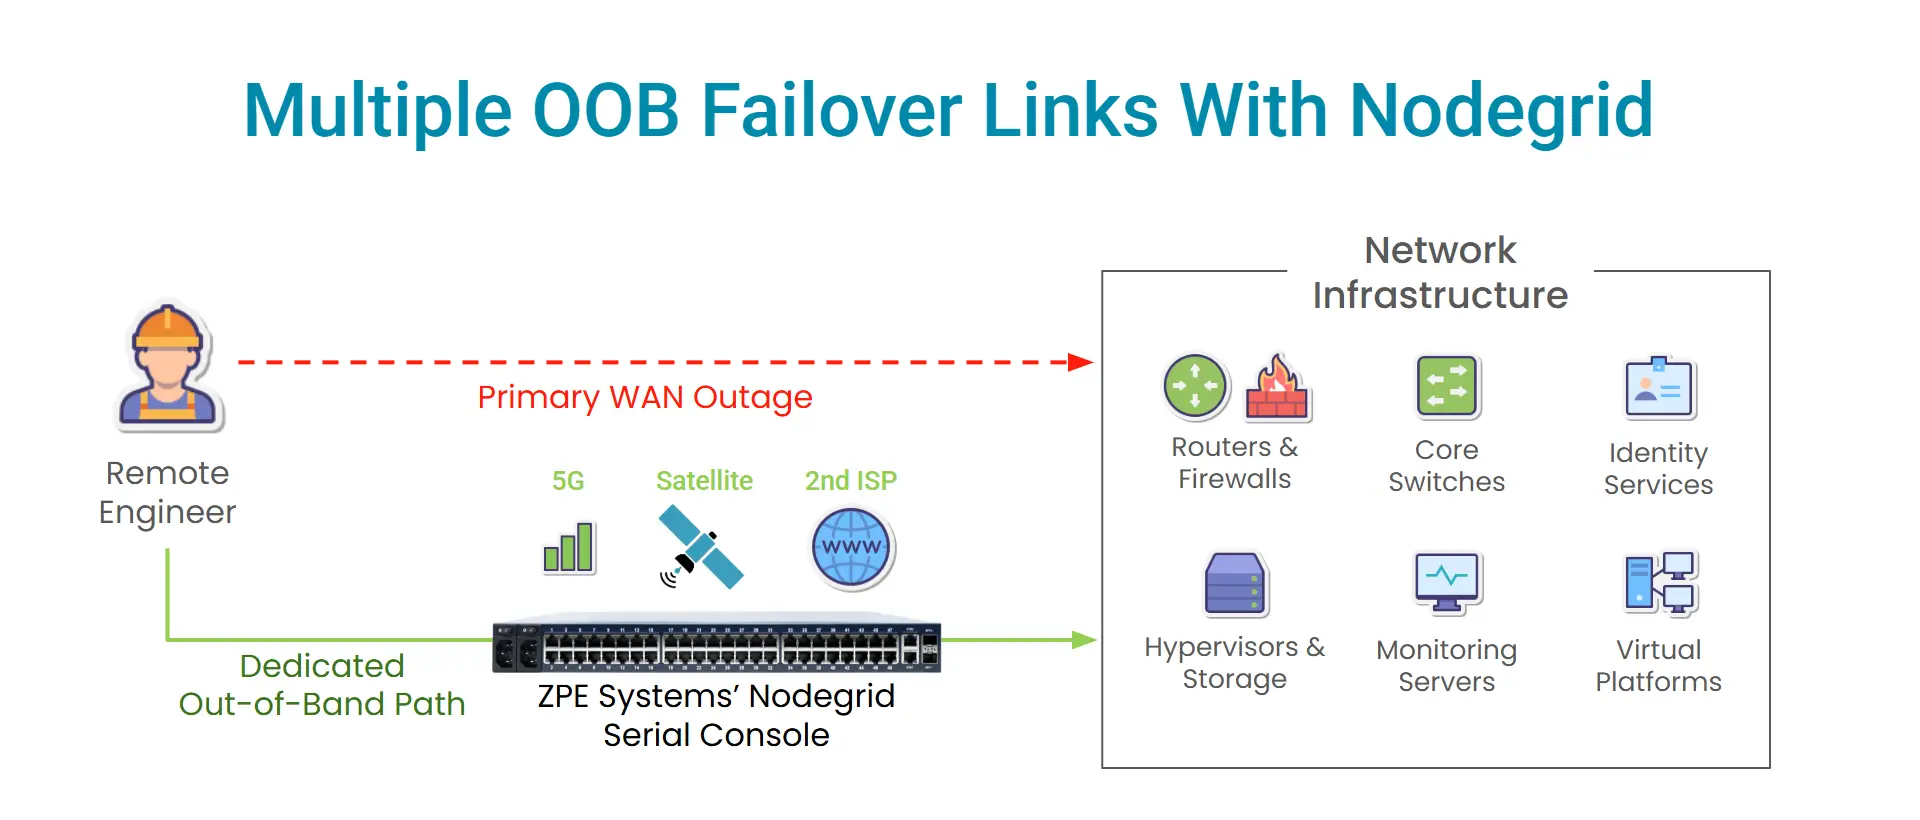
Multiple OOB Failover Links With Nodegrid

One Nodegrid device provides serial, Ethernet, and USB access to routers, switches, firewalls, servers, and the full stack of critical equipment. And when it comes to failover, Nodegrid supports 5G (via built-in modem), satellite, MPLS, and other link types without adding additional devices.

The result is an independent path that keeps critical infrastructure reachable, gives engineers the access they need to diagnose and recover problems remotely, and reduces dependence on on-site intervention.

Stay In Control When The Unexpected Happens

Download the Guide to Deploying Resilient OOB Failover

Beyond Backup Internet: 5G Failover for Network Resilience explains how cellular connectivity can provide an independent path for managing and recovering critical infrastructure when primary connectivity fails. The guide covers five key considerations for deploying cellular, satellite, or other link types as part of a broader network resilience strategy.

Download the guide and learn how to build a failover strategy that keeps you connected when your primary network goes down.

Beyond Backup Internet 5G Failover

Get in Touch For a Failover Assessment

Our engineers can help you identify where your current failover strategy may leave critical infrastructure unreachable, and where an independent management path can improve recovery.

Get in touch for a failover assessment and learn how Nodegrid can help you maintain secure access when your primary or backup network goes down.
The WAN Is the Single Point of Failure Nobody Talks About

The WAN is the Single Point of Failure Nobody Talks About

Modern IT infrastructure depends on the wide area network (WAN) to connect everything together. Data centers, branch offices, cloud environments, edge locations, and remote sites all rely on WAN connectivity to exchange data, run applications, and maintain centralized operations.

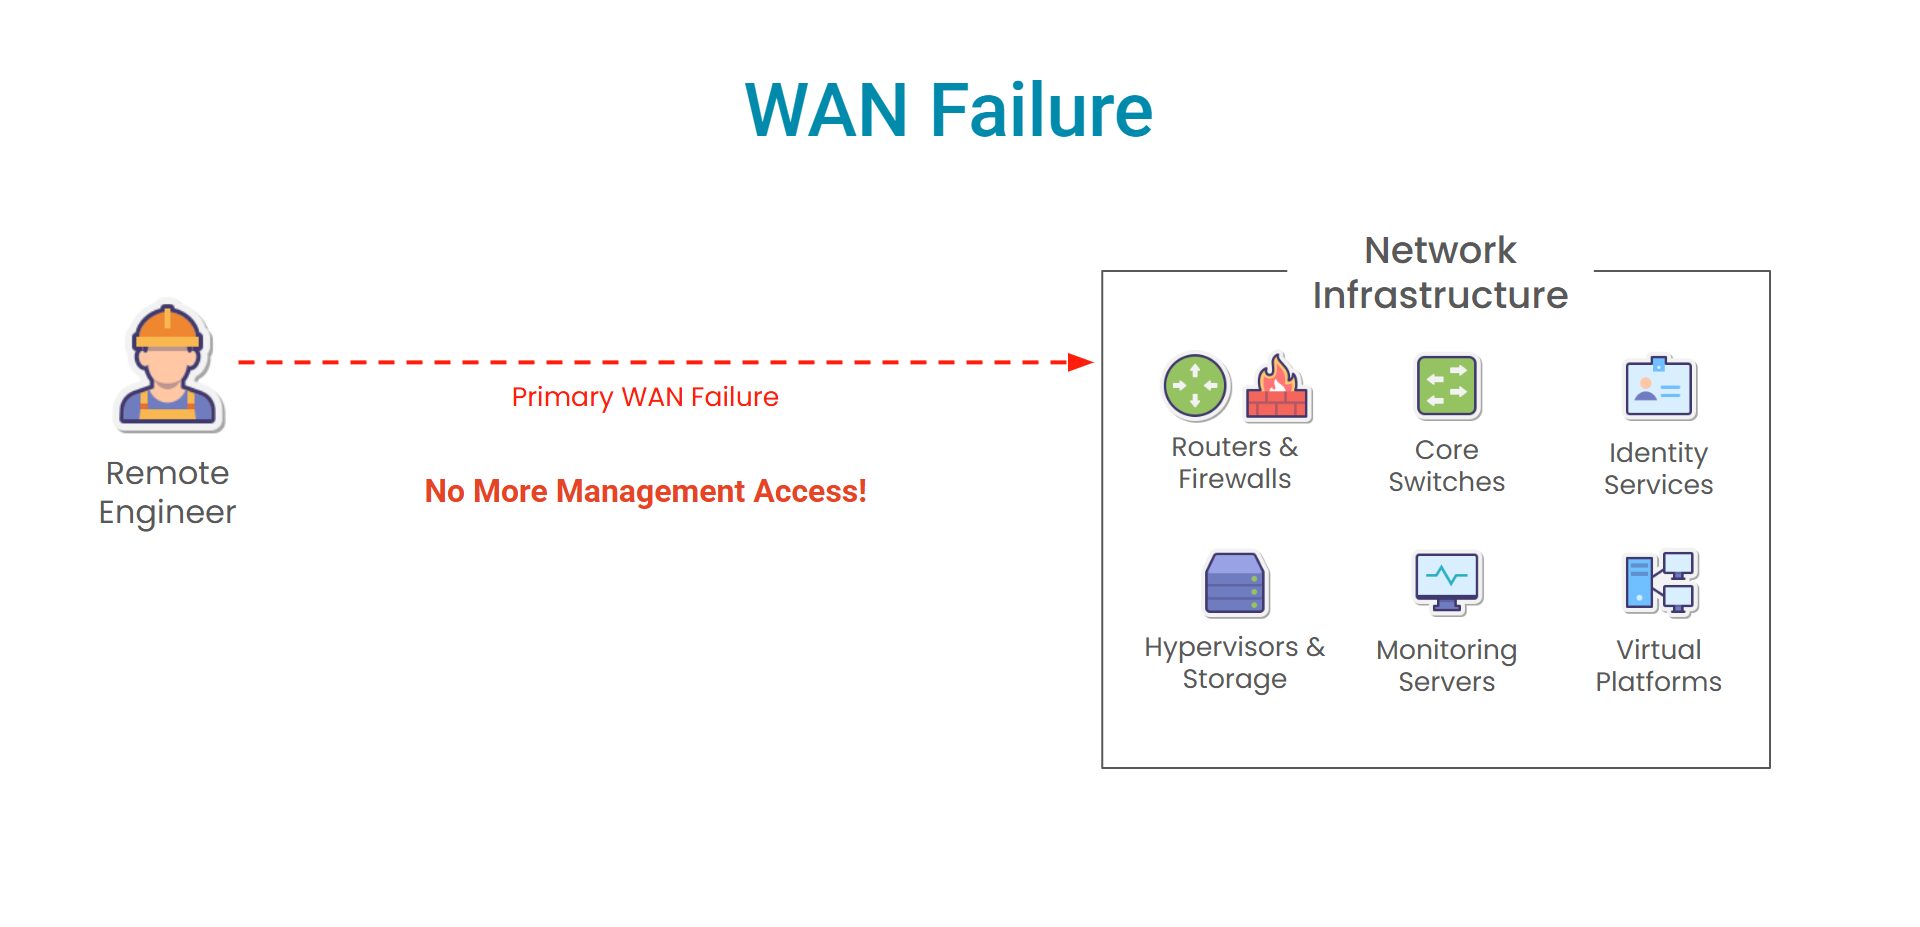
But the WAN also provides the connectivity required to operate the infrastructure itself (think device troubleshooting, config updates, etc.). This creates a problem: when the WAN fails, organizations lose their production services and their ability to manage the infrastructure responsible for restoring them. It’s like walking a tightrope without having a safety net below.

If your remote management capabilities depend on your production network, the WAN can easily become a single point of failure that’ll leave you battling long outages.

What is the WAN?

Unlike a local area network (LAN), which connects devices within a location, the wide area network is the connectivity layer that links geographically distributed networks and infrastructure across cities, regions, or countries. This includes everything from data centers and corporate HQs, to industrial sites, edge kiosks, and remote infrastructure.

Common WAN link types include MPLS, dedicated circuits, broadband, SD-WAN, and Internet connections.

The WAN is the connective tissue between distributed infrastructure. But its importance goes beyond just moving application traffic. That’s because it touches all three network planes.

The WAN Touches Every Network Plane

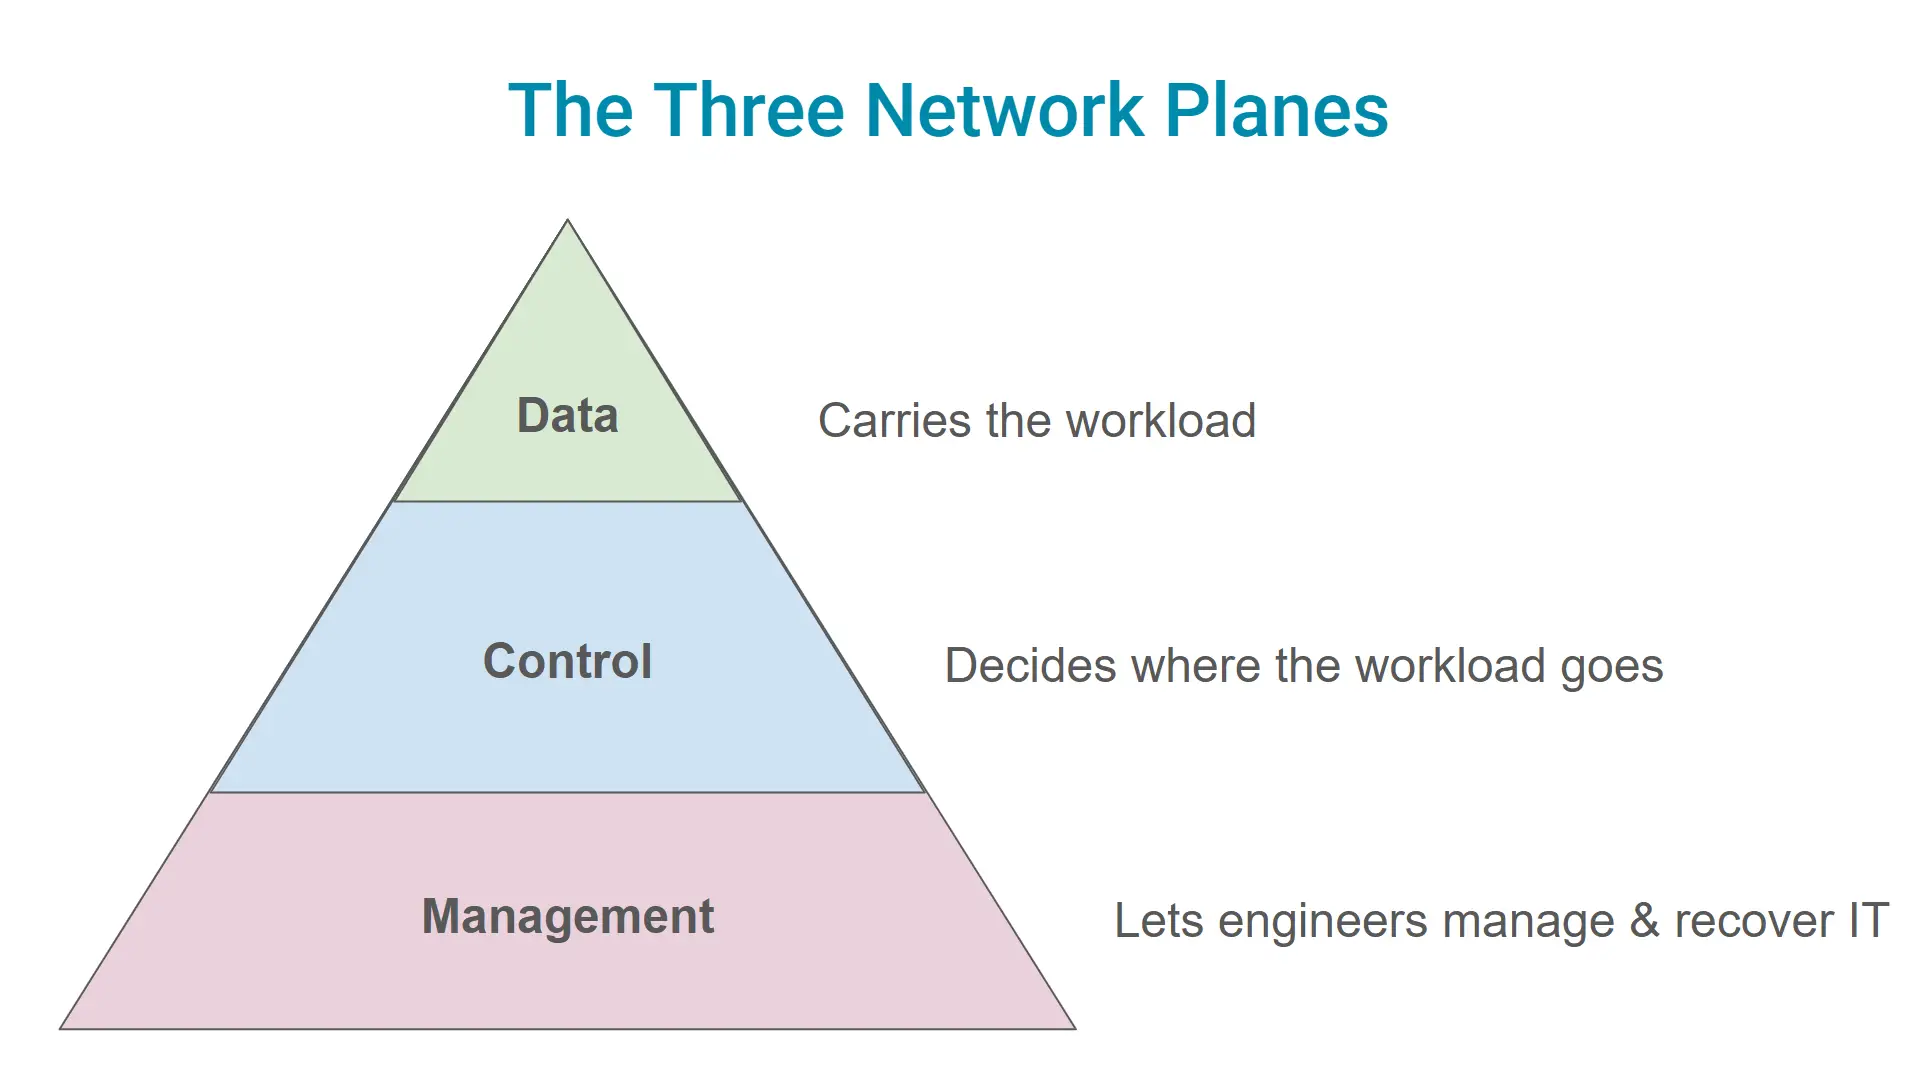
Modern networks have three primary planes that each serve a different purpose. We broke these down in a previous article, but here are the basics:

  1. Production/data plane: Carries the traffic (app workloads, voice, video, etc.)
  2. Control plane: Determines how traffic moves (think BGP, OSPF, VXLAN, EVPN)
  3. Management plane: How engineers access, troubleshoot, configure, and monitor infrastructure

The management plane is especially important when it comes to the WAN and the production network. That’s because this plane is vulnerable in traditional network architectures.

How The WAN Becomes a Single Point of Failure

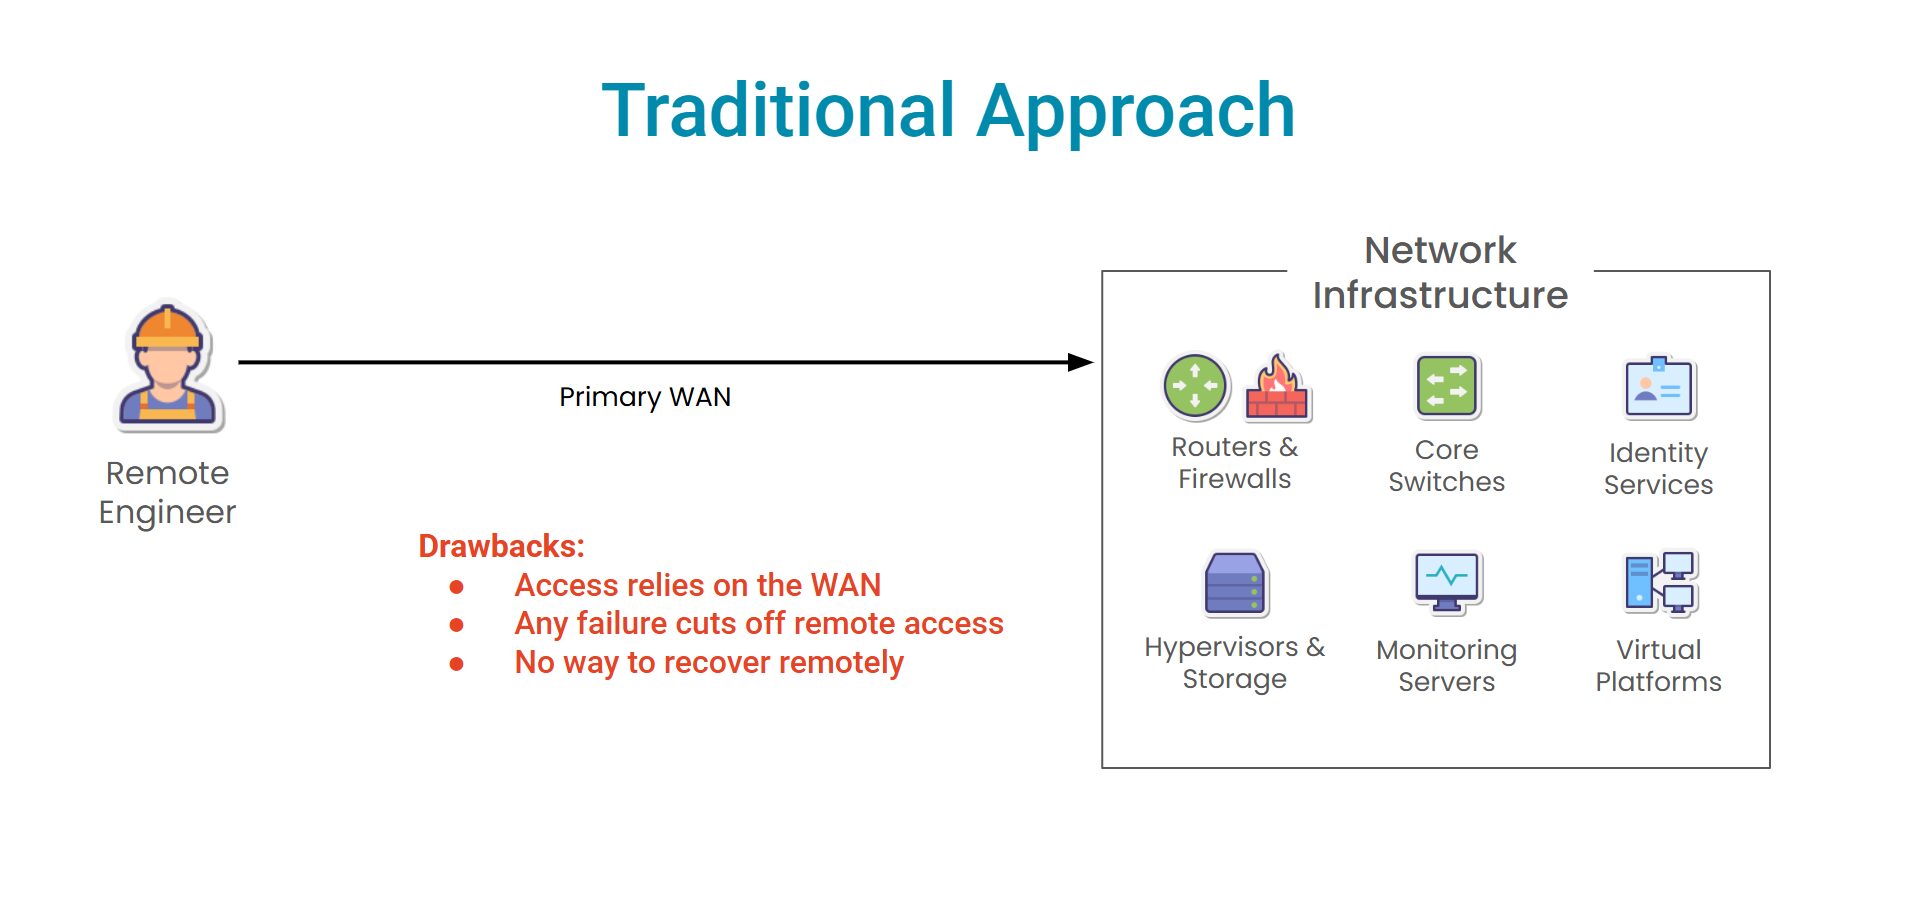
When everything is working fine, management access is like air: you don’t even need to think about it. You can SSH into a router, change a firewall config, or restart a hanging server. It’s very straightforward because of one thing: the WAN is what connects you to the infrastructure.

Traditional Approach

But this is a problem. This means that you really don’t have a dedicated management plane, since management access relies on the production network. When the WAN fails, the production network is what you need to fix — but you no longer have access to it.

WAN Failure

Here’s what happens when the WAN fails:

  • Data plane disruption: Applications and users lose connectivity.
  • Control plane disruption: Routing and network operations are jeopardized.
  • Management plane disruption: Engineers lose remote access to the devices they need to troubleshoot.

When you can’t reach the equipment you need to fix, a production outage turns into an entirely different issue.


What Actually Goes Wrong When the WAN Fails?


ISP and Carrier Outages

Sometimes, the service provider itself has an outage and there’s not much you can do about it. Recent data from Cisco ThousandEyes shows just how often these events occur. During the week of August 24-30, 2026, ThousandEyes observed 297 global ISP outage events, 203 of which were in the United States alone.

Outages instantly become a remote-management problem in these cases when the WAN is the only path back to a site that’s gone offline. You’re left with two options: Wait for your provider to restore the connection, or send an engineer to the affected site(s). Both can easily take hours, sometimes days, before normal operations are restored.


Fiber Cuts and Physical Disruptions

What happens when a construction crew accidentally sends a backhoe bucket or an auger straight through an underground fiber run? If you rely on the WAN for management access, physical disruptions like these could have you waiting for days before they’re fixed.

Cloudflare tracked more than 180 Internet disruptions during 2025, including those caused by cable cuts, power outages, and extreme weather. Some were brief, but others lasted for days. These failures are especially difficult (and frustrating) because you could be hundreds of miles away, and your devices could be perfectly healthy, but the path you use to reach them is physically broken.


Routing and Configuration Errors

Increasing network complexity directly contributes to configuration and change-management problems. Uptime Institute’s 2025 analysis found that 23% of impactful outages were attributed to IT and networking issues, like routing errors, incorrect configs, and firmware problems.

The network equipment is exactly what you need to fix, but a configuration error has eliminated the path you need to access it.


Third-Party Network Failures

There’s an entire ecosystem of ISPs, carriers, cloud providers, colocations, and other third party networks. If any part of this ecosystem fails, it can affect your ability to reach remote infrastructure.

Uptime Institute reports that 39% of those surveyed experienced an outage caused by a third-party networking issue. Essentially, you can lose access to your own infrastructure because of a failure you don’t control.

That’s the common thread with all these outage scenarios. When a WAN failure takes down your production network, your management access goes down with it.


How To Stay Operational During WAN Failures


Build an Isolated Management Infrastructure

Adding redundancy seems like the logical solution. But having true operational resilience means going beyond having a second WAN circuit. You need to be able to confidently answer this question:

Can you still reach the infrastructure if the primary network fails?

If the answer is no, you still have a shared-fate problem: your management access depends on the same infrastructure you’re trying to recover.

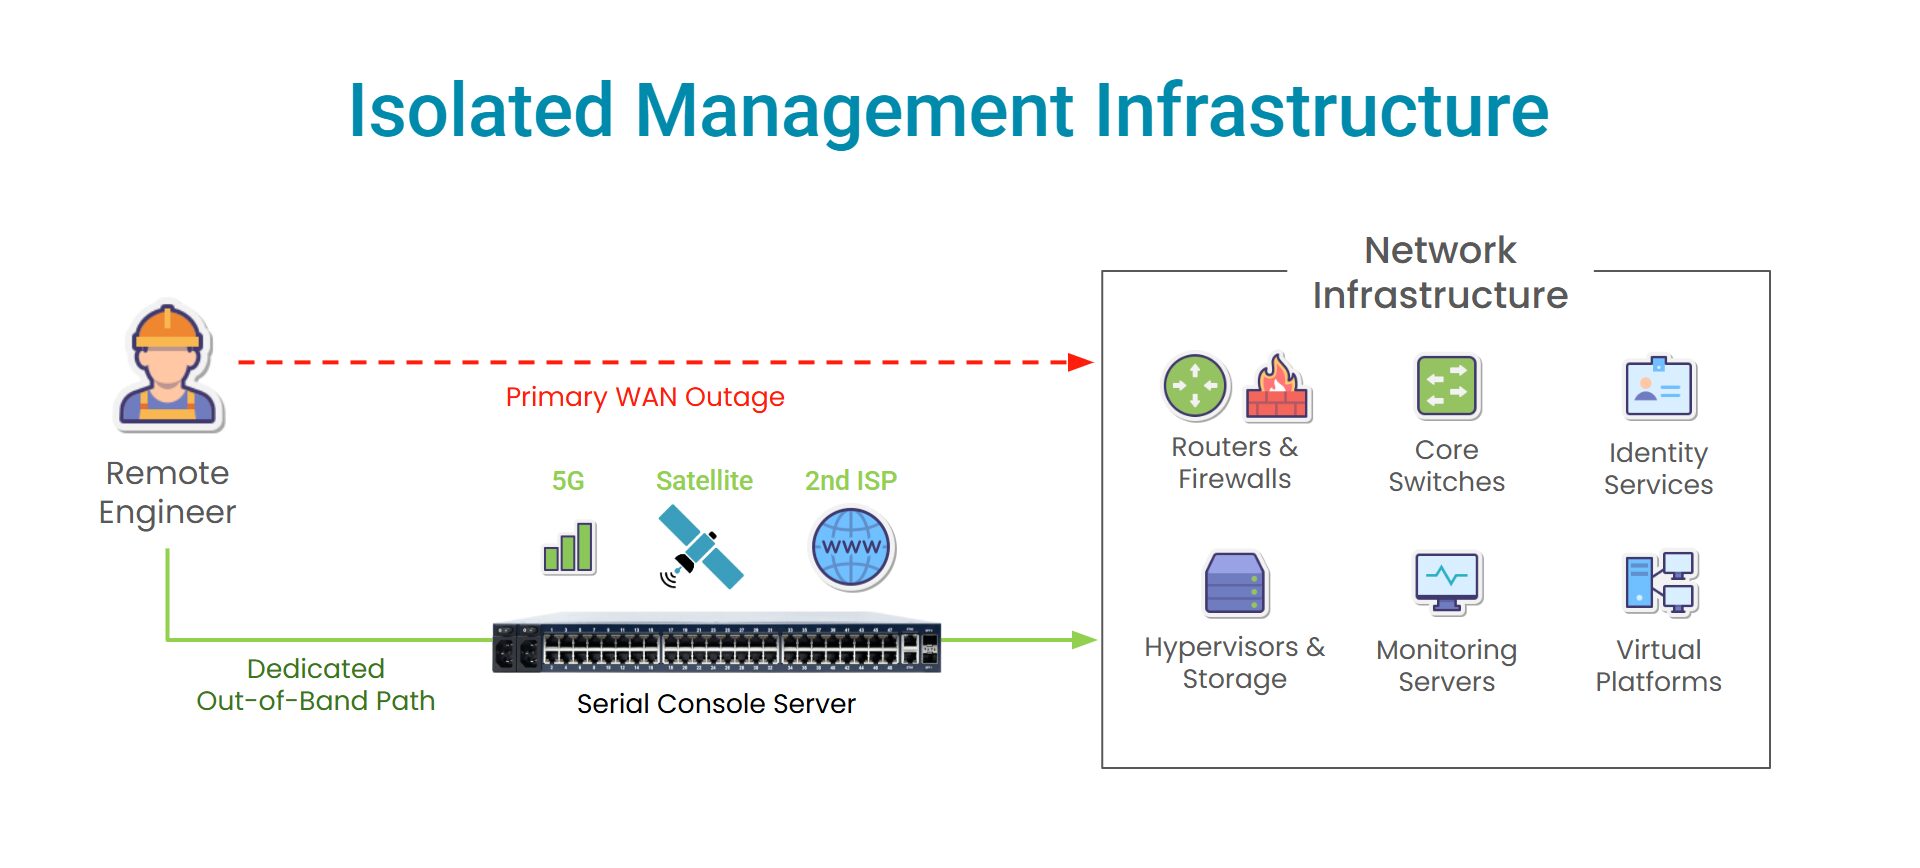
An Isolated Management Infrastructure (IMI) solves this by creating a dedicated management layer that is completely independent of the production network. IMI does not rely on the WAN, routers, switches, or other infrastructure that carry production traffic. Instead, IMI provides a separate path that’s purpose-built for maintaining and recovering production infrastructure. Think of it as a safety net that keeps business from crashing down if there’s a primary network outage.

Isolated Management Infrastructure

What Does IMI Look Like?

Isolated Management Infrastructure is made up of several components:

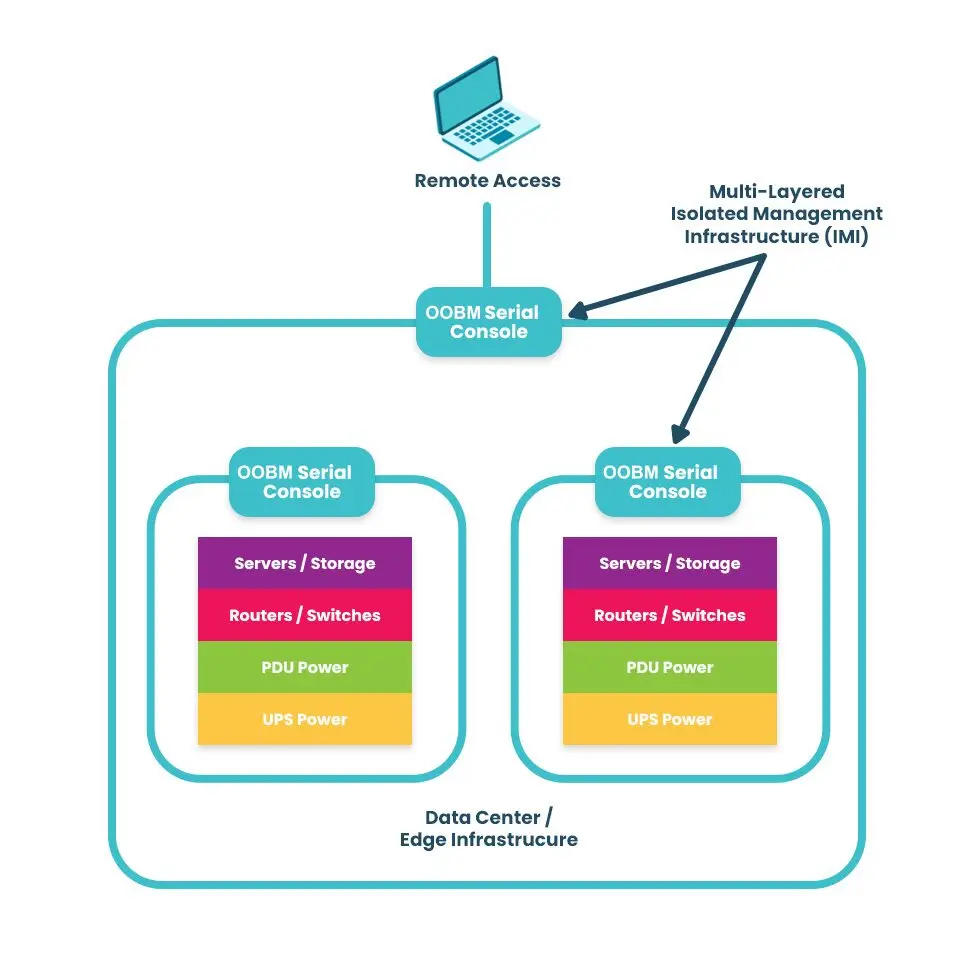
  1. A separate management network that is logically and physically isolated from production infrastructure. This is created by deploying out-of-band serial consoles.
  2. Independent connectivity using 5G, satellite, and/or other link types that don’t rely on terrestrial infrastructure. These provide access to your OOB serial consoles, and thus your production equipment.
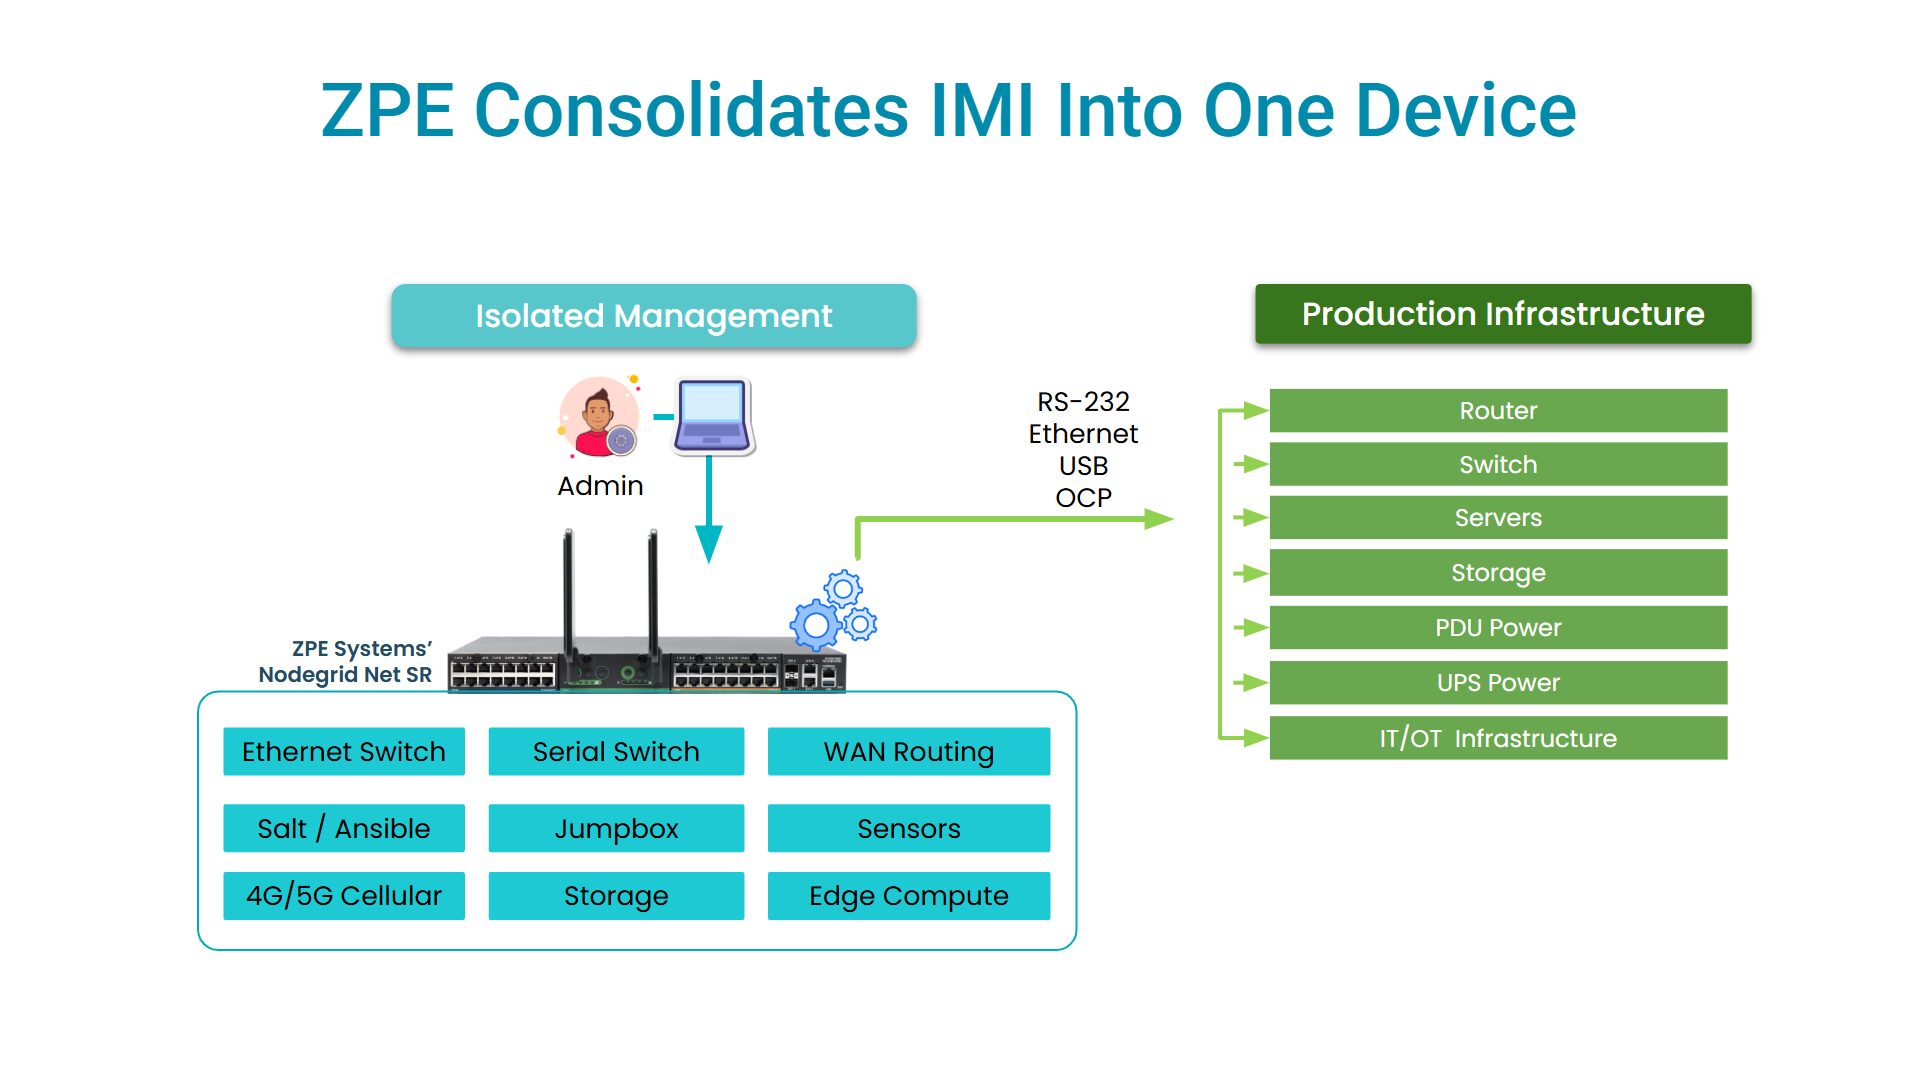
  3. Direct access to the variety of critical IT, including via serial, Ethernet, USB, KVM, and power interfaces. This gives you management access to your entire equipment stack.
ZPE Consolidates IMI Into One Device

This completely changes the recovery process. There’s no more waiting for the WAN to come back or dispatching an engineer to the site. Engineers can use the IMI to pinpoint affected equipment, make config changes, and/or completely rebuild systems.

Take Mercado Libre for example. This Latin America e-commerce giant experienced an unexpected outage at one of their distribution hubs. But because they had installed ZPE Systems’ Nodegrid as their IMI, they were able to keep operating as if nothing happened. “The solution paid for itself with just this one outage,” they said. Read the full Mercado Libre case study here.

Don’t Let WAN Failures Take Down Your Network

Download The Network Resilience Blueprint

The WAN will always be a critical component, and you can’t eliminate every carrier outage, fiber cut, or config error. But you can eliminate your management network’s dependency on the WAN.

The Network Resilience Blueprint is a practical framework for putting IMI into practice. It walks you through five architectural steps to build an infrastructure that’s easy to manage, fast to recover, and most importantly, resilient against WAN failures. Download the blueprint now and keep your critical IT reachable even when the network is down.

The Network Resilience Blueprint

Get in Touch For a Demo of AI Resilience

Our engineers will walk you through the best practices and show you Nodegrid’s capabilities first-hand. See how easy it is to point, click, and manage your distributed AI fleet. Fill out the form to get started.


Network Resilience for AI & Edge Workloads

Network Resilience for AI & Edge Workloads

Designing AI infrastructure that engineers can recover when things break

AI infrastructure is expanding fast across enterprise networks. GPU clusters are powering model training, while edge inference systems process data in real time across industries like finance, manufacturing, retail, and telecommunications. Most AI environments are working well from the perspective of the computing infrastructure.

But with many deployments scaling beyond centralized data centers and into distributed edge environments, network engineers are facing a familiar problem: How do you maintain control when failures happen?

This is an important question to address because AI environments amplify the operational impact of failures. Large GPU clusters, distributed edge locations, and latency-sensitive workloads all depend on reliable network connectivity. When something breaks, recovery becomes just as important as redundancy.


AI Infrastructure Places Different Demands on the Network

Traditional enterprise applications are generally tolerant of brief interruptions. A user might reconnect to an application or retry a transaction without significant impact. But AI workloads are much less forgiving.

Large language model (LLM) training, distributed inference pipelines, and real-time analytics depend on continuous communication between compute, storage, and networking resources. Interruptions have a ripple effect because modern AI environments rely on:

  • GPU clusters connected by high-bandwidth Ethernet or InfiniBand fabrics
  • East-west traffic that exceeds traditional north-south application flows
  • Distributed storage systems supplying training data
  • Kubernetes orchestration platforms scheduling GPU workloads
  • Edge inference nodes continuously exchanging telemetry with centralized systems

For example, a failed top-of-rack switch, an incorrect routing policy, or a misconfigured spine switch can isolate entire GPU pools from storage or orchestration services. Even if the compute nodes remain operational, workloads stall while engineers work to restore connectivity.

For network engineers, resilience is now a job of ensuring the infrastructure remains observable, accessible, and recoverable especially when failures occur.


Understanding the Different Network Planes

Before we go further, it helps to distinguish between three separate but closely related parts of the network, which will help understand where failures happen and their effects:

Production (or data) plane: carries application traffic, including AI training data, inference requests, storage traffic, and user communications. For example, when you submit a prompt to an AI application, the production plane is what carries your prompt, the model’s responses, and supporting data.

Control plane: runs the protocols that determine how traffic moves through the network, including BGP, OSPF, EVPN, VXLAN, spanning tree, and other routing and switching functions. Think of this like the network’s navigation system. The control plane decides the best path for traffic to take, but it doesn’t carry the traffic itself.

Management plane: provides the interfaces engineers use to monitor, configure, and recover infrastructure. This includes SSH, HTTPS, APIs, SNMP, serial console access, intelligent PDUs, and out-of-band management. This is the path that engineers use to log into devices, push config changes, and recover systems during an outage.

Understanding the Different Network Planes

Image: The three network planes: The data plane, which carries the workload; the control plane, which decides where the workload goes; and the management plane, which gives engineers access to manage and recover equipment.


Where AI Infrastructure Failures Actually Happen

Control Plane Failures That Disrupt The Management Plane

Not every outage begins with a hardware failure. In fact, a lot of incidents originate in the control plane with:

  • BGP policy mistakes
  • OSPF adjacency failures
  • EVPN/VXLAN configuration errors
  • VLAN or VRF misconfigurations
  • ACL changes that unintentionally block management traffic

These issues may leave routers, switches, and servers fully operational but unreachable over the production network. If management traffic shares the same infrastructure as application traffic, engineers lose SSH, API, and monitoring access right when they need it most.

This is why it’s important to completely separate the management network from the production network (more on this below).


Automation Mistakes That Create a Big Blast Radius

Infrastructure-as-Code (IaC) and network automation are great for improving consistency, but they also increase the blast radius of configuration errors. A single Ansible playbook, Terraform deployment, or automation workflow can unintentionally affect hundreds of devices simultaneously.

When that happens, engineers need a recovery path that does not depend on the production network remaining operational. This is one of the reasons out-of-band management continues to be standard practice in hyperscale and service provider environments.


GPU Clusters That Are Left Idle

AI infrastructure is built around the most expensive compute resources in the data center. Experts project global AI investments to exceed $1 trillion in 2026, and it’s easy to see why. A single GPU server can cost hundreds of thousands of dollars, and production AI clusters often consist of dozens or hundreds of these systems working together.

Model training requires GPUs to operate as a coordinated cluster. If a network issue isolates part of the cluster or prevents nodes from communicating with storage or orchestration platforms, the training job stalls or fails altogether. Even though the GPUs are powered on, they’re no longer doing productive work.

In inference environments, the impact is different but just as significant. An unreachable edge AI node that stops processing camera feeds, sensor data, or real-time transactions reduces application performance or forces workloads to fail over to other locations.

Idle hardware is just the beginning of the costs. Organizations also lose productive compute time, delay model development, miss service-level objectives (SLOs), and increase operational overhead while engineers work to restore connectivity.

No infrastructure is immune to failures, so eliminating every outage isn’t realistic. The goal instead is to minimize Mean Time to Recovery (MTTR) by giving engineers immediate access to diagnose and recover systems, so expensive GPU resources spend more time running workloads and less time waiting for someone to restore the network.


Addressing a Common Question About AI

One common response to conversations about AI resilience is: “Our AI infrastructure is already working fine. Why do we need to change anything?”

It’s a valid question. After all, if it ain’t broke…

But this underscores something we’ve been talking about for years. It’s not about redesigning networks that already work just fine. It’s about building the ultimate safety net that’ll save you from the growing operational risks of scaling your infrastructure.

Managing a GPU cluster inside a data center is completely different than managing a fleet of AI systems spread across hundreds of remote sites. Engineers need to retain visibility and control when the inevitable routing mistake, WAN outage, or misconfig happens. Resilience needs to be built into the architecture.


Resilience Should Be Built Into AI Architecture

The networking industry has spent decades designing highly available production networks through redundant links, resilient routing protocols, and fault-tolerant hardware. AI infrastructure deserves the same level of attention, but redundancy alone isn’t enough.

Traditional high-availability designs focus on strengthening the production and control planes. Equally important is strengthening the management plane and being able to confidently answer this question: “When an engineer loses connectivity to a remote GPU cluster at 2am, what path do they have to recover it?”

If the answer depends on the production network coming back first, the architecture still has a single point of failure. This is why it’s key to fully separate management from production. This isolation lets engineers diagnose, control, and recover AI infrastructure exactly when it matters most.

So, “Why do we need to change anything?” It’s not really about changing the architecture. It’s more about adding an alternate management path that lets you recover systems even if the production network is down.

That’s where out-of-band and IMI come in.


IMI: The Evolution of Out-of-Band

Out-of-band management is usually thought of as a console server attached to a few routers, meant to give engineers backup access in case the main network goes down. But modern out-of-band — what’s called Isolated Management Infrastructure (IMI) — has much more operational capability, including the ability to fully rebuild systems.
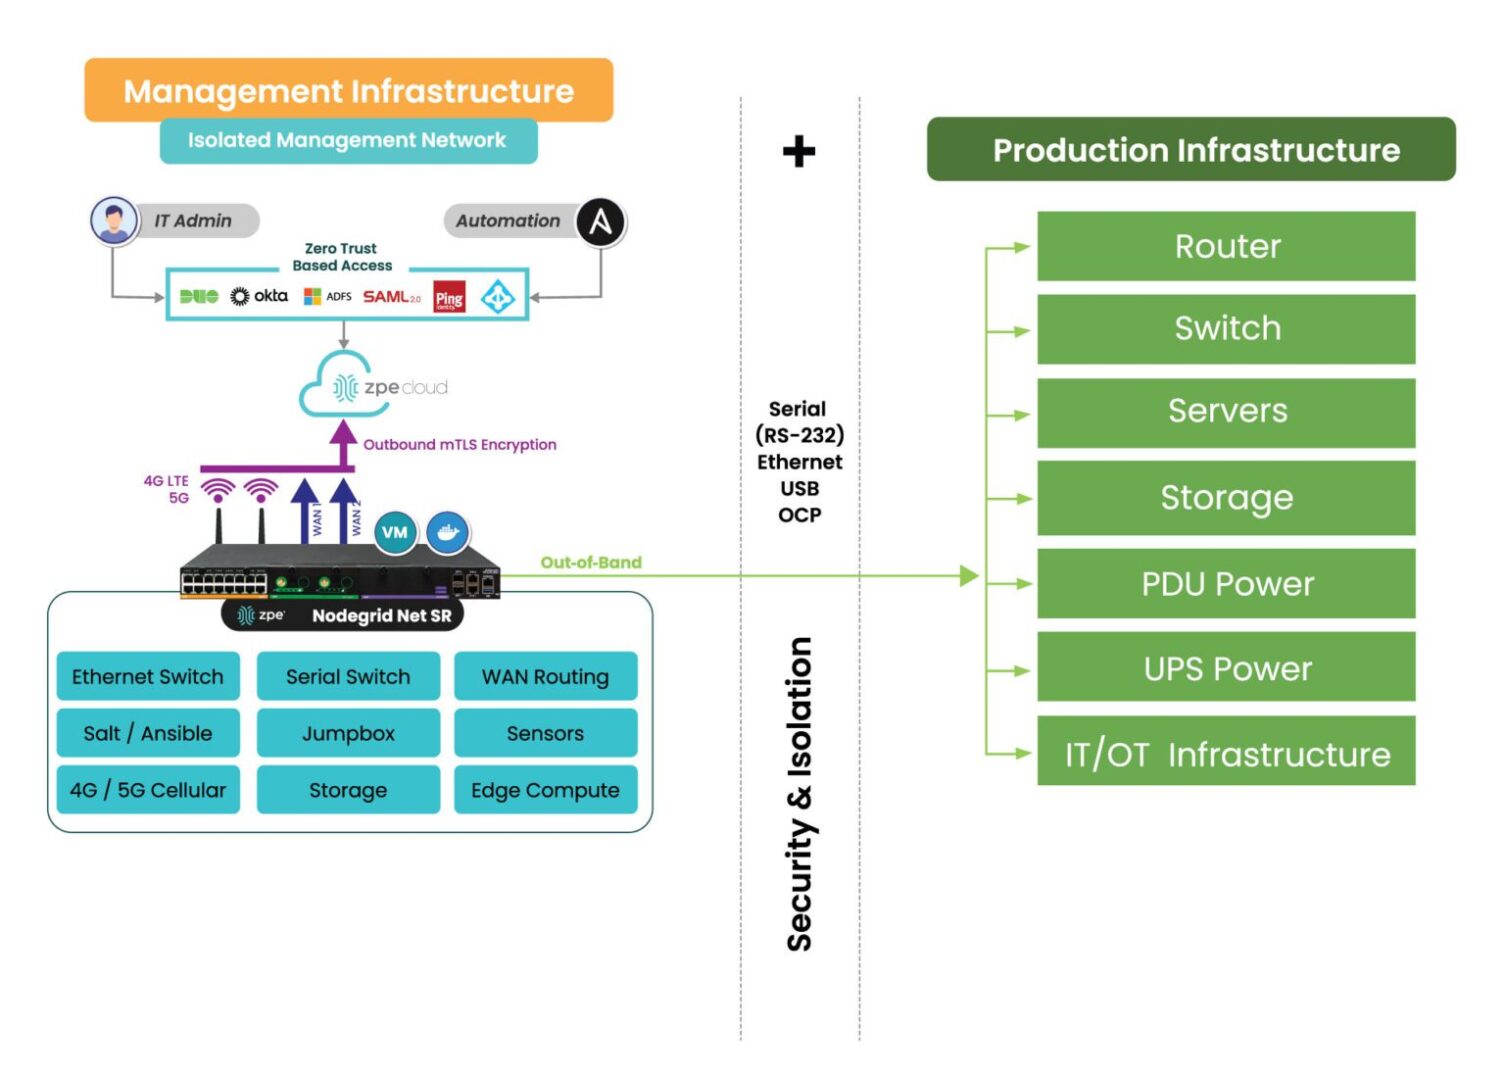
An IMI includes:

  • Serial console access to routers, switches, firewalls, storage arrays, and GPU servers
  • Independent Ethernet management interfaces
  • 5G/LTE or satellite connectivity for WAN independence
  • Remote power management through intelligent PDUs
  • Secure jump-host capabilities with centralized authentication
  • Automated recovery workflows triggered by monitoring platforms
IMI The Evolution of Out-of-Band

Image: Isolated Management Infrastructure provides the operational capabilities to fully rebuild and restore networking systems, even if the network is offline.

This creates a management plane that remains operational regardless of whether the production network is available. So instead of having to rebuild connectivity before troubleshooting can begin, engineers can connect via 5G/LTE or satellite to immediately investigate logs, inspect device health, restore configurations, or power-cycle failed systems.


ZPE is Essential to Resilient Architecture

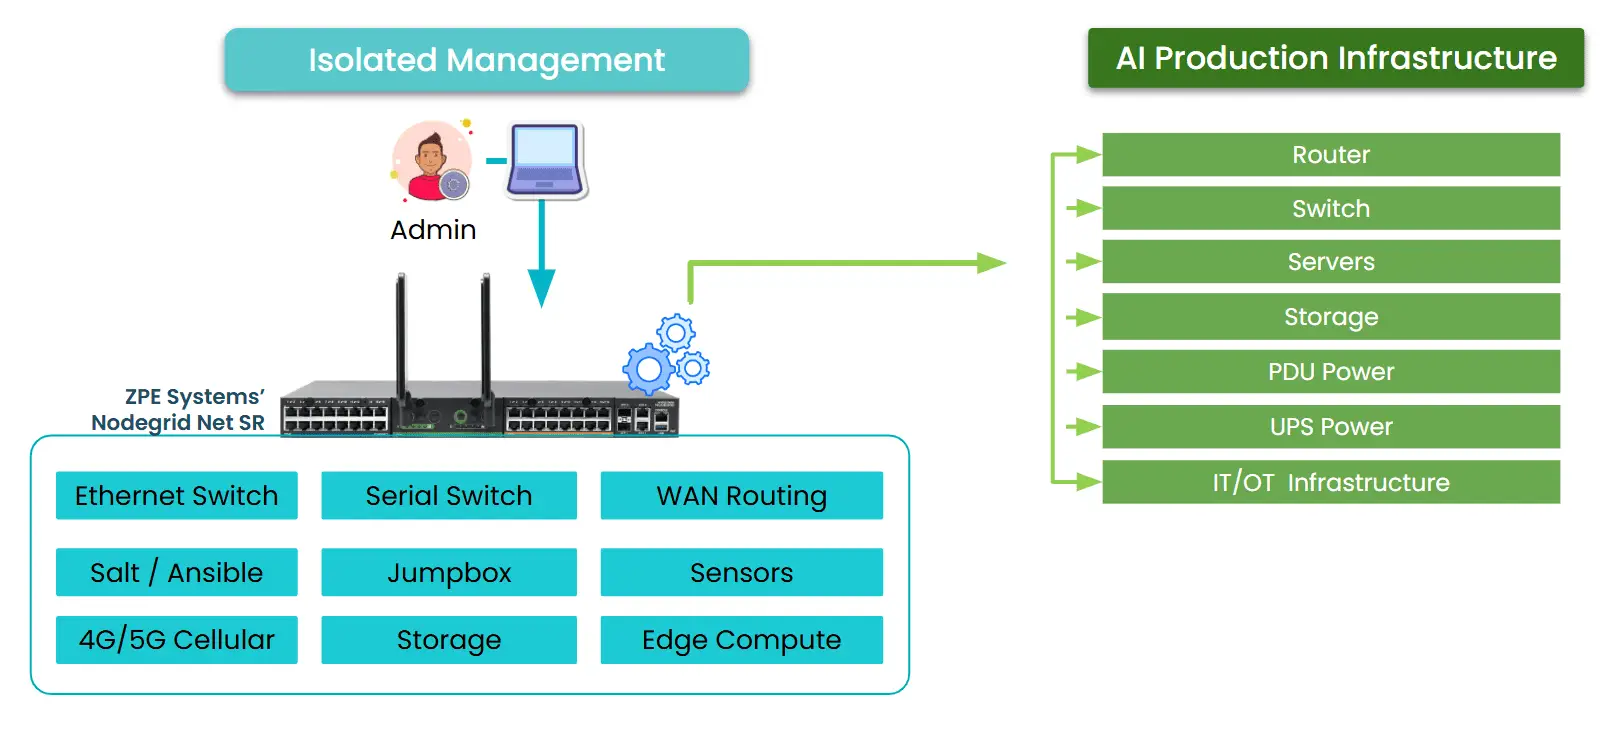
ZPE’s solutions are an essential component of resilient network architecture. They’re used by many organizations as an independent operational layer alongside the production network. At each AI or edge site, one ZPE Nodegrid device can aggregate management access for routers, spine and leaf switches, firewalls, GPU servers, storage, PDUs, and hypervisor/compute platforms.

Isolated Management

Image: ZPE’s solutions consolidate multiple functions into a single device and aggregate management access to a variety of AI production infrastructure, with the ability to connect via RS-232, Ethernet, USB, and OCP interfaces.

This IMI gives engineers secure access during routing failures, WAN outages, failed software upgrades, config errors, and many other outage scenarios. Nodegrid devices can also host virtualized functions (like routing and firewalls) to help further consolidate the overall tech stack. This gives organizations a consistent operational model no matter how many AI sites they have or where their workloads are deployed.

Download the Blueprint for AI Resilience

Want to see how these principles fit together? Download the Network Resilience Blueprint to learn a practical framework for designing an infrastructure that’s easy to manage, quick to recover, and built for today’s distributed AI and edge environments.

The Network Resilience Blueprint

Get in Touch For a Demo of AI Resilience

Our engineers will walk you through the best practices and show you Nodegrid’s capabilities first-hand. See how easy it is to point, click, and manage your distributed AI fleet. Fill out the form to get started.


Why Gen 3 Out-of-Band Is Your Strategic Weapon in 2025

Mike Sale – Why Gen 3 Out-of-Band is Your Strategic Weapon

I think it’s time to revisit the old school way of thinking about managing and securing IT infrastructure. The legacy use case for OOB is outdated. For the past decade, most IT teams have viewed out-of-band (OOB) as a last resort; an insurance policy for when something goes wrong. That mindset made sense when OOB technology was focused on connecting you to a switch or router.

Technology and the role of IT have changed so much in the last few years. There’s a lot more pressure on IT folks these days! But we get it, and that’s why ZPE’s OOB platform has changed to help you.

At a minimum, you have to ensure system endpoints are hardened against attacks, patch and update regularly, back up and restore critical systems, and be prepared to isolate compromised networks. In other words, you have to make sure those complicated hybrid environments don’t go off the rails and cost your company money. OOB for the “just-in-case” scenario doesn’t cut it anymore, and treating it that way is a huge missed opportunity.

Don’t Be Reactive. Be Resilient By Design.

Some OOB vendors claim they have the solution to get you through installation day, doomsday, and everyday ops. But if I’m candid, ZPE is the only vendor who can live up to this standard.   We do what no one else can do! Our work with the world’s largest, most well-known hyperscale and tech companies proves our architecture and design principles.

This Gen 3 out-of-band (aka Isolated Management Infrastructure) is about staying in control no matter what gets thrown at you.

OOB Has A New Job Description

Out-of-band is evolving because of today’s radically different network demands:

  • Edge computing is pushing infrastructure into hard-to-reach (sometimes hostile) environments.
  • Remote and hybrid ops teams need 24/7 secure access without relying on fragile VPNs.
  • Ransomware and insider threats are rising, requiring an isolated recovery path that can’t be hijacked by attackers.
  • Patching delays leave systems vulnerable for weeks or months, and faulty updates can cause crashes that are difficult to recover from.
  • Automation and Infrastructure as Code (IaC) are no longer nice-to-haves – they’re essential for things like initial provisioning, config management, and everyday ops.

It’s a lot to add to the old “break/fix” job description. That’s why traditional OOB solutions fall short and we succeed. ZPE is designed to help teams enforce security policies, manage infrastructure proactively, drive automation, and do all the things that keep the bad stuff from happening in the first place. ZPE’s founders knew this evolution was coming, and that’s why they built Gen 3 out-of-band.

Gen 3 Out-of-Band Is Your Strategic Weapon

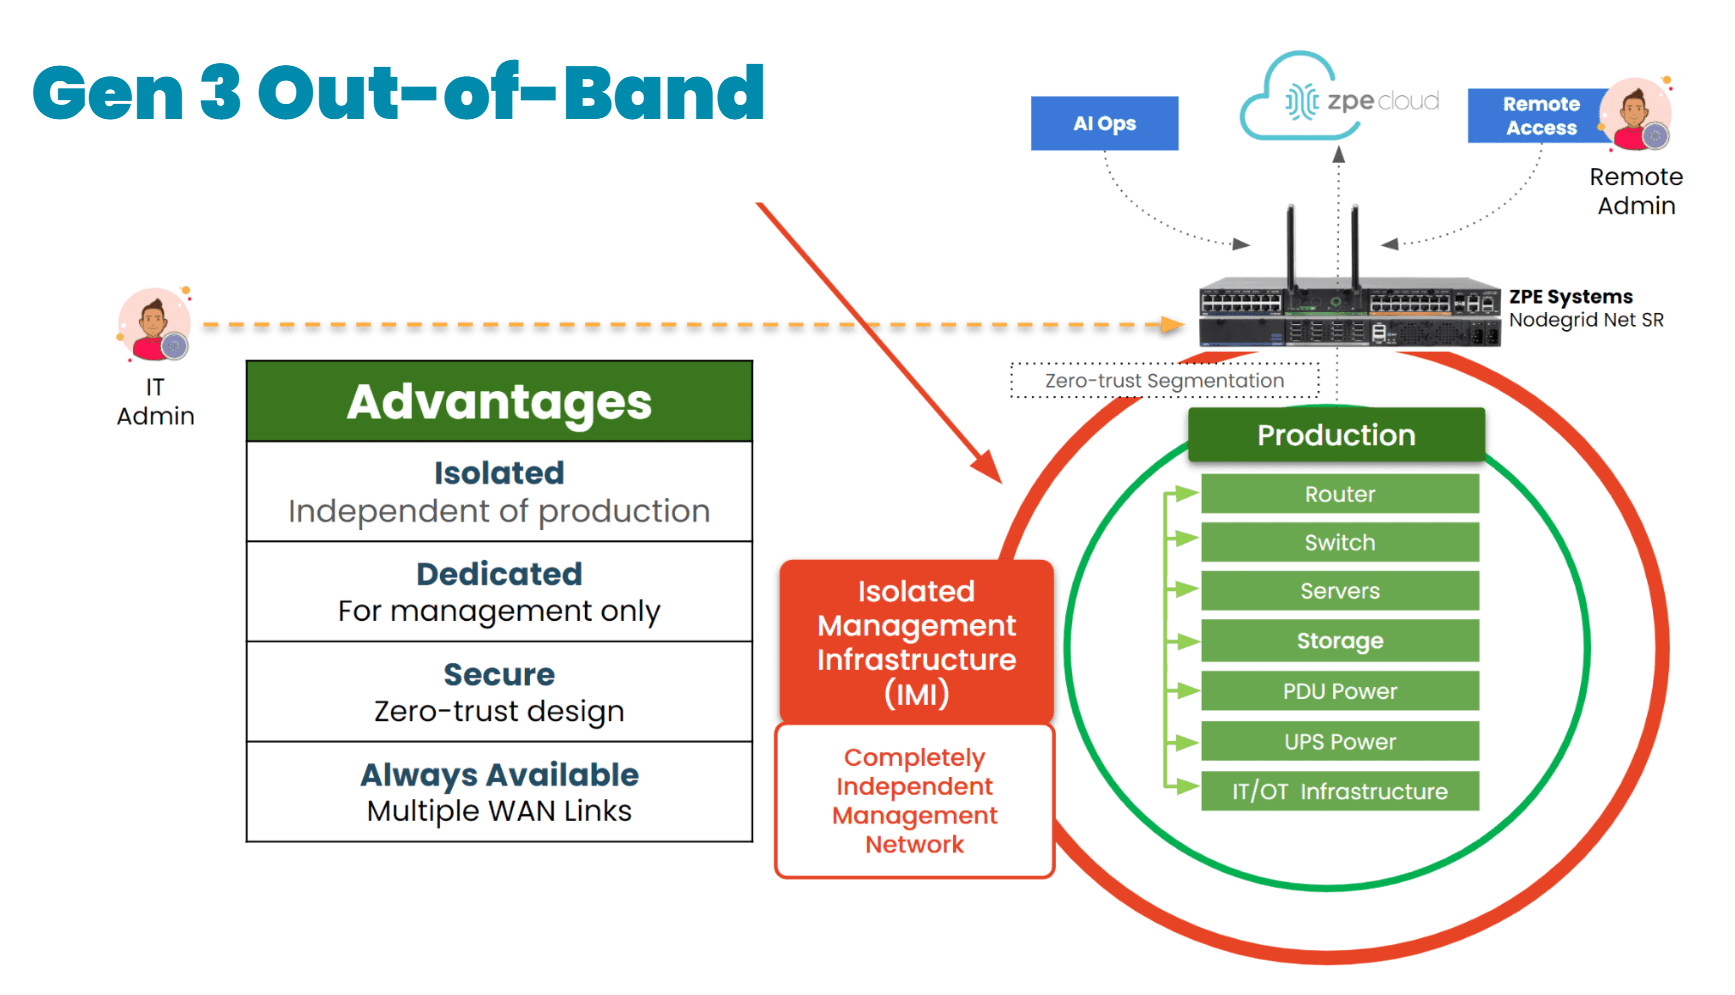
Unlike normal OOB setups that are bolted onto the production network, Gen 3 out-of-band is physically and logically separated via Isolated Management Infrastructure (IMI) approach. That separation is key – it gives teams persistent, secure access to infrastructure without touching the production network.

This means you stay in control no matter what.

Gen 3 out-of-band management uses IMI

Image: Gen 3 out-of-band management takes advantage of an approach called Isolated Management Infrastructure, a fully separate network that guarantees admin access when the main network is down.

Imagine your OOB system helping you:

  • Push golden configurations across 100 remote sites without relying on a VPN.
  • Automatically detect config drift and restore known-good states.
  • Trigger remediation workflows when a security policy is violated.
  • Run automation playbooks at remote locations using integrated tools like Ansible, Terraform, or GitOps pipelines.
  • Maintain operations when production links are compromised or hijacked.
  • Deploy the Gartner-recommended Secure Isolated Recovery Environment to stop an active cyberattack in hours (not weeks).


Gen 3 out-of-band is the dedicated management plane that enables all these things, which is a huge strategic advantage. Here are some real-world examples:

  • Vapor IO shrunk edge data center deployment times to one hour and achieved full lights-out operations. No more late-night wakeup calls or expensive on-site visits.
  • IAA refreshed their nationwide infrastructure while keeping 100% uptime and saving $17,500 per month in management costs.
  • Living Spaces quadrupled business while saving $300,000 per year. They actually shrunk their workload and didn’t need to add any headcount.

OOB is no longer just for the worst day. Gen 3 out-of-band gives you the architecture and platform to build resilience into your business strategy and minimize what the worst day could be.

Mike Sale on LinkedIn

Connect With Me!

Out-of-Band vs. Isolated Management Infrastructure: What’s the Difference?

Out-of-band vs IMI
To stay ahead of network outages, cyberattacks, and unexpected infrastructure failures, IT teams rely on remote access tools. Out-of-band (OOB) management is traditionally used for quick access to troubleshoot and resolve issues when the main network goes down. But in the past decade, hyperscalers and leading enterprises have developed a more advanced approach called Isolated Management Infrastructure (IMI). Although IMI incorporates OOB, it’s important to understand the distinction between the two, especially when designing infrastructure to be resilient and scalable.
What is Out-of-Band Management?

Out-of-Band Management has been around for decades. It gives IT administrators remote access to network equipment through an independent channel, serving as a lifeline when the primary network is down.

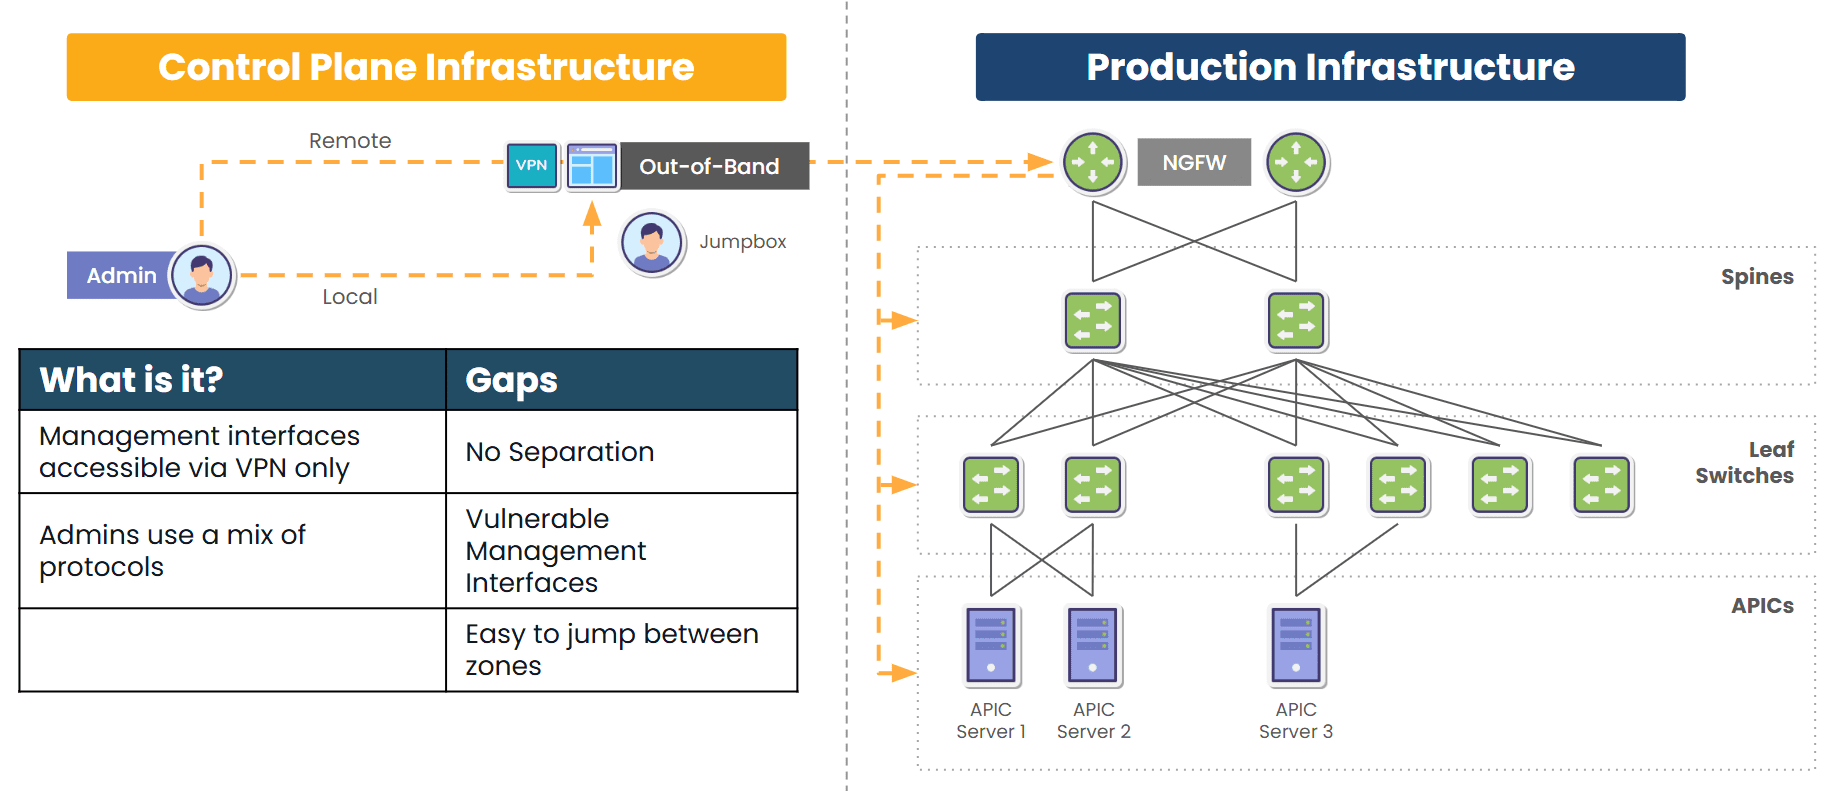
Traditional out-of-band provides a secondary path to production equipment

Image: Traditional out-of-band solutions provide a secondary path to production infrastructure, but still rely in part on production equipment.

Most OOB solutions are like a backup entrance: if the main network is compromised, locked, or unavailable, OOB provides a way to “go around the front door” and fix the problem from the outside.

Key Characteristics:

  • Separate Path: Usually uses dedicated serial ports, USB consoles, or cellular links.
  • Primary Use Cases: Though OOB can be used for regular maintenance and updates, it’s typically used for emergency access, remote rebooting, BIOS/firmware-level diagnostics, and sometimes initial provisioning.
  • Tools Involved: Console servers, terminal servers, or devices with embedded OOB ports (e.g., BMC/IPMI for servers).

Business Impact:

From a business standpoint, traditional OOB solutions offer reactive resilience that helps resolve outages faster and without costly site visits. It also reduces Mean Time to Repair (MTTR) and enhances the ability to manage remote or unmanned locations.

However, solutions like ZPE Systems’ Nodegrid provide robust capability that evolves out-of-band to a new level. This comprehensive, next-gen OOB is called Isolated Management Infrastructure.

What is Isolated Management Infrastructure?

Isolated Management Infrastructure furthers the concept of resilience and is a natural evolution of out-of-band. IMI does two things:

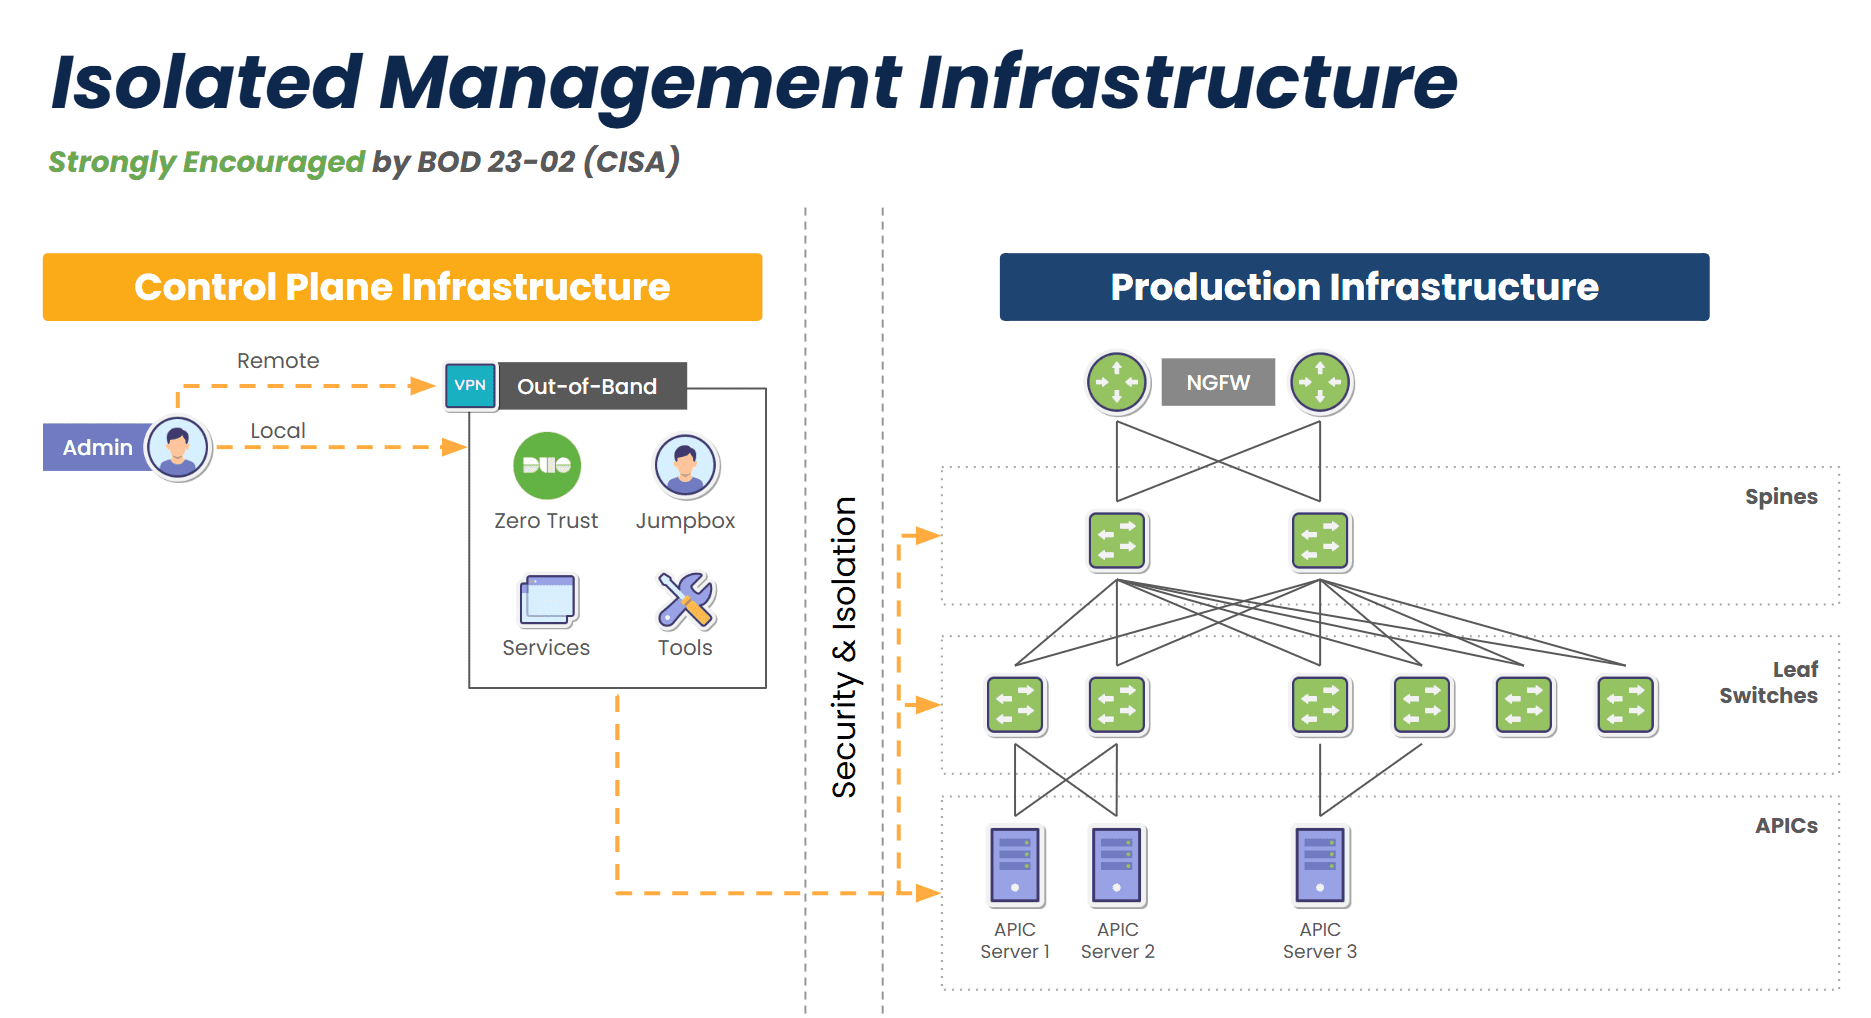
  1. Rather than just providing a secondary path into production devices, IMI creates a completely separate management plane that does not rely on any production device.
  2. IMI incorporates its own switches, routers, servers, and jumpboxes to support additional critical IT functions like networking, computing, security, and automation.

Isolated management infrastructure provides a fully separate management path

Image: Isolated Management Infrastructure creates a completely separate management plane and full-stack platform for maintaining critical services even during disruptions, and is strongly encouraged by CISA BOD 23-02.

IMI doesn’t just provide access during a crisis – it creates a separate layer of control and serves as a resilience system that keeps core services running no matter what. This gives organizations proactive resilience from simple upgrade errors and misconfigurations, to ransomware attacks and global disruptions like 2024’s CrowdStrike outage.

Key Characteristics:

  • Fully Isolated Design: The management plane is physically and logically isolated from the production network, with console access to all production devices via a variety of interfaces including RS-232, Ethernet, USB, and IPMI.
  • Backup Links: Uses two or more backup links for reliable access, such as 5G, Starlink, and others.
  • Multi-Functionality: Hosts network monitoring, DNS, DHCP, automation engines, virtual firewalls, and all tools and functions to support critical services during disruptions.
  • Automation: Provides a safe environment for teams to build, test, and integrate automation workflows, with the ability to automatically revert back to a golden image in case of errors.
  • Ransomware Recovery: Hosts all tools, apps, and services to deploy the Gartner-recommended Secure Isolated Recovery Environments (SIRE).
  • Zero Trust and Compliance Ready: Built to minimize blast radius and support regulated environments, with segmentation and zero trust security features such as MFA and Role-Based Access Controls (RBAC).

Business Impact:

IMI enables operational continuity in the face of cyberattacks, misconfigurations, or outages. It aligns with zero-trust principles and regulatory frameworks like NIST 800-207, making it ideal for government, finance, and healthcare. It also provides a foundation for modern DevSecOps and AI-driven automation strategies.

Comparing Reactive vs. Proactive Resilience


Purpose
Deployment
Services Hosted
Typical Vendors
Best For
Out-of-Band
Recover access when production is down
Console servers or cellular-based devices
None (access only)
Opengear, Lantronix
Legacy networks, branch recovery
IMI
Maintain operations even when production is down
Full-stack platform (compute, network, storage)
Firewalls, monitoring, DNS, etc.
ZPE Systems (Nodegrid), custom-built IMI
Modern, zero-trust, AI-driven environments

Why Businesses Should Care

For CIOs and CTOs

IMI is more than a management tool – it’s a strategic shift in infrastructure design. It minimizes dependency on the production network for critical IT functions and gives teams a layered defense. For organizations using AI, hybrid-cloud architectures, or edge computing, IMI is strongly encouraged and should be incorporated into the initial design.

For Network Architects and Engineers

IMI significantly reduces manual intervention during incidents. Instead of scrambling to access firewalls or core switches when something breaks, teams can rely on an isolated environment that remains fully operational. It also enables advanced automation workflows (e.g., self-healing, dynamic traffic rerouting) that just aren’t possible in traditional OOB environments.

Get a Demo of IMI

Set up a 15-minute demo to see IMI in action. Our experts will show you how to automatically provision devices, recover failed equipment, and combat ransomware. Use the button to set up your demo now.

Watch How IMI Improves Security

Rene Neumann (Director of Solution Engineering) gives a 10-minute presentation on IMI and how it enhances security.

Cisco Live 2024 – Securing the Network Backbone

Why AI System Reliability Depends On Secure Remote Network Management

Thumbnail – AI System Reliability

AI is quickly becoming core to business-critical ops. It’s making manufacturing safer and more efficient, optimizing retail inventory management, and improving healthcare patient outcomes. But there’s a big question for those operating AI infrastructure: How can you make sure your systems stay online even when things go wrong?

AI system reliability is critical because it’s not just about building or using AI – it’s about making sure it’s available through outages, cyberattacks, and any other disruptions. To achieve this, organizations need to support their AI systems with a robust underlying infrastructure that enables secure remote network management.

The High Cost of Unreliable AI

When AI systems go down, customers and business users immediately feel the impact. Whether it’s a failed inference service, a frozen GPU node, or a misconfigured update that crashes an edge device, downtime results in:

  • Missed business opportunities
  • Poor customer experiences
  • Safety and compliance risks
  • Unrecoverable data losses

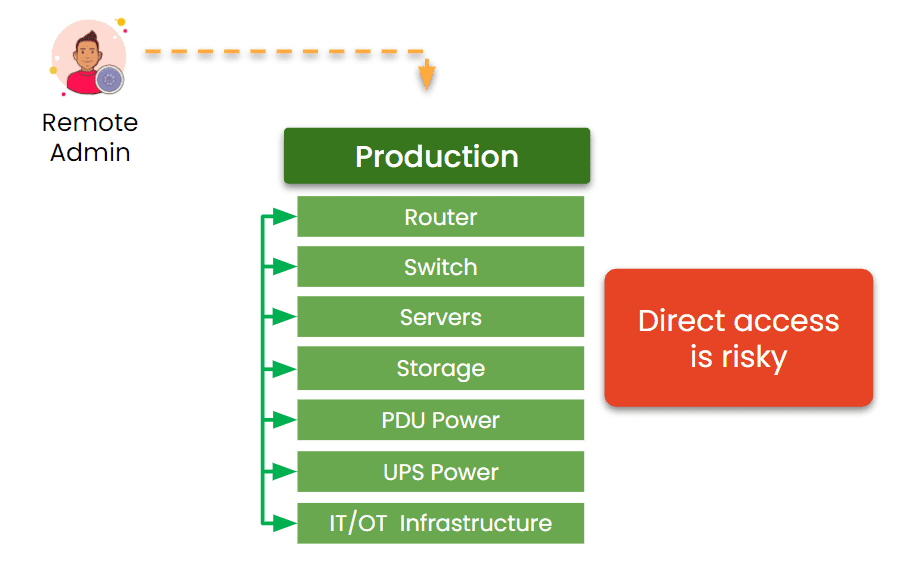
So why can’t admins just remote-in to fix the problem? Because traditional network infrastructure setups use a shared management plane. This means that management access depends on the same network as production AI workloads. When your management tools rely on the production network, you lose access exactly when you need it most – during outages, misconfigurations, or cyber incidents. It’s like if you were free-falling and your reserve parachute relied on your main parachute.

Direct remote access is risky

Image: Traditional network infrastructures are built so that remote admin access depends at least partially on the production network. If a production device fails, admin access is cut off.

This is why hyperscalers developed a specific best practice that is now catching on with large enterprises, Fortune companies, and even government agencies. This best practice is called Isolated Management Infrastructure, or IMI.

What is Isolated Management Infrastructure?

Isolated Management Infrastructure (IMI) separates management access from the production network. It’s a physically and logically distinct environment used exclusively for managing your infrastructure – servers, network switches, storage devices, and more. Remember the parachute analogy? It’s just like that: the reserve chute is a completely separate system designed to save you when the main system is compromised.

IMI separates management access from the production network

Image: Isolated Management Infrastructure fully separates management access from the production network, which gives admins a dependable path to ensure AI system reliability.

This isolation provides a reliable pathway to access and control AI infrastructure, regardless of what’s happening in the production environment.

How IMI Enhances AI System Reliability:

  1. Always-On Access to Infrastructure
    Even if your production network is compromised or offline, IMI remains reachable for diagnostics, patching, or reboots.
  2. Separation of Duties
    Keeping management traffic separate limits the blast radius of failures or breaches, and helps you confidently apply or roll back config changes through a chain of command.
  3. Rapid Problem Resolution
    Admins can immediately act on alerts or failures without waiting for primary systems to recover, and instantly launch a Secure Isolated Recovery Environment (SIRE) to combat active cyberattacks.
  4. Secure Automation
    Admins are often reluctant to apply firmware/software updates or automation workflows out of fear that they’ll cause an outage. IMI gives them a safe environment to test these changes before rolling out to production, and also allows them to safely roll back using a golden image.

IMI vs. Out-of-Band: What’s the Difference?

While out-of-band (OOB) management is a component of many reliable infrastructures, it’s not sufficient on its own. OOB typically refers to a single device’s backup access path, like a serial console or IPMI port.

IMI is broader and architectural: it builds an entire parallel management ecosystem that’s secure, scalable, and independent from your AI workloads. Think of IMI as the full management backbone, not just a side street or second entrance, but a dedicated freeway. Check out this full breakdown comparing OOB vs IMI.

Use Case: Finance

Consider a financial services firm using AI for fraud detection. During a network misconfiguration incident, their LLMs stop receiving real-time data. Without IMI, engineers would be locked out of the systems they need to fix, similar to the CrowdStrike outage of 2024. But with IMI in place, they can restore routing in minutes, which helps them keep compliance systems online while avoiding regulatory fines, reputation damage, and other potential fallout.

Use Case: Manufacturing

Consider a manufacturing company using AI-driven computer vision on the factory floor to spot defects in real time. When a firmware update triggers a failure across several edge inference nodes, the primary network goes dark. Production stops, and on-site technicians no longer have access to the affected devices. With IMI, the IT team can remote-into the management plane, roll back the update, and bring the system back online within minutes, keeping downtime to a minimum while avoiding expensive delays in order fulfillment.

How To Architect for AI System Reliability

Achieving AI system reliability starts well before the first model is trained and even before GPU racks come online. It begins at the infrastructure layer. Here are important things to consider when architecting your IMI:

  • Build a dedicated management network that’s isolated from production.
  • Make sure to support functions such as Ethernet switching, serial switching, jumpbox/crash-cart, 5G, and automation.
  • Use zero-trust access controls and role-based permissions for administrative actions.
  • Design your IMI to scale across data centers, colocation sites, and edge locations.

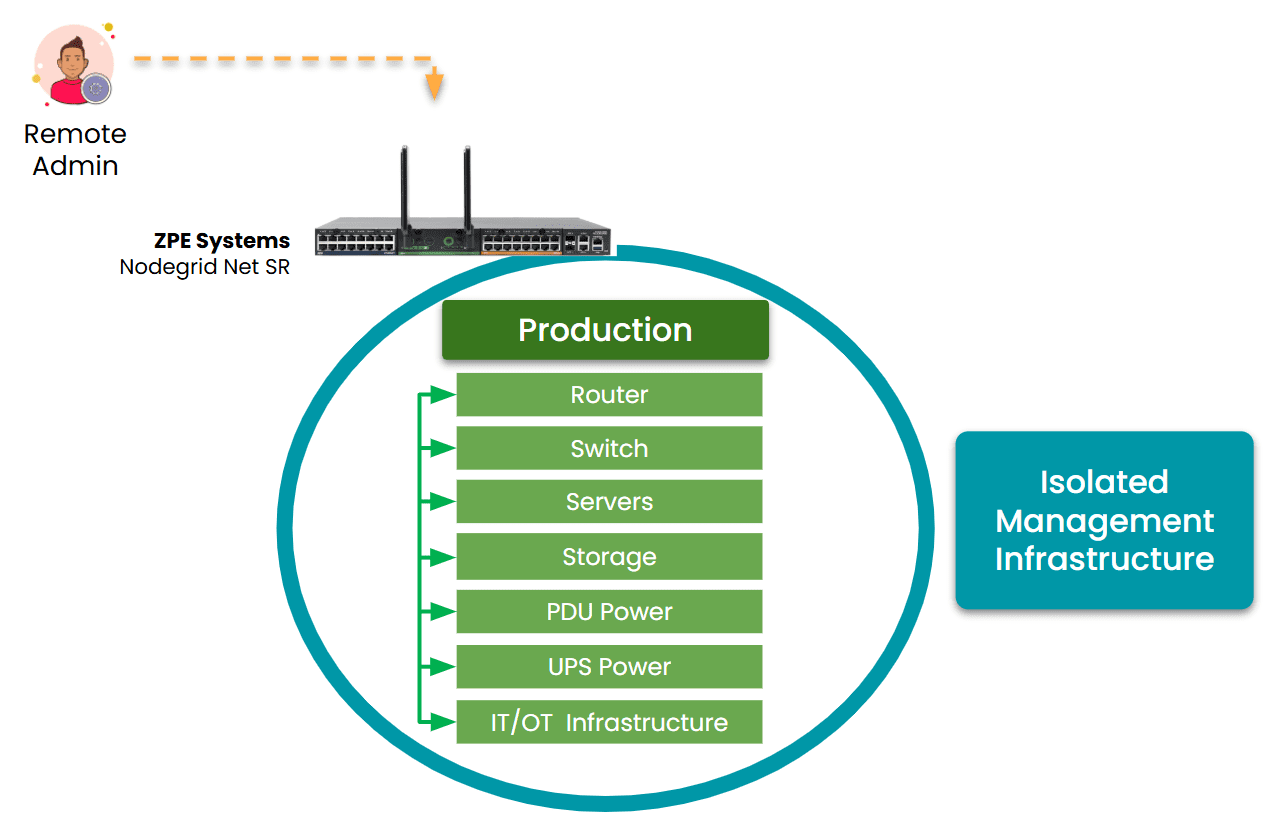
How the Nodegrid Net SR isolates and protects the management network.

Image: Architecting AI system reliability using IMI means deploying Ethernet switches, serial switches, WAN routers, 5G, and up to nine total functions. ZPE Systems’ Nodegrid eliminates the need for separate devices, as these edge routers can host all the functions necessary to deploy a complete IMI.

By treating management access as mission-critical, you ensure that AI system reliability is built-in rather than reactive.

Download the AI Best Practices Guide

AI-driven infrastructure is quickly becoming the industry standard. Organizations that integrate an Isolated Management Infrastructure will gain a competitive edge in AI system reliability, while ensuring resilience, security, and operational control.

To help you implement IMI, ZPE Systems has developed a comprehensive Best Practices Guide for Deploying Nvidia DGX and Other AI Pods. This guide outlines the technical success criteria and key steps required to build a secure, AI-operated network.

Download the guide and take the next step in AI-driven network resilience.