Providing Out-of-Band Connectivity to Mission-Critical IT Resources

Implementing a Network Modernization Strategy for Large-Scale Organizations
Two engineers plan a network modernization strategy from a platform overlooking racks of data center infrastructurea
The COVID-19 pandemic forced many large-scale organizations to decentralize their business operations to enable remote work, which shined a spotlight on how outdated their enterprise networks are. As other world events like wars, a recession, and virus resurgences continue to impact business, organizations must modernize their network infrastructure if they want to survive. However, their survival is also contingent on their ability to meet SLAs and maintain 24/7 availability, so it’s crucial to minimize the disruption caused by infrastructure upgrades. This blog provides advice to large-scale organizations on how to implement a network modernization strategy that minimizes disruptions while leaving room for future growth and innovation.

The importance of network modernization

Network infrastructure updates are expensive and can be disruptive, leaving many large companies wondering if the payoff is worth the risks. However, when COVID-19 struck, these organizations were left scrambling to replace their outdated and insecure VPN solutions with more robust remote connectivity technology. Similarly, in the current recession, enterprises that put off network modernization in the past are now finding themselves without the remote management and orchestration capabilities they need to keep their infrastructure running optimally with reduced staff. Even without the looming threat of major world disruptions, outdated network infrastructure poses a risk to large-scale organizations. Obsolete devices are no longer patched by the vendor, which means any vulnerabilities that exist will remain open for hackers to exploit. Older equipment is also more likely to break, and may not be supported by the provider, making it more difficult and expensive to recover from a failure. Plus, outdated infrastructure hampers an enterprise’s ability to innovate with new technologies to stay competitive in the market. Upgrading network infrastructure is expensive, time-consuming, and requires careful planning to prevent business interruption. However, investing in network modernization now will save you from more costly disruptions in the future.

A network modernization strategy for large-scale organizations

Enterprises need to carefully plan their path to network modernization to ensure they can meet their customer SLAs by avoiding outages and performance degradation. Here are some tips for implementing a network modernization strategy that minimizes disruption while leaving room for future growth.

Bridge the gap with a vendor-agnostic platform

To ensure a smooth upgrade process, organizations will gradually upgrade their infrastructure by replacing individual solutions one at a time. There’s typically an extended window of time in which there are both legacy and modern devices that need to be monitored, managed, and supported. This creates additional complexity for administrators who need to learn how to use the new solutions, integrate them with the existing infrastructure, and ensure there’s little-to-no impact on end users. It’s especially challenging when they need to use different management platforms to access and control each solution. That’s why it’s important to implement a vendor-agnostic network management platform that supports legacy and multi-vendor solutions. A vendor-agnostic platform gives administrators a single pane of glass from which to control the entire heterogeneous network architecture, simplifying day-to-day management and allowing them to focus on optimizing performance and implementing future upgrades. Plus, a unified platform makes it possible to extend new technological capabilities (like remote OOB management and automation) to older infrastructure, accelerating network modernization efforts.

Reduce downtime with remote out-of-band management

Any experienced admin knows that installations and updates are risky procedures. Even with the best-laid plan, errors can occur that prevent new systems from coming online, cause integration issues with existing infrastructure, or even take down dependent network services. The risk is even greater when the upgrades occur remotely without any technicians on-site to power cycle devices or reconfigure systems offline. What if there’s an outage or severe disruption, but COVID lockdowns or natural disasters prevent staff from entering these locations? Remote out-of-band (OOB) management creates an alternative path that admins use to access remote infrastructure. It creates an out-of-band network that’s dedicated to infrastructure management and orchestration and that doesn’t rely on the availability of the production network. That means administrators can access and troubleshoot offline devices remotely, reducing the duration and impact of downtime. Remote OOB management makes it safer for large-scale organizations to implement a network modernization strategy and ensures the continued stability and availability of enterprise infrastructure.

Streamline deployments with automation

Even when new infrastructure deployments run smoothly, they take considerable time and effort on the part of network administrators. Large, global organizations have complex and highly distributed network architectures with thousands of moving parts that need to be upgraded or replaced. Just configuring and installing all of these new solutions can add significant delays to the network modernization process. Plus, configuring so many devices is tedious and prone to human error, causing more delays as admins troubleshoot and fix deployment failures. For example, a typo in an IP address on one device could prevent dependent services from deploying correctly, forcing teams to retrace their steps and waste time identifying the error. Automation is the key to streamlining device deployments and reducing configuration errors. For example, Zero Touch Provisioning (ZTP) allows admins to provision new devices automatically over the network using definition files. These files can be reused as many times as needed to deploy many identical solutions across the enterprise network, significantly reducing the time and effort required to modernize infrastructure. Plus, configuration files can be tested pre-deployment to ensure there are no errors or security vulnerabilities. Vendor-agnostic network management platforms, OOB management, and automation are crucial components of a smooth network modernization strategy. Implementing this strategy is easier if you choose a management solution that integrates all these capabilities into a single, unified platform.

Make Nodegrid a part of your network modernization strategy

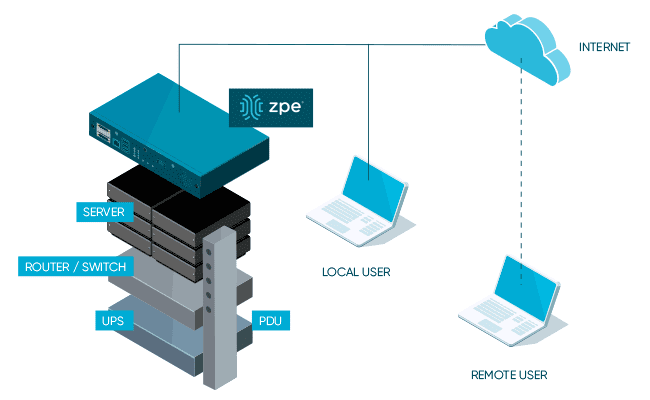
The Nodegrid platform from ZPE Systems delivers vendor-agnostic control, Gen 3 OOB management, and end-to-end network automation capabilities in a single box. Nodegrid has helped large-scale organizations like the Internet Association of Australia update their network infrastructure without disrupting business. Nodegrid serial consoles support both legacy and modern Cisco pinouts, allowing them to dig their hooks into any device in your network infrastructure. That means you can use the ZPE Cloud solution to extend automation and orchestration to your entire heterogeneous architecture, supercharging your network modernization efforts. Nodegrid uses high-speed OOB interfaces (e.g., 5G/4G cellular) to provide admins with a fast and reliable connection for remote upgrades, management, and orchestration. Nodegrid allows you to power cycle devices, enter BIOS menus, manage power load distribution, and more from anywhere in the world with an internet connection. This makes it easier and safer for large-scale organizations to remotely upgrade their network infrastructure and ensures continuous management availability to prevent downtime in the future. The vendor-agnostic Nodegrid platform also allows you to extend automation features like ZTP to both legacy and modern solutions in your network infrastructure. Nodegrid supports integrations with your choice of third-party automation tools, or you can use Nodegrid hardware to directly host custom scripts and automation apps. This both streamlines the network modernization process and gives you the ability to grow and evolve your network with emerging automation technologies like AIOps. Nodegrid streamlines network modernization strategies by providing vendor-agnostic management, remote OOB management, and end-to-end automation support in a single platform. 

Want to learn more about Nodegrid’s role in enterprise?

To learn more about Nodegrid’s role in an enterprise network modernization strategy, contact ZPE Systems today. Contact Us
Using AIOps and Machine Learning To Manage Automated Network Infrastructure

shutterstock_1825096265(1)

Automation is the key to maintaining optimal network performance and availability during tumultuous times. A resilient, automated network keeps functioning even if administrators can’t physically access the infrastructure or when a recession forces companies to reduce their IT workforce. A network automation framework includes all the tools, technologies, and practices required to build a resilient and fully automated enterprise network infrastructure.

The four building blocks of a resilient network automation framework include:

  1. IT/OT production infrastructure
  2. Automation infrastructure
  3. Orchestration infrastructure
  4. AIOps

In previous blogs, we focused on the building blocks that enable network automation and orchestration. In this blog, we’ll discuss how AIOps and machine learning help teams manage their automation and orchestration—and the massive amounts of data produced by their automated systems—more efficiently.

What is AIOps?

AIOps—artificial intelligence for IT operations—was originally introduced by Gartner in 2017. It uses AI technologies like machine learning (ML) and natural language processing (NLP) to analyze IT operations data. This data is pulled in from many different sources, including monitoring and visibility platforms, environmental monitoring sensors, event logs, and firewalls. AIOps utilizes that data to automate tasks like event correlation, anomaly detection, and root cause analysis (RCA) as well as to predict future outcomes and provide valuable business insights.

What’s the difference between AI and machine learning?

Before we delve any deeper into the specific uses for and benefits of AIOps, it’s important to clarify what we mean when we talk about technologies like AI and machine learning.

AI stands for artificial intelligence, which is defined as a computer’s ability to display human-like intelligence through behaviors like learning from new data, drawing conclusions based on that data, and coming up with solutions to problems.

Machine learning, on the other hand, describes a computer’s ability to process large quantities of data and learn from it. Learning is a major requirement for AI, which means that all machine learning applications could be considered AI. However, not all AI is machine learning—artificial intelligence uses additional technology to make decisions, solve problems, and perform other automated functions.

Essentially, AI describes a broad range of technologies, whereas machine learning is a more specific subset of technologies included in the AI umbrella. In the context of AIOps, however, machine learning is often the only artificial intelligence technology in use.

Using AIOps and machine learning to manage automated network infrastructure

In an automated enterprise network, AIOps and machine learning use advanced algorithms to provide in-depth analysis of all the data collected from production infrastructure, automation components, and orchestration systems. AIOps solutions can even take things a step further by making decisions and solving problems based on the results of that data analysis.

Some examples of how AIOps and machine learning can be used to manage automated network infrastructure include:

Security

Cyberattacks and data breaches are major threats to the reliability and performance of network infrastructure. In addition to the financial losses caused by sensitive data exfiltration and reputation loss, security breaches are also a leading cause of downtime, which directly impacts business revenue. According to the ITIC’s 2022 Global Server Hardware Security survey, 76% of enterprises cited security breaches as the top cause of downtime. That means network security is paramount to the resilience of an automated infrastructure.

For many years, network security relied on signature-based detection for jobs like intrusion prevention, antivirus, and spam filtering. Signature-based detection involves comparing an incoming request to a database of known threats to see if it matches—if not, it’s assumed to be safe and allowed into the network. This approach only works if the database is kept up to date and if all incoming threats have been identified in the past. Signature-based detection often fails to catch zero-day exploits or novel malware that it hasn’t seen before, plus it tends to generate a lot of false positives.

AIOps security solutions overcome this problem by learning from past experiences. Machine learning is able to extract information from past threats and then develop algorithms to recognize, predict, and categorize a new threat that it’s never seen before. This makes AIOps adept at preventing new threats as well as detecting ones already on the network.

You can also use AIOps to analyze data from infrastructure logs and other security solutions to spot the more subtle signs of a breach that’s already happened or that’s currently taking place. For example, AIOps and machine learning may detect an unusually large amount of data leaving the network, which could indicate that a malicious actor is exfiltrating sensitive information. Another security use for AI is called User and Entity Behavior Analytics (UEBA), which inspects account activity on a network and reports anomalous behavior that could indicate an account has been compromised.

AIOps improves upon automated network security solutions by using adaptive learning and predictive analysis to detect new and unusual threats with a greater degree of accuracy. It also takes advantage of the massive amounts of data produced by security appliances and network infrastructure to identify the subtle clues left behind by sophisticated cybercriminals. This makes AIOps a valuable tool for maintaining the security and availability of an automated network infrastructure.

Monitoring

An automated network infrastructure generates a massive quantity of logs that can be used to assess health and performance as well as to identify potential issues before they cause any outages or downtime. However, humans aren’t very good at sifting through large amounts of data to figure out what’s relevant and what isn’t.

Many monitoring solutions use basic automation to help weed out important data, for example by letting admins set performance thresholds that generate automatic alerts when devices fall out of the optimal operating range. However, this kind of automation creates a lot of false positives, which are tedious to sort through and could lead to admin neglect or complacency. It can also only detect specific symptoms and issues that fall within the scope of the monitoring thresholds programmed by a sysadmin, which means it can’t adapt to changing circumstances or predict new problems that weren’t anticipated by the admin in advance.

An AIOps monitoring solution collects all the logs produced by automated infrastructure and analyzes them in real time. Sysadmins can still set performance thresholds and program automatic alerts, but AIOps also uses machine learning to “think outside the box” by recognizing patterns and detecting anomalies it wasn’t programmed to look for. That means issues are identified faster, potentially before they cause any noticeable problems for end-users.

Machine learning also gives AIOps monitoring solutions the ability to track performance over time and predict future outcomes based on historical data. For example, organizations can use AIOps analysis to plan infrastructure upgrade schedules based on when device performance is predicted to start degrading, or in advance of a predicted spike in demand for a particular location. This gives CIOs and IT managers the ability to make smarter decisions about where and when to invest money and how to prioritize new initiatives.

AIOps monitoring solutions work well with data lakes, which are large repositories for unstructured data. Data lakes are an efficient way to process large quantities of data, such as monitoring and security logs. This enables the data to be used by AIOps and other big data tools.

AIOps transforms the flood of logs generated by complex, automated network infrastructures into actionable data. Enterprises can use AIOps and machine learning to catch subtle issues before they turn into major problems, improving the performance and availability of network resources. AIOps also provides valuable business intelligence that organizations can use to make smarter and more cost-effective decisions during recessions and other tumultuous events.

Root cause analysis (RCA)

When there’s an outage or other business interruption, the main priority is fixing whatever is preventing systems from operating normally so that systems can get back online. Often, this means fixing the symptoms of some deeper underlying problem. If that core problem isn’t addressed, it’s likely to cause another outage in the future. That means administrators must perform a root cause analysis (RCA) to discover the source, come up with a fix, and document everything for future reference.

Root cause analysis involves digging through devices, applications, and service logs, which human engineers can’t do as efficiently as AI solutions. AIOps can comb through all the relevant logs to determine the most likely cause of the problem as well as recommend the best solution to fix it. Incidents are automatically generated, prioritized, and assigned to the correct team for resolution, ensuring the core problem is quickly and thoroughly fixed to prevent future outages.

Some AIOps solutions can even automatically resolve some issues without waiting for a human engineer to receive an alert, log in to the system, identify the problem, and implement a solution. This can significantly reduce the mean time to resolution (MTTR) and minimize expensive business interruptions.

Sorting through data is what AIOps does best, which makes it the perfect tool for RCA. AIOps can determine the root cause of automated infrastructure failures much faster than human admins, making it easier to fix these underlying problems before they cause future downtime. AI can even proactively implement fixes while issues are ongoing, allowing businesses to recover faster and reduce the cost of outages.

Implementing AIOps and machine learning in a resilient network automation framework

AIOps is the final layer of the network automation framework because it reduces the management complexity involved in monitoring, troubleshooting, and optimizing automated network infrastructure. Because AIOps needs to collect logs from every single component of the network automation framework, it must be a vendor-neutral solution that has access to your orchestration platform as well as all your management hardware and software. This will be much easier if your orchestration, automation infrastructure, and IT/OT management infrastructure are also vendor-neutral.

For example, the Nodegrid platform from ZPE Systems includes management devices like Gen 3 OOB serial consoles and integrated network edge routers that can bring your entire mixed-vendor environment under a single management umbrella. Nodegrid hardware is truly vendor-neutral, which means it can directly host your AIOps applications to help consolidate devices in your rack. The ZPE Cloud infrastructure orchestration platform also supports integrations with third-party and cloud-based AIOps solutions. Either way, you get network infrastructure management, monitoring, automation, orchestration, and AIOps in a single platform.

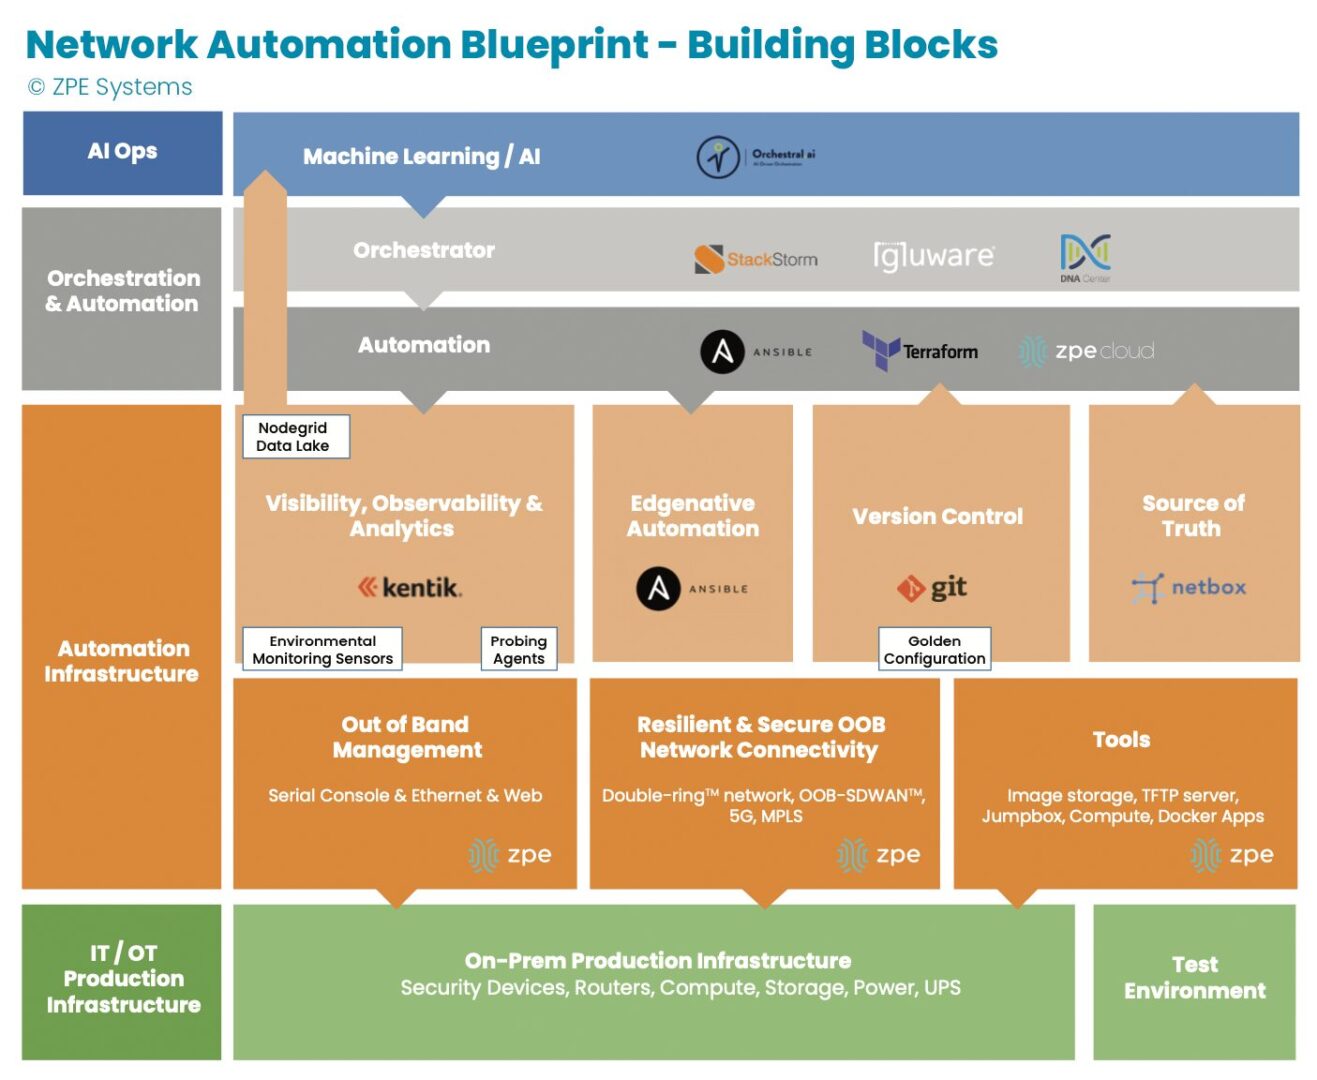
ZPE’s Network Automation Blueprint

AIOps works together with IT/OT production infrastructure, automation infrastructure, and orchestration to ensure network resiliency during uncertain times. The Network Automation Blueprint from ZPE Systems provides a reference architecture for achieving Gartner’s definition of hyperautomation as well as meeting the Open Networking User Group (ONUG) Orchestration and Automation recommendations.

Download the Network Automation Blueprint today and see how all these building blocks fit together to ensure network resiliency.

Ready to learn more about implementing AIOps and machine learning?

To learn more about implementing AIOps and machine learning with Nodegrid, contact ZPE Systems today.

Contact Us
A Guide to Infrastructure Orchestration and Automation

infrastructure orchestration and automation
As the recession continues to affect businesses across all industries, enterprise network resilience has never been more critical. The typical outage costs at least $100,000—a price tag that most companies can’t easily absorb in the current economic climate. However, decreasing business revenues have caused many companies, especially in the tech industry, to lay off large portions of their key IT staff. That means there are fewer administrators to monitor and manage network infrastructure and fewer engineers available to respond to issues and recover from outages.

Network automation is the key to ensuring 24/7 availability and optimal performance with less human interaction. A network automation framework provides all the tools and guidance needed to create a fully-automated network infrastructure that’s resilient to failure.

The four building blocks of a resilient network automation framework include:

  1. IT/OT production infrastructure
  2. Automation infrastructure
  3. Orchestration infrastructure
  4. AIOps

In previous blogs we discussed the role of IT/OT production infrastructure in network automation and how an IT/OT convergence strategy accelerates network automation. We also described the automation infrastructure components that enable end-to-end network automation. In this post, we’ll explain how infrastructure orchestration and automation build upon the previous two layers to enable streamlined, hyperautomated network resiliency. Our final blog in the series will conclude with a guide to using AIOps and other machine learning technologies to complete the network automation framework.

What is infrastructure orchestration and automation?

The infrastructure orchestration and automation layer contains the tools and paradigms used to efficiently manage and control that automation. The core components of infrastructure orchestration and automation include:

Version control

The automation infrastructure layer uses infrastructure as code (IaC) to decouple device configurations from the underlying hardware so they can be written as scripts or definition files that automatically provision network resources. In addition, this layer uses software-defined networking (SDN) to create a virtual control plane that overlays the production network infrastructure, allowing network management and optimization tasks to be written as automated scripts.

The goal of IaC and SDN is to reduce human error, speed up device provisioning, and build a more streamlined and resilient network infrastructure. However, IaC and SDN programming can be very complex, and not all sysadmins and network administrators are expert coders. In addition, an automated enterprise network has hundreds or even thousands of these definition files and scripts to store, manage, and deploy.

This is why a network automation framework should include version control in the orchestration and automation layer. Version control is a very familiar concept to programmers, especially in DevOps environments, but not all network and infrastructure teams have used it before. Version control involves storing all code in a centralized repository and then tracking and managing changes to that code.

Let’s say one administrator is responsible for configuring and maintaining the IaC definition file used to provision a particular model of Meraki AP. Here are some examples of how that workflow could break down when that one admin is out of the office for an extended period of time due to COVID-19 or gets laid off due to cutbacks in the organization:

  • Twenty new Meraki APs need to be deployed to a new site with identical configurations.
  • The existing definition needs to be updated and pushed out ASAP to patch a security vulnerability.
  • Someone discovers an error in the current version and they need to roll back to a previous configuration.

A version control system for IaC and SDN acts as the single source of truth for the entire automated infrastructure. All automation scripts and definition files are stored in one centralized location, so anyone with authorization can deploy identical devices with the push of a button. When an admin needs to change the code, those changes are tracked and can be rolled back at any time if a mistake is made. Version control systems even allow admins to leave notes explaining the reasoning or logic behind individual changes, so other team members can pick up where they left off, or in their absence, identify the root cause of issues.

Another key benefit of version control is that it facilitates the use of automated testing. QA and security analysts can run automated scans on code in the version control repository pre-production, so any misconfigurations or security vulnerabilities are identified and fixed before deployment. This reduces the risk of human error and improves the security and resiliency of the automated network infrastructure.

Version control is a core component of infrastructure orchestration and automation because it serves as the single source of truth for the entire automated network architecture.

Orchestrator

Automation is meant to make life easier, but it can be very complicated to manage on a large scale. Modern enterprise network architectures include thousands of moving parts in locations around the world and in the cloud. Automating each of these workflows means writing, testing, deploying, managing, and troubleshooting many different definition files and automation scripts. Doing all of that manually adds more work to overloaded and under-resourced network infrastructure teams, which increases the risk of something going wrong. Simply put, organizations need a way to automate their automation.

An orchestrator is a tool used to control all of the automated workflows on an enterprise network, just like a conductor orchestrates many different instruments and musicians into one cohesive symphony. An orchestrator uses management devices, like Gen 3 OOB serial consoles and SD-WAN gateway routers, to gain control over the physical and virtual network infrastructure. Administrators program the orchestrator to automatically deploy definition files or networking scripts (which it pulls from the version control system) in response to certain triggers. That means admins could potentially automate every step in every workflow, removing the need for human intervention and reducing the chance of errors.

Plus, an orchestrator can react to events much faster than even the best administrator. For example, if a spike in demand is overloading resources at one regional data center, the orchestrator can instantly deploy automated load-balancing workflows to reroute traffic before end-users notice any performance issues. This allows enterprises to maintain 24/7 network availability and performance even with reduced IT staff.

As part of a resilient network automation framework, the orchestrator should be vendor-agnostic (vendor-neutral). It needs to be compatible with all of the automation infrastructure components, as well as the production IT/OT solutions. It also needs to support all of the major third-party automation vendors, such as Ansible and Gluware, to give infrastructure teams the flexibility to use the tools they’re most comfortable with and that work best in their enterprise’s unique environment. Finally, the orchestrator needs to integrate with other tools within the orchestration and automation layer, including the version control system and the monitoring and analytics platform.

The orchestrator is what gives the “orchestration and automation” layer its name. It provides admins with the ability to automatically manage all the automated workflows that make up a resilient network infrastructure. An orchestrator reduces the risk of outages caused by human error and can automatically respond to and prevent potential issues.

Visibility & insights

It’s tempting to think of infrastructure orchestration and automation as a “set it and forget it” solution that can perfectly manage an enterprise network without any human oversight, but the technology isn’t quite there yet. Administrators need a way to monitor all the automated workflows, identify problems the orchestrator may have missed, and analyze the health and performance of the network infrastructure.

A visibility and insights platform collects logs from all the various components of the automated network infrastructure and aggregates the data in one centralized location. It provides visualizations of current device health and network performance, and may even include predictive analysis to power business insights. This gives administrators a big-picture overview of distributed, complex, and automated network architectures so they can ensure continuous availability and optimal performance.

As with the version control system and the orchestrator, the visibility and insights solution needs to be vendor-agnostic so it can dig into every single hardware and software solution in the automated network infrastructure. In a resilient network automation framework, the vendor-neutral version control, orchestrator, and visibility solutions are all combined in a single platform.

Infrastructure orchestration and automation with a single platform

A unified infrastructure orchestration and automation platform like ZPE Cloud simplifies the control and management of a fully-automated enterprise network. ZPE Cloud uses Nodegrid hardware—such as Gen 3 OOB serial consoles and integrated network edge routers—to deliver orchestration and automation to large, distributed, multi-vendor network infrastructures. The ZPE Cloud management app supports integrations with your choice of third-party version control and infrastructure automation solutions, or you can use Nodegrid hardware to directly host your automation software.

With ZPE Cloud, you also get comprehensive monitoring data on all connected infrastructure, plus, you can use Nodegrid environmental monitor sensors to gain insights on conditions in remote data centers and network closets.

ZPE’s Network Automation Blueprint

Infrastructure orchestration and automation works together with IT/OT production infrastructure, automation infrastructure, and AIOps to ensure network resiliency during uncertain times. The Network Automation Blueprint from ZPE Systems provides a reference architecture for achieving Gartner’s definition of hyperautomation as well as meeting the Open Networking User Group (ONUG) Orchestration and Automation recommendations.

In a future blog post, we’ll discuss the remaining building block of the Network Automation Blueprint in depth. In the meantime, you can read about IT/OT production infrastructure and automation infrastructure, or click here to get a sneak peek of the blueprint, which includes a 10-step checklist to get started with automation now.

Ready to learn more about infrastructure orchestration and automation?

To learn more about infrastructure orchestration and automation with ZPE Cloud and Nodegrid, contact ZPE Systems today.

Contact Us
Network Engineers: 5 Must-Have Tools During a Slow Economy

Network Engineers: 5 Must-Have Tools During a Slow Economy

Network engineers need powerful tools to keep digital services online and customers happy. This is especially true during economic downturn, when organizations must freeze hiring and put more strain on existing staff. Revenue relies on network availability, and with experts predicting a recession this winter, significant operational challenges are inevitable for most organizations.

The burden of overcoming these challenges falls on network engineers. Success means maintaining reliable services and reaping any professional benefits (salary increases, promotions, etc.). Failure, on the other hand, means the very realistic possibility of major business losses and job cuts, including yours.

In order to make sure you don’t fall into the latter scenario, here are five must-have tools and techniques to help network engineers overcome these challenges.

Tool 1. OOBI-LAN™

Out-of-band (OOB) management is an essential part of a network engineer’s toolkit. At the conceptual level, out-of-band is meant to provide management access to production equipment, even if the production equipment is offline.

One major problem is that many organizations invest a lot of time and money into their production infrastructure, but not into any dedicated OOB infrastructure. In other words, they deploy OOB solutions that rely in part on their production equipment, such as OOB VLANs connected to in-band switches. All it takes is a mistake, misconfiguration, or attack to bring down the production and management networks, leaving network engineers to rebuild the entire system from scratch while their services remain offline to customers. This is simply not acceptable in a slow economy, where the business’ resources and revenue are already too thin.

From the pandemic lockdowns, organizations have learned that they need a way to more quickly recover their network locations. According to the Uptime Institute’s 2022 Outage Analysis, outages lasting longer than 24 hours increased to nearly 30% in 2021. This has led many to build dedicated OOB infrastructure for the LAN (OOBI-LAN). They deploy a serial console locally to establish connectivity to the management ports of their sensitive equipment. Network engineers must use this serial console to access their production infrastructure. This serial console minimizes the attack surface since it’s the only device connected to the Internet, and allows network engineers to restore services even if production equipment is down.

Tool 2. OOBI-WAN™

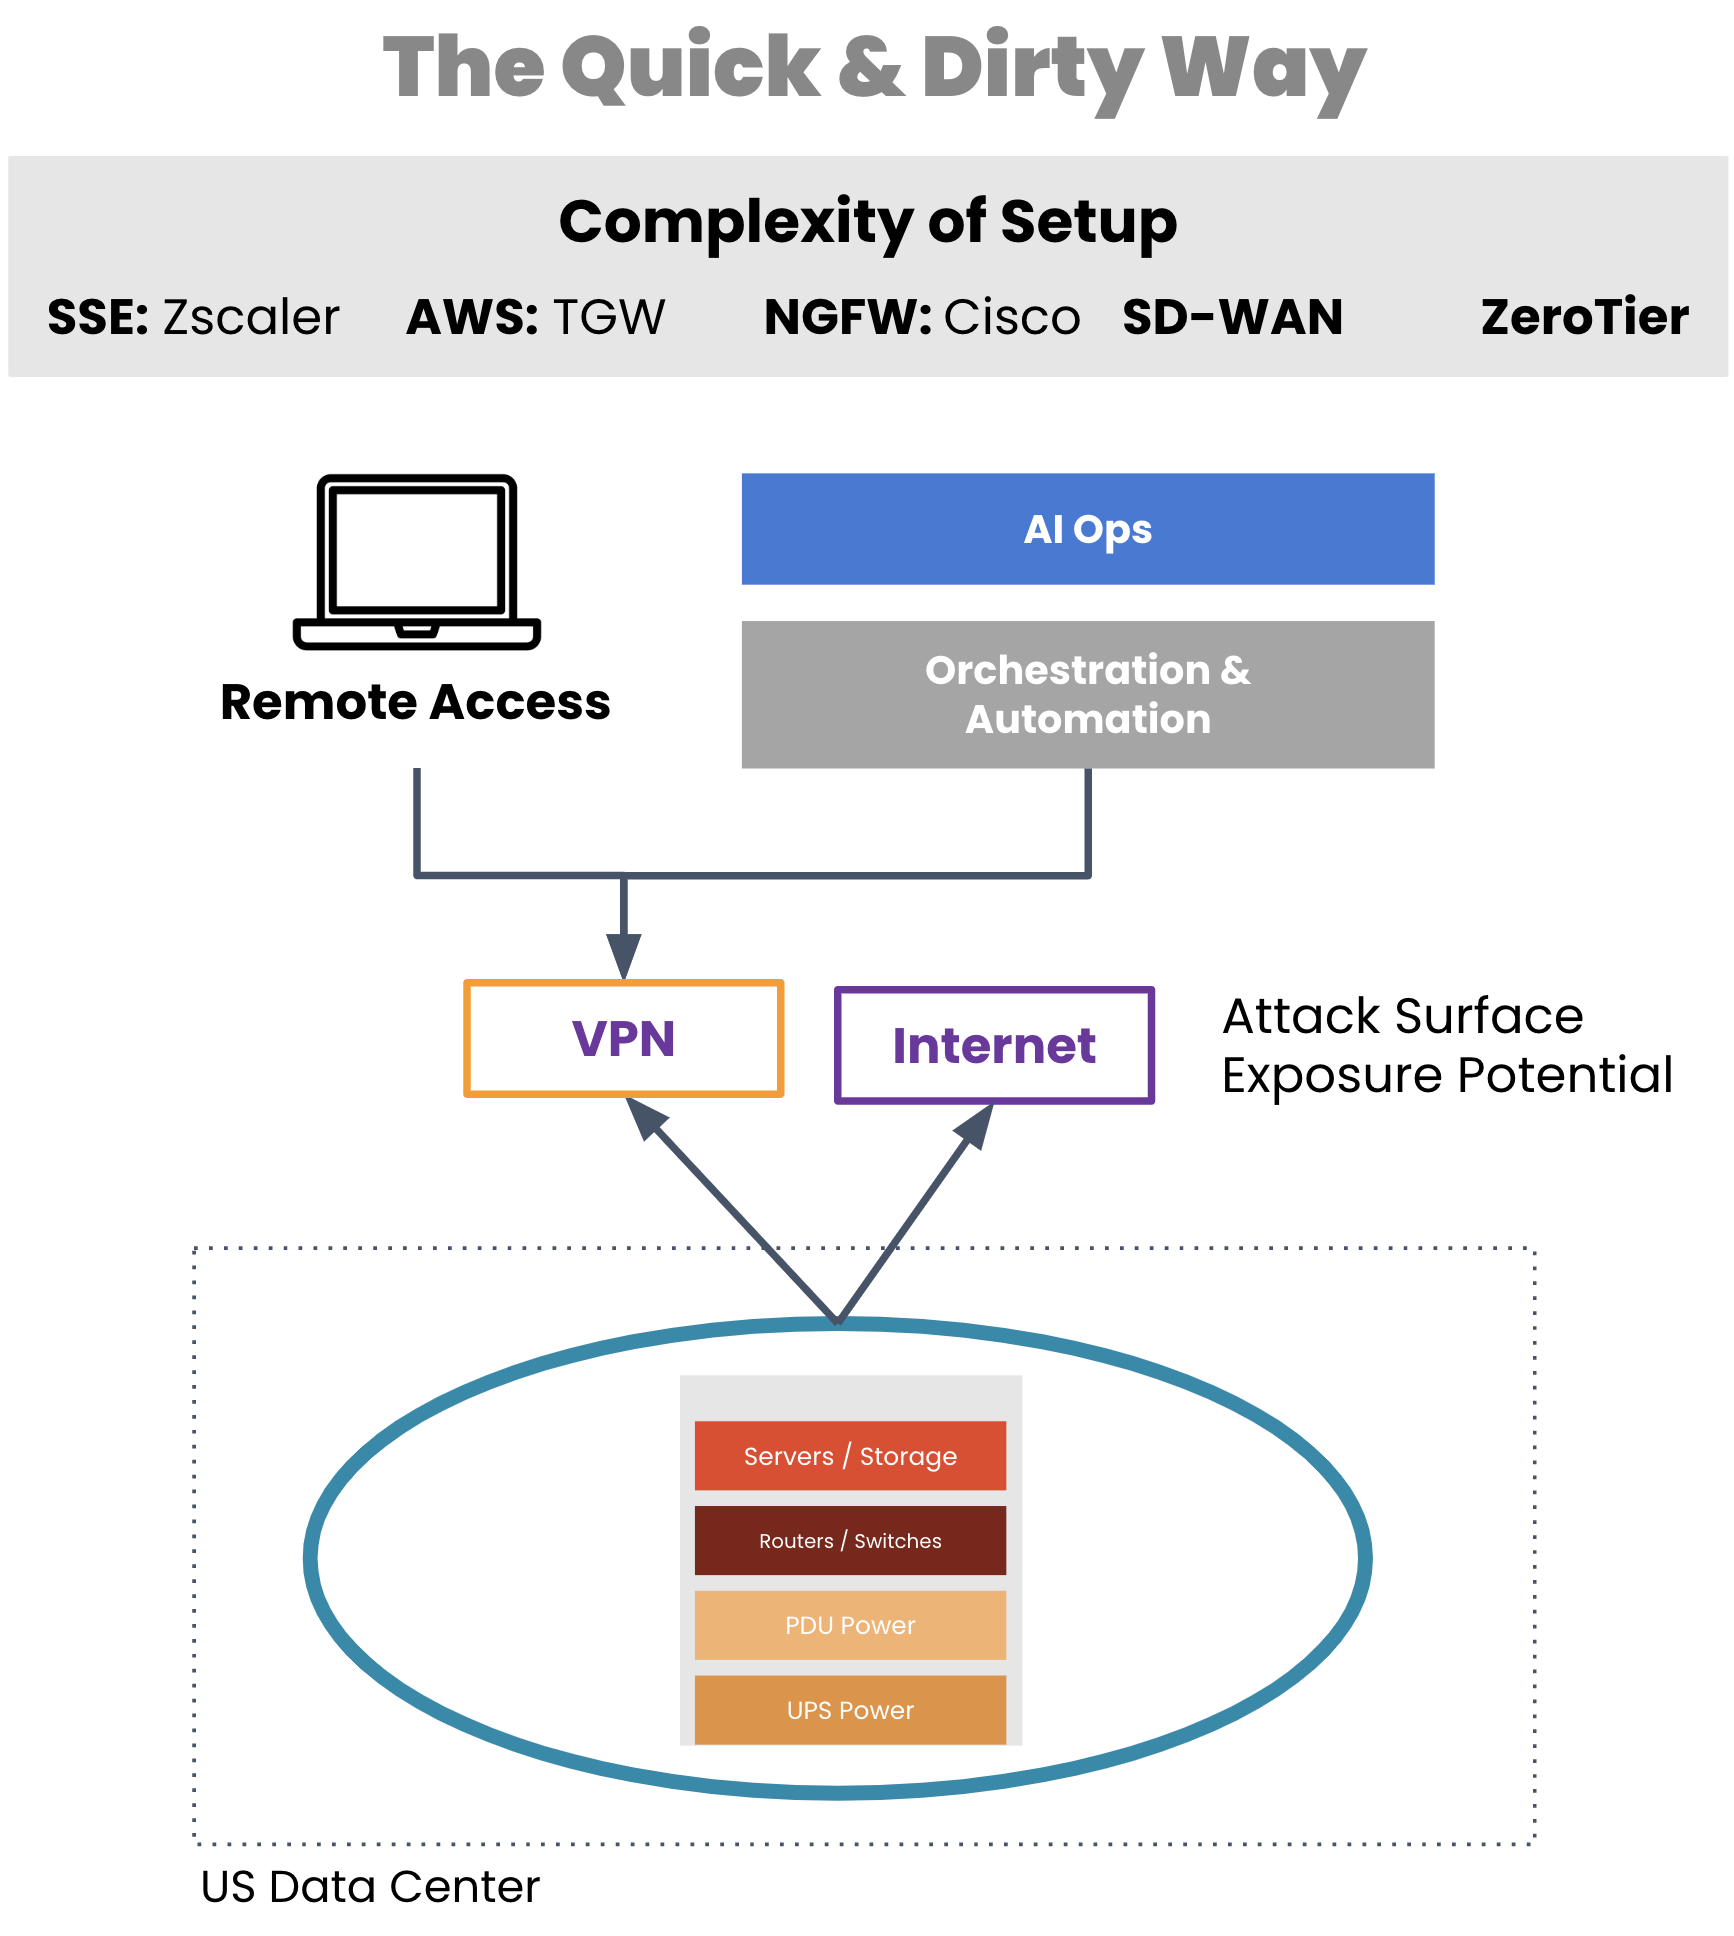
A critical tool for network engineers is out-of-band that enables remote WAN management. But typically, organizations employ a WAN management strategy that also relies on their production infrastructure, such as for creating VPN tunnels for management traffic. If a VPN tunnel becomes broken or the production gear fails, network engineers are suddenly left without remote access to their equipment.

Aside from a lack of availability, traditional OOB access comes with real security risks. Exposing LTE modems to the Internet, leveraging untrusted third-party VPN services, using OOB hardware that’s old and unpatched, and worse — exposing the management port of devices to public Internet. All of these are attack surfaces, any of which can give access to your infrastructure and be used as the pivot point to get to the rest of the infrastructure.

traditional WAN management approach

Image: Management access depends on production equipment to establish VPN tunnels. 

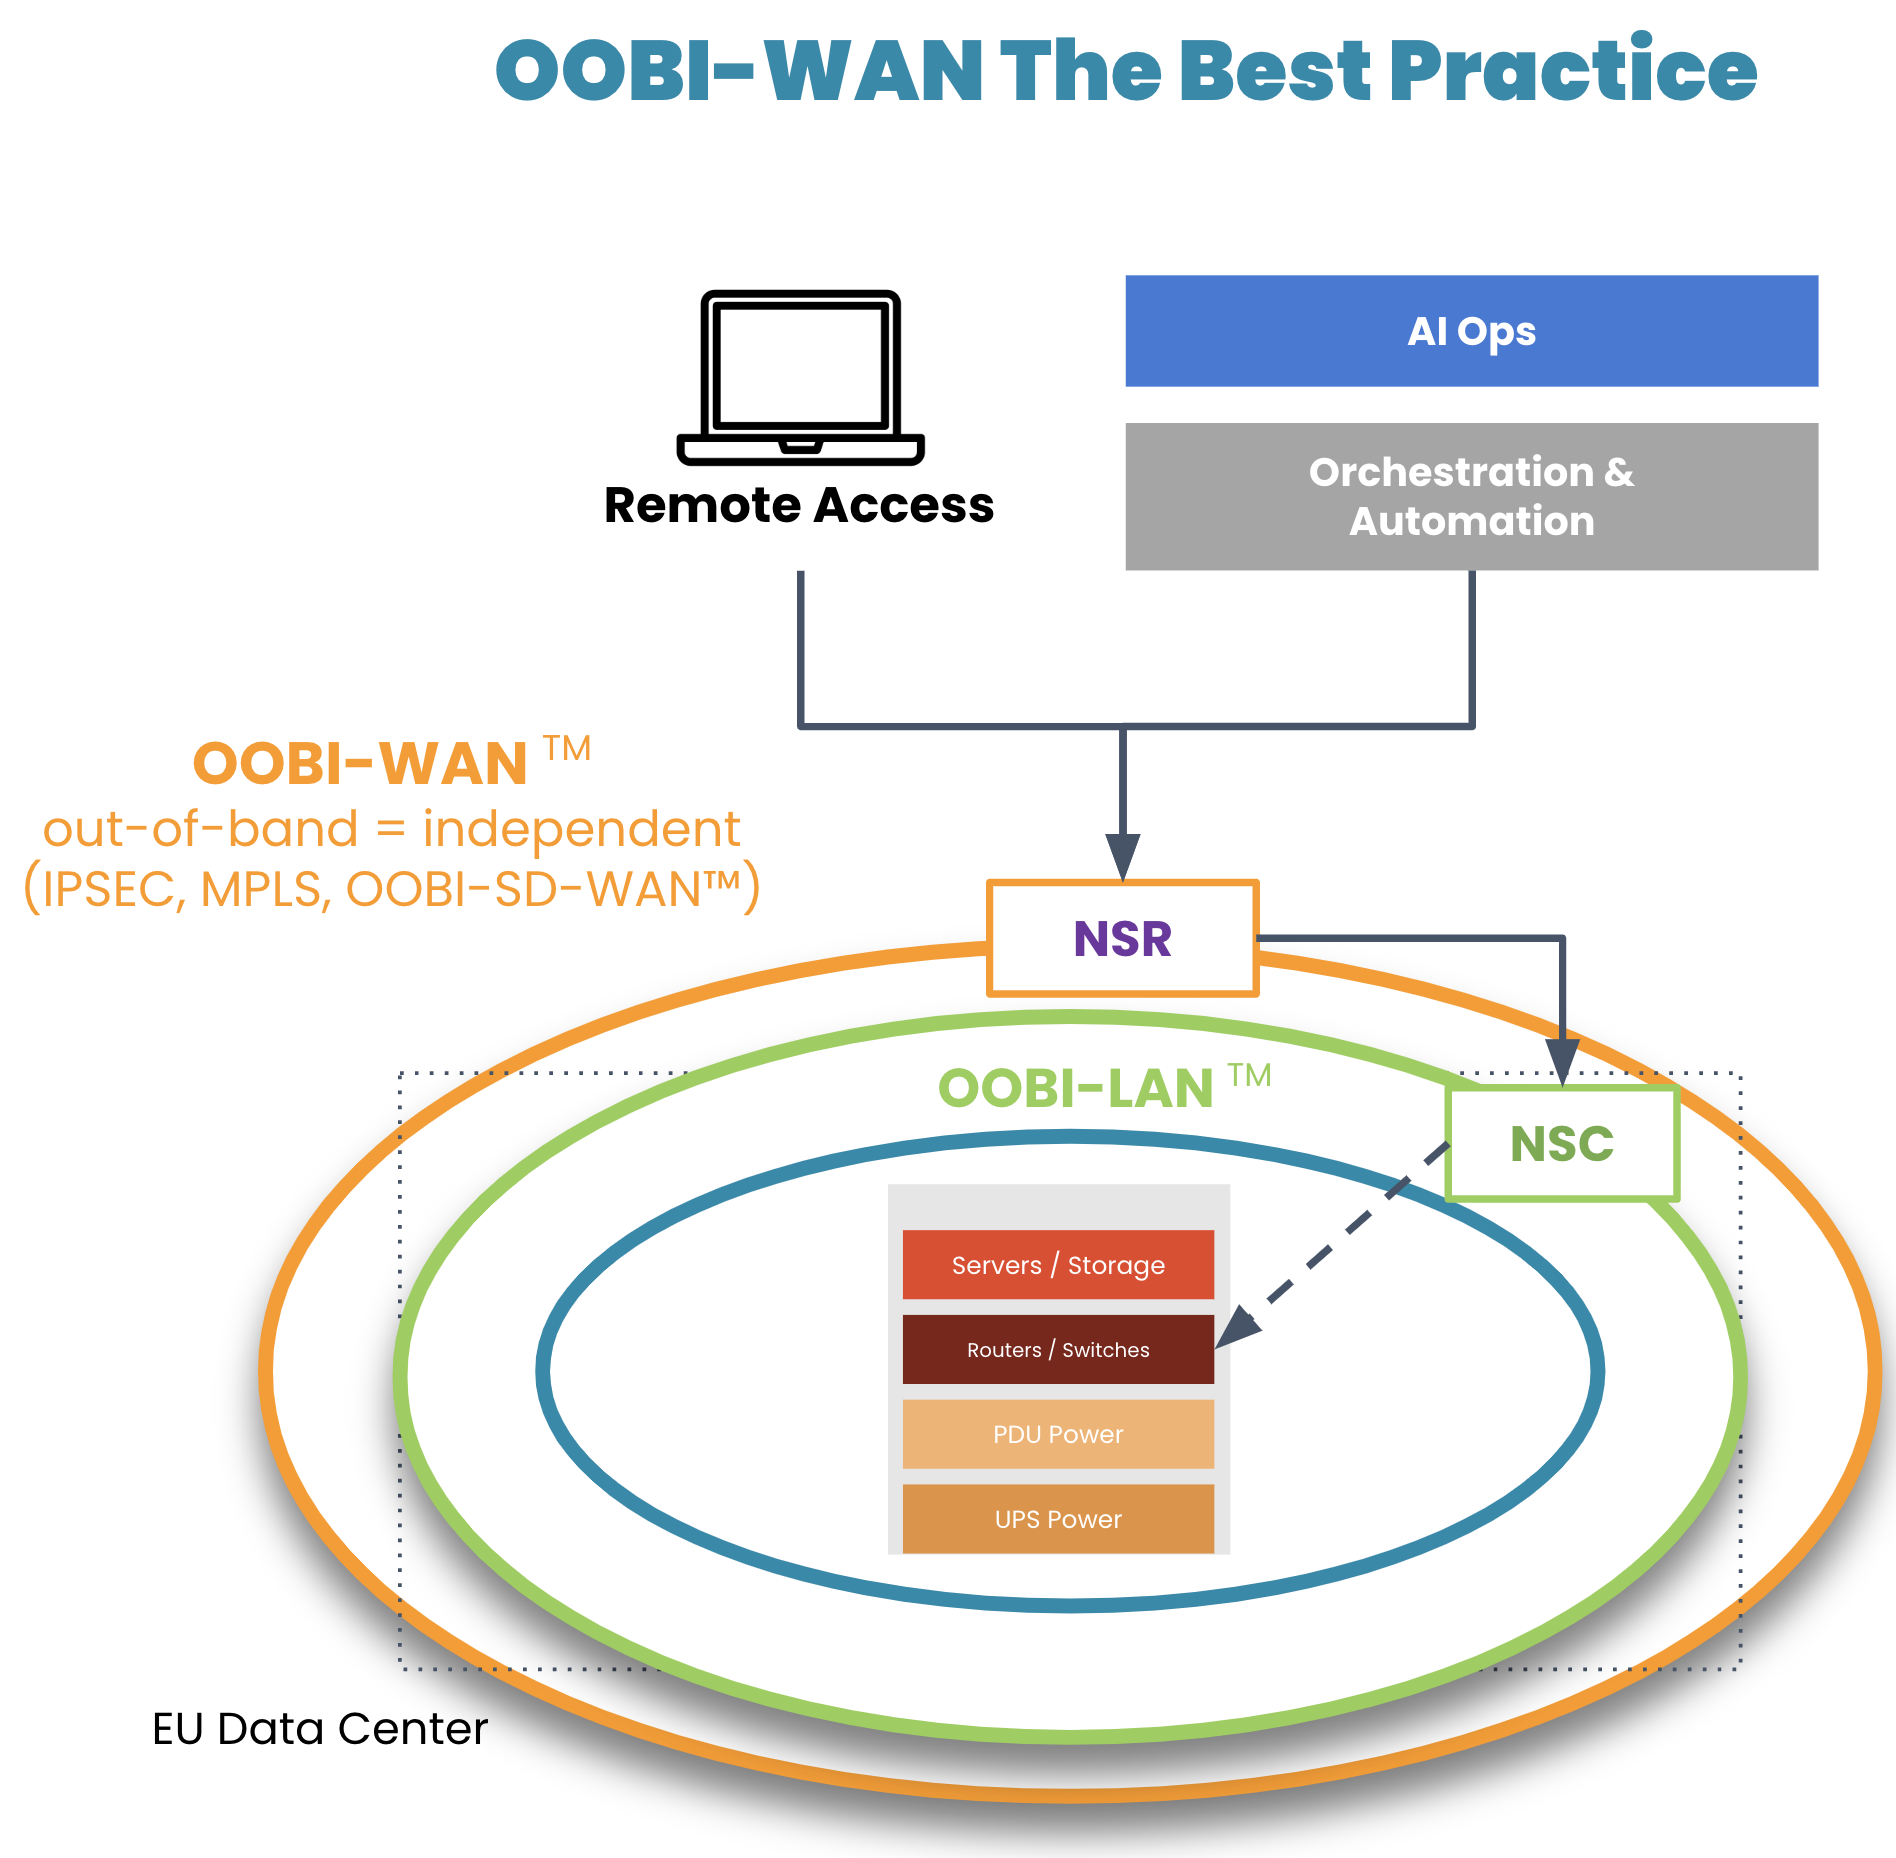
On top of their OOBI-LAN, organizations have built dedicated OOB infrastructure for the WAN (OOBI-WAN – there’s a Star Wars reference somewhere in there) for added resilience against these scenarios.

OOBI-WAN is the WAN best practice

Image: OOBI-WAN and OOBI-LAN create a fully separate out-of-band infrastructure that can be used to completely rebuild production infrastructure. 

OOBI-WAN uses MPLS, IPsec, or SD-WAN links to create an overlay network dedicated specifically to management traffic. This gives network engineers private access to their infrastructure for management and troubleshooting, essentially creating a completely separate OOB network that does not rely on any part of the production network. OOBI-WAN lets network engineers use their WAN connection to remotely access their OOBI-LAN and fully rebuild their distributed networks, regardless of the state of their production infrastructure.  

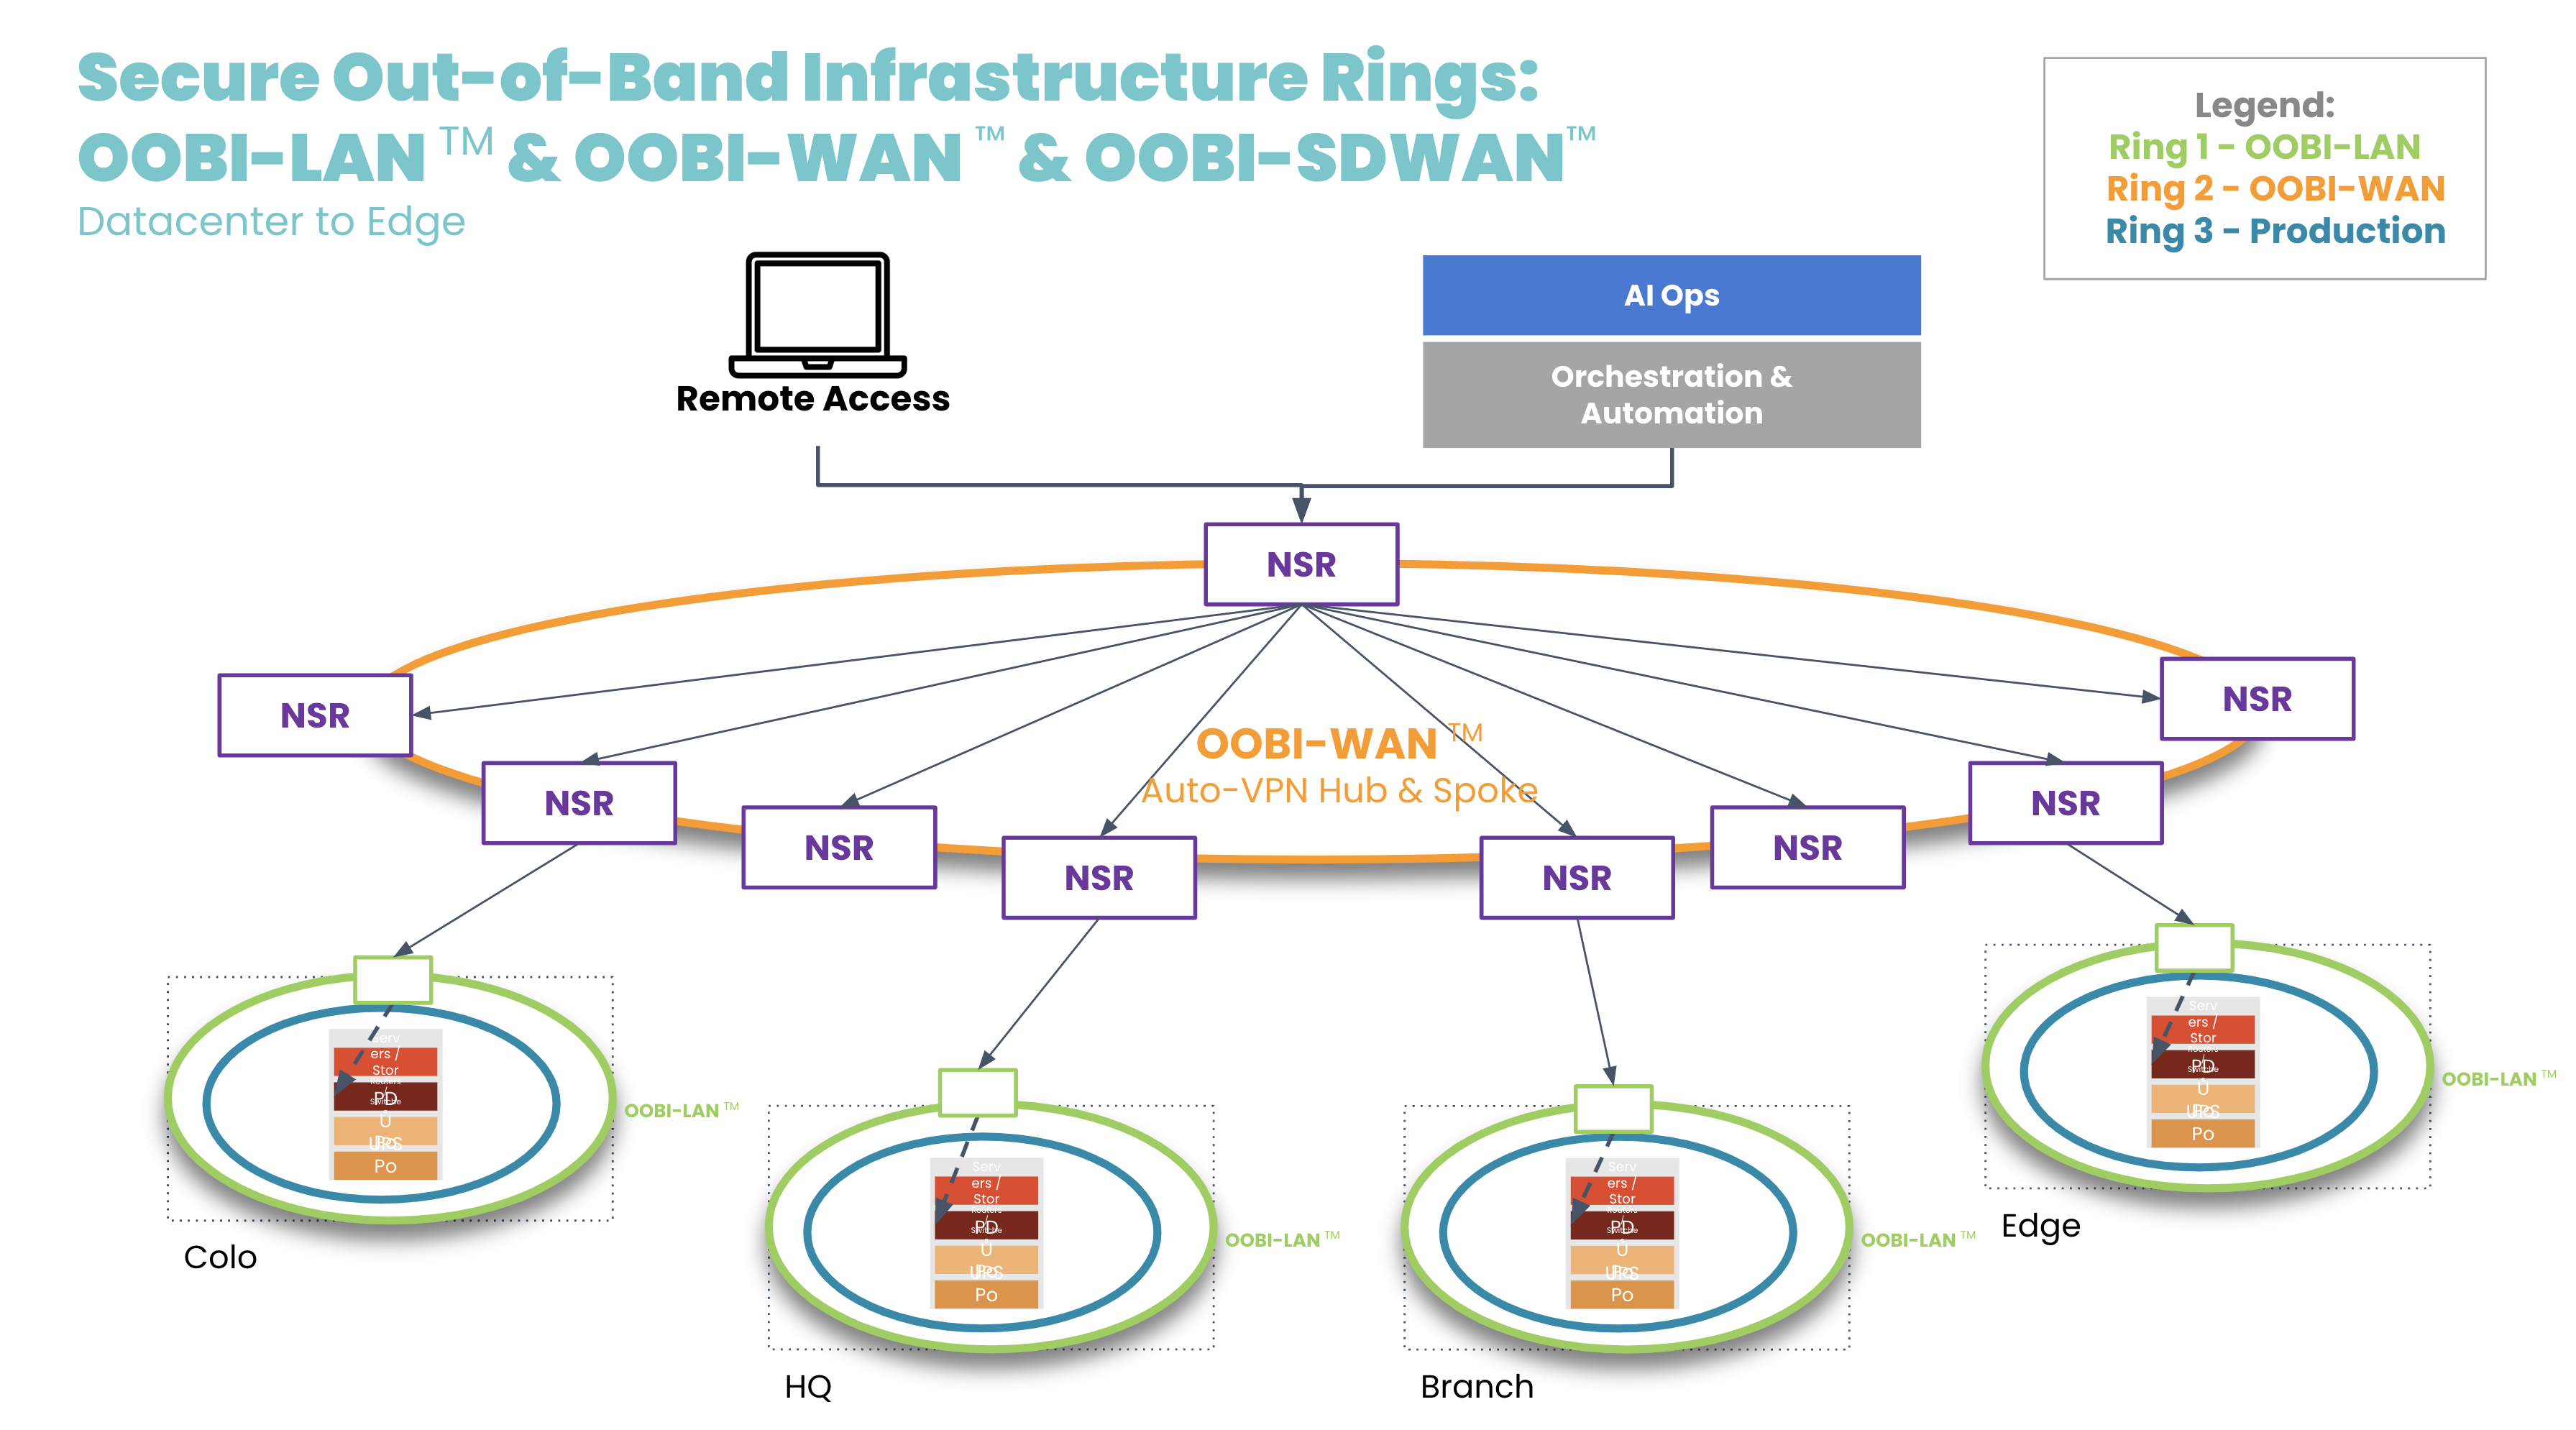
A key part of OOBI-WAN is the inherent security that is built at all layers. To build secure OOBI-WAN, the best practice is to use OOBI-SDWAN™ which automates the building of VPN tunnels between all the nodes that need to be managed. OOBI-SDWAN provides the expected auto-VPN feature which means VPN encryption keys remain secure, as they don’t need to be copied/pasted/typed into multiple third-party devices. OOBI-SDWAN also ensures that an SLA is provided on the OOBI network along with observability dashboards of connectivity and the access state of the network. The combination of OOBI-SDWAN with a zero trust security framework is the best way to gain reliability in a way that reduces your risk.

OOBI-WAN hub and spoke

Tool 3. Fully independent automation infrastructure

Another tool that network engineers are becoming familiar with is automation. Network automation codifies repetitive tasks to reduce workloads for configuration management, compliance, and troubleshooting. During a slow economy, being able to scale an IT team’s efforts is especially valuable to business operations and end customers.

There is one major concern, however: having automation that runs loose and begins destroying the network, much like a bull in a China shop. Network engineers typically must learn new automation tools and programming languages, which requires trial and error. And because there is a lack of a best practice reference architecture, teams don’t know any better than to automate directly on the production network. This causes anxiety, as one mistake could bring down the network, cause catastrophic losses, and leave network engineers without an efficient way to recover.

Image: The orange section describes dedicated automation infrastructure used for safely implementing automation.

In recent years, teams have been deploying automation on dedicated infrastructure like their OOB network. This automation infrastructure sits between the production infrastructure and the orchestration infrastructure, and serves as a safe way to build an automation pipeline. Open, Linux-based appliances like the Nodegrid Net SR combine a variety of functions and can host automation tools, like those for observability and analytics, version control, and source of truth. This independent automation infrastructure allows network engineers to ensure the integrity of configuration changes, software updates, and remediation protocols in an out-of-band manner, rather than testing directly on the production network. They can scale their capabilities, and in case of errors, roll back to a golden configuration that keeps services online.

Tool 4. Remote access to local jump box

Network engineers have another tool at their disposal: the jump box (a.k.a. jump server, jump host). A jump box hosts tools for maintaining operations, and these include file servers, image storage, configuration management tools, and troubleshooting commands. The jump box is a valuable asset for normal operations and for restoring services, such as when a device fails and needs its image rebuilt.

The issue with jump boxes is that they are typically a separate device that requires power, cooling, rack space, and maintenance. Some jump boxes also require on-site technicians to physically connect to the equipment needing repair.

Many organizations have adapted by upgrading their OOB infrastructure with appliances that can run full virtual machines (VMs). These can run all the tools mentioned above as well as with Docker containers, while consolidating power consumption, cooling resources, and rack space. The OOB appliance can double as a jump box. Combined with OOBI-LAN and OOBI-WAN, network engineers get remote access to re-image a device, diagnose DNS/routing issues, and perform any other necessary tasks. Key point is that discrete jump boxes – Like the Intel NUC — to be converted to virtual jump boxes running on a secure OOB platform like the Nodegrid Service routers.

Tool 5. Smart hands

A final way that network engineers get help through a slow economy is by outsourcing to so-called ‘smart hands.’ Employing smart hands means involving a third-party expert who can take on some of the IT workload. It’s a viable strategy, especially for teams feeling crushed by corporate belt tightening and the resulting mountain of tasks.

Companies who take this approach must be aware that the skills of smart hands varies greatly, as does the cost. This means it’s essential to strike a balance between which tasks to outsource, and which tasks to keep in house. For example, many organizations use smart hands for simple jobs such as replacing hardware and installing equipment at new sites. For more specialized jobs that require deeper knowledge of the environment, such as fixing a misconfigured IP address or route, teams use in-house personnel. This balance helps organizations get the support they need to keep operations running.

Get a cheat sheet to implement these tools fast

Some companies thrive during economic downturn, because they’ve intelligently placed these tools within their network architecture. Over the past decade, we’ve worked with these companies — including the largest tech giants — to describe in painstaking detail how they set up their infrastructure. We just released all 40+ pages of this validated reference architecture, complete with implementation diagrams and examples.

It’s called the network automation blueprint and it combines all of these tools. Network engineers can confidently answer questions like:

  • How do we meet SLAs with a smaller workforce?
  • How can we keep sites operating without physical access to equipment?
  • How can we perform weekly updates/patching without breaking things?

The blueprint is your cheat sheet to implementing a more resilient network, and fast. Click the button below to download your copy now.

Upgrade Network Infrastructure With Minimal Business Interruption

upgrade network infrastructure

Outdated network infrastructure poses a significant risk to the security and continuity of business operations. According to NTT’s “2020 Global Network Insights Report,” obsolete devices contain nearly twice as many security vulnerabilities as currently supported solutions. Outdated network hardware is also more likely to fail, and the ability to recover from a failure is severely hampered by a lack of vendor support. However, network upgrades can be highly disruptive, so many organizations delay network upgrades to avoid business interruption. They don’t realize that their outdated devices are like ticking time bombs that could bring down their network at any moment. In this post, we’ll provide advice that helps answer the question: How do I upgrade network infrastructure without disrupting business operations?

Why and when to upgrade network infrastructure

Obsolete network infrastructure no longer receives updates and security patches from the vendor. That means any vulnerabilities that exist on the device will remain open, giving cybercriminals time to find and exploit them. In addition, older network solutions often lack the advanced security features like SSO and MFA, which are required for Zero Trust.

Even supported legacy devices suffer from limitations that can prevent a business from achieving its technological goals. For instance, legacy devices may not support automation, making it difficult to achieve NetDevOps transformation. Plus, as enterprise networks grow more distributed, there’s a need for solutions that support SD-WAN and SD-Branch technology.

Sometimes the solutions themselves aren’t terribly outdated, it’s just that business requirements have changed in such a way that the existing infrastructure can’t support. For example, an organization may migrate some applications and systems to the cloud, so they need networking solutions that support hybrid environments. In addition, the mix of old and new devices and cloud and on-premises resources increases management complexity and prevents teams from effectively leveraging network orchestration.

Obsolete devices, outdated security, limited automation support, and changing business requirements are all important reasons to upgrade network infrastructure. However, these upgrades must be approached with a thoughtful strategy to reduce the impact on the performance and availability of business resources.

How to upgrade network infrastructure with minimal business interruption

Vendor agnostic platforms are the key to smooth network infrastructure upgrades. Vendor agnostic (a.k.a. vendor neutral) network management platforms support integrations with all or most viable and established network solutions, including legacy devices.

Vendor-neutral management devices, such as the Nodegrid Serial Console, support both legacy and modern Cisco pinouts. That means Nodegrid provides a single, unified platform from which to manage all the outdated devices you already have as well as any new solutions you add to your infrastructure. This reduces management complexity for network administrators, giving them more time to focus on optimizing performance and planning future network upgrades.

Additionally, a vendor-neutral network orchestration platform can use that management device to extend modern automation and orchestration to legacy hardware. A truly vendor-agnostic platform, such as Nodegrid Manager (for on-premises and private cloud deployments) or ZPE Cloud (for public cloud and hybrid deployments) can run third-party automation playbooks and custom Python scripts. This gives network administrators the unprecedented ability to implement a fully-automated NetOps environment even while still rolling out infrastructure upgrades.

The final piece of the puzzle is vendor-neutral Zero Touch Provisioning (ZTP). ZTP gives you the ability to deploy new devices efficiently and securely in remote data centers, branch offices, and edge compute sites. ZTP devices are provisioned automatically over the network, reducing the need for onsite deployments or pre-staging. A vendor-neutral ZTP solution like Nodegrid can extend ZTP to other vendors’ devices so you can quickly deploy upgraded infrastructure.

Nodegrid delivers vendor-neutral management, orchestration, and ZTP so you can upgrade network infrastructure with minimal business interruption.

Need Help Upgrading Your Network Infrastructure?

Contact ZPE Systems to learn how to upgrade your network infrastructure with Nodegrid.

Contact Us

How To Keep Colocation Data Center Pricing in Check

Rows of data center racks in a colocation facility take up a lot of space, which contributes to colocation data center pricing.

With inflation and supply chain issues causing hardware prices to surge, and a winter recession looming on the horizon, every organization is looking for ways to cut technology costs. Though colocation hosting is often much less expensive than building and maintaining an on-premises data center, factors like physical space usage, power and bandwidth consumption, and remote support can cause your monthly colo bill to spiral out of control. This blog examines some of the most common reasons for colocation data center pricing increases and offers advice on how to keep these costs in check.

Colocation data center pricing considerations

First, here are four common factors that could cause your colocation data center pricing to increase.

1. Physical space

One of the major elements determining colocation pricing is the amount of physical space being rented. Some facilities charge by the rack unit and others by square footage (i.e., how much floor space is taken up by your racks). Costs for colocation space are typically calculated based on your portion of the facility’s operating expenses, which include things like physical security, building maintenance, and energy for cooling.

2. Power consumption

Power usage also heavily affects colocation data center pricing. While some facilities offer flat-rate power pricing, it’s more common to see pricing based on kilowatt usage. The price of data center power usage depends on many factors, such as electricity costs in the region, how energy-efficient the facility is, and how much energy it takes to cool your equipment.

3. Bandwidth consumption

Bandwidth is another usage-based expense that affects data center pricing. Organizations usually purchase bandwidth from the ISP, not directly from the facility, although some data centers do offer colo packages that also include internet access and bandwidth. That means that bandwidth pricing varies significantly from organization to organization.

4. Remote hands

Though colocation data centers handle many aspects of building and facility maintenance, customers are typically responsible for deploying and maintaining their own equipment. Most organizations do so via remote DCIM (data center infrastructure management) solutions, so they do not need to maintain a physical presence in the colocation facility. However, sometimes hardware failures or other issues make remote troubleshooting impossible, so they need to use on-site managed services, sometimes referred to as “remote hands.” Some colocation facilities include an allotted time for remote hands services in their pricing, but more often this is an added fee that’s paid for as needed.

There are many other factors contributing to the cost of colocation data center hosting—such as the location of the facility, the cost of your hardware, and the uptime promised by the provider. However, these four factors are relatively easy for you to change and control without needing to completely overhaul your infrastructure or move to a different facility.

Four ways to keep colocation data center pricing in check

Now, let’s discuss how to decrease your physical footprint, lower your power and bandwidth consumption, and minimize your reliance on managed support services.

Consolidated devices

Replacing bulky, outdated, single-purpose hardware with consolidated, high-density devices is a great way to reduce your colocation data center footprint without sacrificing functionality or performance. For example, the Nodegrid Serial Console Plus (NSCP) provides out-of-band management, routing, and switching for up to 96 devices in a single, 1U rackmount appliance. The NSCP helps reduce the number of serial consoles, KVM switches, or jump boxes in your colocation data center, allowing you to save money or use the extra space for new equipment.

Another option is the Nodegrid Net Services Router (NSR), a modular appliance that can replace up to six other devices in your rack. The NSR provides routing and switching with network failover and out-of-band management, with expansion modules for Docker & Kubernetes container hosting, Guest OS & VNF hosting, and more. The NSR is an ideal solution for small colocation deployments because it can reduce the number of computing and storage devices in your rack. For example, the NSR can reduce your footprint from 4U to 1U, allowing you to cut costs and reduce the complexity of your remote infrastructure.

Remote DCIM power management

As mentioned above, most organizations use remote DCIM solutions to manage colocation infrastructure. Power management is an important aspect of remote DCIM for keeping colocation data center costs in check. Remote DCIM power management allows you to visualize power consumption, both at the individual device level and at a big-picture level. If you can see where you’re using power inefficiently, you can correct the problem (for instance, by replacing a faulty UPS or simply redistributing the load) before costs spiral out of control.

For power cost savings, you should use remote management DCIM that supports automation, such as Nodegrid Manager. This vendor-neutral platform allows seamless integrations with third-party or self-developed automation tools and scripts. That means you can use Nodegrid to automatically monitor for and correct inefficient power load distribution to ensure consistent usage and prevent overage fees. Plus, Nodegrid supports end-to-end automation for all your network and infrastructure management workflows, helping to reduce the overall manual workload for your administrators.

Software-defined networking

Traditionally, administrators set and monitor bandwidth usage by accessing the CLI (command line interface) or GUI (graphical user interface) on individual, hardware-based network devices like switches and routers. For complex and distributed network architectures using many switches in many locations (including remote colocation facilities), manual bandwidth control is so time-consuming and inefficient that organizations end up with a “set it and forget it” approach. That means bandwidth usage is free to fluctuate as much as it wants within certain thresholds, and organizations just eat the overage costs.

Software-defined networking, or SDN, decouples network routing and management workflows from the underlying hardware. This allows organizations to centrally control and automate their entire network architecture, which includes bandwidth management for remote colocation infrastructure. Centralized SDN management gives administrators a single interface from which to control all the networking devices and workflows, so they don’t need to jump from device to device to monitor and manage bandwidth usage.

The application of SDN technology to WAN management is known as SD-WAN, and when that extends into the remote LAN it’s known as SD-Branch. SDN, SD-WAN, and SD-Branch technology use intelligent routing to ensure efficient bandwidth usage and network load balancing. That means you can keep your colocation data center bandwidth costs in check while significantly reducing the amount of work involved for your network administrators.

Out-of-band management

Out-of-band management, or OOBM, separates your management network from your production network, allowing you to remotely manage, troubleshoot, and orchestrate your colocation data center infrastructure on a dedicated connection. This has numerous benefits, including:

  • Resource-intensive network orchestration workflows won’t affect the bandwidth or performance of the production network.
  • Administrators can still access remote infrastructure even if the primary ISP link goes down.
  • Administrators gain the ability to remotely troubleshoot even when a hardware failure or configuration mistake causes a production network outage.

OOBM can help reduce your reliance on colocation data center managed services because your administrators have an alternative path to critical infrastructure even during an outage. A Gen 3 OOB solution like Nodegrid can further reduce your colocation data center pricing in several ways:

  1. OOB management is built into all Nodegrid devices, so you don’t need to purchase any additional hardware (or rent additional rack space) to enable out-of-band management.
  2. Nodegrid OOB integrates with the vendor-agnostic Nodegrid Manager platform, which means you’ll have reliable 24/7 remote access to monitor and orchestrate power load distribution to ensure cost-efficiency.
  3. Nodegrid OOB devices can directly host your software-defined networking, SD-WAN, and SD-Branch solutions so you don’t need to purchase additional hardware. You can also integrate SDN, SD-WAN, and SD-Branch software with the Nodegrid Manager platform for unified control.

The Nodegrid solution from ZPE Systems can help you keep colocation data center pricing in check through consolidated devices, remote DCIM orchestration, software-defined networking support, and Gen 3 out-of-band management.

Want to find out more about reducing colocation data center pricing with Nodegrid?

Contact ZPE Systems today!