Providing Out-of-Band Connectivity to Mission-Critical IT Resources

The WAN Is the Single Point of Failure Nobody Talks About
The WAN is the Single Point of Failure Nobody Talks About

Modern IT infrastructure depends on the wide area network (WAN) to connect everything together. Data centers, branch offices, cloud environments, edge locations, and remote sites all rely on WAN connectivity to exchange data, run applications, and maintain centralized operations.

But the WAN also provides the connectivity required to operate the infrastructure itself (think device troubleshooting, config updates, etc.). This creates a problem: when the WAN fails, organizations lose their production services and their ability to manage the infrastructure responsible for restoring them. It’s like walking a tightrope without having a safety net below.

If your remote management capabilities depend on your production network, the WAN can easily become a single point of failure that’ll leave you battling long outages.

What is the WAN?

Unlike a local area network (LAN), which connects devices within a location, the wide area network is the connectivity layer that links geographically distributed networks and infrastructure across cities, regions, or countries. This includes everything from data centers and corporate HQs, to industrial sites, edge kiosks, and remote infrastructure.

Common WAN link types include MPLS, dedicated circuits, broadband, SD-WAN, and Internet connections.

The WAN is the connective tissue between distributed infrastructure. But its importance goes beyond just moving application traffic. That’s because it touches all three network planes.

The WAN Touches Every Network Plane

Modern networks have three primary planes that each serve a different purpose. We broke these down in a previous article, but here are the basics:

  1. Production/data plane: Carries the traffic (app workloads, voice, video, etc.)
  2. Control plane: Determines how traffic moves (think BGP, OSPF, VXLAN, EVPN)
  3. Management plane: How engineers access, troubleshoot, configure, and monitor infrastructure

The management plane is especially important when it comes to the WAN and the production network. That’s because this plane is vulnerable in traditional network architectures.

How The WAN Becomes a Single Point of Failure

When everything is working fine, management access is like air: you don’t even need to think about it. You can SSH into a router, change a firewall config, or restart a hanging server. It’s very straightforward because of one thing: the WAN is what connects you to the infrastructure.
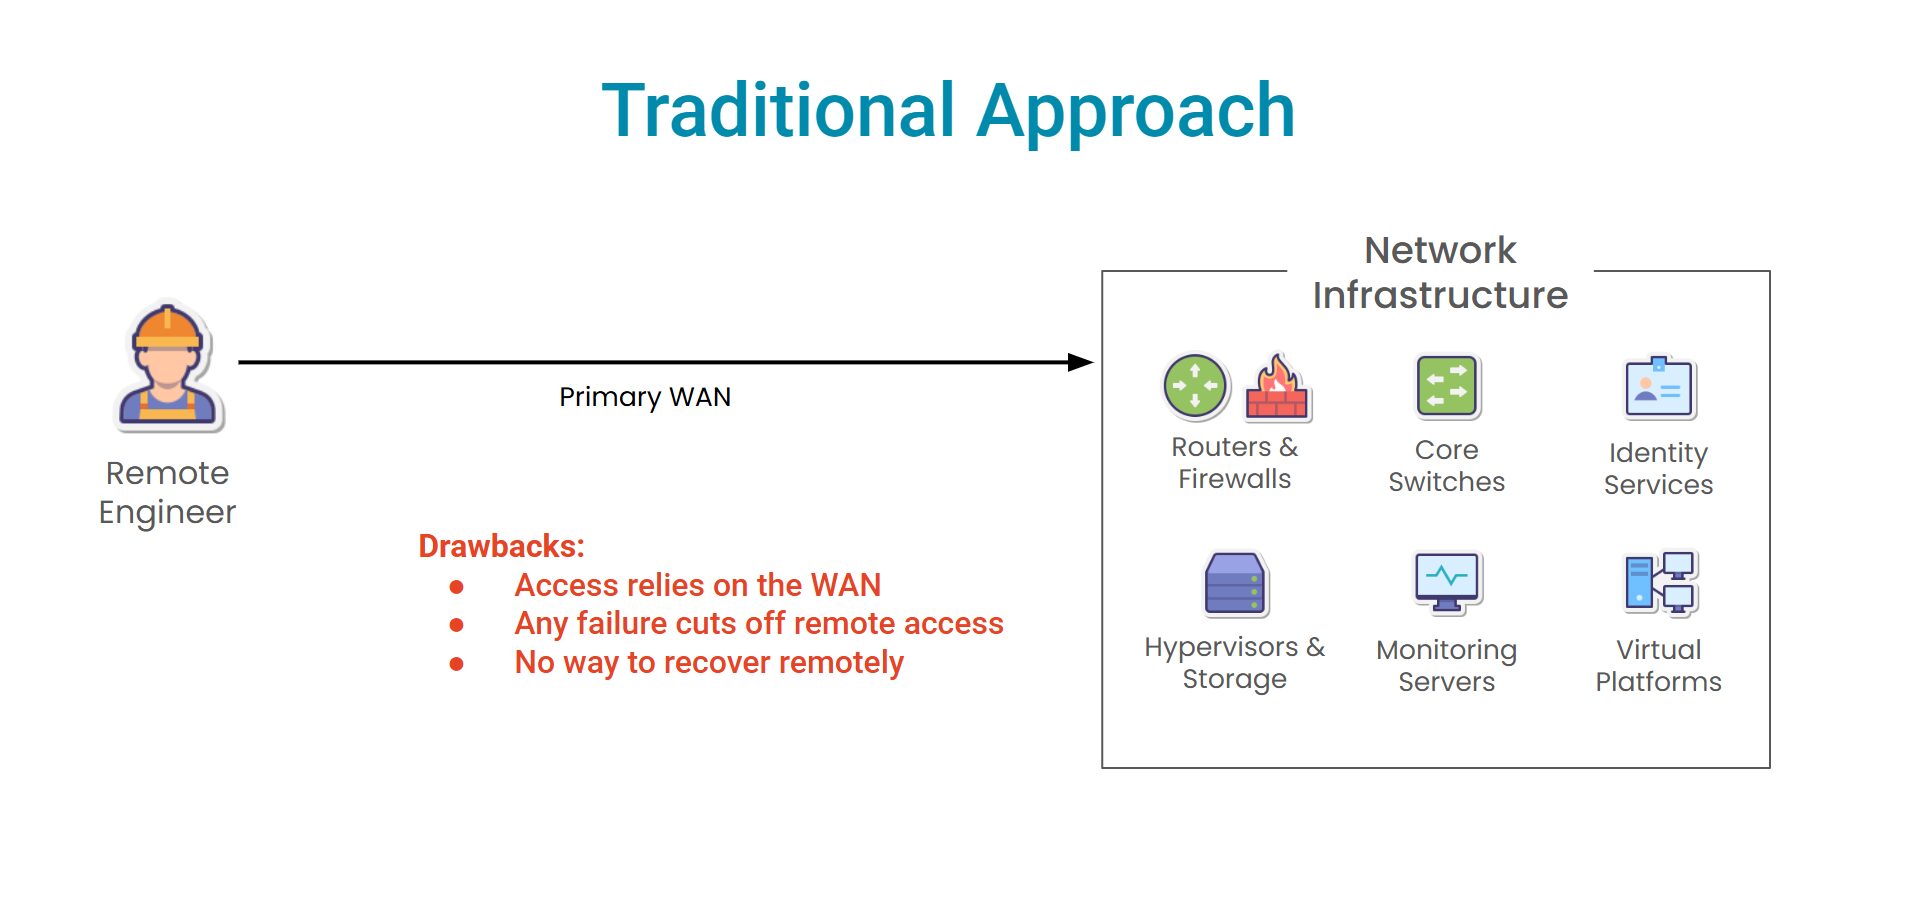
Traditional Approach

But this is a problem. This means that you really don’t have a dedicated management plane, since management access relies on the production network. When the WAN fails, the production network is what you need to fix — but you no longer have access to it.
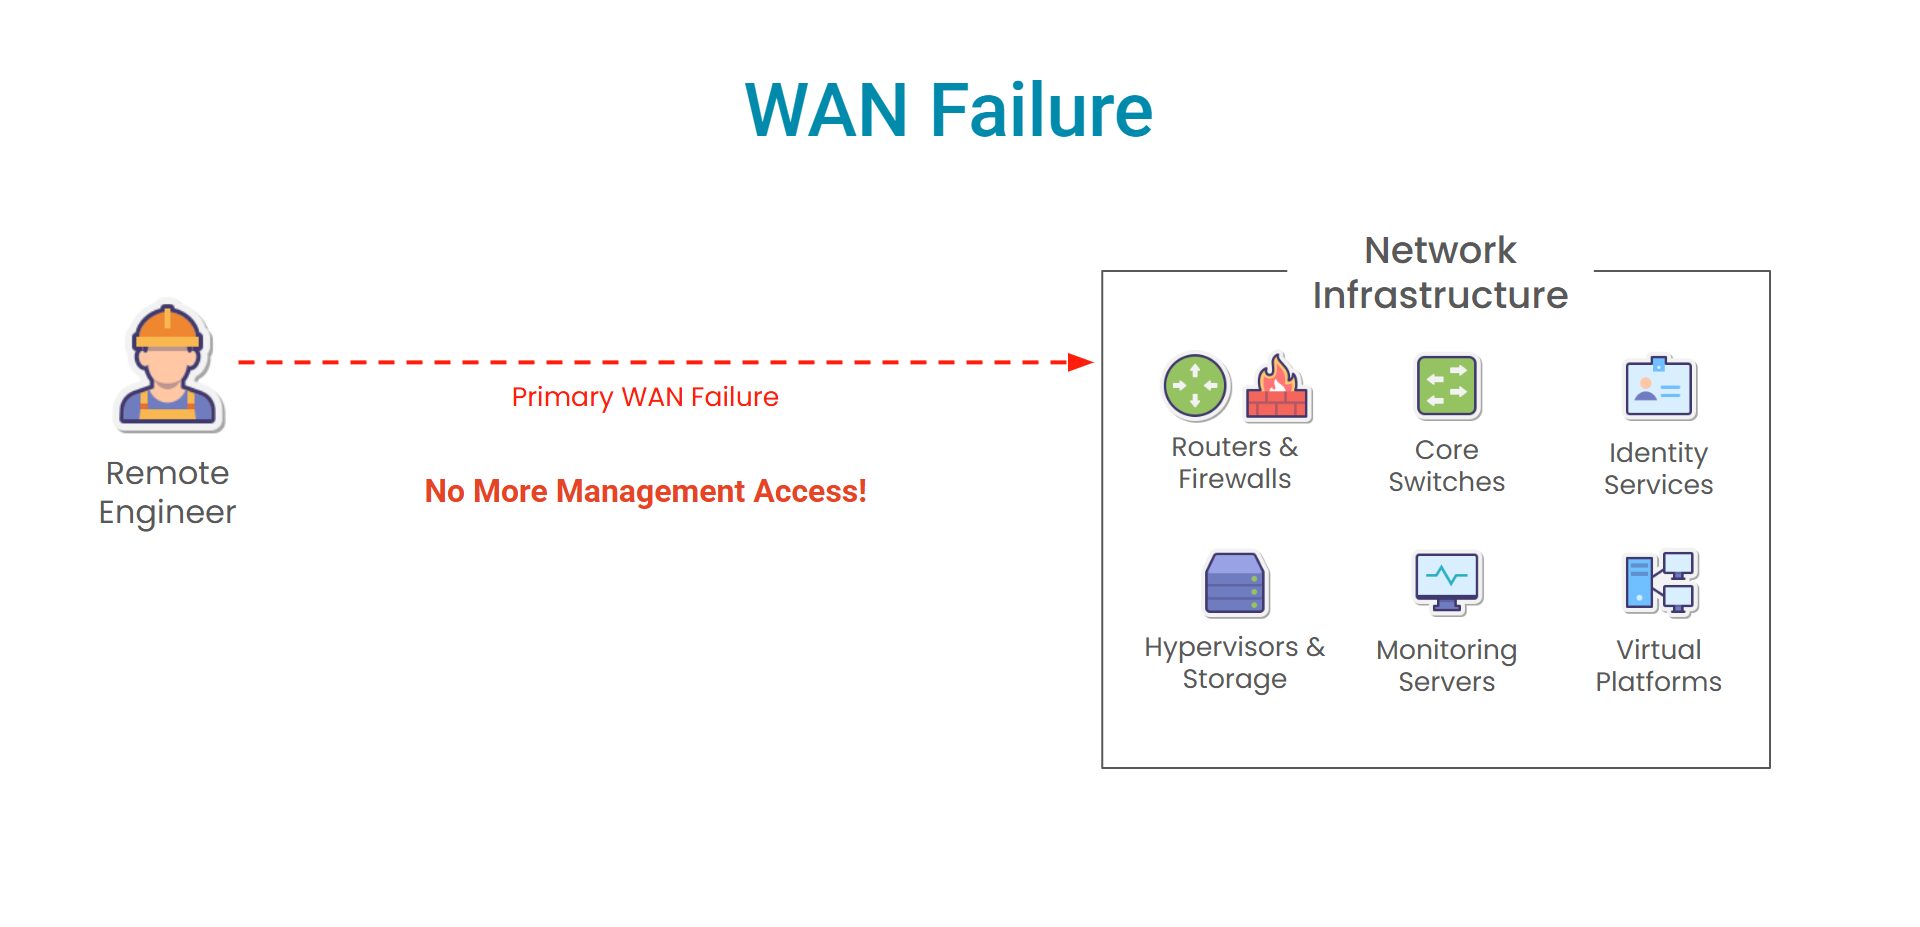
WAN Failure

Here’s what happens when the WAN fails:

  • Data plane disruption: Applications and users lose connectivity.
  • Control plane disruption: Routing and network operations are jeopardized.
  • Management plane disruption: Engineers lose remote access to the devices they need to troubleshoot.

When you can’t reach the equipment you need to fix, a production outage turns into an entirely different issue.


What Actually Goes Wrong When the WAN Fails?


ISP and Carrier Outages

Sometimes, the service provider itself has an outage and there’s not much you can do about it. Recent data from Cisco ThousandEyes shows just how often these events occur. During the week of August 24-30, 2026, ThousandEyes observed 297 global ISP outage events, 203 of which were in the United States alone.

Outages instantly become a remote-management problem in these cases when the WAN is the only path back to a site that’s gone offline. You’re left with two options: Wait for your provider to restore the connection, or send an engineer to the affected site(s). Both can easily take hours, sometimes days, before normal operations are restored.


Fiber Cuts and Physical Disruptions

What happens when a construction crew accidentally sends a backhoe bucket or an auger straight through an underground fiber run? If you rely on the WAN for management access, physical disruptions like these could have you waiting for days before they’re fixed.

Cloudflare tracked more than 180 Internet disruptions during 2025, including those caused by cable cuts, power outages, and extreme weather. Some were brief, but others lasted for days. These failures are especially difficult (and frustrating) because you could be hundreds of miles away, and your devices could be perfectly healthy, but the path you use to reach them is physically broken.


Routing and Configuration Errors

Increasing network complexity directly contributes to configuration and change-management problems. Uptime Institute’s 2025 analysis found that 23% of impactful outages were attributed to IT and networking issues, like routing errors, incorrect configs, and firmware problems.

The network equipment is exactly what you need to fix, but a configuration error has eliminated the path you need to access it.


Third-Party Network Failures

There’s an entire ecosystem of ISPs, carriers, cloud providers, colocations, and other third party networks. If any part of this ecosystem fails, it can affect your ability to reach remote infrastructure.

Uptime Institute reports that 39% of those surveyed experienced an outage caused by a third-party networking issue. Essentially, you can lose access to your own infrastructure because of a failure you don’t control.

That’s the common thread with all these outage scenarios. When a WAN failure takes down your production network, your management access goes down with it.


How To Stay Operational During WAN Failures


Build an Isolated Management Infrastructure

Adding redundancy seems like the logical solution. But having true operational resilience means going beyond having a second WAN circuit. You need to be able to confidently answer this question:

Can you still reach the infrastructure if the primary network fails?

If the answer is no, you still have a shared-fate problem: your management access depends on the same infrastructure you’re trying to recover.

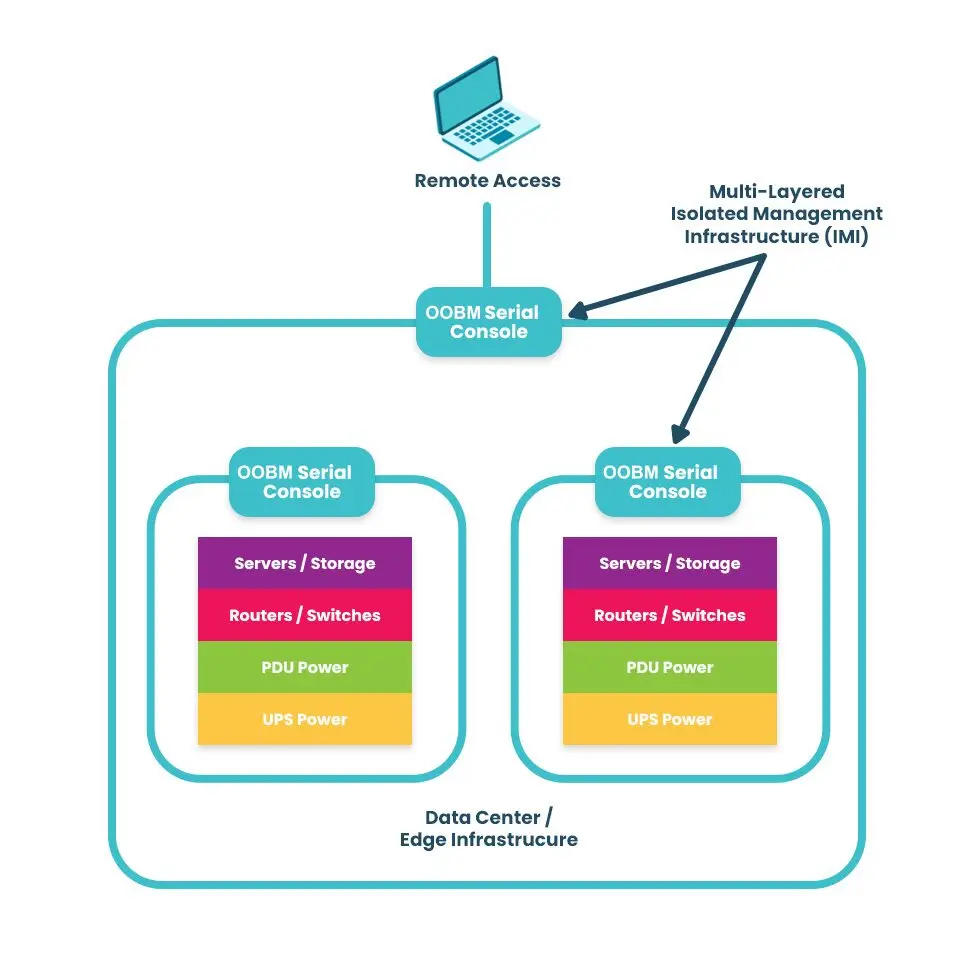
An Isolated Management Infrastructure (IMI) solves this by creating a dedicated management layer that is completely independent of the production network. IMI does not rely on the WAN, routers, switches, or other infrastructure that carry production traffic. Instead, IMI provides a separate path that’s purpose-built for maintaining and recovering production infrastructure. Think of it as a safety net that keeps business from crashing down if there’s a primary network outage.
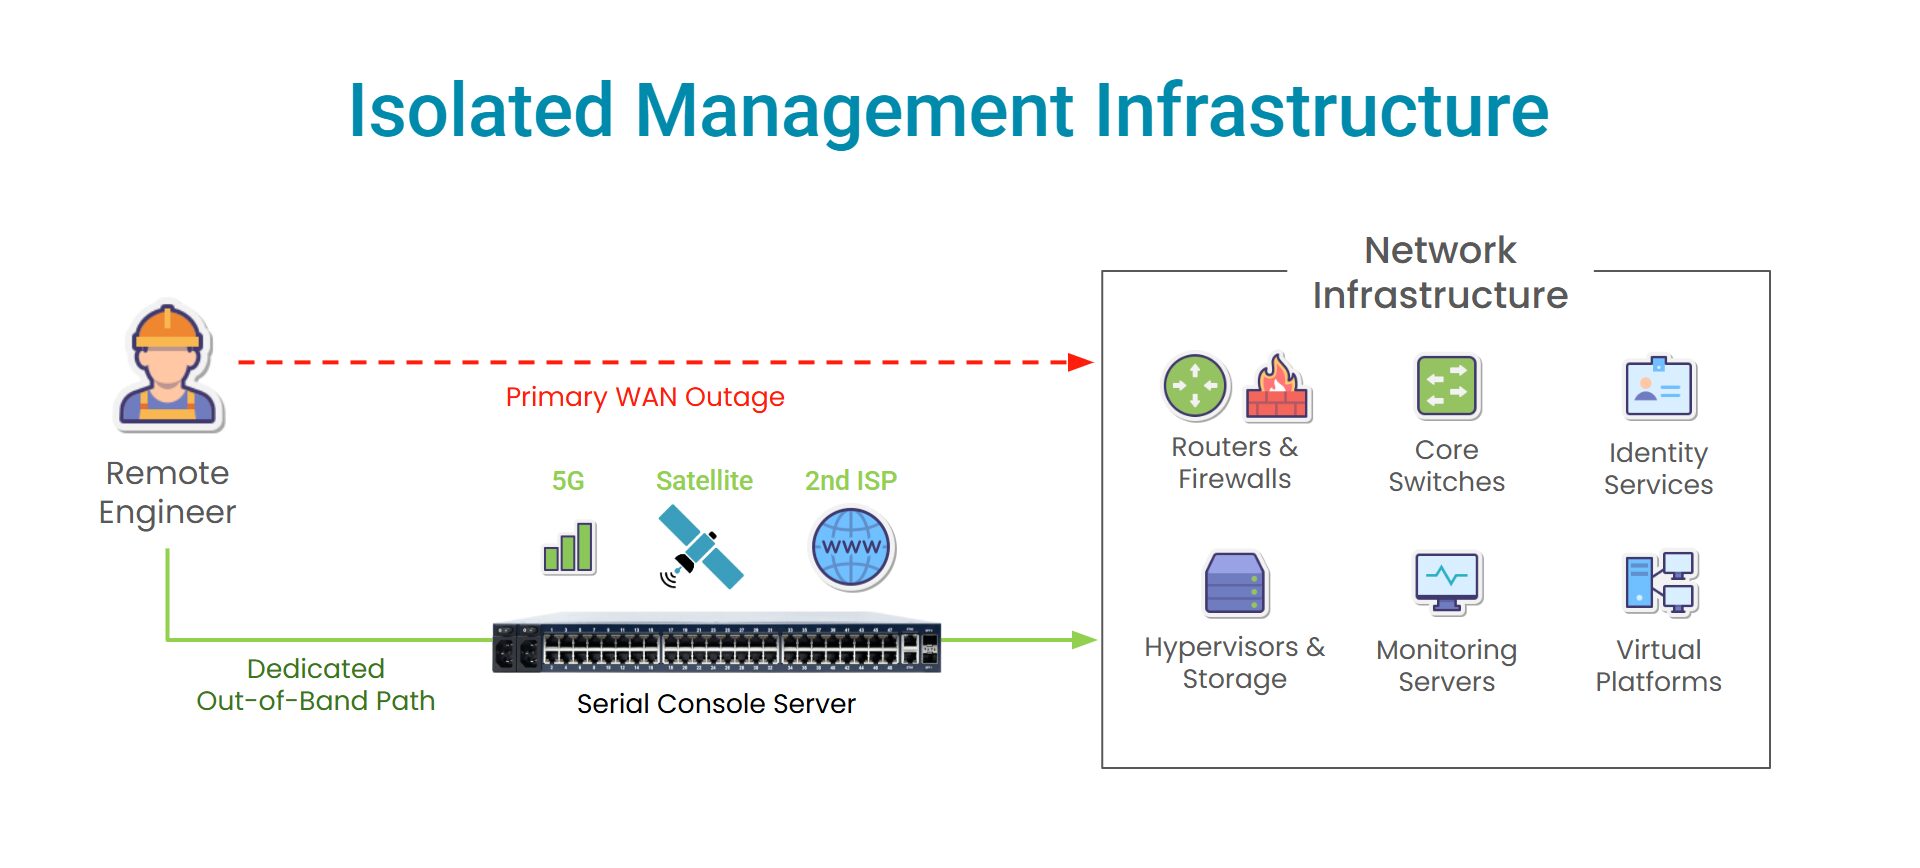
Isolated Management Infrastructure

What Does IMI Look Like?

Isolated Management Infrastructure is made up of several components:

  1. A separate management network that is logically and physically isolated from production infrastructure. This is created by deploying out-of-band serial consoles.
  2. Independent connectivity using 5G, satellite, and/or other link types that don’t rely on terrestrial infrastructure. These provide access to your OOB serial consoles, and thus your production equipment.
  3. Direct access to the variety of critical IT, including via serial, Ethernet, USB, KVM, and power interfaces. This gives you management access to your entire equipment stack.
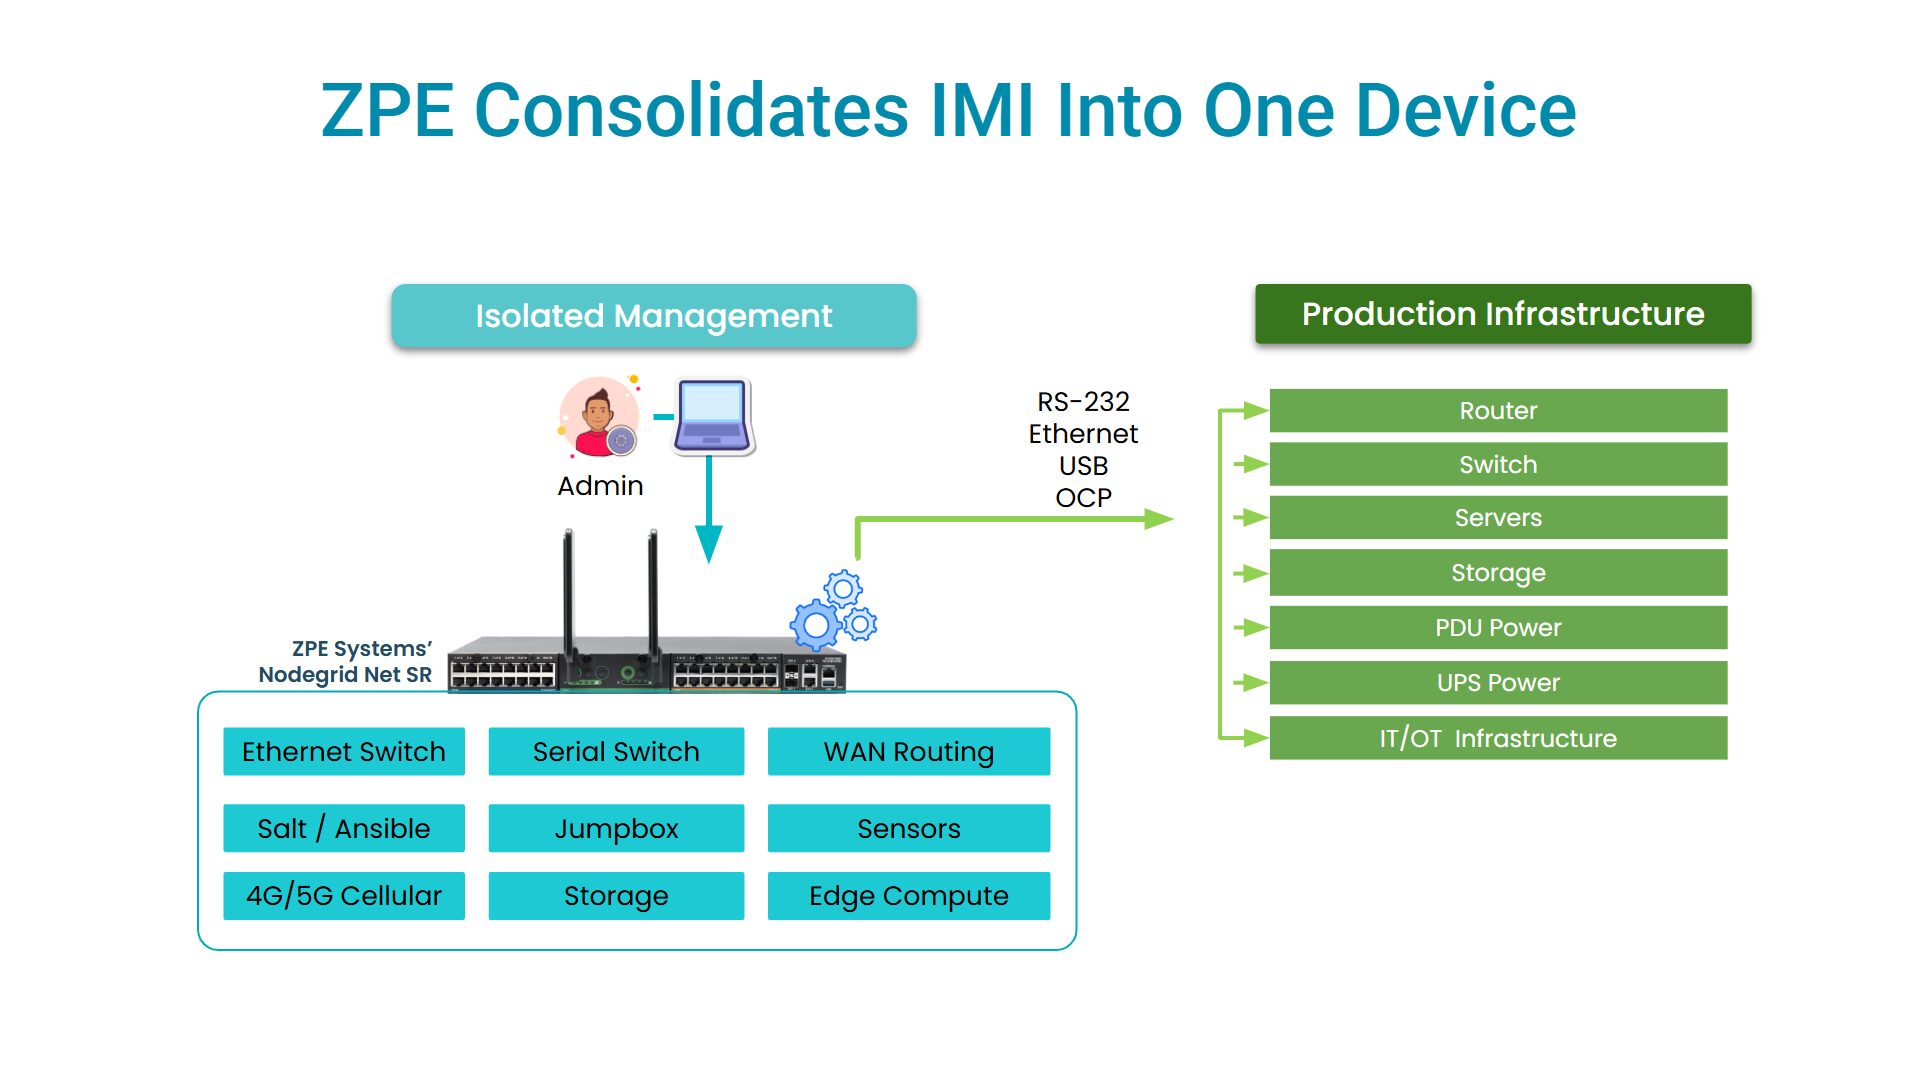
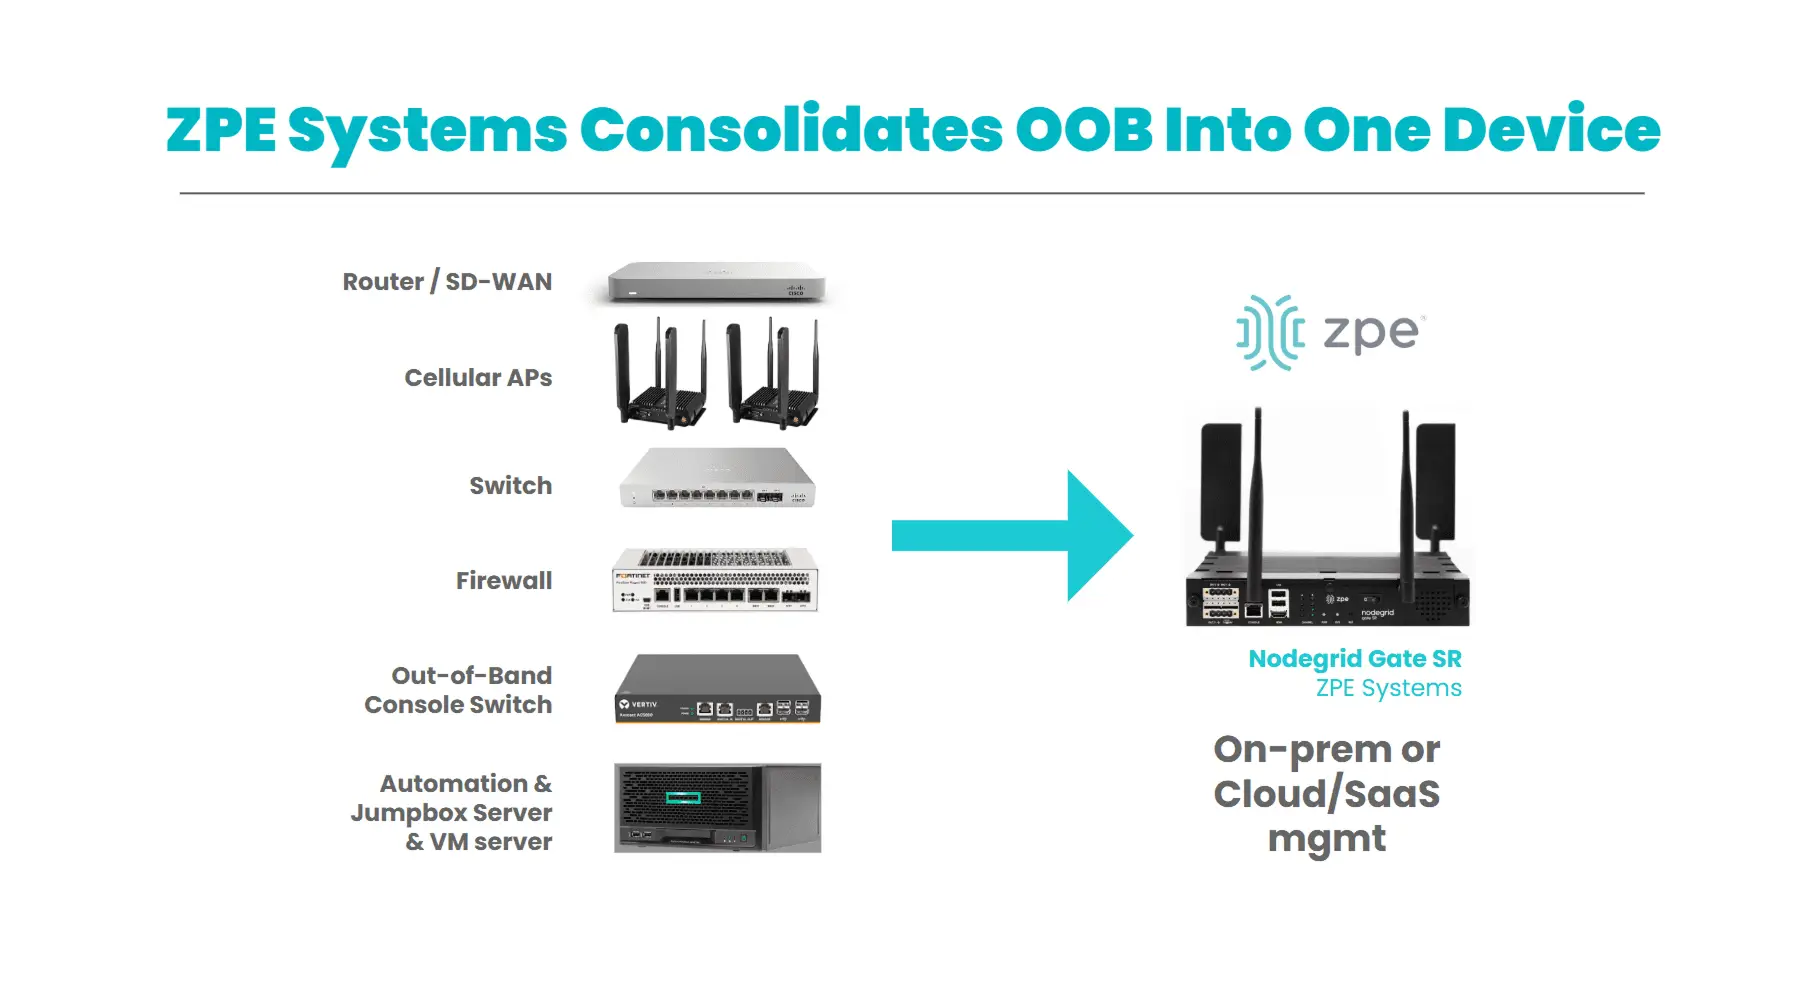
ZPE Consolidates IMI Into One Device

This completely changes the recovery process. There’s no more waiting for the WAN to come back or dispatching an engineer to the site. Engineers can use the IMI to pinpoint affected equipment, make config changes, and/or completely rebuild systems.

Take Mercado Libre for example. This Latin America e-commerce giant experienced an unexpected outage at one of their distribution hubs. But because they had installed ZPE Systems’ Nodegrid as their IMI, they were able to keep operating as if nothing happened. “The solution paid for itself with just this one outage,” they said. Read the full Mercado Libre case study here.

Don’t Let WAN Failures Take Down Your Network

Download The Network Resilience Blueprint

The WAN will always be a critical component, and you can’t eliminate every carrier outage, fiber cut, or config error. But you can eliminate your management network’s dependency on the WAN.

The Network Resilience Blueprint is a practical framework for putting IMI into practice. It walks you through five architectural steps to build an infrastructure that’s easy to manage, fast to recover, and most importantly, resilient against WAN failures. Download the blueprint now and keep your critical IT reachable even when the network is down.
The Network Resilience Blueprint

Get in Touch For a Demo of AI Resilience

Our engineers will walk you through the best practices and show you Nodegrid’s capabilities first-hand. See how easy it is to point, click, and manage your distributed AI fleet. Fill out the form to get started.

 

Network Resilience for AI & Edge Workloads

Network Resilience for AI & Edge Workloads

Designing AI infrastructure that engineers can recover when things break

AI infrastructure is expanding fast across enterprise networks. GPU clusters are powering model training, while edge inference systems process data in real time across industries like finance, manufacturing, retail, and telecommunications. Most AI environments are working well from the perspective of the computing infrastructure.

But with many deployments scaling beyond centralized data centers and into distributed edge environments, network engineers are facing a familiar problem: How do you maintain control when failures happen?

This is an important question to address because AI environments amplify the operational impact of failures. Large GPU clusters, distributed edge locations, and latency-sensitive workloads all depend on reliable network connectivity. When something breaks, recovery becomes just as important as redundancy.


AI Infrastructure Places Different Demands on the Network

Traditional enterprise applications are generally tolerant of brief interruptions. A user might reconnect to an application or retry a transaction without significant impact. But AI workloads are much less forgiving.

Large language model (LLM) training, distributed inference pipelines, and real-time analytics depend on continuous communication between compute, storage, and networking resources. Interruptions have a ripple effect because modern AI environments rely on:

  • GPU clusters connected by high-bandwidth Ethernet or InfiniBand fabrics
  • East-west traffic that exceeds traditional north-south application flows
  • Distributed storage systems supplying training data
  • Kubernetes orchestration platforms scheduling GPU workloads
  • Edge inference nodes continuously exchanging telemetry with centralized systems

For example, a failed top-of-rack switch, an incorrect routing policy, or a misconfigured spine switch can isolate entire GPU pools from storage or orchestration services. Even if the compute nodes remain operational, workloads stall while engineers work to restore connectivity.

For network engineers, resilience is now a job of ensuring the infrastructure remains observable, accessible, and recoverable especially when failures occur.


Understanding the Different Network Planes

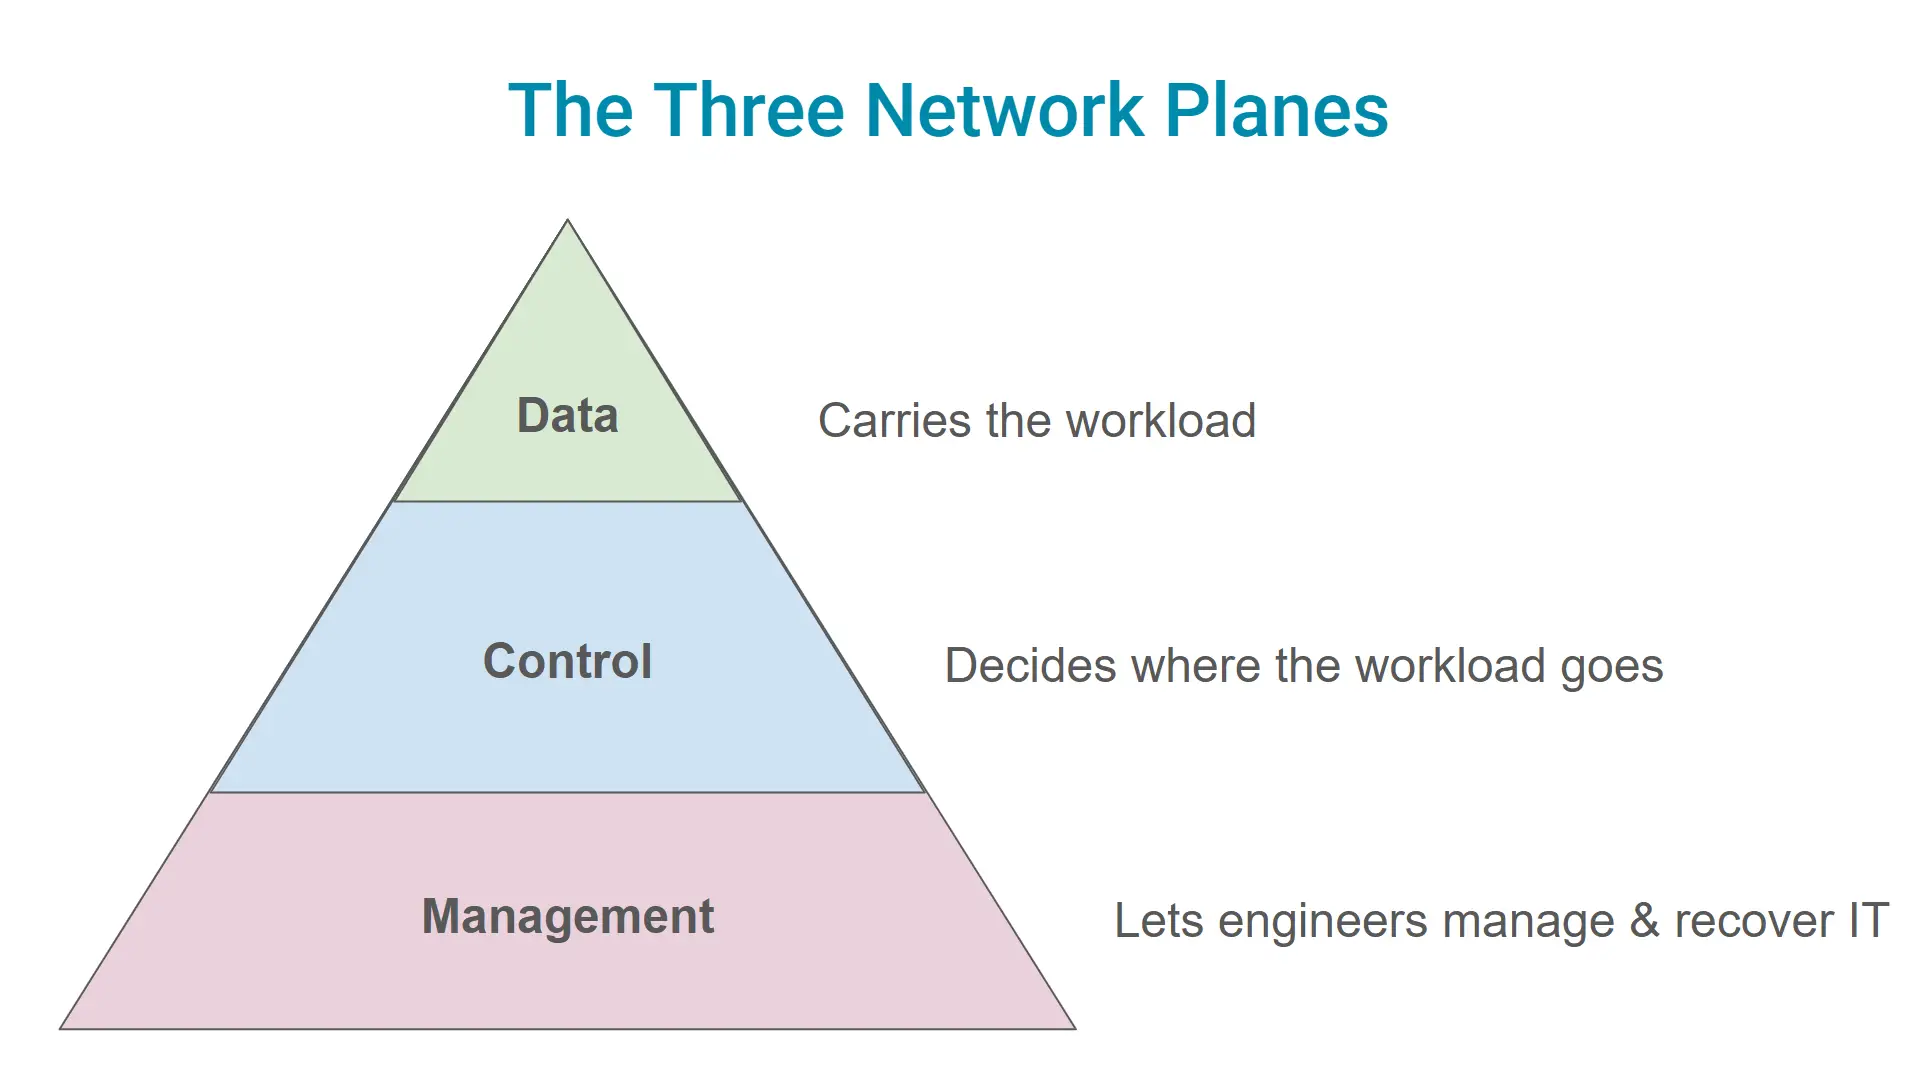
Before we go further, it helps to distinguish between three separate but closely related parts of the network, which will help understand where failures happen and their effects:

Production (or data) plane: carries application traffic, including AI training data, inference requests, storage traffic, and user communications. For example, when you submit a prompt to an AI application, the production plane is what carries your prompt, the model’s responses, and supporting data.

Control plane: runs the protocols that determine how traffic moves through the network, including BGP, OSPF, EVPN, VXLAN, spanning tree, and other routing and switching functions. Think of this like the network’s navigation system. The control plane decides the best path for traffic to take, but it doesn’t carry the traffic itself.

Management plane: provides the interfaces engineers use to monitor, configure, and recover infrastructure. This includes SSH, HTTPS, APIs, SNMP, serial console access, intelligent PDUs, and out-of-band management. This is the path that engineers use to log into devices, push config changes, and recover systems during an outage.

Understanding the Different Network Planes

Image: The three network planes: The data plane, which carries the workload; the control plane, which decides where the workload goes; and the management plane, which gives engineers access to manage and recover equipment.


Where AI Infrastructure Failures Actually Happen

Control Plane Failures That Disrupt The Management Plane

Not every outage begins with a hardware failure. In fact, a lot of incidents originate in the control plane with:

  • BGP policy mistakes
  • OSPF adjacency failures
  • EVPN/VXLAN configuration errors
  • VLAN or VRF misconfigurations
  • ACL changes that unintentionally block management traffic

These issues may leave routers, switches, and servers fully operational but unreachable over the production network. If management traffic shares the same infrastructure as application traffic, engineers lose SSH, API, and monitoring access right when they need it most.

This is why it’s important to completely separate the management network from the production network (more on this below).


Automation Mistakes That Create a Big Blast Radius

Infrastructure-as-Code (IaC) and network automation are great for improving consistency, but they also increase the blast radius of configuration errors. A single Ansible playbook, Terraform deployment, or automation workflow can unintentionally affect hundreds of devices simultaneously.

When that happens, engineers need a recovery path that does not depend on the production network remaining operational. This is one of the reasons out-of-band management continues to be standard practice in hyperscale and service provider environments.


GPU Clusters That Are Left Idle

AI infrastructure is built around the most expensive compute resources in the data center. Experts project global AI investments to exceed $1 trillion in 2026, and it’s easy to see why. A single GPU server can cost hundreds of thousands of dollars, and production AI clusters often consist of dozens or hundreds of these systems working together.

Model training requires GPUs to operate as a coordinated cluster. If a network issue isolates part of the cluster or prevents nodes from communicating with storage or orchestration platforms, the training job stalls or fails altogether. Even though the GPUs are powered on, they’re no longer doing productive work.

In inference environments, the impact is different but just as significant. An unreachable edge AI node that stops processing camera feeds, sensor data, or real-time transactions reduces application performance or forces workloads to fail over to other locations.

Idle hardware is just the beginning of the costs. Organizations also lose productive compute time, delay model development, miss service-level objectives (SLOs), and increase operational overhead while engineers work to restore connectivity.

No infrastructure is immune to failures, so eliminating every outage isn’t realistic. The goal instead is to minimize Mean Time to Recovery (MTTR) by giving engineers immediate access to diagnose and recover systems, so expensive GPU resources spend more time running workloads and less time waiting for someone to restore the network.


Addressing a Common Question About AI

One common response to conversations about AI resilience is: “Our AI infrastructure is already working fine. Why do we need to change anything?”

It’s a valid question. After all, if it ain’t broke…

But this underscores something we’ve been talking about for years. It’s not about redesigning networks that already work just fine. It’s about building the ultimate safety net that’ll save you from the growing operational risks of scaling your infrastructure.

Managing a GPU cluster inside a data center is completely different than managing a fleet of AI systems spread across hundreds of remote sites. Engineers need to retain visibility and control when the inevitable routing mistake, WAN outage, or misconfig happens. Resilience needs to be built into the architecture.


Resilience Should Be Built Into AI Architecture

The networking industry has spent decades designing highly available production networks through redundant links, resilient routing protocols, and fault-tolerant hardware. AI infrastructure deserves the same level of attention, but redundancy alone isn’t enough.

Traditional high-availability designs focus on strengthening the production and control planes. Equally important is strengthening the management plane and being able to confidently answer this question: “When an engineer loses connectivity to a remote GPU cluster at 2am, what path do they have to recover it?”

If the answer depends on the production network coming back first, the architecture still has a single point of failure. This is why it’s key to fully separate management from production. This isolation lets engineers diagnose, control, and recover AI infrastructure exactly when it matters most.

So, “Why do we need to change anything?” It’s not really about changing the architecture. It’s more about adding an alternate management path that lets you recover systems even if the production network is down.

That’s where out-of-band and IMI come in.


IMI: The Evolution of Out-of-Band

Out-of-band management is usually thought of as a console server attached to a few routers, meant to give engineers backup access in case the main network goes down. But modern out-of-band — what’s called Isolated Management Infrastructure (IMI) — has much more operational capability, including the ability to fully rebuild systems.

An IMI includes:

  • Serial console access to routers, switches, firewalls, storage arrays, and GPU servers
  • Independent Ethernet management interfaces
  • 5G/LTE or satellite connectivity for WAN independence
  • Remote power management through intelligent PDUs
  • Secure jump-host capabilities with centralized authentication
  • Automated recovery workflows triggered by monitoring platforms
IMI The Evolution of Out-of-Band

Image: Isolated Management Infrastructure provides the operational capabilities to fully rebuild and restore networking systems, even if the network is offline.

This creates a management plane that remains operational regardless of whether the production network is available. So instead of having to rebuild connectivity before troubleshooting can begin, engineers can connect via 5G/LTE or satellite to immediately investigate logs, inspect device health, restore configurations, or power-cycle failed systems.


ZPE is Essential to Resilient Architecture

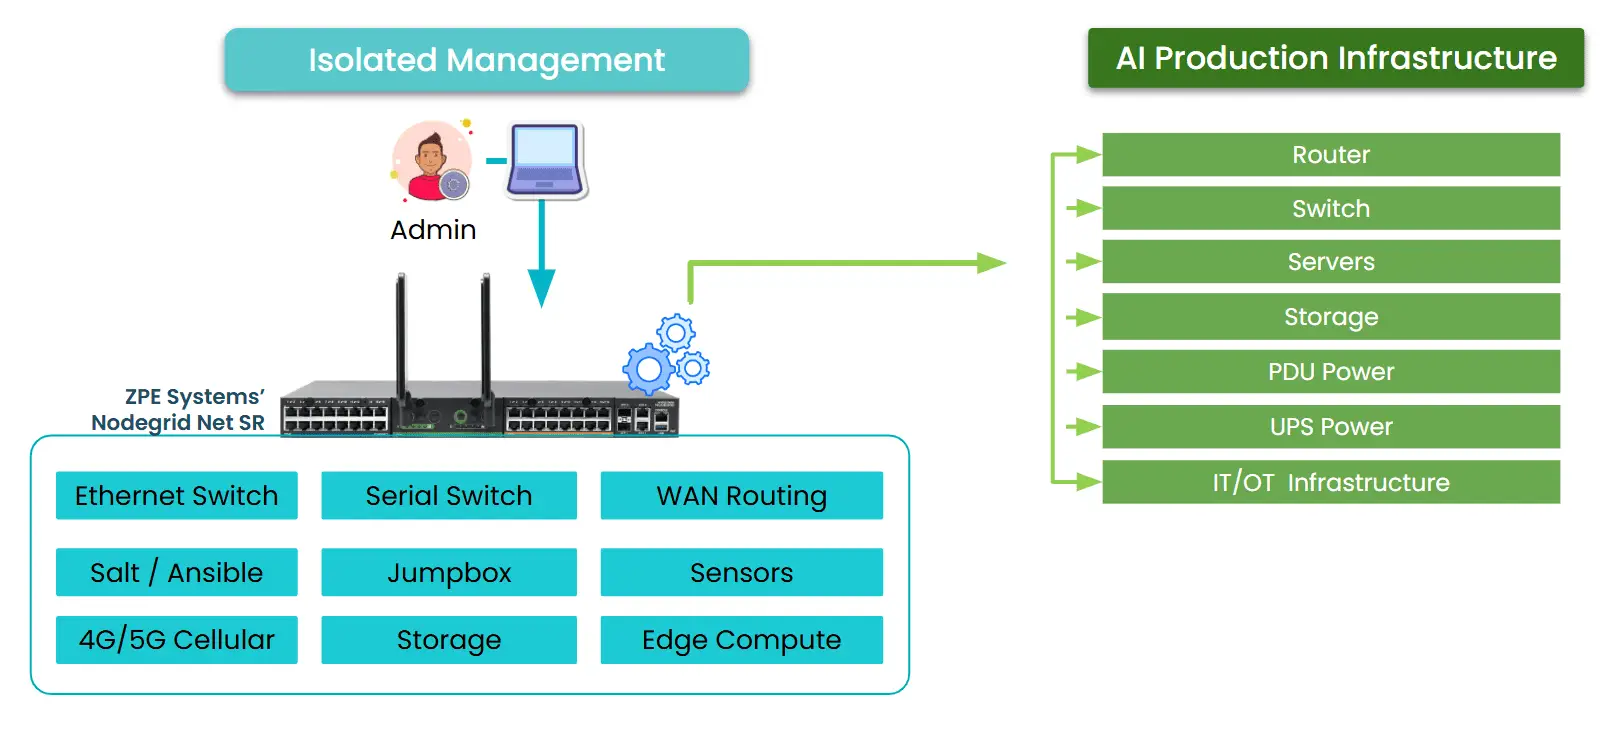
ZPE’s solutions are an essential component of resilient network architecture. They’re used by many organizations as an independent operational layer alongside the production network. At each AI or edge site, one ZPE Nodegrid device can aggregate management access for routers, spine and leaf switches, firewalls, GPU servers, storage, PDUs, and hypervisor/compute platforms.

Isolated Management

Image: ZPE’s solutions consolidate multiple functions into a single device and aggregate management access to a variety of AI production infrastructure, with the ability to connect via RS-232, Ethernet, USB, and OCP interfaces.

This IMI gives engineers secure access during routing failures, WAN outages, failed software upgrades, config errors, and many other outage scenarios. Nodegrid devices can also host virtualized functions (like routing and firewalls) to help further consolidate the overall tech stack. This gives organizations a consistent operational model no matter how many AI sites they have or where their workloads are deployed.

Download the Blueprint for AI Resilience

Want to see how these principles fit together? Download the Network Resilience Blueprint to learn a practical framework for designing an infrastructure that’s easy to manage, quick to recover, and built for today’s distributed AI and edge environments.

The Network Resilience Blueprint

Get in Touch For a Demo of AI Resilience

Our engineers will walk you through the best practices and show you Nodegrid’s capabilities first-hand. See how easy it is to point, click, and manage your distributed AI fleet. Fill out the form to get started.
 

Out-of-Band Deployment Best Practices

OOB Deployment Best Practices

Modern networks are sprawling. Think about all the data centers, branch offices, edge locations, retail sites, and remote industrial environments that organizations need operating 24/7. Supporting these with apps and services requires vast networking infrastructure. But here’s the thing: the network is more critical now than it’s ever been, meaning downtime can be a major problem.

A single WAN outage, configuration error, device failure, or ISP issue can leave IT teams without access to critical infrastructure. Their access path and tools become useless. What should be a quick remote fix turns into hours of travel and on-site troubleshooting.

Why does this happen? Because many organizations still rely on traditional management – where remote access depends on the production network – and this architecture was never designed for today’s distributed environments. It leaves engineers cut off from the infrastructure they need at the exact time they need it most.

This is where out-of-band (OOB) management changes everything. OOB is an independent management layer separate from the production network. Engineers use this for secure access to infrastructure, even if there’s a device failure, routing error, ISP outage, or other downtime scenario. Out-of-band access is the foundation for resilient network operations because it helps organizations maintain visibility, accelerate recovery, and reduce downtime across distributed environments.


Best Practices for Deploying Out-of-Band Infrastructure

Deploying a proper out-of-band infrastructure requires more than just adding remote console access. The most effective deployments design for resilience, scalability, and operational simplicity from the beginning. Here are some best practices to follow when building your OOB network.


1. Separate the Management Network from the Production Network

We can’t say it enough: production networks are not management networks.

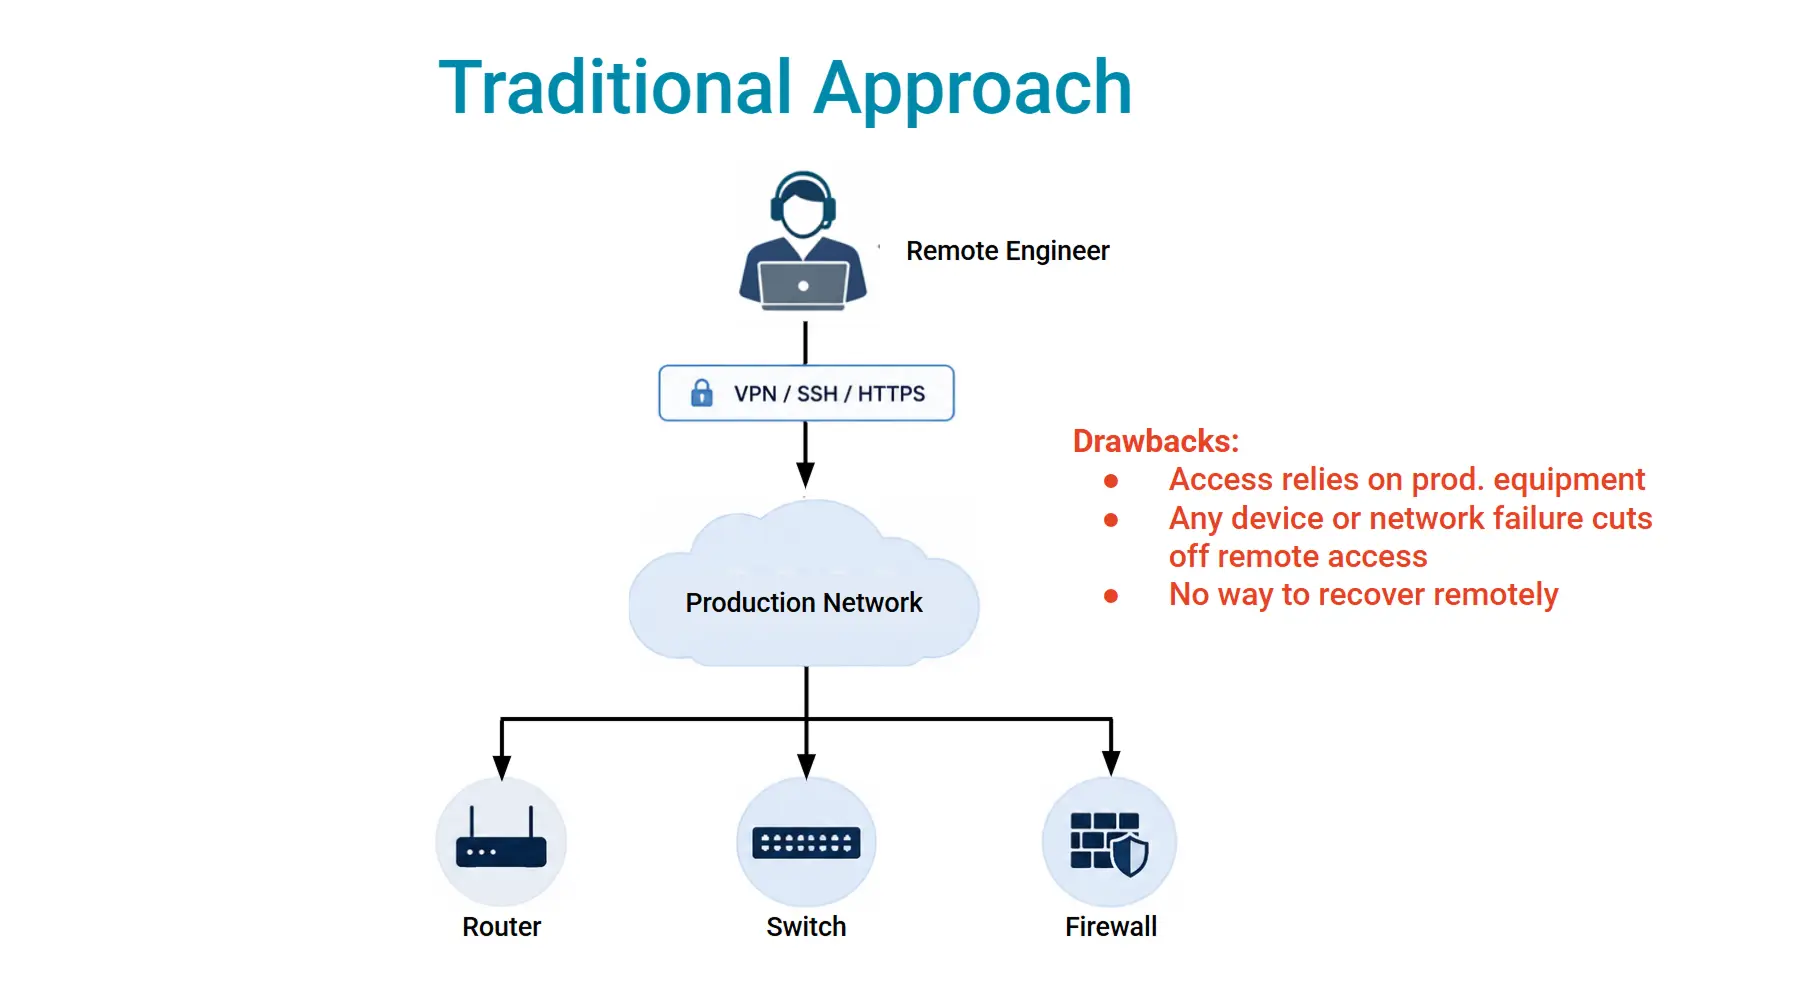
In traditional environments, remote management depends entirely on the production network itself. Engineers connect to routers, switches, firewalls, and servers using protocols like SSH or HTTPS. But they do this over the same WAN links and routing infrastructure they are responsible for maintaining. Which means that when the production network fails (for any number of reasons), those remote management paths also disappear with it. Visibility and control vanish when they’re needed most.


Traditional Approach – Diagram

Image: Traditional remote management architectures rely on the production infrastructure, which is the exact infrastructure that needs to be managed.

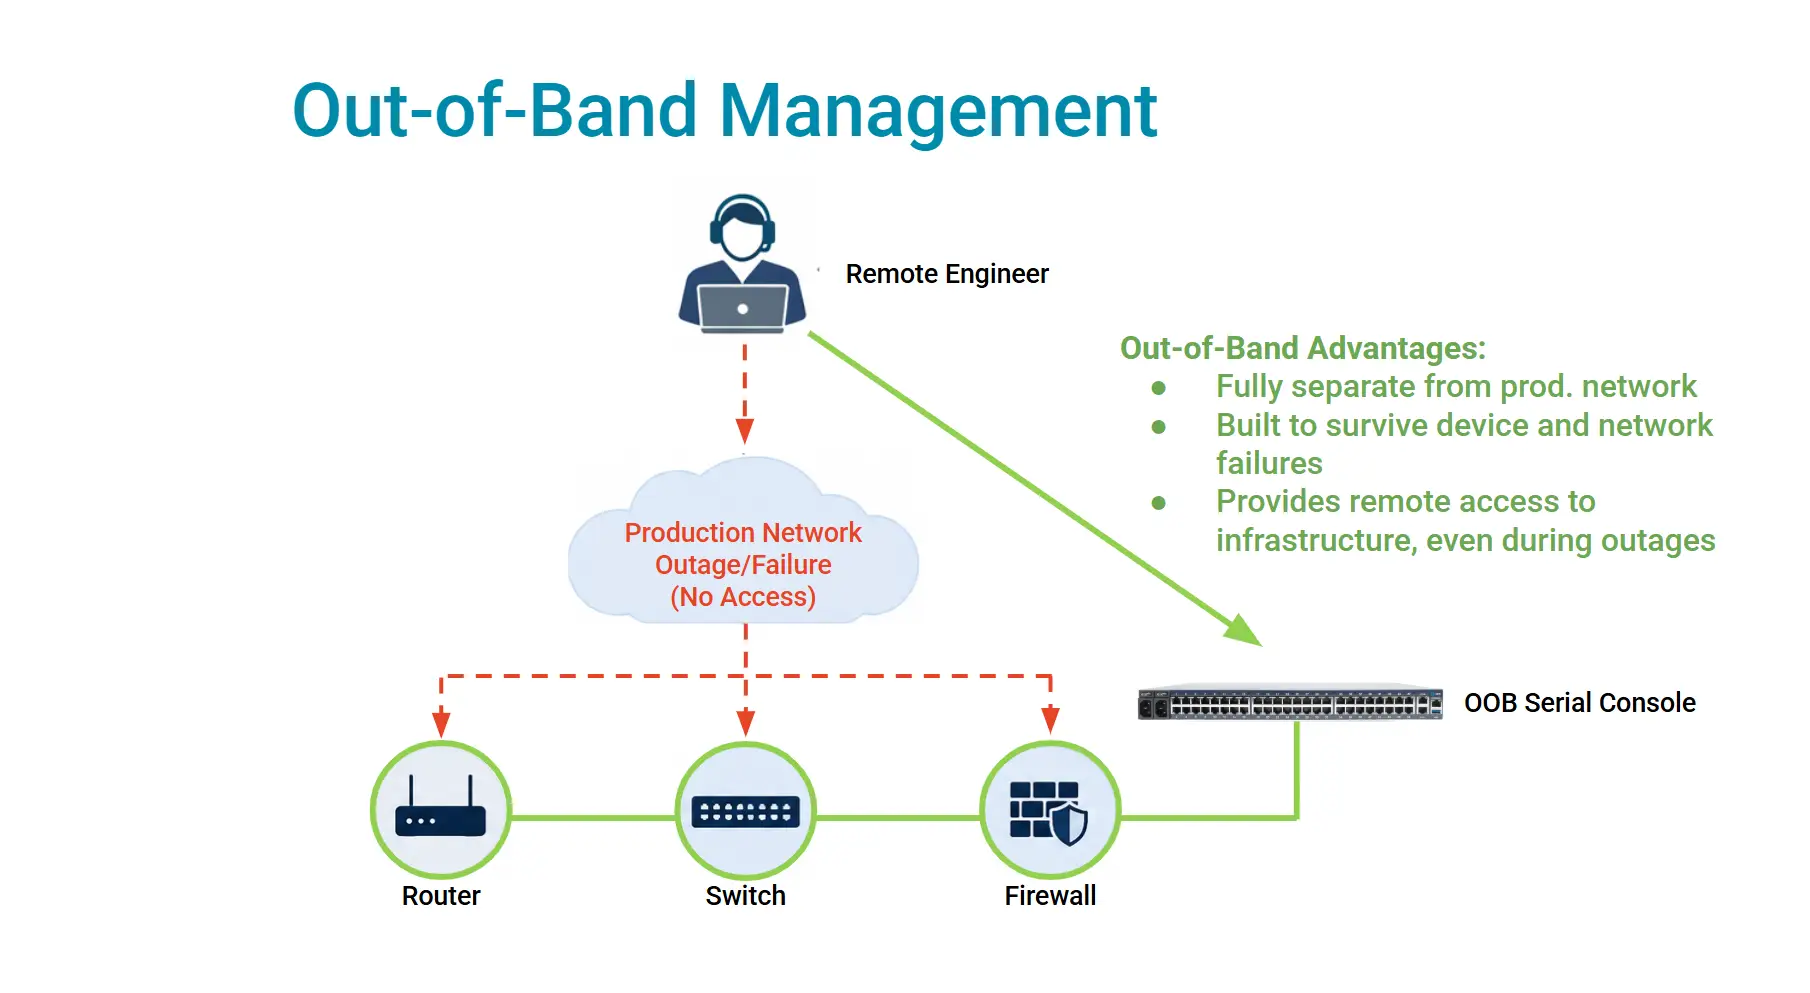
Out-of-band management improves resilience by creating a management layer that remains accessible when the primary network experiences problems. When building your out-of-band network, follow the best practice of logically and physically separating it from production. This is what’s known as Isolated Management Infrastructure (IMI), and it’s what modern OOB designs incorporate to ensure admin access in worst-case scenarios.

Out-of-Band Management – Diagram

Image: Out-of-band management is built to withstand production network outages, and provides full remote access to infrastructure, even if the production network is completely offline.


2. Deploy More Than One Connectivity Path At Every Site

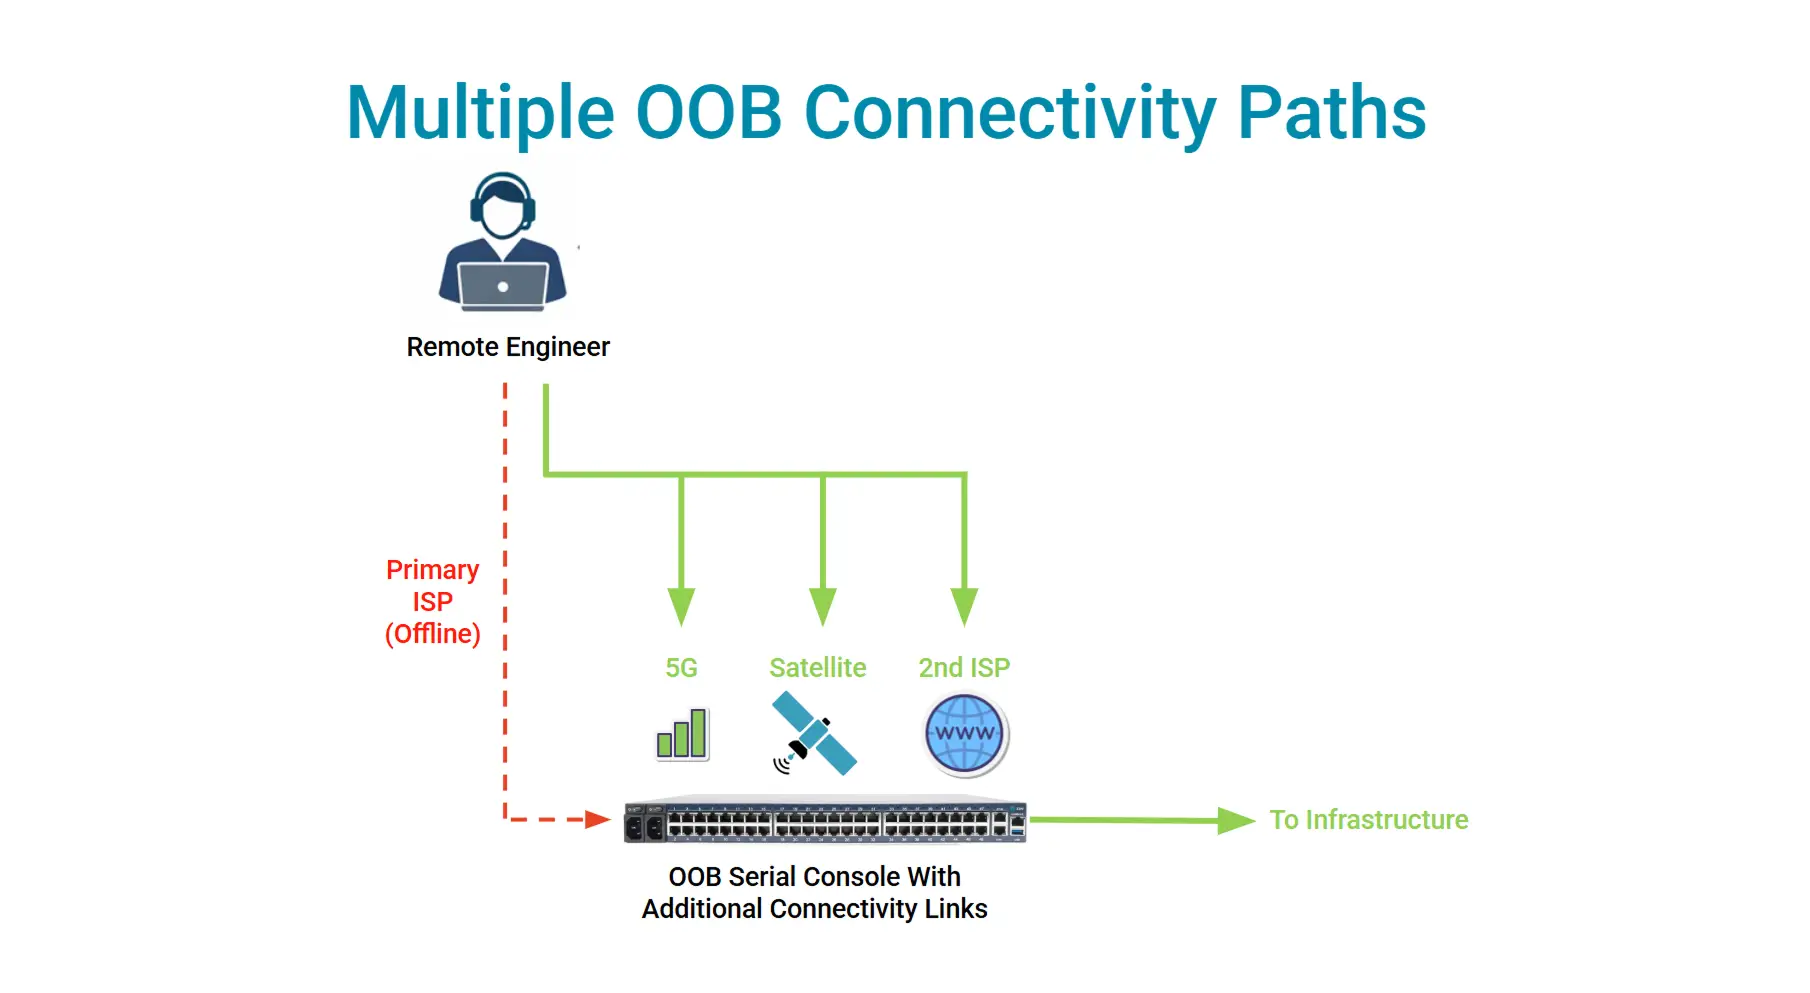
Having an out-of-band network is a great start. But, having only one connection can leave engineers hamstrung. If the OOB path suffers a WAN or ISP failure, admin access is cut off and sites become unreachable. Downtime lasts longer because restoring service requires a truck roll and on-site troubleshooting.

Multiple OOB Connectivity Paths – Diagram

Image: Modern out-of-band management networks design for connectivity failures, and employ one, two, or even three backup link types (like 5G, satellite, secondary ISP, etc.).

Modern OOB networks are isolated, and just as importantly, they employ more than one type of connection. When building your out-of-band network, the goal is to ensure you maintain management access no matter what. Deploy multiple OOB access links at every site, like 5G, satellite, MPLS, etc. These layers of connectivity significantly improve recovery times and practically eliminate the need for truck rolls during incidents.


3. Standardize Infrastructure and Centralize Management

It’s difficult to manage sprawling networks when every site has bespoke configurations or tools, separate VPN connections, manual device inventories, etc. This approach is not sustainable in distributed environments because it slows down troubleshooting and creates operational bottlenecks/inefficiencies.

Imagine an engineer logging into devices one-by-one across different tools and interfaces – while juggling IP addresses and credentials for everything – and having to bring services back online ASAP during a severe outage.

Standardizing infrastructure and centralizing management eliminates this complexity by creating a consistent operating model across every site. Instead of managing devices through disconnected tools, spreadsheets, and manual processes, teams get a unified architecture for accessing, monitoring, and controlling infrastructure.

When designing your out-of-band network, the goal is to simplify operations at scale. Look for solutions that replace IP address spreadsheets and fragmented workflows with a centralized, intuitive interface. Prioritize platforms that eliminate manual configuration processes and instead enable zero-touch provisioning and standardized deployment templates. Consistent visibility and control across locations helps you troubleshoot faster, recover from outages efficiently, and operate a distributed network without complexity.

4. Reduce Hardware Sprawl Where Possible

Traditional out-of-band deployments involve multiple standalone devices for routing, failover, console access, and security. This approach works, but it creates unnecessary complexity at remote sites. More hardware means more power consumption, more rack space requirements, and more management overhead.

Consolidates OOB Into One Device
Image: Modern out-of-band devices, such as ZPE Systems’ Nodegrid Services Routers, are capable of combining many functions, like routing, switching, cellular, out-of-band, and more into a single appliance.

Simplicity helps with resilience, and modern OOB architectures design around this principle. When building your out-of-band network, reduce hardware sprawl as much as possible by consolidating functions. Look for devices that can handle routing, switching, cellular failover, and more in a single rack unit or less. This makes it much easier to deploy, maintain, and scale your out-of-band infrastructure.


5. Continuously Test Failure Scenarios

Having the resilience strategy and architecture in place is only part of the solution. Outages have a way of upending even the most meticulous plans. Failover processes, recovery workflows, and remote access procedures can behave radically different during actual incidents than they do during normal operations, so regular testing is a must.

Testing helps to identify gaps and fixes instead of discovering these during a real-world scenario. Just imagine scrambling during an outage because incorrect APN settings are preventing 5G connectivity, or expired certificates are blocking remote connections, or outdated firmware is causing compatibility issues.

Once your out-of-band network is built, make sure to regularly validate that engineers can access infrastructure during failure scenarios. You’ll gain the confidence that your out-of-band environment will perform as expected when it matters most.

Get Help Evaluating Your Environment

Connect with a ZPE engineer to discuss your current environment and see how to close any resilience gaps in your architecture. Get in touch using the form.

Build a Resilient Out-of-Band Network With These Resources

Out-of-band infrastructure provides the independent access layer required to reduce downtime, accelerate recovery, and maintain visibility during outages. But deploying an effective OOB strategy needs to account for connectivity, security, and scalability. We compiled these resources to help you build your resilient out-of-band network.


Download the Blueprint for Network Resilience

Want to see how these principles fit together? Download the Network Resilience Blueprint to learn a practical framework for designing an infrastructure that’s easy to manage and quick to recover.

The Network Resilience Blueprint

ZPE Systems Introduces NSR 2U and NVIDIA Jetson Expansion Card, Combining AI Acceleration, Networking, and Infrastructure Resilience

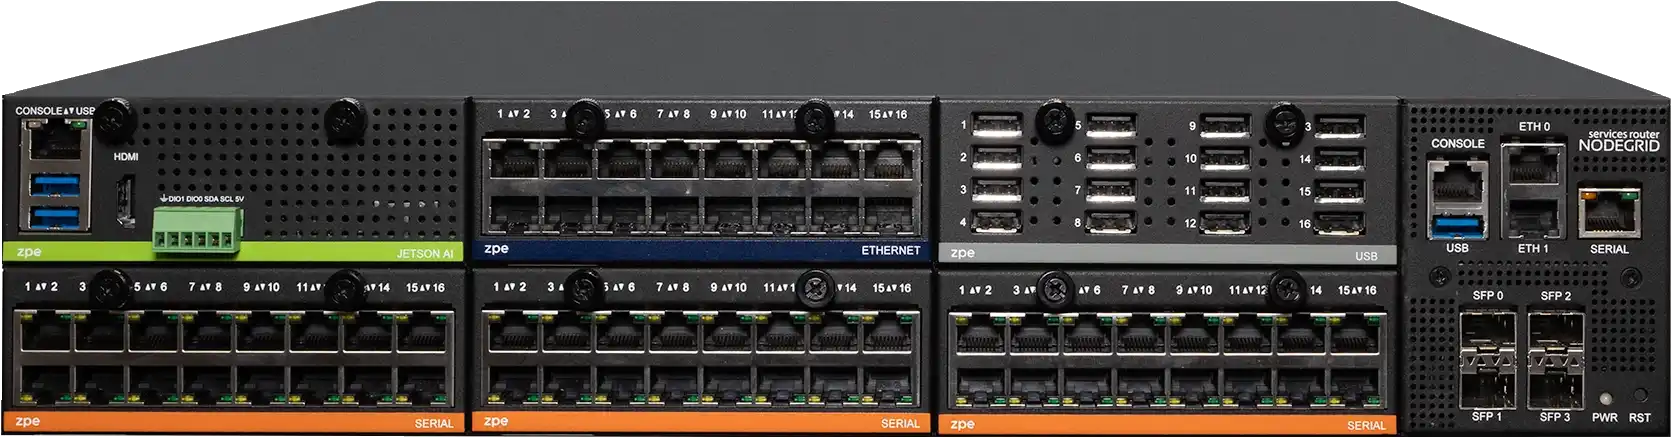
Nodegrid Net Services Router 2U

Las Vegas, NV — June 1, 2026 – At Cisco Live 2026, ZPE Systems (a brand of Legrand) today announced the Nodegrid Net Services Router™ 2U (NSR 2U), a modular, next-generation x86 platform that consolidates routing, network services, and out-of-band (OOB) management into a single, centrally managed system for distributed and edge environments.

As organizations expand AI workloads across edge and distributed environments, infrastructure teams face growing operational complexity, rising downtime risks, and limited visibility during outages. The NSR 2U addresses these challenges by combining networking, AI acceleration, compute, and integrated out-of-band management into a single resilient platform.

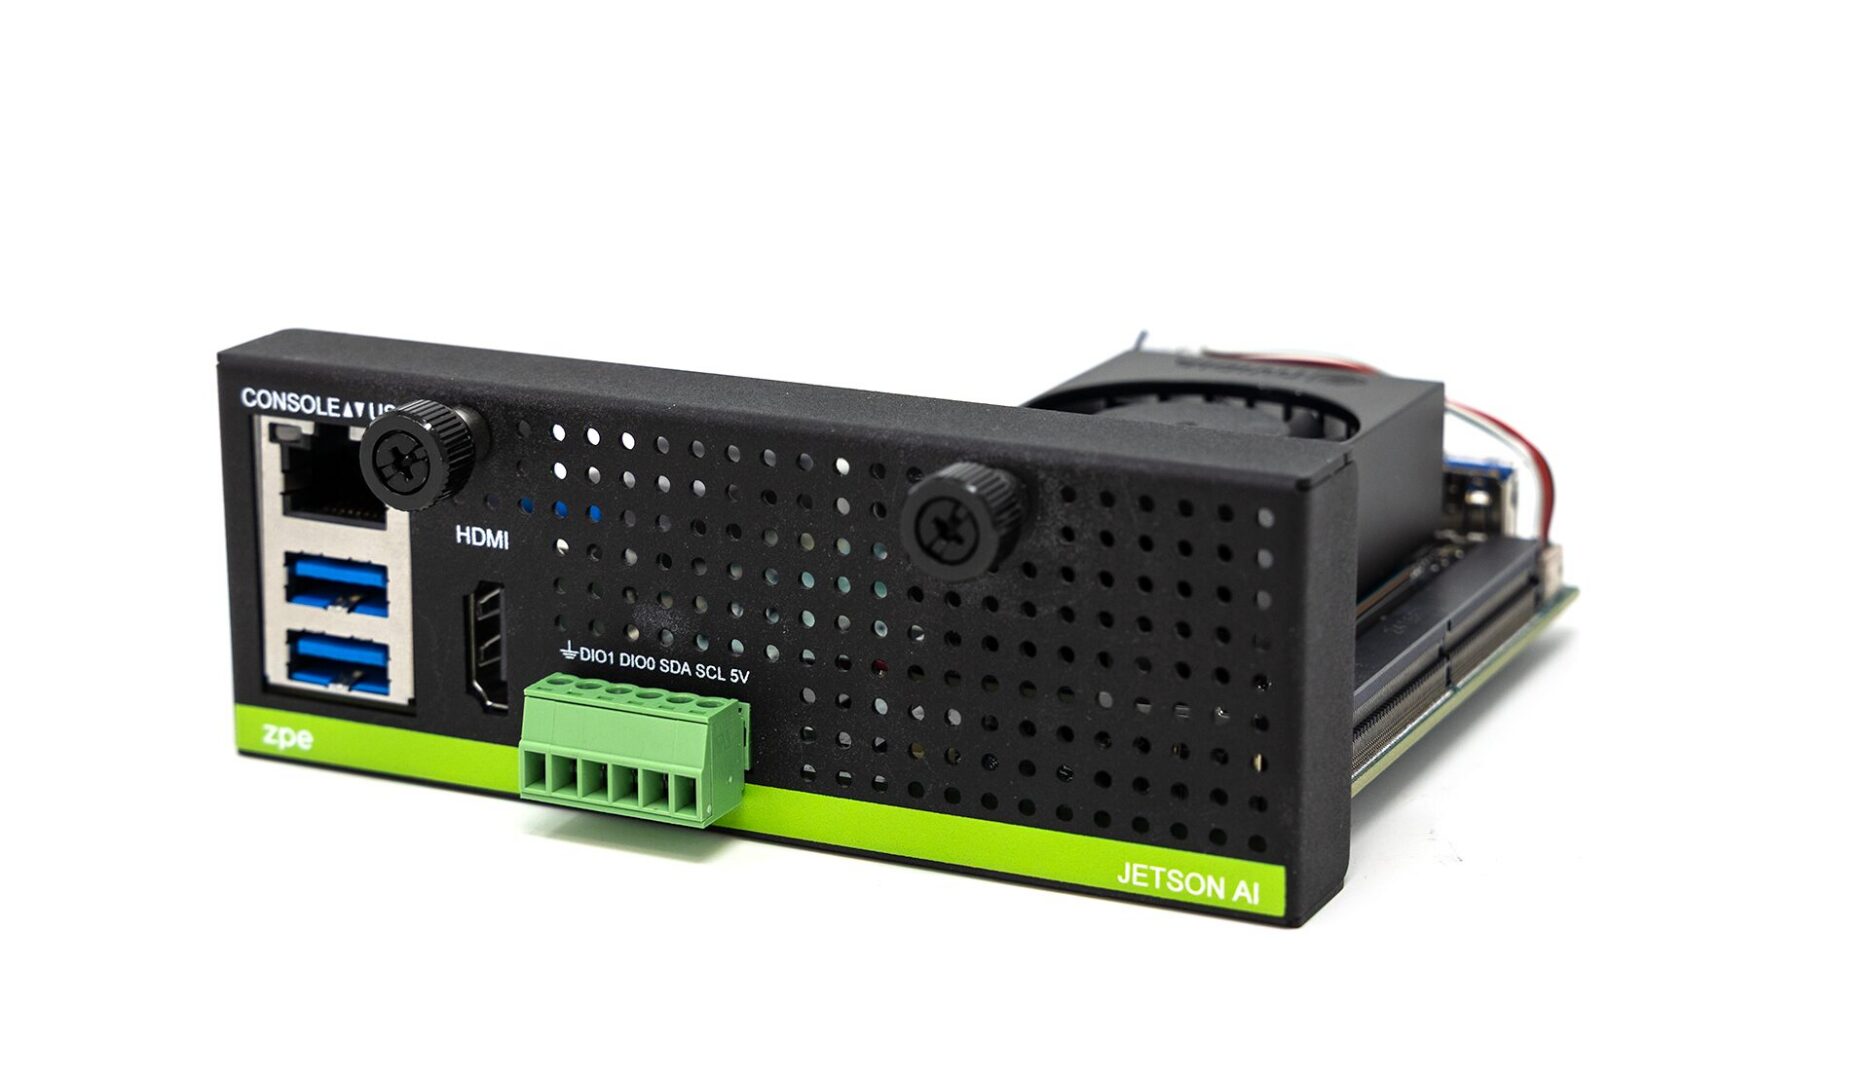
Jetson—NSR-Card—Front-Angled

Alongside the new platform, ZPE Systems is introducing the NVIDIA Jetson AI Expansion Card for NSR—backward compatible with both NSR and NSR 2U—enabling customers to run edge AI inference and acceleration directly on the device at the edge without adding external servers or operational complexity.

The NSR 2U represents a significant leap in performance, modularity, and serviceability, providing organizations with a future-ready foundation for secure, scalable, and automated infrastructure operations.

The combination of AI acceleration and integrated OOB management enables organizations to build infrastructure that can both detect issues intelligently, and also remain reachable and recoverable during failures. Setting a new industry standard, the solution is the first platform to combine networking, edge AI, compute, and recovery in one system, providing a resilient, AI-ready solution that keeps infrastructure running during primary network outages.

“Our customers are managing increasingly complex remote sites with minimal on-site staff and told us they needed a single platform that could do it all from anywhere. The NSR 2U is that platform — and with the NVIDIA Jetson Expansion Card, it brings AI-powered network operations to the edge,” said Vishal Gupta, Director of Product Management, ZPE Systems. “It’s the most capable Nodegrid appliance we’ve ever built, driven entirely by customer demand.”

A New Standard for Edge, Cloud, and Data Center Infrastructure

The NSR 2U is purpose-built to consolidate networking, compute, and management into a single platform capable of running diverse workloads across edge, cloud, and data center environments.

It supports a wide range of functions, including high-performance switching, security services, WAN optimization, containerized applications, and resilient out-of-band access, all within a unified system.

Its 2U architecture, combined with 10 expansion slots, upgraded compute, and a next-generation switching fabric, gives organizations the flexibility to build and scale infrastructure based on their exact requirements, without overprovisioning or deploying multiple appliances.

This makes the NSR 2U ideal for distributed enterprises, retail and remote locations, service providers, and converged infrastructure (CI) deployments.

AI at the Edge: Introducing the NVIDIA Jetson AI Expansion Card for NSR

The newly launched NVIDIA Jetson AI Expansion Card for NSR brings GPU‑powered intelligence directly into the Nodegrid ecosystem. Designed for both the NSR and NSR 2U platforms, this card enables customers to run AI/ML workloads where they matter most: close to data sources, users, and critical infrastructure.

This new module allows organizations to:

  • Run real‑time inference for security analytics, anomaly detection, and predictive maintenance
  • Deploy AI‑driven automation for network optimization and event correlation
  • Process video, sensor, and telemetry data locally to reduce cloud dependency
  • Consolidate AI, networking, and OOB management into a single, compact platform

By integrating NVIDIA Jetson into the NSR architecture, ZPE Systems eliminates the need for separate edge AI devices, reducing cost, complexity, and power consumption while enabling resilient, AI-driven infrastructure operations that remain manageable and recoverable even during outages.

With the NSR 2U and NVIDIA Jetson, ZPE Systems is redefining infrastructure operations for the AI era by bringing networking, intelligence, and resilience together into a single platform.

Explore the NSR 2U and NVIDIA Jetson Card by visiting the links below. Explore product specs, download the data sheet, and set up a demo to get hands-on with these new products!

Enhancing IT Operations with AI and Out-of-Band (OOB) Management

Thumbnail – Enhancing IT Ops with AI & out-of-band

You don’t really understand your infrastructure until it stops responding.

Not when dashboards are green or when alerts are quiet. But when you lose access to a core device, the network path disappears, and suddenly all your tools depend on the very thing that just failed.

That’s the moment most traditional IT operations fall apart.

Over time, I’ve realized that two things fundamentally change how you operate in those moments:

AI that helps you understand what’s happening, and Out-of-Band (OOB) access that lets you actually do something about it.

Put these together and they completely change how you operate.


The Reality of AI: Visibility Without Access is Useless

AI has made huge leaps in IT operations. It can analyze logs faster than any human, correlate events across systems, and let you know about issues you might not catch until it’s too late.

But there’s one big problem no one talks about enough: insight doesn’t fix outages.

You can know exactly what failed and still be locked out of the device you need to fix.

That’s where OOB comes in. OOB gives you a path that doesn’t depend on the production network. When everything else breaks, it’s the one door that still opens.

When you have both intelligence and access, you stop being stuck even when these worst-case scenarios happen.


Where AI Shows Up In My Work

In my role supporting IT infrastructure and network operations, the combination of AI and OOB directly improves how I manage incidents, maintain systems, and make sure everything keeps running.

1. When Something Breaks and You Don’t Have Time To Guess

Most incidents start with a lot of noise. Alerts pile up, metrics spike, and the systems all tell different stories.

AI helps cut through that noise and chaos. It highlights what’s abnormal, correlates signals, and points you in a direction that’s useful.

Then, instead of trying to reach a device through a broken network path (or waiting for someone on-site), you can go straight in through the out-of-band path. You don’t have to put up with delays or workarounds. You see the issue and you act on it right away.


2. When The Network Is Down – And That’s The Whole Problem

This is the scenario that exposes every weakness in traditional remote access. VPNs fail, jump hosts become unreachable, and monitoring tools go dark.

Suddenly, you’re blind and locked out at the same time.

With OOB, that doesn’t happen.

You still have direct access to your routers, switches, firewalls, and servers, because your management path isn’t tied to the outage. That means you can:

Out of band management for MSPs and remote recovery

Now layer AI on top of that.

Instead of reacting manually, you can trigger recovery actions based on known patterns. The system identifies the issue, and you either validate or let automation handle it.

You fix the issue within minutes instead of waiting hours to regain control.


3. When Alerts Become a Problem

Alerts become their own kind of outage. So many can come in, make too much noise, and become easy to ignore or shift way down on the priorities list.

AI helps pull the signals from the noise. It learns patterns, reduces false positives, and prioritizes what needs attention now. Combine this with OOB and it becomes actionable.

You’re getting alerts that matter now, and a way to immediately respond to them regardless of the network’s state. This changes how teams operate under pressure, especially when there’s so much noise that risks putting teams into a state of analysis paralysis.


4. When You See The Failure Coming

Some of the best outages are the ones that never happen.

AI is getting better at spotting early signals, like hardware behaving slightly off, configs drifting, and performance degrading in subtle ways.

Little problems you wouldn’t normally catch until they turn into really big problems.

With OOB access, you don’t have to wait. You can step in early to:

  • Validate configurations
  • Apply patches
  • Fix issues before they impact production

And you can do it without disrupting live traffic. The way you operate shifts from reactive to intentional.


5. When Security Incidents Get Complicated

Security events don’t follow clean paths. If a system is compromised, your primary network might not be trustworthy anymore. Access could be restricted or intentionally cut off.

That’s where OOB becomes your control point.

You can isolate systems, investigate directly, and respond without relying on potentially compromised infrastructure.

AI helps detect the threat. OOB gives you a way to contain it.

Without both, response slows down and risk increases.


The Shift Most Teams Don’t Plan For

Teams like to assume their tools will be there when they need them. Why wouldn’t they be, right?

But outages don’t work like that.

The very systems you depend on, like monitoring, remote access, and automation, often rely on the same network that just failed.

That’s the blind spot, and that’s what AI and out-of-band solve.

  • AI improves how you understand problems
  • OOB ensures you’re never locked out of fixing them

When you combine the two, you stop operating in a reactive loop of:

Detect Wait → Recover

And move toward:

Detect → Access → Resolve (immediately)


What You Can Do: Build Your OOB Network

After enough outages, you start to see that better tools don’t always make things better. It’s more about having tools that still work when everything else doesn’t.

AI helps you see what’s happening faster and more clearly. OOB ensures you’re never cut off from the systems you need to fix.

Together, they make IT operations resilient in the moments that actually matter. And those moments are the ones people remember.

Here are some helpful resources to start building your out-of-band network.

Get In Touch With Us!

If your environment depends on high uptime, fast response, and remote visibility, Nodegrid is the solution that incorporates AI with out-of-band management.

Use the form below to contact us and let’s talk about your network resilience goals.

rednesp Selects ZPE Systems to Deliver Always-On, High-Performance Research Connectivity

Thumbnail – rednesp case study

rednesp is São Paulo’s Research and Education Network, serving more than 20 universities, research institutions, and innovation centers across Brazil. rednesp provides critical network infrastructure for the scientific community, meaning uptime and performance are key.

Operating a research and education network at scale, however, comes with unique challenges. End users need to have reliable connectivity for performing experiments and simulations, and they need a high-performance network for transferring large datasets and running distributed workloads. Any outage could disrupt innovative work and potentially delay scientific breakthroughs. For rednesp, this means having total operational control over the infrastructure, and ZPE Systems’ out-of-band is the only solution that can live up to their needs.

Read the case study now to see how ZPE’s independent management plane, rapid recovery, and centralized control deliver the always-on, high-performance connectivity that rednesp’s community depends on.

DOWNLOAD THE CASE STUDY

How to Overcome the Top Network Failure Scenarios That Break MSP Remote Access

How to Overcome the Top Network Failure Scenarios

Managed service providers rely on remote access to keep customer environments running. VPNs, jump hosts, and centralized access tools make it possible to manage infrastructure across dozens or hundreds of sites without leaving the operations center.

But during outages, these tools can become part of the problem. When remote access depends on the production network, even routine failures can cut off the access engineers need to fix issues. What should be a quick recovery turns into a prolonged outage that requires on-site intervention.

Here are some of the most common failure scenarios MSPs face, and a look at the architecture that helps overcome them.


Routing Failures

Many routing failures stem from human error. According to 2025 research from the Uptime Institute, almost 40% of organizations suffered a major outage due to human error in the last three years. If a core router experiences a misconfiguration, control-plane crash, or routing instability, the network paths that connect engineers to the environment may disappear entirely.

Common examples include:

  • BGP route leaks or policy errors that remove upstream connectivity
  • OSPF adjacency failures that break internal routing between segments
  • VRF or VLAN misconfigurations that isolate management subnets
  • Routing table corruption during firmware upgrades

In these situations, VPN sessions drop immediately because the path between the engineer and the VPN gateway no longer exists. Worse, the router responsible for the failure may be fully operational from a hardware perspective and all it needs is a configuration correction. But engineers can’t gain remote console access to make this correction.

What should have been a 30-second configuration rollback becomes a multi-hour recovery effort.


Firewall Policy Errors

Firewall misconfigurations are one of the most common causes of remote access loss. Modern firewalls enforce highly automated policies through orchestration systems, policy templates, or automated compliance updates. These systems are great for consistency, but they introduce new failure modes.

A few examples include:

  • A security policy update accidentally blocking VPN management traffic
  • A zone-based firewall rule preventing internal device access
  • A NAT configuration error breaking inbound VPN connections
  • An automated policy sync overwriting existing allow rules

A lot of times, the firewall itself remains online and functional. The only issue is a misconfigured rule. Because the firewall sits directly in the remote access path, it becomes unreachable (just like the router we mentioned in the previous example). Engineers may be able to confirm the outage through monitoring systems, but without access to the firewall CLI or console, there is no way to correct the configuration remotely.


WAN or ISP Outages

Many MSP environments rely on customer WAN circuits to provide remote management access. Failures on these circuits cut remote connectivity regardless of the health of the internal infrastructure. Fiber cuts, for example, are one of the most common causes of outages that last 48 hours or longer.

Common scenarios include:

  • Carrier fiber cuts (looking at you, backhoe operators 😜)
  • Last-mile circuit failures at branch locations
  • ISP routing incidents causing upstream blackholing
  • DDoS mitigation events that disrupt inbound traffic


Backhoe Excavator

Image: Behold, the natural predator of fiber cables.

Customer networks may still be operating internally. Devices are running, servers are responding, and monitoring systems might still be collecting metrics locally. But engineers outside the network have no path into the environment. Even simple recovery actions like restarting an edge router or verifying a routing table may require on-site access.


Authentication Infrastructure Failures

Jump host environments depend on centralized authentication systems such as Active Directory, LDAP directories, or identity federation platforms. When these go down, engineers get locked out of their own management infrastructure.

This can happen due to:

  • Active Directory replication failures
  • Expired domain controller certificates
  • LDAP service crashes
  • Identity provider outages affecting SSO login flows

Engineers can probably still reach the jump host in these scenarios, but they can’t log in because authentication fails. The result is the same: engineers can see the problem, but they can’t access the systems required to fix it.


DNS and Management Service Failures

Another subtle failure mode occurs when core infrastructure services degrade. Many management environments rely on DNS resolution, certificate validation, or internal service discovery mechanisms.

If DNS services fail or management service endpoints become unavailable:

  • Jump hosts may not resolve device hostnames
  • SSH connections fail due to certificate validation errors
  • Automation platforms lose connectivity to managed infrastructure

The devices themselves may still be reachable, but the tools engineers rely on stop working.


The Pattern Behind These Failures

These scenarios might seem unrelated, but they all share the same root issue: remote access depends on the production network.

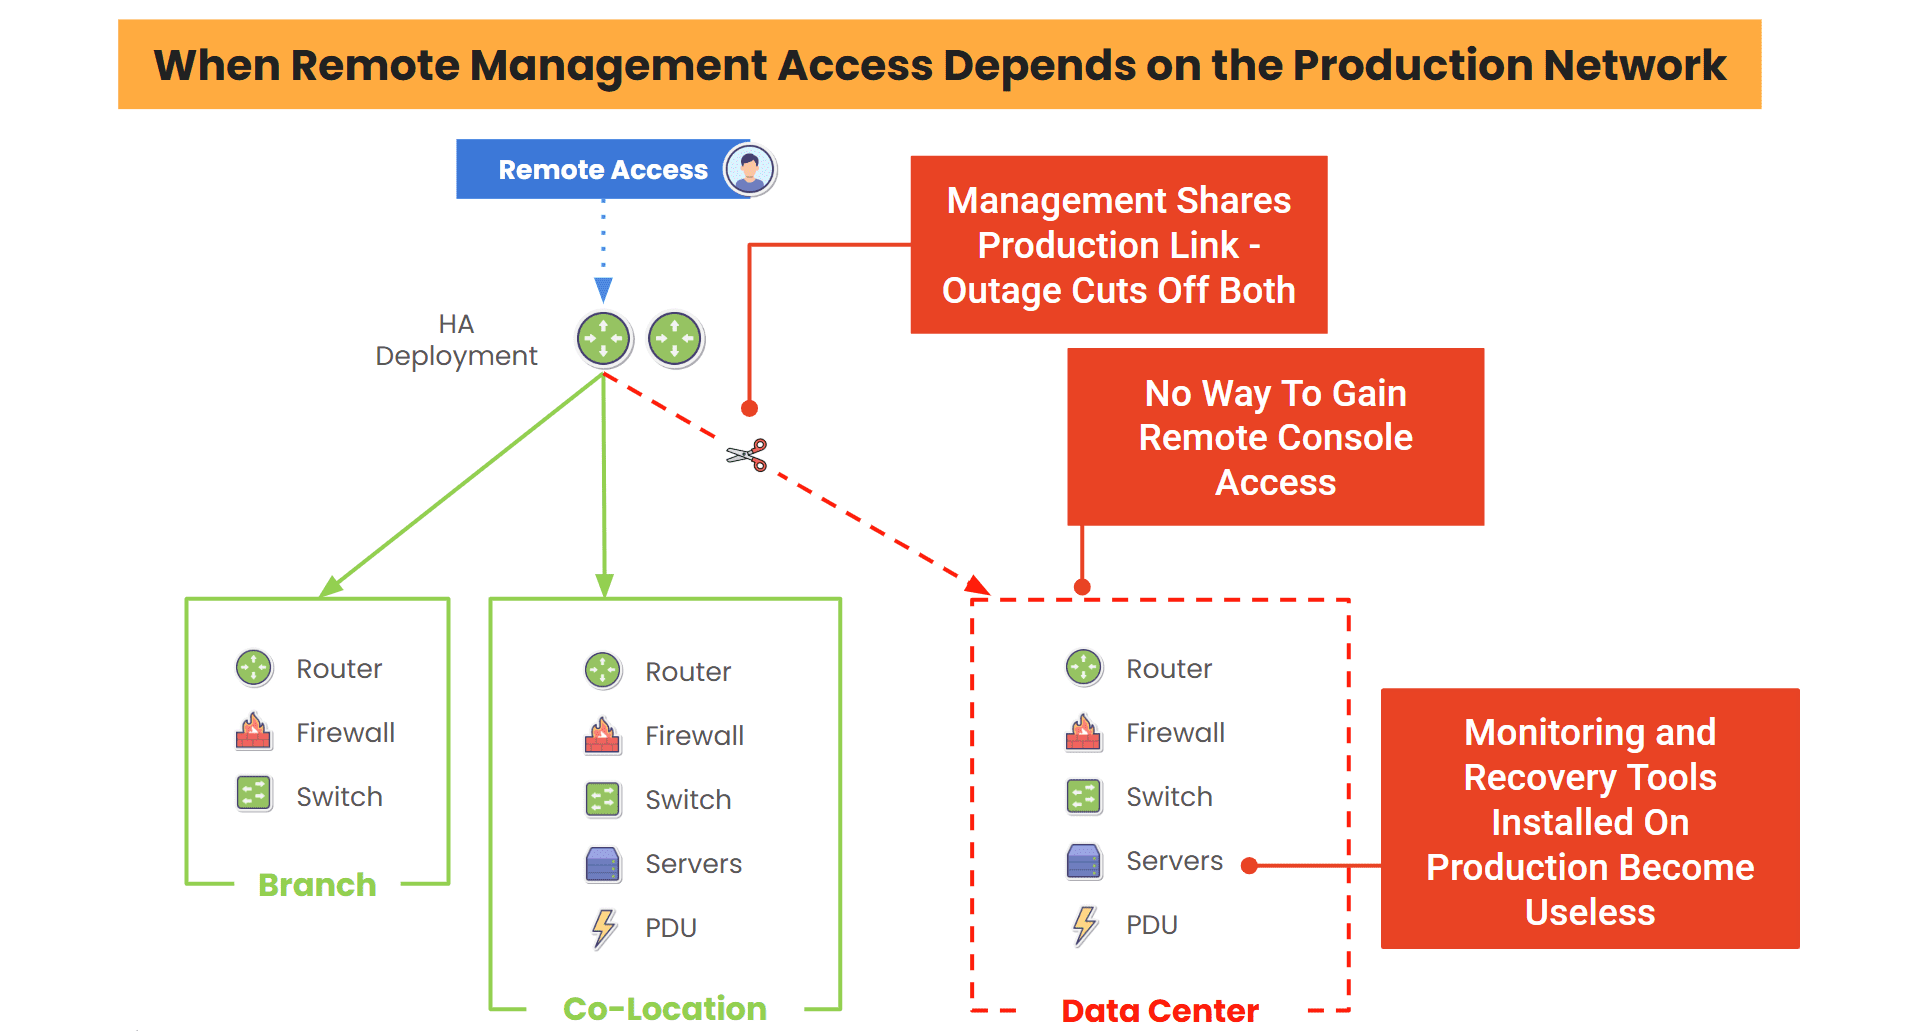
When that network fails, whether due to routing, security, WAN, or service issues, engineers lose the ability to reach the infrastructure they need to fix. That’s when recovery slows down, truck rolls and labor costs increase, and SLA risks rise.

In-band management relies on the network

Image: When remote management access depends on the production network, outages cut off both links, leaving engineers unable to remotely recover.

What should be routine incidents turn into operational disruptions. Engineers are unable to gain remote console access for recovery, and any tools running on the production network become useless. The only way to bring the network back online is to put engineers on site.


How To Overcome The Top Network Failure Scenarios

VPNs and jump hosts are effective, and they’re useful tools for day-to-day operations. But, MSPs won’t be able to overcome these top network failure scenarios if they rely on VPNs and jump hosts as the only path to critical infrastructure.

The key is being able to maintain access even when the production network goes down.

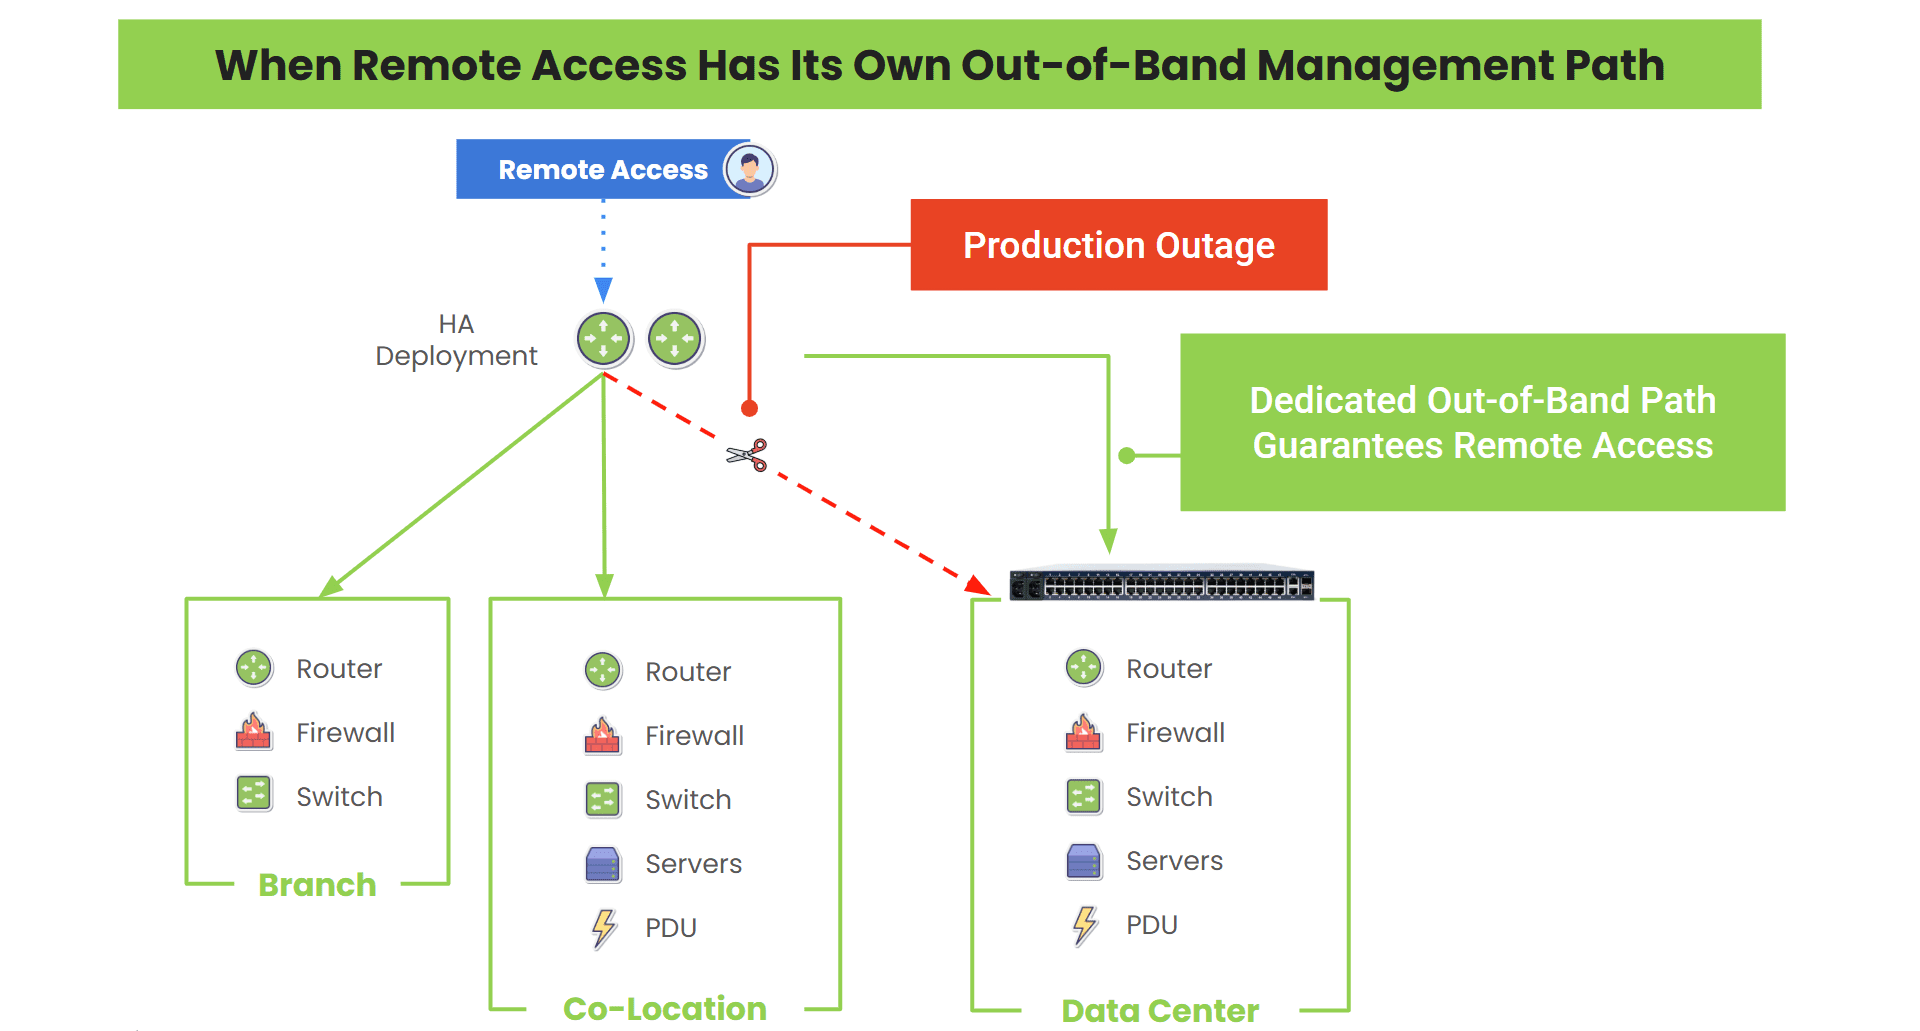
This is where out-of-band (OOB) and isolated management infrastructure (IMI) come into play. These create a completely separate remote access path that remains available no matter what kind of outages happen on the production network.

Out-of-band guarantees MSP remote access

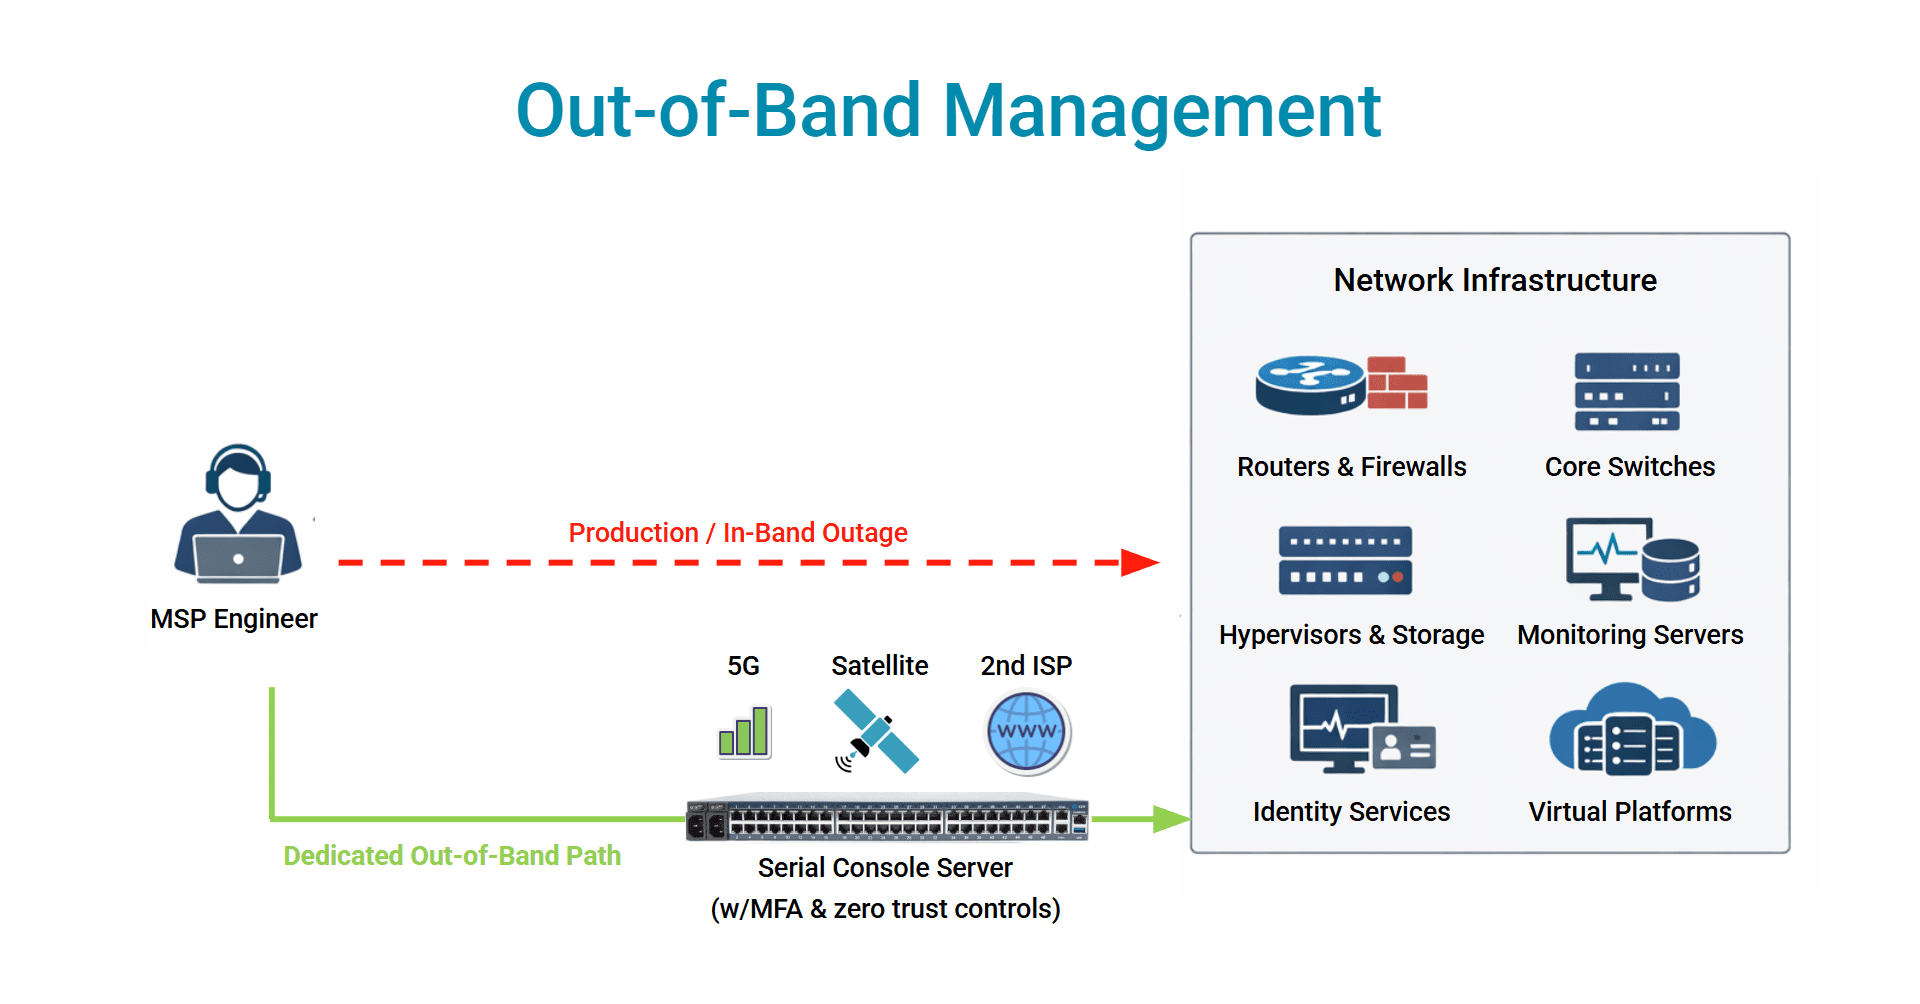
Image: A dedicated out-of-band management path ensures engineers can remotely access their infrastructure, even when there’s a complete outage on the production network.


What Can Engineers Do With Out-of-Band?

Modern OOB and IMI setups allow engineers to see what’s going on and act, no matter what’s happening on the production network.

This dedicated management path means MSP teams can:

  • Access device consoles directly, even if routing is broken
  • Perform config rollbacks on routers and firewalls after failed changes
  • Power-cycle/reboot equipment remotely (no on-site help needed)
  • Troubleshoot WAN failures from inside the network
  • Maintain access to infrastructure during ISP outages or authentication failures

Outages that would normally drag on for hours can now be resolved in minutes from the NOC. Check out our demonstration video to see what this looks like in action!

Calculate the Impact of MSP Network Failures

The most important question to ask is: can your engineers still reach the infrastructure when the network itself is down?

If the answer is no, it’s time to calculate how much these failure scenarios are costing in truck rolls, labor, and SLA penalties.

Use the MSP Downtime Cost Worksheet to quantify your exposure and see how much faster recovery could improve your margins.

Why VPNs and Jump Hosts Fail MSPs at Scale, And How To Fix It

Thumbnail – Why VPNs and Jump Hosts Fail MSPs at Scale

MSPs and Managed Network Service providers depend on remote access every day. Engineers connect to firewalls, routers, switches, hypervisors, and servers across dozens or even hundreds of customer environments. It’s a core function of operations, and without it, MSPs just wouldn’t exist.

The foundation of the remote access model is familiar for many providers: VPN tunnels combined with jump hosts or bastion servers. These tools allow engineers to log into a centralized environment and reach infrastructure across customer networks. This model works reasonably well when there are few customers. But as MSPs add sites, scale their customer base, and deploy more infrastructure, this traditional model becomes unmanageable.

Let’s find out why by looking at how VPN and jump host architectures actually work during real-world failure scenarios.


The MSP Remote Access Model

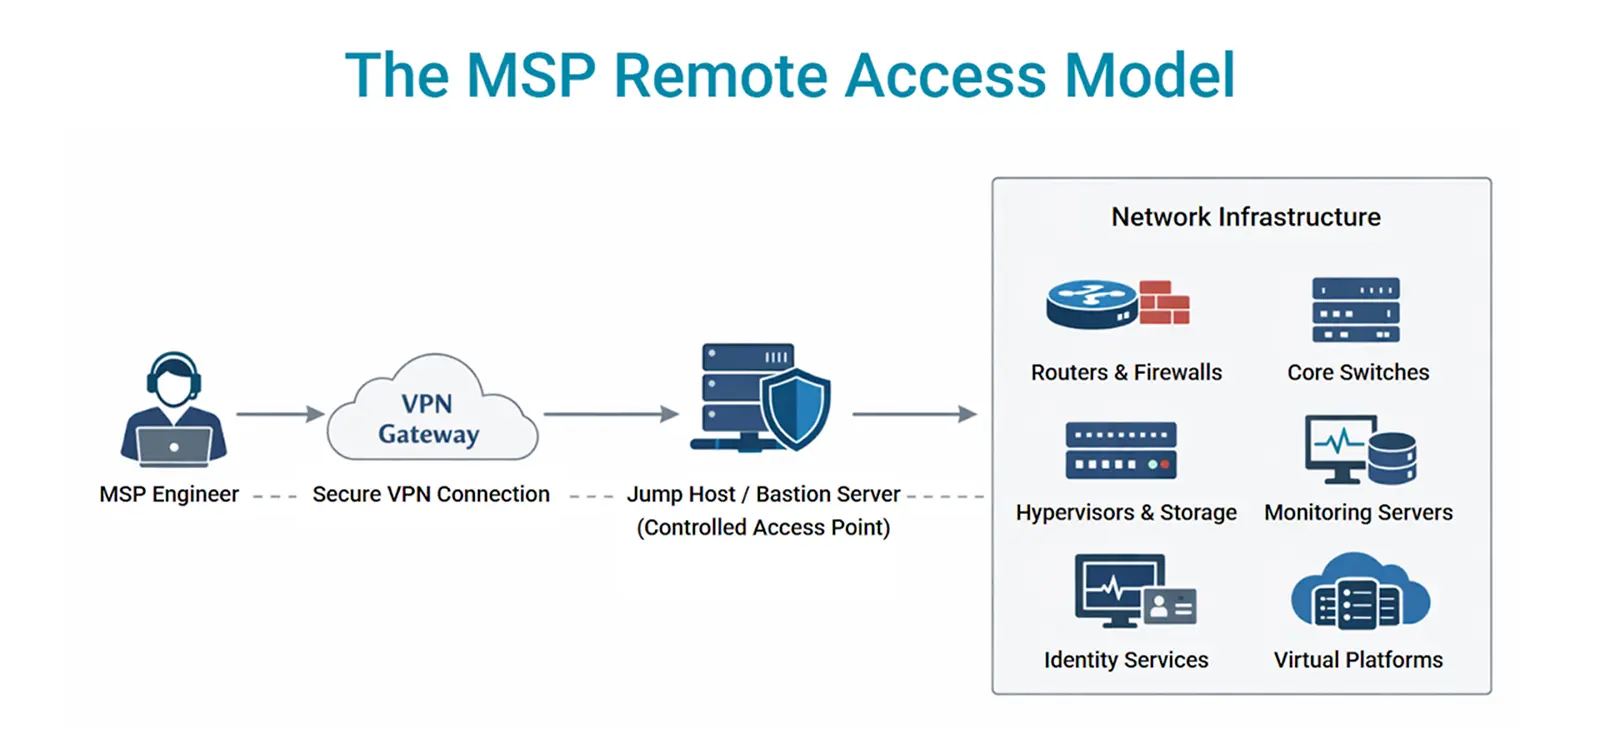
Most MSP/MNS environments rely on a layered remote access architecture. Engineers connect through a VPN gateway hosted either by the MSP or the customer environment. Once authenticated, they reach an internal jump host or bastion server that acts as a controlled entry point to the network infrastructure.

From the jump host/bastion server, they access infrastructure including:

  • Edge routers and firewalls
  • Core switches
  • Hypervisors and storage systems
  • Monitoring servers
  • Identity services
  • Virtual infrastructure platforms (like VMware, Microsoft Hyper-V, etc.)
msp-remote-access-model

Image: MSP remote access relies on the very infrastructure it manages.

This architecture has some benefits. It centralizes access control for the specific customer environment, somewhat simplifies credential management, and allows security teams to enforce authentication policies before engineers reach sensitive systems.

But remote access relies on the assumption that all of this production infrastructure remains operational.

What happens when it fails?


When In-Band Management Breaks: Common Failure Scenarios

VPNs and jump hosts operate entirely in-band, meaning they rely on the same network infrastructure they are meant to manage.

We covered this dependency at length in our last MSP article. Essentially, in-band management is cut off during failures, turning small issues into big outages that eat into MSP margins. And there’s a whole range of failures that can occur. Here are just a few of the common scenarios that lead to long outages and truck rolls:

Routing failures can entirely remove the path between engineers and the environment. A BGP misconfiguration, OSPF failure, or even a bad firmware update can drop VPN sessions instantly. The device causing the issue may still be running, but without access, engineers can’t fix it.

Firewall policy errors often block management traffic. A single misapplied rule or automated update can cut off access to internal systems. The firewall is online but unreachable, making a simple rule change impossible without on-site help.

WAN or ISP outages eliminate remote connectivity altogether. Even if the internal network is still functioning, engineers outside the environment have no way in. What should be a quick fix becomes a truck roll.

Authentication failures can lock engineers out of jump hosts, even when systems are otherwise healthy. If identity services like Active Directory or LDAP are unavailable, login attempts fail and troubleshooting stops.

Core service failures, such as DNS or certificate validation issues, can also break access indirectly. Devices may still be reachable, but the tools used to connect to them stop working.

We break down these scenarios and show you how to fix them in our Top Network Failure Scenarios article. But the pattern is clear: Even when infrastructure is still running, engineers lose the ability to reach it when it matters most.


Why the Problem Gets Worse as MSPs Scale

Let’s set aside the fragility of this in-band remote access model and talk strictly about scale. When you’re managing dozens of customer environments, each introduces more VPN gateways, firewalls/policies, routing domains, identity integrations, etc.

That simple remote access model turns into a highly distributed patchwork of VPN tunnels, jump hosts, bastion servers, and authentication systems spanning multiple networks. It doesn’t take a large leap of the imagination to see why this doesn’t scale.

Access is Fragmented

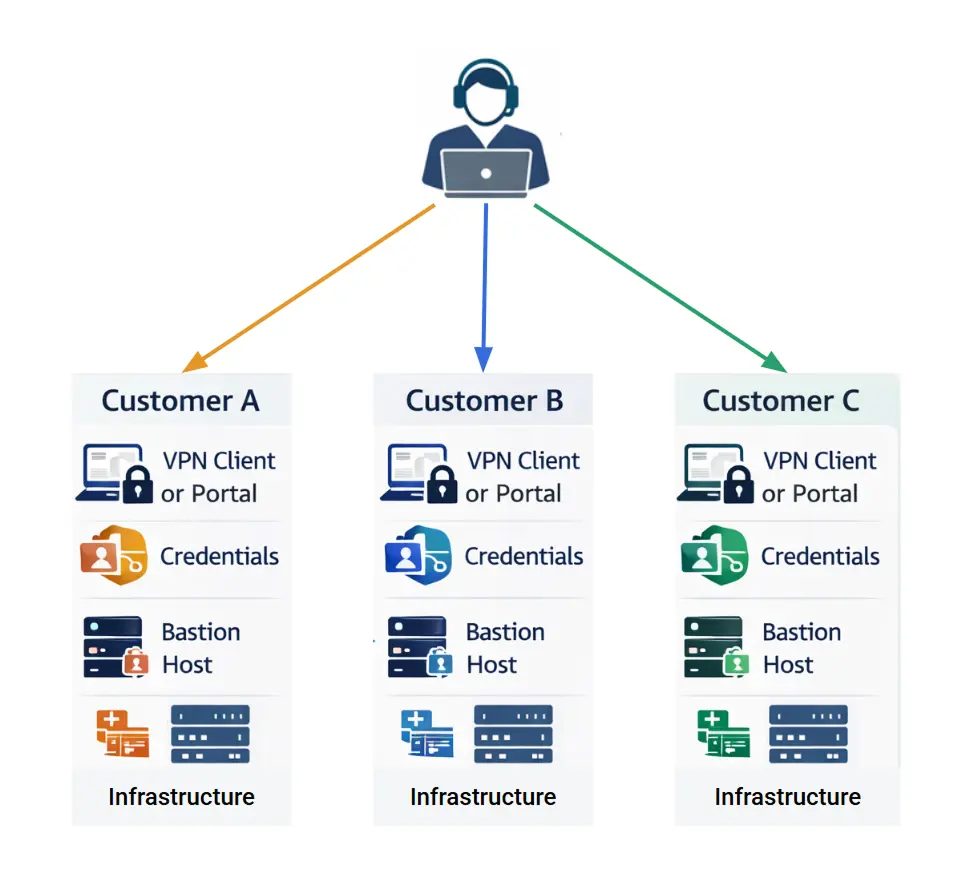
Engineers rarely connect to a single management environment (unless of course they’re using ZPE Cloud). Instead, they maintain separate access paths for each customer, which looks like this:

  • Different VPN clients or portals
  • Separate credential sets
  • Unique bastion hosts
  • Different network segmentation models
fragmented-access

Image: MSPs need to juggle multiple access paths, credentials, and infrastructure for different customers.

Troubleshooting a single outage may require navigating several access layers before even reaching the affected device. This slows response time and increases the likelihood of access failures during incidents.

Ops Overhead Grows

As environments get bigger, so does the job of maintaining access infrastructure. MSP teams need to set up and maintain VPN gateways, manage identity federation between organizations, monitor jump host infrastructure, rotate/secure access credentials, and fix connectivity issues.

It’s easy for engineers to spend as much time maintaining the access system as they do managing the infrastructure itself.

Recovery Delays Multiply Across Sites

One incident is manageable. But imagine there’s a regional ISP outage or widespread software bug that takes down a dozen customer sites. Engineers are forced to:

  • Queue troubleshooting tasks across environments
  • Dispatch all their technicians to remote locations
  • Coordinate access with third-party facilities
  • Work around broken VPN connectivity
Blue Screen of Death

Image: Software bugs, like the one that caused 2024’s CrowdStrike outage, can render mission-critical PCs useless until remedied by on-site intervention.

As the number of managed sites grows, these recovery delays compound and the limitations of traditional remote access become clear.

Operational Costs Rise Quietly

When managing so many sites and incidents per year, the financial impact adds up. That practical remote access solution becomes a hefty cost of doing business, especially when incidents require additional troubleshooting hours, escalations to senior engineers, on-site recovery/travel expenses, and SLA penalties/credits.

Engineering Turns Into Firefighting

One of the biggest impacts on business is when engineers can no longer focus on optimizing the network, automating jobs, or rolling out security enhancements, and instead have to focus on putting out ops fires. When strategic improvements take a back seat to remote access failures and reactive outage recovery, teams become less productive.


How To Fix It: Separate Management From Production

Solving the challenge doesn’t involve deploying more remote access or monitoring tools. Many MSPs are taking a step back and addressing the underlying architecture. They’re finding that out-of-band management using the proper Isolated Management Infrastructure (IMI) is the only path forward (pun intended).

Maintain Access When the Network Fails

Out-of-band architectures introduce a separate management path that operates independently of the production network. Instead of relying solely on VPN connectivity through the customer infrastructure, engineers can reach devices through a dedicated management plane designed specifically for recovery and operational control. This includes:

  • Direct console access to network and other devices
  • Independent connectivity using secondary and tertiary WAN links
  • Centralized management gateways that remain reachable during major outages

This management plane is reachable via 5G/cellular, satellite (like Starlink), secondary ISP, and other links. Modern serial console servers, like the Nodegrid Serial Console Plus, also include enterprise-grade security features like multi-factor authentication and zero trust controls, and isolation to keep the management plane completely hidden from threats. MSPs remain in control whether they’re battling a widespread outage or active cyberattack.

Out of band management for MSPs and remote recovery

Image: Out-of-band management allows MSPs to securely connect to infrastructure, even when the production network fails.

If routing breaks, engineers can still reach the router console.

If firewall policies block access, engineers can log in through the out-of-band path and correct the rule.

If the WAN circuit fails entirely, cellular/satellite connectivity still provides a path into the environment.

The key difference is that management access no longer depends on the health of the production network. Management access becomes completely independent and always reachable.

Simplify Operations Across Many Environments

Out-of-band helps address the operational complexity that scales with traditional in-band management. Engineers no longer need to juggle separate VPNs, credentials, jump hosts, etc. for each customer. They get one management infrastructure that centralizes access and standardizes connectivity across sites. MSP teams get to:

  • Maintain consistent access workflows across customers
  • Enforce centralized authentication and authorization policies
  • Audit administrative activity across all managed environments
  • Reduce the number of tools required to access infrastructure
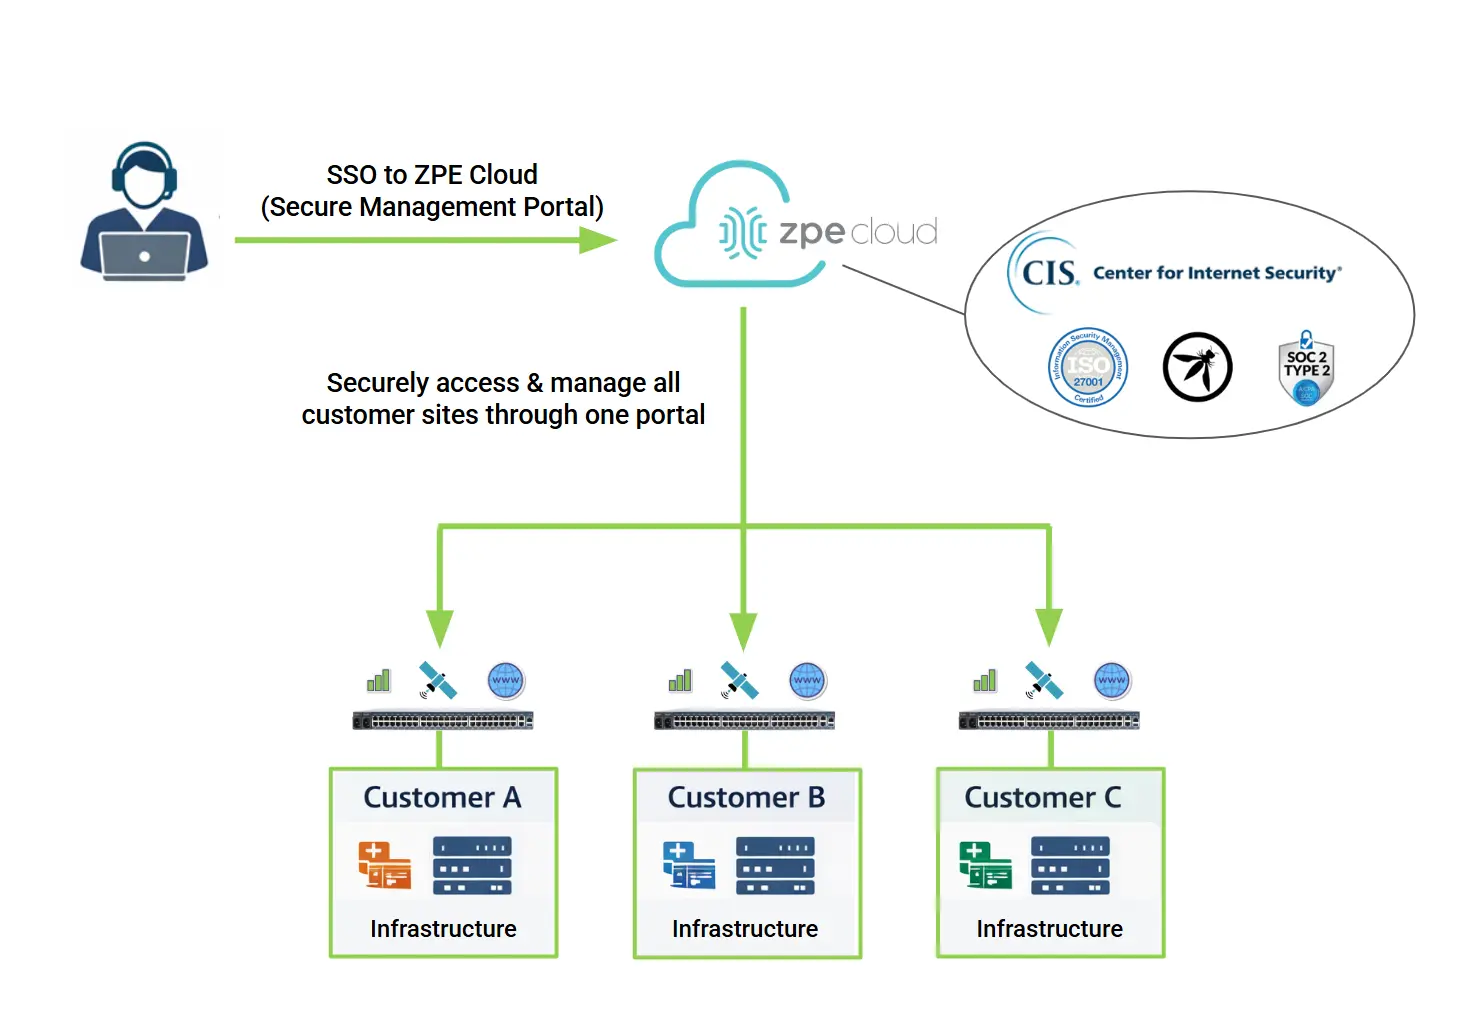
Centralized Management of MSP Customer Environments

Image: Out-of-band helps MSPs streamline day-to-day operations by eliminating the need to juggle multiple VPNs, credentials, jump hosts, and other access layers for each customer.

For MSPs that use the secure management portal ZPE Cloud, they can log in once and simply click to switch between customer environments (here’s a cool video showing how easy it is). This simplifies day-to-day operations and outage recovery, and helps teams become more productive.

Combine Resilient Access and Centralized Control

Modern platforms combine out-of-band connectivity with centralized orchestration to provide both operational resilience and secure access management. Solutions like ZPE’s Nodegrid are designed to act as a dedicated management gateway for distributed infrastructure. Within this single platform, MSPs can:

  • Maintain always-available console access to networking, computing, and their full stack of devices
  • Connect to remote sites through independent cellular or secondary links
  • Enforce role-based access controls and identity integration
  • Record and audit administrative sessions with detailed logging
  • Manage thousands of devices across geographically distributed environments
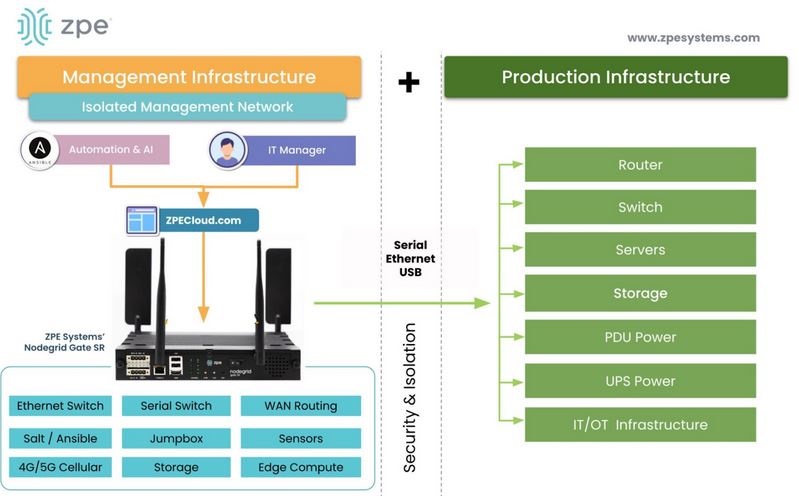
A diagram showing how to use ZPE to follow Gartner’s best practices for an isolated management infrastructure.

Image: ZPE’s Nodegrid devices combine 9+ functions into one and create an isolated management infrastructure ideal for secure, reliable access to production assets.

This architecture effectively creates an isolated management plane that remains available even when the production network is experiencing failures.

Make Recovery Predictable Instead of Reactive

For MSPs, the real advantage of this model is operational. When engineers know they will always be able to reach infrastructure during an outage, recovery becomes faster and more consistent. Troubleshooting can begin immediately, configuration errors can be corrected remotely, and incidents that used to require on-site intervention can be resolved from the operations center.

At scale, these improvements translate directly into measurable outcomes:

  • Faster mean time to resolution
  • Fewer truck rolls
  • Lower operational overhead
  • Improved SLA performance

In other words, the architecture changes how teams handle operations and how efficiently MSPs grow their business.


Understanding the Financial Impact

For many providers, the operational costs of traditional remote access models remain hidden until they analyze how often incidents require on-site intervention or extended troubleshooting.

To help MSP teams quantify this impact, we created a simple worksheet that estimates the true cost of downtime across managed environments.

It walks through common inputs such as incident volume, technician time, truck roll costs, and SLA penalties to calculate the annual financial impact of outage recovery.

From there, it shows how resilient management infrastructure can significantly reduce those costs. Download it now to analyze your costs and see your potential ROI by adopting out-of-band.

Why Most MSPs Still Struggle With Network Outages (Even With Great Tools)

Thumbnail – Why Most MSPs still struggle with network outages

Managed service providers have never had more technology at their disposal. Real-time alerts stream in from monitoring platforms. Engineers can troubleshoot off-site using remote access tools. Automation handles patching, configuration updates, and routine maintenance. On paper, today’s MSP toolkit is powerful and mature.

But when serious network outages happen, many providers still struggle to get back to normal. Restoring services can require hours of coordination, travel, and escalation. It’s this disconnect that raises an important question:

If the tools are better than ever, why is it so hard to recover from downtime?


There’s A Hidden Dependency Inside Traditional Remote Management

Some of the tools MSPs have at their fingertips are VPN tunnels, remote desktop sessions, and internally hosted jump environments. These are effective for routine maintenance. But this traditional remote management approach hides a major dependency: it all relies on the production network.

This is called in-band management, and it’s the biggest obstacle MSPs face when trying to get back online. In-band management is where admin access depends on the very infrastructure it grants access to. It works great when everything is working. But if a core router fails, firewall policies break, a WAN link drops, or an upstream provider experiences disruption, access disappears entirely.

ZPE Systems – In-band management cuts remote admin access during outages

Image: With in-band management, remote admin access is cut off when there is a production network outage.

At the basic level, this is a problem with the underlying management architecture (or lack thereof). Here are common obstacles that stem from in-band management and make MSPs struggle with network downtime.


Minor Issues Easily Turn Into Long Interruptions

Monitoring and alerting platforms excel at detecting problems. They can identify packet loss, device failures, link instability, and performance degradation within seconds. Engineers are immediately in the loop when something goes wrong.

The problem is these systems don’t provide the ability to act. If routing fails or firewall rules change unexpectedly, engineers lose the remote path needed to investigate. If an ISP circuit drops, VPN access vanishes with it. If DNS or authentication services become unavailable, login attempts stall.

Alerts keep coming in, dashboards light up, and customer complaints keep the phones ringing. But without direct device-level access, there’s no way to remotely reach the underlying infrastructure. What would have been a few minutes of troubleshooting turns into a prolonged service event requiring on-site support.


Physical Access Turns Into A Waiting Game

When remote access fails, on-site intervention becomes the only option, but this can also stand in the way.

Technicians often need to:

  • Drive several hours to the colocation or branch facility
  • Wait for security approval or badge verification
  • Schedule access windows during limited hours
  • Coordinate with third-party support
  • Navigate strict escort requirements
  • Deal with weather delays, travel logistics, or facility staffing shortages

Once they arrive, they also might have to wait longer for cage access, compliance checks, or coordination with other on-site personnel. Meanwhile, customer services remain degraded or offline.

No amount of monitoring can compensate for losing the path to the devices themselves.


Scale Turns Occasional Friction into Business Risk

These delays might feel like a small inconvenience. An engineer goes on site, fixes the problem, and moves on. It seems manageable.

But as MSPs scale, the friction compounds as each outage consumes:

  • High-value engineering hours
  • Travel budgets
  • SLA margin buffers
  • Customer satisfaction and positive reviews

As incident volume grows, recovery delays begin to affect staffing efficiency and profitability. Travel time expands. Skilled engineers spend more hours away from high-value work. Response windows widen, and maintaining consistent service-level performance becomes more difficult. The “manageable” approach becomes a structural drag on growth.

Traditional in-band management does not scale cleanly. It scales cost, complexity, and operational risk.


Why Better Tools Alone Won’t Solve the Problem

It’s tempting to think that you can solve the problem with more monitoring, automation, remote software, or other investments. But if you can’t reach the infrastructure when it matters most, no amount of tooling will save you.

The core issue is this: How do you get dependable, guaranteed access during failures? In even simpler words, how do you recover without rolling a truck?

Outages cut off MSPs from their tools

Image: When MSPs rely on in-band management, they can be easily cut off from remote admin access to customer sites.


Rethinking What “Prepared for Outages” Really Means

Resilient management access doesn’t mean what it did 20 years ago, when it was enough to plug in a console server and modem to be able to fix 90% of incidents. This outdated approach relies at least partly on production infrastructure, and even though out-of-band devices are used, they’re not set up on a proper out-of-band network. MSPs using this management model (and many still do) are only kind of prepared for outages…but not really.

True resilience requires physical and logical separation between management access and production traffic. Instead of relying solely on in-band connectivity, forward-looking MSPs are deploying dedicated out-of-band and isolated management infrastructure (IMI). This approach creates a separate, resilient access path that remains available even when the primary network fails. In other words, MSPs stay in control no matter what disruptions occur.

OOB gives MSPs dedicated remote access to their tools

Image: With dedicated out-of-band and isolated management infrastructure, MSPs can remotely access any managed device even during complete production network outages.

This architecture enables engineers to:

  • Maintain console-level access during WAN outages or cyberattacks
  • Remotely access power and BIOS controls for hard reboots
  • Reach network devices even if routing is misconfigured
  • Begin immediate troubleshooting and recovery without going on site
ZPE Systems – Out-of-band management and IMI guarantee remote admin access

Image: ZPE Systems’ Nodegrid allows MSPs to easily deploy out-of-band and IMI across branch, colocation, and data center sites.

Out-of-band and IMI help MSPs pivot from a reactive recovery posture to a proactive, engineered-resilience approach. But one major hurdle remains: How do you build this architecture?

Solutions like ZPE Systems’ Nodegrid are built specifically for setting up a proper out-of-band network and IMI. Nodegrid devices combine all the functions necessary, like routing, switching, cellular/satellite, and others, with an on-prem or cloud management model. In fact, Nodegrid can be used to set up an out-of-band network in less than an hour.

Beyond remote access, Nodegrid integrates identity enforcement, granular authorization, session logging and auditing, and dozens of enterprise-grade security features directly into its architecture. That means MSPs improve operational recovery and security posture simultaneously.

With out-of-band and IMI, MSPs can be confident that they’re prepared for any type of outage.


Calculate the Real Cost of Your Recovery Model

How much are outages actually costing you in truck rolls, labor, and SLA penalties? Get our free download to calculate your current costs and how much you could save by switching to Nodegrid. It only takes a few minutes. Download the guided walkthrough now!

Mercado Libre y ZPE: Garantizando el Uptime del Mayor E-commerce de América Latina

ZPE Systems – Mercado Libre – Garantizando el Uptime del Mayor E-commerce de América Latina

Mercado Libre, la plataforma de comercio electrónico y fintech más grande de América Latina, da soporte a más de 148 millones de usuarios con servicios de compras en línea, pagos y logística. Con más de 200 unidades operativas en toda la región, el uptime es crítico; un solo minuto de downtime puede retrasar envíos, paralizar pagos y afectar la confianza del cliente.

¿El desafío? Solo el 25 % de las unidades cuenta con personal de TI dedicado, lo que hace que las caídas del sistema sean costosas y lentas de resolver. Las fallas de Internet o de los enlaces del centro de datos pueden derribar aplicaciones principales, mientras que los errores de configuración en dispositivos clave pueden tardar hasta un día entero en solucionarse. Mercado Libre necesitaba una forma de simplificar la gestión a escala, garantizar la continuidad del negocio y evitar costosas intervenciones presenciales.

Al adoptar la plataforma Nodegrid de ZPE Systems, Mercado Libre obtuvo conectividad out-of-band basada en LTE, failover seguro hacia los centros de datos y gestión centralizada en la nube. El resultado es una mayor resiliencia, una recuperación más rápida y menos desplazamientos técnicos a campo — o, en otras palabras, convertir el uptime en una ventaja competitiva para la economía digital de América Latina.

Resultados clave:

  • Continuidad del negocio: Los envíos y pagos siguen fluyendo durante las caídas de red
  • Recuperación rápida: Las correcciones remotas evitan más de 24 horas de downtime
  • Eficiencia: Implementaciones más rápidas y menos visitas presenciales

“Todos en la unidad quedaron impresionados. El LTE integrado asumió la conexión automáticamente y la distribución continuó con normalidad. La solución de ZPE se pagó por sí sola con solo esta caída de red.”  –  Evandro Soares Correia, Jr. – Administrador de TI, Mercado Libre

DESCARGAR EL CASO DE ESTUDIO EN: