Providing Out-of-Band Connectivity to Mission-Critical IT Resources

Dissecting the MGM Cyberattack: Lions, Tigers, & Bears, Oh My!
Dissecting the MGM Cyberattack

This article was written by James Cabe, CISSP, whose cybersecurity expertise has helped major companies including Microsoft and Fortinet.

The recent MGM cyberattack reportedly caused the company to lose millions in revenue per day. The successful kill chain attack — originally a military tactic used to accomplish a particular objective — granted inside access to the attackers, who encrypted and held for ransom some of MGM’s most prized assets. These ‘crown jewel’ assets, as they’re called in the cybersecurity realm, are most critical to the accomplishment of an organization’s mission. Because ransomware attacks persist in corporate networks until fully cleared, organizations must be ready to “fight through” an attack using resilient systems and effective procedures. This should involve identifying these crown jewels and designing them in a way that ensures they can operate through attacks.

When these types of large-profile attacks occur, many cast their eyes at cybersecurity leaders for failing to fend off the bad guys. The reality is these leaders struggle to get budget, corporate buy-in, and digital assets that are required to build a strong defense for business continuity. For MGM, it’s likely they also faced difficulty operationalizing current assets across a gigantic digital estate, and ultimately lacked a plan to recover from a total outage of crown jewel assets.

From the attacker’s perspective, an exceptional level of intelligence and preparation are required in order to understand a target’s internal operations and architecture and execute a successful kill chain. Successfully attacking a sophisticated organization like MGM requires rapid information stealing to capture and leverage cloud credentials, as well as to lock up those resources and lock out the most important support staff in an organization. This is the crux of the issue: infostealers and ransomware automate the mass grabbing of resources and quickly set up a denial of services for the stakeholders that are responsible for fixing these systems.

How did the MGM cyberattack start? After MGM discovered the breach, how did the attacker stay one step ahead? What approach should organizations take to ensure they can recover if they’re targeted?

Who Started The MGM Cyberattack, and How?

The MGM cyberattack began after an adversary group named “Scattered Spider” used phishing over the phone, an approach called ‘vishing,’ to convince MGM’s customer support rep into granting them access with elevated privileges. Scattered Spider is the same group responsible for the SIM-swapping campaign that happened a few months ago, where they successfully subverted multifactor authentication. Their primary tactic involves social engineering, which they use to steal personal information from employees.  

MGM and many other casinos currently use advanced Zero Trust identity security from Okta. However, the attacker was able to trick the service desk into resetting a password to gain access into the network. Even with newer Zero Trust identity solutions, most organizations unravel once attackers get to the real “chewy center” of the network: the humans operating them. 
Spider Bug Insect graphic

Okta is quoted saying, “In recent weeks, multiple US-based Okta customers have reported a consistent pattern of social engineering attacks against their IT service desk personnel, in which the caller’s strategy was to convince service desk personnel to reset all multi-factor authentication (MFA) factors enrolled by highly privileged users.” Okta further warned, “The attackers then leveraged their compromise of highly privileged Okta Super Administrator accounts to abuse legitimate identity federation features that enabled them to impersonate users within the compromised organization.” 

The MGM cyberattack and those like it are more about processes than technology. Let’s explore how the attack progressed, and how the criminals were successful at staying persistent and ultimately hitting their goal. 

How Did A Simple Authentication Attack Morph Into a Complex Attack?

The Scattered Spider threat actors use a platform written by UNC3944 or AlphaV (known by several names). This is a middleware developer for attack platforms that allow criminals to follow a specific set of instructions (a kill chain) to gain access and ultimately encrypt and exfiltrate data from a targeted company. AlphaV’s platform is called BlackCat, which they use to establish a foothold, establish Command and Control (C2) for the malware, and exfiltrate data, to ultimately get paid.

With elevated Okta privileges at MGM, Scattered Spider deployed a file containing a Java-based remote access trojan, which became a “vending machine” for other remote access trojans (RATs) that sought out other nearby machines to spread quickly. The AlphaV RAT would ‘pwn‘ MGM’s Azure virtual servers to gain access, then sniff for more user passwords and create dummy accounts.  

These RATs leveraged a built-in tool called “POORTRY,” the Microsoft Serial Console driver turned malicious, to terminate selected processes on Windows systems (e.g., Endpoint Detection and Response (EDR) agents on endpoints). AlphaV, the platform maintainer, signed the POORTRY driver with a Microsoft Windows Hardware Compatibility Authenticode signature. This helped the malware to evade most Endpoint Detection software. 

This tool was used to get elevated and persistent access to the Okta Proxy servers that were in the scope of the attack and accessible remotely by the attacker. This attack can evade a lot of detection tools. This access allowed them to capture AM\IAM accounts that allowed them greater access to the organization. This stealing of credentials from the Okta Proxy servers was confirmed by Okta responders as well as the threat actor on their blog. This is called a “living off the land” attack. 
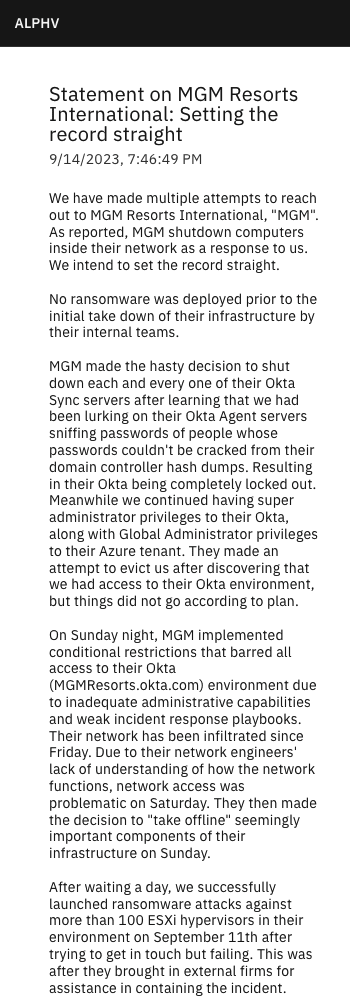
Alphv statement on MGM

How Did MGM Discover the Cyberattack?

The first notification of the hack was dropped on the VXUnderground forums. The staff there verified through chat contact with the threat group UNC3944\AlphaV, who works in conjunction with the Scattered Spider threat actor, The attacker also confirmed this on their blog on the darknets.

On September 11, 2023, anyone attempting to visit MGM’s website was greeted by a message stating that the website was currently unavailable. The attack also stopped hotel card readers, gaming machines, and other equipment critical to MGM’s day-to-day operations and revenue generating activities. 
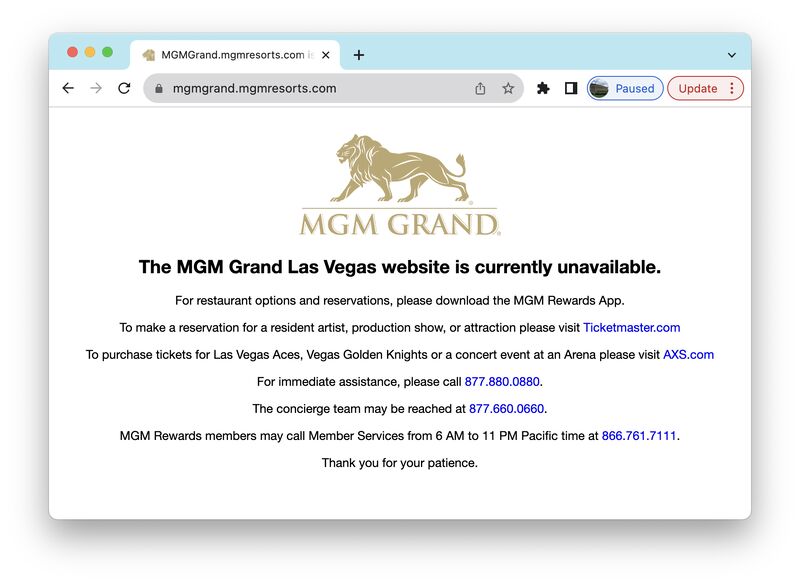
Screenshot showing MGM casino's website down.

How Did the Attacker Maintain Control?

The initial attack allowed AlphaV, who runs the C2 (Command and Control) networks for the RattyRat trojan, to have remote access to the VMware server farm that services the guest systems, the gaming control platforms, and possibly the payment processing systems. They maintained control despite all of MGM’s attempts to mitigate the problem, because they were able to establish elevated access in places the organization could not easily remove them from without removing access to the whole organization. They established something called “persistence.”

From the attacker’s blog on the darknet, “MGM made the hasty decision to shut down every one of their Okta Sync servers after learning that we had been lurking on their Okta Agent servers sniffing passwords of people whose passwords couldn’t be cracked from their domain controller hash dumps. At this point MGM being completely locked out of their local environment. Meanwhile the attacker continued having super administrator privileges to their Okta, along with Global Administrator privileges to their Azure tenant. They made an attempt to evict us after discovering that we had access to their Okta environment, but things did not go according to plan. On Sunday night, MGM implemented conditional restrictions that barred all access to their Okta (MGMResorts.okta.com) environment due to inadequate administrative capabilities and weak incident response playbooks. Their network has been infiltrated since Friday. Due to their network engineers’ lack of understanding of how the network functions, network access was problematic on Saturday. They then made the decision to ‘take offline’ seemingly important components of their infrastructure on Sunday. After waiting a day, we successfully launched ransomware attacks against more than 100 ESXi hypervisors in their environment on September 11th after trying to get in touch but failing.“

MGM tried many things to remove access into their network. However, because of an advanced attack that installed a shadow identity provider in their own Identity Solution, they were able to maintain access long enough to redeploy access to most of the assets they found to be the backbone of the company. AlphaV was then able to encrypt most of the crown jewels of MGM’s operations network.

Is There a Way to Stop These Types of Attacks? 

The MGM cyberattack required physical reconnaissance, patience, and a lot of planning to set up the kill chain. Playbooks that can protect against this kind of attack are hard to create, because it can mean taking all guest services offline for a period, which requires very high authority in the organization. One of the comments from the attacker was that the organization did not act fast enough to take all remote access offline to their management framework that consisted of Okta Proxy Servers. When they did, the adversary was then able to lock them out by submitting a Multifactor Authentication Reset. To stall the attacker, they would have had to induce a full outage of their crown jewels while a formal assessment of all assets could be performed. Taking assets offline requires buy-in at the board level and executive level, which are difficult to come by even if an organization emphasizes its operational excellence, detection, and defense.

Organizations should have a plan to quickly recover from a total loss of a site, outside of backups (which can be lost) and disaster recovery sites. Organizations need to be properly hard-segmented into a full IMI (Isolated Management Infrastructure). Keeping crown jewels safe from an attacker that targets the chewiest part of an organization should be top of any list going from 2023 budget to 2024 planning.

The following is a light version of what can be done in a fully-automated response that can take mere hours instead of days for an outage (a full operations blueprint will be out in the near future).
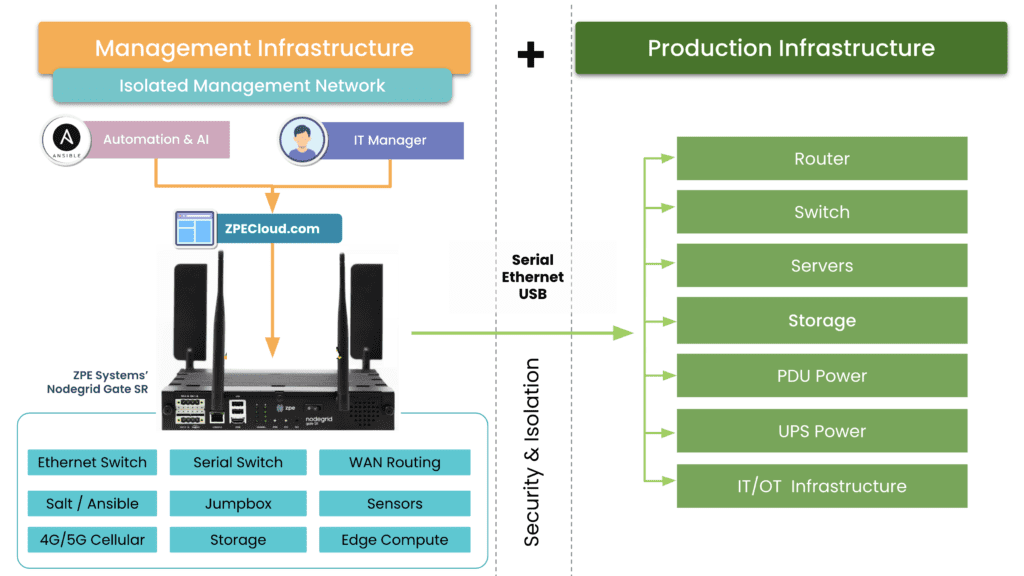
Isolated Management Infrastructure diagram

An IMI can host an IRE (Isolated Recovery Environment), which is used to cut off all user data and remote access (except for OOB) to an entire infected site. A properly implemented recovery environment should automate most of these activities to speed up the recovery. One of the first considerations is the requirement for a secondary organization in your IAM that is not attached to normal operations. This is what is known as a set of “Break the Glass” accounts. These are known in military circles but have made it into formal practice as part of a strong playbook for ransomware. Once you do this, you can instantiate selected Zero Trust remote access to the site using credentials that are not in the scope of the attack, and then bring up a communications channel for a virtual war room using software like Rocket Chat, Jitsi, Slack, or other standalone communications tools that are installable on the IRE environment. 

Avoiding normal authentication methods or IAM and normal communication channels is required for the integrity of the recovery and strengthens the recovery playbook. During this time, no email may be used that is associated directly with the organization. Ideally, email should never touch an account that is associated with it either.

The next step is to create a new set of clean side networks that do not directly connect to the main backbone or put it behind another firewall for triage good/bad. Using a sniffer software running on the IRE, the recovery team can then run a passive scan or an active scanner against all machines continuing to try to send email to exchange\M365. You can give access to people that are deemed good (not sending traffic) but lock off (with an EDR) the ability to open Outlook for a while, while keeping them on the web email. From there, continue working through to find all the sending drivers to see if they have a good backup. If not, back up the infected drive for offline data retrieval for later. Then reimage while scanning the UEFI BIOS during boot (if needed, run an IPMI scan). If the site has a list of assets that are considered crown jewels, prioritize these.

Once you have a segmented “clean side” established with all the network services required to operate the site (DNS, IAM, DHCP), then Internet access can be restored to this site on a limited basis; which means only out-bound communications, nothing in-bound. Restorative operations can continue apace. making sure that the infected side assets are captured in backup for later forensics following chain-of-custody if damages exceeding insurance limits are found to be the case. This is decided in the war room.

Get the Blueprint for Isolated Management Infrastructure

Maintaining control of critical systems is something security practitioners deal with in the Operational Technology (Industrial Control Systems) side of an organization. For them, the critical and most impactful part of the problem is the loss of control rather than the loss of data, a problem highlighted by the MGM cyberattack. Operational Technology Safety and Security teams set up and maintain Safety Systems as a fallback measure in case of any kind of disaster. This automation allows fallback of services safely, from which point they can recover operations. In 2023, most of our business is done on computers and networks. It is how to plan for business continuity. Now is the time that IT started following this safety system blueprint as well. 

Download the Network Automation Blueprint now, which helps you lay the groundwork for your IMI so you can recover from any attack.

Get in touch with me!

True security can only be achieved through resilience, and that’s my mission. If you want help shoring up your defenses, building an IMI, and implementing a Resilience System, get in touch with me. Here are links to my social media accounts:
What is a radio access network (RAN)?

This post provides an introduction to radio access networks (RAN) before discussing 5G RAN challenges, solutions, and use cases.
5G cellular technology is used for internet of things (IoT) deployments and operational technology (OT) automation across many different kinds of organizations, including city governments, global logistics companies, and healthcare providers. 5G access is provided by a radio access network (RAN) using mobile towers and small cells, but deploying these networks is challenging due to numerous factors, including poor public opinion. This post provides an introduction to radio access networks before discussing 5G RAN challenges, solutions, and use cases.

Table of Contents:

What is a Radio Access Network (RAN)?

A radio access network (RAN) is the portion of a cellular network that connects smartphones and other end-user devices to the internet. Information is communicated back and forth between smartphones and the RAN’s transceivers via radio waves. Those wireless signals are translated into digital form, passed to the core network, and then to the global internet.

What is 5G RAN?

Every cellular generation has its own associated RAN technology. 4G RAN was the first generation based entirely on the internet protocol (IP) rather than older circuit-based technology. The newest generation, 5G, supports faster speeds, great capacity, and lower latency than previous generations. However, there are significant challenges in the way of 5G implementation.

5G Radio Access Network (RAN) challenges

There are three major hurdles to 5G implementation:

  1. Public opinion – Thanks in part to misinformation and conspiracy theories, there has been a lot of resistance to 5G implementations. While many people already use smartphones with 5G technology, they tend to balk at the idea of giant cell towers and masts going up in their town or city.
  2. mmWave limitations – Wireless frequencies in the mmWave (millimeter wave) spectrum provide the speed and capacity required for 5G, but they have a shorter range and difficulty penetrating walls. That makes 5G tricky in industrial settings and office buildings.
  3. Remote recovery – A 5G RAN typically operates in cramped spaces without a continuous human presence, and administrators monitor and manage the equipment remotely over the cellular network. However, if that cell link goes down due to equipment failure or natural disaster, teams are cut off, and a truck must be rolled to fix the issue, adding significant costs and downtime.

Addressing these hurdles is complicated, as the solutions often create additional challenges. For example, the first two points can be addressed with 5G small cell technology. Small cells are typically compact enough to deploy on top of buildings or street furniture to extend 5G coverage into densely populated areas without a full-size mobile mast. This makes 5G small cell networks more palatable to city officials and the general public alike. However, small cells are still subject to planning restrictions, and the absence of a common 5G small cell framework makes the application process difficult and time-consuming.

In addition, some small cells are tiny enough to deploy indoors, improving 5G propagation and coverage in buildings. However, operators would need to deploy dozens or hundreds of small cells to achieve the speed and reliability needed for industrial IoT and high-tech use cases. Each one requires significant power resources as well as a fiber or wireless backhaul, and due to a lack of standardization, operators may even have to submit many individual planning applications. Plus, a small cell network of that size is complex to monitor and manage, requiring additional hardware and software solutions that add even more costs and complexity.

Addressing the third point requires an out-of-band network connection to 5G RAN deployments. For example, a 4G/LTE serial console provides an alternative internet connection so teams can remotely access RAN equipment during 5G outages. A serial console directly connects to radio access network infrastructure so remote administrators can do things like reboot a hung device or refresh DHCP even if the local network is down.

However, many serial consoles suffer from vendor lock-in, meaning they don’t connect to all devices or support third-party management, troubleshooting, and recovery tools. This either limits an administrator’s ability to remotely recover from outages or forces them to deploy additional hardware and software solutions to gain all the remote functionality required, adding to the expense and complexity of 5G RAN deployments.

A new approach to 5G deployments

The upgrade from 4G to 5G is proving to be more fraught than previous transitions between generations, so it’s clear that a new approach is needed. Small cell technology is a good start, but a lack of standardization severely hampers its adoption. Help is on the way, though – a group called the Small Cell Forum (SCF), which is made up of wireless leaders like AT&T, Cisco, Qualcomm, and Samsung, is working to establish a set of common definitions and recommendations to help the industry standardize 5G small cell networks.

In their definitional report, the SCF highlights the need for vendor-neutral hardware that’s customizable and swappable for various 5G use cases. Architectural design and planning applications are simpler when all of a small cell network’s equipment supports the same common 5G interface. Multi-functional devices combining networking, out-of-band access, and third-party application hosting significantly reduce expenses and management complexity.

Let’s examine some potential 5G use cases that could benefit from this new approach.

Smart cities

A smart city is the ideal use case for a 5G small cell network. Since wireless clients are packed into densely populated areas, an array of 5G small cells should provide sufficient coverage without the need for a full-sized mast. Deploying a small, vendor-neutral, multi-functional device like the Nodegrid Mini Services Router alongside small cells provides flexible backhaul options, out-of-band remote management, and application hosting. Installing small cells and Mini SRs on streetlamps, parking structures, and other public infrastructure gives teams everything they need to remotely monitor, operate, and recover 5G smart city infrastructure without adding more complexity to the network.

Global asset tracking and logistics

The internet of things (IoT) makes it possible for large, global enterprises to streamline asset tracking and supply chain logistics. Organizations use IoT-enabled devices to handle inventory management, fulfillment, shipment tracking, quality control, and more. 5G small cell technology provides the necessary speed, coverage, and bandwidth, but the sheer number of devices – and their global distribution – creates a lot of management complexity.

All-in-one solutions like Nodegrid reduce the tech stack by combining networking, management, and application hosting in a single box. Plus, Nodegrid provides a centralized management platform that can unify all connected devices, apps, and services in a single place. Administrators get a single pane of glass to monitor, control, troubleshoot, and automate the entire global architecture, reducing costs and streamlining operations.

Building automation

Many large property management companies rely on building automation systems that use operational technology (OT) to control door locks, lighting, HVAC, and more with very little human intervention. 5G’s improved speed and lower latency open up even greater automation capabilities, especially in warehouses and manufacturing plants.

Nodegrid’s compact, vendor-neutral solutions give remote operators a reliable, out-of-band connection to automated building systems to keep businesses running 24/7, even during 5G outages or LAN failures. You can deploy the Mini SR in cramped or semi-outdoor spaces to extend monitoring, security, and management coverage to every part of the 5G deployment. Nodegrid enables end-to-end building automation and makes 5G networks more resilient to failure.

Simplifying 5G with Nodegrid

A 5G radio access network (RAN) provides internet access to 5G-enabled systems, such as smartphones and IoT devices. While 5G deployments are proving complicated and fraught with issues, these challenges are overcome using small cell technology and vendor-neutral, multi-function devices like Nodegrid. Nodegrid’s integrated services routers deliver all-in-one networking, out-of-band management, backhauling, and application hosting capabilities to simplify 5G deployments without compromise.

Learn how Nodegrid can help deliver simplified 5G with out-of-band management!

Request a free Nodegrid demo to see how vendor-neutral solutions simplify 5G radio access network (RAN) deployments.

Contact Us

Data Center Migration Checklist

A data center migration is represented by a person physically pushing a rack of data center infrastructure into place
Various reasons may prompt a move to a new data center, like finding a different provider with lower prices, or the added security of relocating assets from an on-premises location to a colocation facility or private cloud.

Despite the potential benefits, data center migrations are often tough on enterprises, both internally and from the client side of things. Data center managers, systems administrators, and network engineers must cope with the logistical difficulties of planning, executing, and supporting the move. End-users may experience service disruptions and performance issues that make their jobs harder. Migrations also tend to reveal any weaknesses in the actual infrastructure that’s moved, which means systems that once worked perfectly may require extra support during and after the migration.

The best way to limit headaches and business disruptions is to plan every step of a data center migration meticulously. This guide provides a basic data center migration checklist to help with planning and includes additional resources for streamlining your move.

Data center migration checklist

Data center migrations are always complex and unique to each organization, but there are typically two major approaches:

  • Lift-and-shift. You physically move infrastructure from one data center to another. In some ways, this is the easiest approach because all components are known, but it can limit your potential benefits if gear remains in racks for easy transport to the new location rather than using the move as an opportunity to improve or upgrade certain parts.
  • New build. You replace some or all of your infrastructure with different solutions in a new data center. This approach is more complex because services and dependencies must be migrated to new environments, but it also permits organizations to simultaneously improve operational processes, cut costs, and update existing tech stacks.

The following data center migration checklist will help guide your planning for either approach and ensure you’re asking the right questions to prepare for any potential problems.

Quick Data Center Migration Checklist

  • Conduct site surveys of the current and the new data centers to determine the existing limitations and available resources, like space, power, cooling, cable management, and security.

  • Locate – or create – documentation for infrastructure requirements such as storage, compute, networking, and applications.

  • Outline the dependencies and ancillary systems from the current data center environment that you must replicate in the new data center.

  • Plan the physical layout and overall network topology of the new environment, including physical cabling, out-of-band management, network, storage, power, rack layout, and cooling.

  • Plan your management access, both for the deployment and for ongoing maintenance, and determine how to assist the rollout (for example, with remote access and automation).

  • Determine your networking requirements (e.g., VLANs, IP addresses, DNS, MPLS) and make an implementation plan.

  • Plan out the migration itself and include disaster recovery options and checkpoints in case something changes or issues arise.

  • Determine who is responsible for which aspects of the move and communicate all expectations and plans.

  • Assign a dedicated triage team to handle end-user support requests if there are issues during or immediately after the move.

  • Create a list of vendor contacts for each migrated component so it’s easier to contact support if something goes wrong.

  • If possible, use a lab environment to simulate key steps of the data center migration to identify potential issues or gaps.

  • Have a testing plan ready to execute once the move is complete to ensure infrastructure integrity, performance, and reliability in the new data center environment.

1.  Site surveys

The first step is to determine your physical requirements – how much space, power, cooling, cable management, etc., you’ll need in the new data center. Then, conduct site surveys of the new environment to identify existing limitations and available resources. For example, you’ll want to make sure the HVAC system can provide adequate climate control – specific to the new locale – for your incoming hardware. You may need to verify that your power supply can support additional chillers or dehumidifiers, if necessary, to maintain optimal temperature ranges. In addition to physical infrastructure requirements, factors like security and physical accessibility are important considerations for your new location.

2. Infrastructure documentation

At a bare minimum, you need an accurate list of all the physical and virtual infrastructure you’re moving to the new data center. You should also collect any existing documentation on your application and system requirements for storage, compute, networking, and security to ensure you cover all these bases in the migration. If that documentation doesn’t exist, now’s the time to create it. Having as much documentation as possible will streamline many of the following steps in your data center move.

3. Dependencies and ancillary services

Aside from the infrastructure you’re moving, hundreds or thousands of other services will likely be affected by the change. It’s important to map out these dependencies and ancillary services to learn how the migration will affect them and what you can do to smooth the transition. For example, if an application or service relies on a legacy database, you may need to upgrade both the database and its hardware to ensure end-users have uninterrupted access. As an added benefit, creating this map also aids in implementing micro-segmentation for Zero Trust security.

4. Layout and topology

The next step is to plan the physical layout of the new data center infrastructure. Where will network, storage, and power devices sit in the rack and cabinets? How will you handle cable management? Will your planned layout provide enough airflow for cooling? This is also the time to plan the network topology – how traffic will flow to, from, and within the new data center infrastructure.

5. Management access

You must determine how your administrators will deploy and manage the new data center infrastructure. Will you enable remote access? If so, how will you ensure continuous availability during migration or when issues arise? Do you plan to automate your deployment with zero touch provisioning?

6. Network planning

If you didn’t cover this in your infrastructure documentation, you’ll need specific documentation for your data center networking requirements – both WAN (wide area networking) and LAN (local area networking). This is a good time to determine whether you want to exactly replicate your existing network environment or make any network infrastructure upgrades. Then, create a detailed implementation plan covering everything from VLANs to IP address provisioning, DNS migrations, and ordering MPLS circuits.

7. Migration & build planning

Next, plan out each step of the move or build itself – the actions your team will perform immediately before, during, and after the migration. It’s important to include disaster recovery options in case critical services break, or unforeseen changes cause delays. Implementing checkpoints at key stages of the move will help ensure any issues are fixed before they impact subsequent migration steps.

8. Assembling a team

At this stage, you likely have a team responsible for planning the data center migration, but you also need to identify who’s responsible for every aspect of the move itself. It’s critical to do this as early as possible so you have time to set expectations, communicate the plan, and handle any required pre-migration training or support. Additionally, ensure this team includes dedicated support staff who can triage end-user requests if any issues arise during or after the migration.

9. Vendor support

Any experienced sysadmin will tell you that anything that could go wrong with a data center migration probably will, so you should plan for the worst but hope for the best. That means collecting a list of vendor contacts for each hardware and software component you’re migrating so it will be easier to contact support if something goes awry. For especially critical systems, you may even want to alert your vendor POCs prior to the move so they can be on hand (or near their phones) on the day of the move.

10. Lab simulation

This step may not be feasible for every organization, but ideally, you’ll use a lab environment to simulate key stages of the data center migration before you actually move. Running a virtualized simulation can help you identify potential hiccups with connection settings or compatibility issues. It can also highlight gaps in your planning – like forgetting to restore user access and security rules after building new firewalls – so you can address them before they affect production services.

11. Post-migration testing

Finally, you need to create a post-migration testing plan that’s ready to implement as soon as the move is complete. Testing will validate the integrity, performance, and reliability of infrastructure in the new environment, allowing teams to proactively resolve issues instead of waiting for monitoring notifications or end-user complaints.

Streamlining your data center migration

Using this data center migration checklist to create a comprehensive plan will help reduce setbacks on the day of the move. To further streamline the migration process and set yourself up for success in your new environment, consider upgrading to a vendor-neutral data center orchestration platform. Such a platform will provide a unified tool for administrators and engineers to monitor, deploy, and manage modern, multi-vendor, and legacy data center infrastructure. Reducing the number of individual solutions you need to access and manage during migration will decrease complexity and speed up the move, so you can start reaping the benefits of your new environment sooner.

Want to learn more about Data Center migration?

For a complete data center migration checklist, including in-depth guidance and best practices for moving day, click here to download our Complete Guide to Data Center Migrations or contact ZPE Systems today to learn more.
Contact Us Download Now

The Biggest Ransomware Attack You Haven’t Heard of…Yet

James Cabe CISSP

This article was written by James Cabe, CISSP, whose cybersecurity expertise has helped major companies including Microsoft and Fortinet.

MOVEit over SolarWinds — The largest and most successful ransomware attack ever recorded is happening. Right now. It’s attacking healthcare and financial institutions with high rates of success, and recently stole sensitive data of 4 million more healthcare patients. It uses something called CL0P ransomware, and the threat actor is a well-known criminal group with the name FIN11. Many organizations are finding it difficult to stop the attack because they have no way to access infected devices, take them offline, patch, or even replace them. So, what exactly is going on?

The group responsible for the attack

FIN11 is a cybercriminal group that has been active since 2016 or before, originating from the Commonwealth of Independent States (CIS). While the group has historically been associated with widespread phishing campaigns, their focus has shifted towards other initial access vectors. FIN11 often runs high-volume operations targeting industries in North America and Europe for data theft and ransomware deployment, primarily leveraging CL0P (aka CLOP).

FIN11 is responsible for multiple widespread, high-profile intrusion campaigns leveraging zero-day vulnerabilities, and the group likely has access to the networks of many more organizations than it is able to successfully monetize. Despite this, they’re currently attacking MOVEit, a well-known SaaS provider who relies on a file transfer appliance called Accellion lFile Transfer Appliance (FTA). This legacy product remains unpatched, which has led to the breach of many Fortune 100 companies and state and federal agencies.

FIN11

How did the ransomware attack start?

The ransomware attack began with several Accellion FTA customers, including those in industries like healthcare, legal, finance, retail, and telecom. Companies such as Jones Day Law, Kroger, Singtel, and many others had no idea that they had been attacked, because the initial breach was quiet and headless.

Their only indication came after receiving a threatening email aimed at extortion. 

In this email, the group threatened to publish stolen data on the “CL0P^_- LEAKS” .onion website, according to an investigation from Accellion. The Federal Bureau of Investigation (FBI) and the Cybersecurity and Infrastructure Security Agency (CISA) are releasing this joint CSA to disseminate known CL0P ransomware IOCs and TTPs identified through FBI investigations as recently as June 2023.

According to the investigation, four zero-day security holes were exploited in the attacks:

  • CVE-2021-27101 – SQL injection via a crafted Host header
  • CVE-2021-27102 – OS command execution via a local web service call
  • CVE-2021-27103 – SSRF via a crafted POST request
  • CVE-2021-27104 – OS command execution via a crafted POST request

And, the published victim data appears to have been stolen using a “WEB SHELL”. These web shells give remote administrative access to the web server and create a jumping off point to attack the rest of the internal network. Mandiant, a well-known cyber investigation arm of Google, added, “The exfiltration activity has affected entities in a wide range of sectors and countries” (Threatpost). Exfiltration is the unauthorized removal of important or damaging data from an organization.

However the biggest problem is that these web shells are what researchers call “PERSISTENCE”. This means that an attacker can remain in your network indefinitely to continue damaging and attacking your resources. Researchers call these “APTs,” or Advanced Persistent Threats.

Why is the ransomware attack still going strong?

The ransomware attack is still going strong because there’s no patch available. According to open source information, beginning on May 27, 2023, CL0P Ransomware Gang began exploiting a previously unknown SQL injection vulnerability (CVE-2023-34362) in Accelion’s appliance that is the backbone of a solution known as Progress Software’s MOVEit Transfer service. Internet-facing MOVEit Transfer web applications were infected with a web shell named LEMURLOOT, which was then used to steal data from underlying MOVEit Transfer databases. In similar spates of activity, TA505, which is the group responsible for the Dridex trojan and Locky ransomware, conducted zero-day-exploit-driven campaigns against Accellion FTA devices in 2020 and 2021, and Fortra/Linoma GoAnywhere MFT servers in early 2023.

What most organizations want to know is: How do you quickly respond to issues like these? How can you be properly prepared to respond to an issue you didn’t cause or didn’t expect?

Patching is a good response. However, it takes an average of 205 days to patch a recently known zero-day exploit like the MOVEit vulnerability. While patching alone is typically the ideal response, it isn’t automatic nor can it be done quickly.

Another approach involves removing the offending software or appliance, or cutting off access to the software or appliance. But once you remove this access, how do you continue normal operations, and how can you easily bring the software/appliance back online? Without adequate infrastructure in place, physically deploying to each site is not practical, especially for distributed organizations.

CISA and the FBI encourage organizations to implement the recommendations in the Mitigations section of this CSA to reduce the likelihood and impact of CL0P ransomware and other ransomware incidents. The Mitigations section describes many approaches, including patching, removing software/appliance access, and implementing a recovery plan. But all of these take too much time and too many resources, which leaves organizations vulnerable as they scramble to create an adequate response.

The great news is, organizations can cover all their bases without having to reinvent the wheel. This approach is recommended in one of CISA’s recent directives, and gives organizations somewhat of a silver bullet that allows them to quickly defeat ransomware and remain prepared for any future attack.

What approach does CISA recommend to address ransomware attacks?

CISA’s recent directive (23-02), which addresses the vulnerability of Internet-exposed management interfaces, calls for organizations to create an isolated management infrastructure (IMI) via out-of-band connectivity. This is a drop-in solution that the military, telcos, and hyperscalers/cloud companies use to respond to widespread ransomware and other issues impacting security and resilience. This approach — which ZPE Systems has perfected in the last decade with the help of Big Tech — gives organizations a completely separate control plane through which they can monitor and manage their entire IT infrastructure in a safe and dedicated fashion.

What is isolated management infrastructure?

Isolated management infrastructure consists of the hardware and software that create a management network that’s fully separate from other production and management networks. The key to this is in out-of-band connectivity, which is defined as connectivity other than TCP/IP. Out-of-band can include direct USB, serial, or even non-routed zero-trust connections to crown-jewel assets.

Essentially, the IMI gives an organization complete oversight and control of their widespread IT infrastructure, in a way that is secure and accessible only to their IT teams.

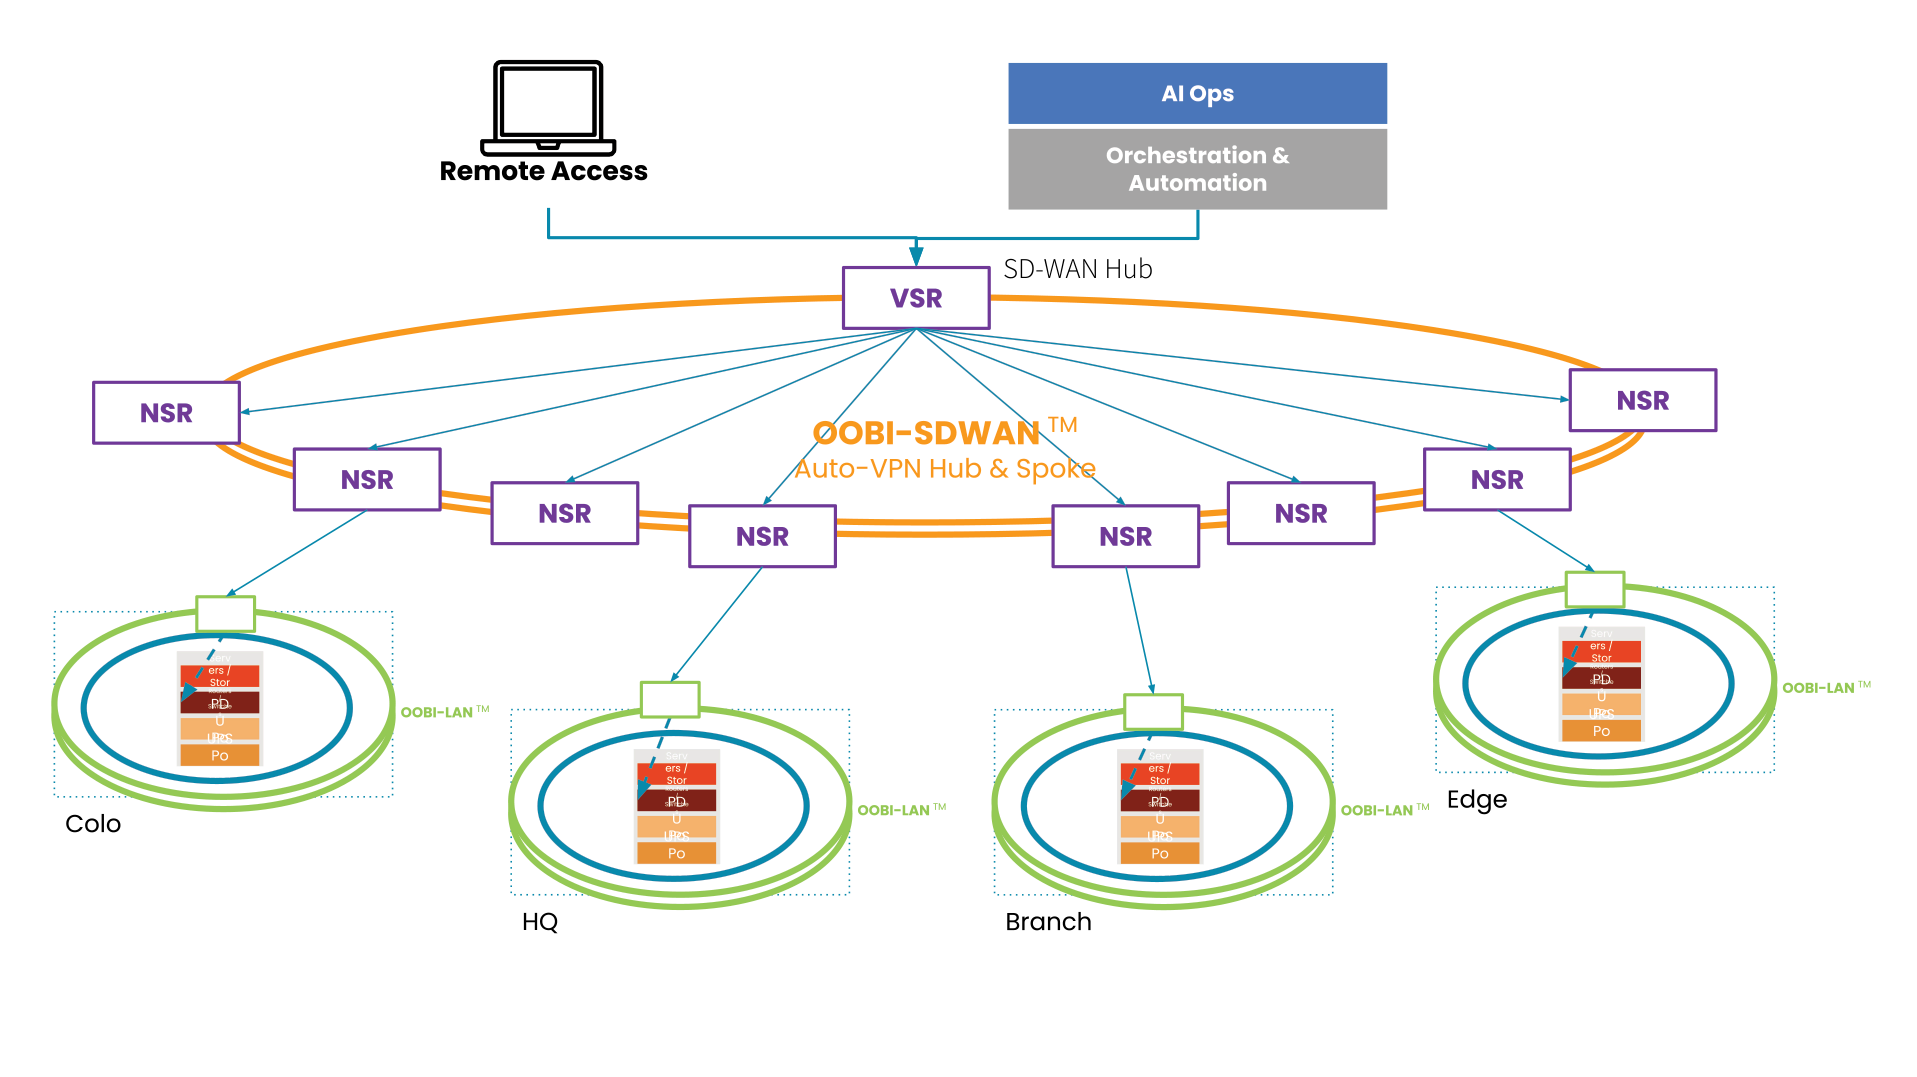
In this diagram, the production infrastructure (blue ring) sits at each distributed location. The out-of-band infrastructure for LAN (OOBI-LAN) is the green ring and surrounds the production infrastructure with one layer of isolated management. The OOBI-WAN (orange ring) is what provides a second layer of isolated management, which teams can access from a central or remote location, to gain access to the OOBI-LAN and ultimately the production infrastructure.

ZPE Automation

Knowing these assets and providing access across the organization can be easy and does not have to disrupt current operations. 

How can IMI stop the FIN11 ransomware attack?

In the ongoing FIN11 ransomware attack, Internet-facing applications are targets of the zero-day exploit. This means that no amount of security solutions can pre-mitigate the attack (i.e., there’s nothing you can do to stop it). This is where IMI shines.

Isolated Management Network diagram sitting beside production infrastructure

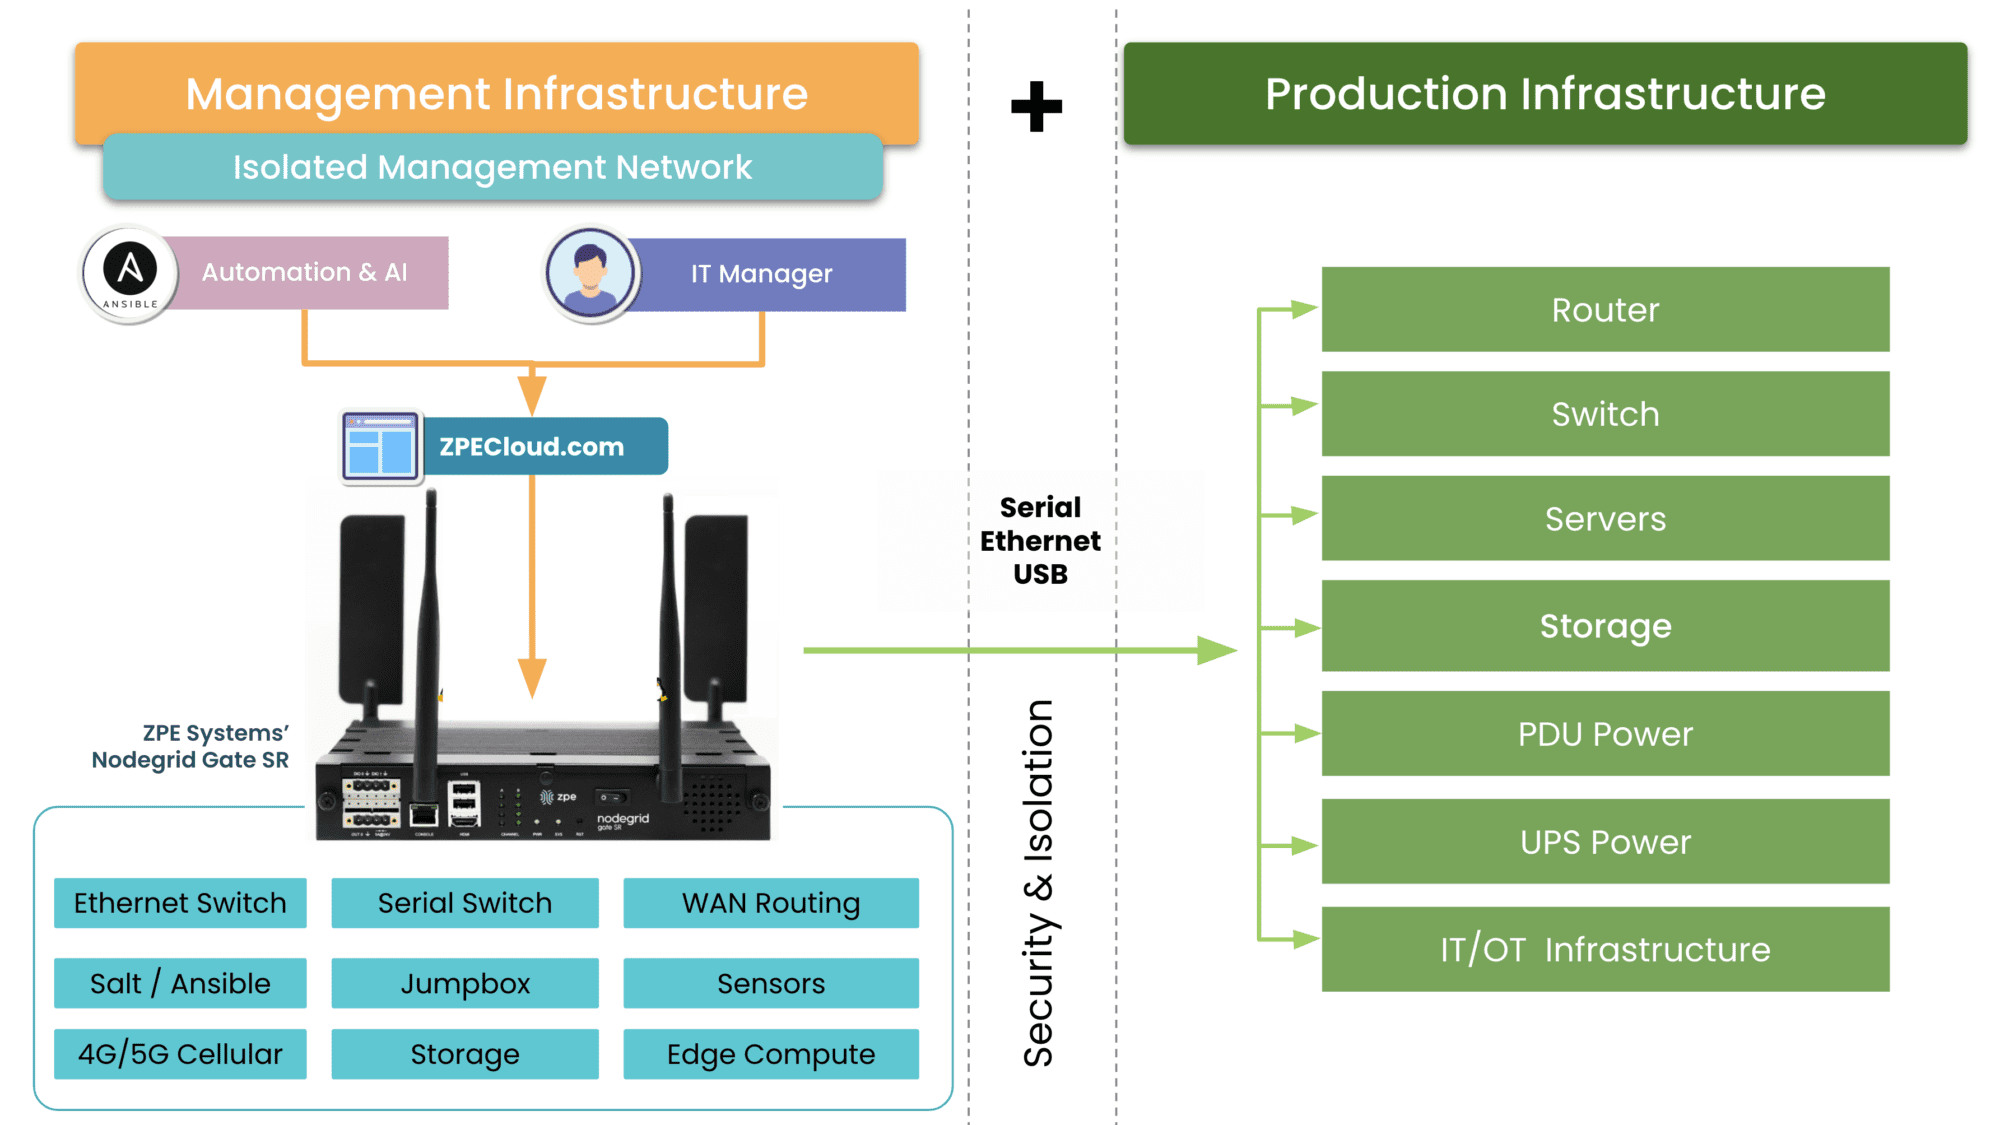
Remember the OOBI-LAN/OOBI-WAN diagram? Here’s a zoomed-in view of the isolated management infrastructure sitting beside the production infrastructure. The IMI connects via serial, Ethernet, and USB to production gear, and provides the necessary functions (routing, storing golden images, hosting jumpbox tools, etc.) to recover from attack. But how?

IT teams can use OOBI-WAN to remotely access their OOBI-LAN and production gear. They can pull affected devices offline and bring them in for forensics, which takes place in an Isolated Recovery Environment (IRE). This means these assets and networks are still reachable by analysts and responders, but isolated from other vulnerable assets. This allows an organization to quickly and even automatically deploy tools and resources inside of this environment through devices like ZPE Systems’ Nodegrid.

To combat the FIN11 attack, organizations don’t need to unplug cables or shut their devices off. They can instead deploy their IMI as the framework for closing the attack surface while maintaining access and critical data to aid in recovery.

Get the blueprint for isolated management infrastructure

Don’t wait until the next attack to shore up your defenses. ZPE Systems has worked with Big Tech for ten years developing the isolated management infrastructure. It’s now available inside the Network Automation Blueprint, and walks you through how to implement your own IMI. Download the blueprint now to stay ready for any attack.

Get in touch with me!

True security can only be achieved through resilience, and that’s my mission. If you want help shoring up your defenses, building an IMI, and implementing a Resilience System, get in touch with me. Here are links to my social media accounts:
SD-WAN ROI Calculator & Cost Reduction Strategies

sd-wan roi calculator

As an organization expands by adding new branches, its WAN also expands. The larger the WAN grows, the more network traffic needs to flow through MPLS (multi-protocol label switching) circuits, which have much more expensive bandwidth fees than traditional circuits. Some organizations improve their network performance by deploying security appliances at regional data centers, so they don’t need to backhaul traffic through the central firewall, but this only increases MPLS expenses and operating costs. Plus, spinning up each branch takes time, partly because of how long it takes to install a new MPLS circuit, which reduces agility and increases overhead costs.

SD-WAN, or software-defined wide area networking, abstracts WAN management to a separate control plane, streamlining workflows and allowing for a high degree of automation. SD-WAN makes it possible to leverage 5G and other networking technologies to reduce the reliance on MPLS circuits while still applying security policies and controls. With SD-WAN, you can lower your MPLS bandwidth costs, reduce the number of security appliances deployed around the enterprise, and deploy new branches faster.

In this post, we describe how SD-WAN decreases branch networking costs. We also explore strategies to reduce your expenses, providing an SD-WAN ROI calculator for a more personalized estimate of your potential savings.

How SD-WAN reduces branch networking costs


Reducing branch networking costs with SD-WAN

SD-WAN decreases MPLS bandwidth expenses by leveraging 5G and other available networks when possible.
An SD-WAN on-ramp to SASE means fewer security appliances deployed around the enterprise.
SD-WAN results in faster branch deployments by decreasing the reliance on new MPLS circuit installations.


Implementing SD-WAN can result in the following cost reduction benefits.

Decreased MPLS bandwidth expenses

In a traditional WAN architecture, MPLS circuits are installed at each branch to create a semi-private connection back to the primary enterprise network; this traffic isn’t encrypted, but it is partitioned from the public internet and other MPLS customers. MPLS networks are very reliable, but the bandwidth is significantly more expensive than public internet bandwidth. Finding ways to reduce the amount of traffic over MPLS circuits can reduce the ongoing operational costs of each branch.

SD-WAN leverages whatever networks are at its disposal—including MPLS, public ISPs, and 5G/4G cellular—to find the best and most efficient path for branch traffic. An organization can use SD-WAN software to prioritize specific kinds of traffic based on parameters such as the apps or resources being requested, so precious MPLS bandwidth is only used when needed. Many organizations are able to move away from MPLS completely by using SD-WAN. Providers are also required to build their SD-WAN fabric from encrypted tunnels, allowing SD-WAN to direct traffic over the public internet with less risk.

Cost reduction strategy: secure access service edge (SASE)

Even with SD-WAN’s encryption, branch traffic still needs to pass through a security appliance in the central data center so enterprise security policies and controls can be applied, which likely means using the MPLS anyway. Secure access service edge, or SASE, rolls up multiple enterprise security technologies (such as next-generation firewalls (NGFWs) and data loss prevention) into a single solution delivered as a service, which means organizations can deploy it to regional data centers or even the branches themselves. SD-WAN’s intelligent routing feature can determine when branch traffic is destined for cloud or web resources, then direct this traffic through the SASE stack instead of using the MPLS to reach the central firewall. SASE can help eliminate MPLS usage completely while reducing bottlenecks for greater cost savings.

With SD-WAN and SASE, your organization can reduce the ongoing monthly expense of MPLS bandwidth at each branch without sacrificing reliability or security.


Fewer security appliances

To ensure that branch traffic is as secure as the primary enterprise network, teams usually backhaul that traffic through the same central firewall for inspection and policy application. This creates a massive bottleneck that can slow the entire enterprise down, so some organizations choose to deploy security appliances at smaller regional data centers near their branch locations to distribute the load. However, that usually means additional MPLS circuits are provisioned at each data center, increasing startup and bandwidth costs. Plus, there are the hardware, software, and licensing costs for all the additional security appliances.

We’ve already mentioned how SD-WAN leverages alternative networks (as well as encrypted tunnels) to reduce MPLS bandwidth usage and how SASE applies enterprise security controls to branch traffic while bypassing firewalls entirely. These two benefits also result in cost savings from needing to purchase and license fewer security appliances. Since vendors deliver SASE as a service, it doesn’t necessarily require special hardware to run, and some providers even offer it as a managed cloud service, eliminating the hardware cost altogether.

Cost reduction strategy: vendor-neutral solutions

On-premises versions of SASE usually don’t need vendor-specific hardware so you can deploy the software on any available server as a VM. However, many branches lack the extra server storage or computer headroom needed for this kind of deployment. To ensure you can deploy SASE without buying additional resources, consider vendor-neutral branch networking solutions that can directly host and run third-party VMs. That means you can get gateway routing, switching, out-of-band serial console management, and SASE in a single device, consolidating the branch networking stack to reduce hardware expenses and management complexity.

With SD-WAN, SASE, and vendor-neutral solutions, you can streamline your branch deployments to reduce costs and increase efficiency.


Faster branch deployments

Generally speaking, the faster a company can deploy a new branch, the faster it will see a return on investment (ROI). However, getting a new MPLS circuit provisioned can take a long time—several months is typical—which can delay deployment timelines and increase overhead expenses while an organization sits on a non-productive branch.

SD-WAN makes it possible to leverage alternative network technologies to get a branch up and running before the MPLS circuit is ready. For example, SD-WAN can direct branch traffic across a 5G network even before the main fiber or cable connection is installed. When all of the branch circuits are provisioned, SD-WAN can seamlessly incorporate them into its routing policies based on preconfigured policies and automation triggers for a smooth deployment. In short, SD-WAN eliminates the organization’s reliance on MPLS for revenue generation, with branches that can be fully operational as soon as LTE or ISP links are set up.

Cost reduction strategy: zero touch provisioning (ZTP)

Another way to reduce branch spin-up times is with zero touch provisioning, or ZTP. ZTP uses software scripts to execute new device configurations over the network, reducing the need for pre-staging or manual, on-site programming. Typical branch deployments involve sending engineers on-site to manually copy and paste configuration files, which is time consuming and increases the risk of human error. With ZTP, unskilled on-site staff simply plug in new device cables and the configuration scripts are automatically retrieved and executed to fully build the environment without human touch. Plus, ZTP scripts are reusable, so you can use the same ones to deploy many different branches.

With SD-WAN and ZTP, your organization can reduce branch deployment delays and see a faster ROI from new branches.


SD-WAN ROI calculator

ZPE Systems provides vendor-neutral branch networking solutions that can directly host or integrate your choice of SD-WAN and SASE applications. ZPE’s platform also allows you to extend ZTP and other automation to every device in every branch on your network. Check out our SD-WAN ROI calculator for a customized estimate of how much money you can save by deploying SD-WAN on ZPE’s platform.

ZPE System’s Nodegrid solution combines branch networking, out-of-band management, and vendor-neutral orchestration into a single platform.

To learn more about using Nodegrid as your on-ramp to SD-WAN, or for help with the SD-WAN ROI calculator, contact ZPE Systems today

Contact Us

Opengear EOL: IM7200 Alternative Options

Opengear alternatives

The Opengear IM7200 is a line of out-of-band (OOB) serial consoles, also known as terminal servers, console servers, serial console servers, serial console routers, and serial console switches. The Infrastructure Manager (IM) solution provides consolidated remote management of data center infrastructure. The IM7200 is EOL as of the 31st of March, 2023, with an end-of-sale date of the 30th of September 2023 – click here to see a full list of affected product SKUs. In this blog, we’ll discuss replacement options for the IM7200, including Opengear alternatives that deliver unlimited automation capabilities and complete vendor freedom.


Table of contents:

Opengear IM7200 overview

The Opengear IM7200 is a line of serial console solutions that provide out-of-band (OOB) management for 8-48 devices. It’s designed to give administrators a dedicated control plane from which to access and manage remote infrastructure in data centers and large IT deployments.

With the IM7200 now EOL, Opengear recommends migrating to the OM2200 series. Let’s take a look at the features, specifications, and limitations of the Opengear OM2200 before discussing some alternative options.


Looking for replacement options for other discontinued serial consoles and branch routers? Try:

Opengear migration options: OM2200

The Opengear OM2200 Operations Manager console server solution provides OOB management for up to 48 devices over serial and/or Ethernet. OOB and failover use dual fiber ports, with an optional LTE-A Pro cellular module available. One of the OM2200’s biggest strengths is its power management capabilities, uniquely supporting over 100 power vendors’ equipment.

The OM series is Opengear’s line of NetOps console servers, which means they support Opengear’s automation modules as well as Python scripts and Docker container deployments. However, Zero Touch Provisioning (ZTP) and RESTful APIs are locked behind an upgraded version of Opengear’s Lighthouse software. In addition, the OM2200 is what’s known as a 2nd generation or “Gen 2” serial console, which means it isn’t vendor-neutral and can’t integrate or host third-party applications for automation or security.

Opengear OM2200 Features & Tech Specs

Notable Serial Console Features

• SSH direct to consoles

• Keystroke logging

• Alert on cable disconnects

• Text pattern match

• Multiple concurrent sessions

• Automatic device name discovery

OOB Managed Interfaces

• 16, 32, 48 ports

Hardware

• AMD X86, 64-bit CPU

• 8 GB DRAM

• 64 GB SSD

Automation

• Opengear NetOps modules

• Docker

• Python

• Perl and bash support

• Ruby

Automation for End Devices

• Can run playbooks

• Python

• Lighthouse

Guest OS

• Docker support

Power Management

• Monitor UPS battery status

• Automate routine maintenance and load testing

• Control PDU outlets via serial, USB, and Ethernet

• Enforce remote power permissions and map managed consoles to outlets

• Minimize MTTR with out-of-band power control

• Uniquely supports over 100 power vendors’ equipment

Hardware Security

• TPM 2.0

• Embedded firewall

Form Factor

Fixed 1RU


Opengear OM2200 limitations

The OM2200 is a good Gen 2 serial console switch that offers some major improvements over the IM7200, but it still falls short of delivering Gen 3 OOB console server functionality in the following ways.

  • Vendor lock-in: The X86 CPU and Linux-based OS makes the OM2200 programmable and extensible, but Opengear’s Lighthouse management software is not truly vendor-neutral. That means your third-party integration capabilities will be limited to specific supported solutions. If you have a hybrid, distributed, or multi-vendor infrastructure, this limitation could leave gaps in your management and orchestration coverage.
  • Limited automation: The OM2200 improves upon the 7200 by supporting Opengear NetOps modules and allowing scripting and ZTP within the Lighthouse Automation edition. However, this automation only extends to certain supported end-devices, which means you’ll either need to stay within Opengear’s ecosystem, or manually provision and deploy the rest of your infrastructure.
  • Lack of security: The OM2200 includes TPM 2.0 security, SAML 2.0 support, and an embedded firewall. However, it does not include additional hardware security like geofencing, BIOS protection, or UEFI secure boot. This increases the risk that a stolen serial console could be used by cybercriminals to breach your OOB management network.


Both the Opengear IM7200 and OM2200 are Gen 2 serial console servers, which means they provide OOB management access as well as some automation functionality to simplify individual network management workflows. However, due to vendor lock-in and minimal hardware security, the OM series falls short of the end-to-end automation and security required for a Gen 3 serial console solution.

Opengear alternative options from ZPE Systems

Another migration option for EOL Opengear console servers is the Nodegrid solution from ZPE Systems. This Gen 3 OOB management platform includes a wide range of serial console servers and integrated branch services routers to choose from, with the Nodegrid Serial Console Plus (NSCP), the Nodegrid Serial Console S Series, and the Noderid Net Services Router (NSR) serving as direct replacements for the IM7200.

Nodegrid Serial Console Plus (NSCP)

The high-density Nodegrid Serial Console Plus comes in 16, 32, 48, and 96 serial RJ45 port configurations as well as providing 2 USB 3.0 ports for a total of 98 managed devices on a single 1RU solution. That means a single NSCP could replace up to 12 Opengear IM7200 serial consoles, saving on hardware costs and optimizing rack space.

Nodegrid Serial Console S Series

The Nodegrid S series, which comes in 16, 32, or 48-port configurations, uses auto-sensing ports to provide seamless management of modern, legacy, and mixed-vendor infrastructure. The S Series RS232 serial console switch is the perfect legacy modernization platform because it allows you to extend automation to end devices that otherwise wouldn’t support it.

Nodegrid Net Services Router (NSR)

The Nodegrid Net Services Router (NSR) is an all-in-one branch networking solution that delivers OOB, SD-WAN, and more in a single box. The NSR has a modular design that lets you customize your solution with extra terminal server capabilities, storage, processing power, or GbE Ethernet ports.

All Nodegrid devices are secured with on-board features like BIOS protection, geofencing, TPM 2.0, and UEFI Secure Boot. An embedded firewall provides additional functionality like multi-site IPSec VPN, advanced authentication, and 2FA and SAML 2.0.

Nodegrid’s hardware can also directly host VMs, Docker containers, and third-party security and automation applications. Plus, the Linux-based Nodegrid OS supports NetOps automation and orchestration via integrations with tools like Docker, Chef, Puppet, and Ansible. In addition, ZPE’s management software, which is available as an on-premises or web-based solution, provides vendor-neutral visibility and orchestration of all your data center and cloud infrastructure behind one pane of glass.

Nodegrid features & tech specs


Nodegrid NSCP

Nodegrid S Series

Nodegrid NSR

Notable Serial Console Features

• SSH direct to consoles

• Keystroke logging

• Logging to ZPE Cloud, NFS, Local

• Alert on cable disconnects

• Text pattern match with scriptable actions

• Multiple concurrent sessions

• Automatic device name discovery

• Session sharing for collaboration

• IP address per serial port

• Secure session logout enforcement

• Power control hotkey on serial port

• Configurable icon per serial port

OOB Managed Interfaces

• 16, 32, 48, 96 ports (1RU)

• 16, 32, 48 ports

• Up to 5 x 16-port RJ-45 Serial modules

Hardware

• Intel X86, 64-bit CPU optimized for running VMs and automation tools

• Dual-SIM 5G/4G/LTE, Wi-Fi, and V.02 modem for OOB/Failover

• Intel X86, 64-bit CPU optimized for running VMs and automation tools

• Dual-SIM 5G/4G/LTE, Wi-Fi, and V.02 modem for OOB/Failover

• Intel X86, 64-bit CPU optimized for running VMs and automation tools

• Dual-SIM 5G/4G/LTE, Wi-Fi, and V.02 modem for OOB/Failover

Automation

• ZPE Cloud

• Chef

• Docker

• Puppet

• Python

• Ruby

• ShellScript

• Node.js JavaScript

• Red Hat Ansible

• KVM Hypervisor

• ZPE Cloud

• Chef

• Docker

• Puppet

• Python

• Ruby

• ShellScript

• Node.js JavaScript

• Red Hat Ansible

• KVM Hypervisor

• ZPE Cloud

• Chef

• Docker

• Puppet

• Python

• Ruby

• ShellScript

• Node.js JavaScript

• Red Hat Ansible

• KVM Hypervisor

Automation for End Devices

• ZPE Cloud

• Chef

• Docker

• Puppet

• Python

• Ruby

• ShellScript

• Node.js JavaScript

• Red Hat Ansible

• KVM Hypervisor

• ZPE Cloud

• Chef

• Docker

• Puppet

• Python

• Ruby

• ShellScript

• Node.js JavaScript

• Red Hat Ansible

• KVM Hypervisor

• ZPE Cloud

• Chef

• Docker

• Puppet

• Python

• Ruby

• ShellScript

• Node.js JavaScript

• Red Hat Ansible

• KVM Hypervisor

Guest OS

• VMs, Docker, Kubernetes, LXC

• VMs, Docker, Kubernetes, LXC

• VMs, Docker, Kubernetes, LXC

Power Management

• Supports major power strips manufacturers

• Power management integrated with serial session (escape sequence in the serial session or power buttons in web serial session)

• Power control of VMs

• Access rights for users & user groups

• Supports major power strips manufacturers

• Power management integrated with serial session (escape sequence in the serial session or power buttons in web serial session)

• Power control of VMs

• Access rights for users & user groups

• Supports major power strips manufacturers

• Power management integrated with serial session (escape sequence in the serial session or power buttons in web serial session)

• Power control of VMs

• Access rights for users & user groups

Hardware Security

• TPM 2.0

• Encrypted solid-state disk

• UEFI BIOS with protection

• Secure Boot (signed OS

• Geofencing

• TPM 2.0

• Encrypted solid-state disk

• UEFI BIOS with protection

• Secure Boot (signed OS

• Geofencing

• TPM 2.0

• Encrypted solid-state disk

• UEFI BIOS with protection

• Secure Boot (signed OS

• Geofencing

Form Factor

Fixed 1RU

Fixed 1RU

Modular 1RU

The Nodegrid Gen 3 serial console solution is an Opengear alternative that serves as a direct replacement for the IM7200 while delivering enhanced automation capabilities and complete vendor freedom.

Watch a free Nodegrid demo to see a Gen 3 console server solution in action.

Watch the Video

Opengear IM7200 migration SKUs:

Opengear IM7200 EOL SKU

In Scope Features

ZPE Replacement Product

IM7208-2-DAC

IM7208-2-DDC

8 Serial ports, OOB management

Fixed Form Factor:

ZPE-NSCP-T16R-STND-DAC

ZPE-NSC-T16S-STND-DAC

ZPE-NSCP-T16R-STND-DDC

ZPE-NSC-T16S-STND-DDC


Modular Form Factor:

ZPE-NSR-816-DAC with 1 x 16 port serial module 1 x ZPE-NSR-16SRL-EXPN

ZPE-NSR-816-DDC with 1 x 16 port serial module 1 x ZPE-NSR-16SRL-EXPN

IM7216-2-DAC

IM7216-2-DDC

16 Serial ports, OOB management

Fixed Form Factor:

ZPE-NSCP-T16R-STND-DAC

ZPE-NSC-T16S-STND-DAC

ZPE-NSCP-T16R-STND-DDC

ZPE-NSC-T16S-STND-DDC


Modular Form Factor:

ZPE-NSR-816-DAC with 1 x 16 port serial module 1 x ZPE-NSR-16SRL-EXPN

ZPE-NSR-816-DDC with 1 x 16 port serial module 1 x ZPE-NSR-16SRL-EXPN

IM7232-2-DAC

IM7232-2-DDC

32 Serial ports, OOB management

Fixed Form Factor:

ZPE-NSCP-T32R-STND-DAC

ZPE-NSC-T32S-STND-DAC

ZPE-NSCP-T32R-STND-DDC

ZPE-NSC-T32S-STND-DDC


Modular Form Factor:

ZPE-NSR-816-DAC with 2 x 16 port serial module 2 x ZPE-NSR-16SRL-EXPN

ZPE-NSR-816-DDC with 2 x 16 port serial module 2 x ZPE-NSR-16SRL-EXPN

IM7248-2-DAC

IM7248-2-DDC

48 Serial ports, OOB management

Fixed Form Factor:

ZPE-NSCP-T48R-STND-DAC

ZPE-NSC-T48S-STND-DAC

ZPE-NSCP-T48R-STND-DDC

ZPE-NSC-T48S-STND-DDC


Modular Form Factor:

ZPE-NSR-816-DAC with 3 x 16 port serial module 3 x ZPE-NSR-16SRL-EXPN

ZPE-NSR-816-DDC with 3 x 16 port serial module 3 x ZPE-NSR-16SRL-EXPN

96 port not available in IM or OM series

96 Serial ports, OOB management

ZPE-NSCP-T96R-STND-DAC

ZPE-NSCP-T96R-STND-DDC

Ready to replace your EOL Opengear IM7200 with a Gen 3 out-of-band serial console solution?

Call ZPE Systems today at 1-844-4ZPE-SYS for a special trade-in promotion.

Contact Us