Providing Out-of-Band Connectivity to Mission-Critical IT Resources

DORA Act: 5 Takeaways For The Financial Sector
Thumbnail – DORA Act 5 Takeaways for the Financial Sector

The Digital Operational Resilience Act (DORA) is a regulatory initiative within the European Union that aims to enhance the operational resilience of the financial sector. Its main goal is to prevent and mitigate cyber threats and operational disruptions. The DORA Act outlines regulatory requirements for the security of network and information systems “whereby all firms need to make sure they can withstand, respond to and recover from all types of ICT-related disruptions and threats” (DORA Act website).

Who and What Are Covered Under the DORA Act?

The DORA Act is a regulation that covers all financial entities within the European Union (EU). It recognizes the critical role of information and communication technology (ICT) systems in financial services. DORA applies to financial services including payments, securities, credit rating, algorithmic trading, lending, insurance, and back-office operations. It establishes a framework for ICT risk management through technical standards, which are being released in two phases, the first of which was published on January 17, 2024. The DORA Act will go into effect in its entirety on January 17, 2025.

With cyberattacks constantly in the news cycle, it’s no surprise that governing bodies are putting forth standards for operational resilience. But without combing through this lengthy piece of legislation, what should IT teams start thinking about from a practical standpoint? Here are 5 takeaways on what the DORA Act means for the financial sector.

DORA Act: 5 Takeaways for the Financial Sector

1. Shore-up your cybersecurity measures

The DORA Act emphasizes strengthening cybersecurity measures within the financial sector. It requires financial institutions, such as banks, stock exchanges, and financial infrastructure providers, to implement robust cybersecurity controls and protocols. These include adopting advanced authentication mechanisms, encryption standards, and network segmentation to protect sensitive financial data and critical infrastructure from cyber threats. Part of this will also require organizations to apply system patches and updates in a timely manner, which means automated patching will become necessary to every organization’s security posture.

2. Implement resilience systems

Operational resilience is a key focus area of the DORA Act, aiming to ensure the continuity of essential financial services in the face of cyber threats, natural disasters, and other operational disruptions. Financial institutions are required to develop comprehensive business continuity plans, establish redundant systems and backup facilities, and conduct regular stress tests to assess their ability to withstand and recover from various scenarios. Implementing a resilience system helps with this, as it provides all the infrastructure, tools, and services necessary to continue operating during major incidents.

3. Conduct regular scans for vulnerabilities

The DORA Act mandates financial institutions to implement robust risk management practices to identify, assess, and mitigate cyber risks and operational vulnerabilities. This includes conducting regular assessments, vulnerability scans, and penetration tests, and developing incident response procedures to quickly address threats. This is all part of taking a proactive approach to identify and mitigate cyber incidents, and reduce the impact that adverse events have on financial stability and consumer confidence.

4. Collaborate and share information with industry peers

The DORA Act encourages financial institutions to share cybersecurity threat intelligence, incident data, and best practices with industry peers, regulators, and law enforcement agencies. The ability to monitor systems and collect data will be crucial to this approach, and will require systems that can rapidly (and securely) deploy apps/services during ongoing incidents. This will help financial institutions to better understand emerging threats, coordinate responses to cyber incidents, and strengthen collective defenses against threats and operational disruptions.

5. Segment physical and logical systems to pass regular audits

Through the DORA Act, regulators are empowered to conduct regular assessments, audits, and inspections of systems. This will ensure that financial institutions are implementing adequate controls and safeguards to protect against cyber threats and operational disruptions. A crucial part to this will involve physical and logical separation of systems, such as through Isolated Management Infrastructure, as well as implementing zero trust architecture across the organization. These will help bolster resilience by eliminating control dependencies between management and production networks, which will also help to streamline audits.

Get the blueprint to help you comply with the DORA Act

DORA’s requirements are meant to help IT teams better protect sensitive data and the integrity of financial systems as a whole. But without a proper network management infrastructure, their production networks are too sensitive to errors and vulnerable to attacks. ZPE has created the blueprint that covers these 5 crucial takeaways outlined in the DORA Act. The architecture outlined in this blueprint has been trusted by Big Tech for more than a decade, as it allows them to deploy modern cybersecurity measures, physically and logically separated systems, and rapid recovery processes. Download the blueprint now.
What to do if You’re Ransomware’d: A Healthcare Example

What to do if youre ransomwared

This article was written by James Cabe, CISSP, a 30-year cybersecurity expert who’s helped major companies including Microsoft and Fortinet.

Ransomware gangs target the innocent and vulnerable. They hit a Chicago hospital in December 2023, a London hospital in October the same year, and schools and hospitals in New Jersey as recently as January 2024. This is one of the biggest reasons I’m committed to stopping these criminals by educating organizations on how to re-think and re-architect their approach to cybersecurity.

In previous articles, I discussed IMI (Isolated Management Infrastructure) and IRE (Isolated Recovery Environments), and how they could have quickly altered outcomes for MGM, Ragnar Locker victims, and organizations affected by the MOVEit vulnerability. Using IMI and IRE, organizations find that the key to not only speedy recovery, but also to limiting the blast radius and attack persistence, is isolation.

Why is isolation (not segmentation) key to ransomware recovery?

The NIST framework for incident response has five steps: Identify, Protect, Detect, Respond, and Recover. It’s missing a crucial step, however: Isolate. Stay tuned for a full breakdown of this in my next article. But the reason this is so critical is because attacks move at machine speed, and are very pervasive and persistent. If your management network is not fully isolated from production assets, the infection spreads to everything. Suddenly, you’re locked out completely and looking at months of tedious recovery. For healthcare providers, this jeopardizes everything from patient care to regulatory compliance.

Isolation is integral to building a resilience system, or in other words, a system that gives you more than basic serial console/out-of-band access and instead provides an entire infrastructure dedicated to keeping you in control of your systems — be it during a ransomware attack, ISP outage, natural disaster, etc. Because this infrastructure is physically and virtually isolated from production (no dependencies on production switches/routers, no open management ports, etc.), it’s nearly impossible for attackers to lock you out.

So, what really should you do if you’re ransomware’d? Let’s walk through an example attack on a healthcare system, and compare the traditional DR (Disaster Recovery) response to the IMI/IRE approach.

Ransomware in Healthcare: Disaster Recovery vs Isolated Recovery

Suppose you’re in charge of a hospital’s network. MDIoT, patient databases, and DICOM storage are the crown jewels of your infrastructure. Suddenly, you discover ransomware has encrypted patient records and is likely spreading quickly to other crown jewel assets. The risks and potential fallout can’t be understated. Millions of people are depending on you to protect their sensitive info, while the hospital is depending on you to help them avoid regulatory/legal penalties and ensure they can continue operating.

The problem with Disaster Recovery

Though the word ‘recovery’ is in the name, the DR approach is limited in its capacity to recover systems during an attack. Disaster Recovery typically employs a couple things:

  • Backups, which are copies of data, configurations, and code that are used to restore a production system when it fails.
  • Redundancy, which involves duplicating critical systems, services, and applications as a failsafe in the event that primaries go down (think cellular failover devices, secondary firewalls, etc.).

What happens when you activate your DR processes? It’s highly likely that you won’t be able to, and that’s because the typical DR setup relies on the production network. There’s no isolation.

Think about it this way: your backup servers need direct access to the data they’re backing up. If your file servers get pwned, your backup servers will, too. If your primary firewall gets hacked, your secondary will, too. The problem with backup and redundancy systems — and any system, for that matter — is that when they depend on the underlying infrastructure to remain operational, they’re just as susceptible to outages and attacks. It’s like having a reserve parachute that depends on the main parachute.

And what about the rest of your systems? You just discovered the attack has encrypted your servers and is quickly bringing operations to a crawl. How are you going to get in and fight back? What if you try to log into your management network, only to find that you’re locked out? All of your tools, configurations, and capabilities have been compromised.

This is why CISA, the FBI, US Navy, and other agencies recommend implementing Isolated Management Infrastructure.

IMI and IRE guarantee you can fight back against ransomware

You discover that the ransomware has spread. Not only has it encrypted data and stopped operations, but it has also locked you out of your own management network and is affecting the software configurations throughout the hospital. This is where IMI (Isolated Management Infrastructure) and IRE (Isolated Recovery Environment) come in.

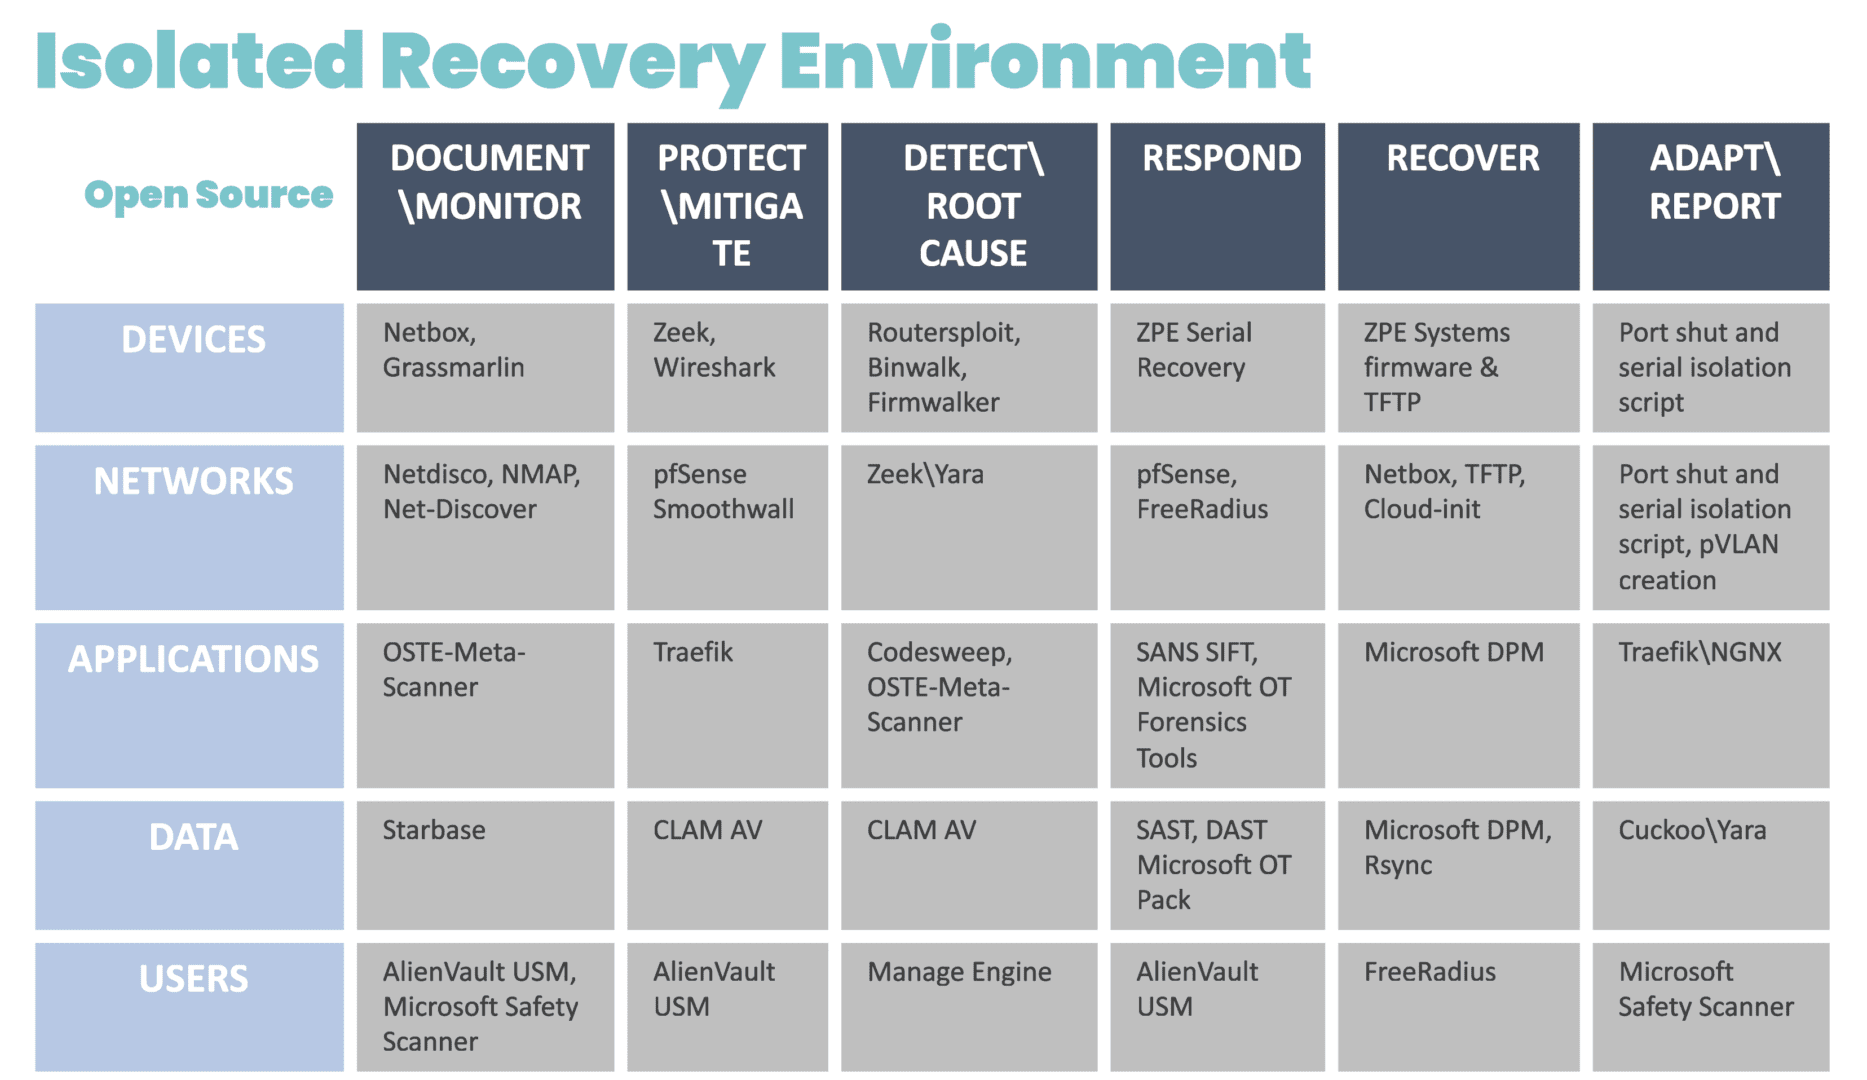
Because IMI is physically separate from affected systems, it guarantees management access so teams can set up communication and a temporary ‘war room’ for incident response. The IRE can then be created using a combination of cellular, compute, connectivity, and power control (see diagram for design and steps). Docker containers should be used to bring up each step.

Diagram showing a chart containing the systems and open-source tools that can be deployed for an Isolated Recovery Environment

Image: The infrastructure and incident response protocol involved in the Isolated Recovery Environment. These products were chosen from free or open source projects that have proven to be very useful in each of these stages of recovery. These can be automated in pieces for each phase, and then be brought down via Docker container to eliminate the risk of leakage or risk during each phase.

Without diving too far into the technicalities, the IRE enables you to recover survivable data, restore software configurations, and prevent reinfection. Here are some things you can do (and should do) in this scenario, courtesy of the IRE:

Establish your war room

You can’t fight ransomware if you can’t securely communicate with your team. Use the IRE to create offline, break-the-glass accounts that are not attached to email. This allows you to communicate and set up ticketing for forensics purposes.

Isolate affected systems

There’s no use running antivirus if reinfection can occur. Use the IRE to take offline the switch that connects the backup and file servers. Isolate these servers from each other and shut down direct backup ports. Then, you can remote-in (KVM, iKVM, iDRAC) to run antivirus and EDR (Endpoint Detection and Response).

Restore data and device images

The key is to have backup data at its most current, both for patient data and device/software configurations. Because the IRE provides an isolated environment, and you’ve already pulled your backups offline, you can gradually restore data, re-image devices, and restore configurations without risking reinfection. The IRE ensures devices “keep away” from each other until they can be cleansed and recovered.

Things You’ll Need To Build The IMI and IRE

Network Automation Blueprint

We’ve created a comprehensive blueprint that shows how to implement the architecture for IMI and IRE. Don’t let the name fool you. The Network Automation Blueprint covers everything from establishing a dedicated management network, to automating deployment of services for ransomware recovery. Get your PDF copy now at the link below.

Gen 3 Console Servers To Replace End-of-Life Gear

It’s nearly impossible to build the IMI or deploy the IRE using older console servers. That’s because these only give you basic remote access and a hint of automation capabilities. You’ll still need the ability to run VMs and containers. Gen 3 console servers let you do all of the things for IMI and IRE, like full control plane/data plane separation, hosting apps, and deploying VMs/containers on-demand. They’ve also been validated by Synopsys and have built-in security features I’ve been talking about for years. Check out the link below for resources about Gen 3 and how we’ll help you upgrade.

Get in touch with me!

I’d love to talk with you about IMI, IRE, and resilience systems. These are becoming more crucial to operational resilience and ransomware recovery, and countries are passing new regulations that will require these approaches. Get in touch with me via social media to talk about this!

Zero Trust Security Benefits

A 3D illustration of the words Zero Trust

Network security has become more challenging for companies whose employees, devices, and applications no longer reside within one easily defended perimeter. Additionally, cyber attacks like ransomware constantly threaten networks, forcing organizations to operate under the assumption that systems are already breached.

Zero trust security is a methodology that helps companies limit the blast radius of an attack to prevent the exfiltration of sensitive and valuable data. Zero trust assumes that every user, device, and application is unsafe until proven otherwise, following the principle of “never trust, always verify.” This guide discusses how zero trust security benefits organizations by increasing network visibility, reducing the scope of cyber attacks, and providing precise security coverage.

Zero trust security benefits

The Top 3 Zero Trust Security Benefits

Improves Network Control

Zero trust visibility tools improve network control and efficiency by enabling preventative maintenance, faster incident response, and automation.

Reduces Attack Radius

Zero trust security limits the lateral movement of attackers on the network to reduce the duration of and damage caused by successful breaches.

Provides Precise Security Coverage

Zero trust uses highly specific security policies and controls, ensuring the best possible protection for each resource without any coverage gaps.

1. Improves network control

Implementing zero trust security requires knowing exactly what devices, users, applications, and services access the network, where they reside, and their potential vulnerabilities. Additionally, you must monitor all traffic on the network to identify unusual activity that could indicate compromise, and react to potential breaches. Zero trust teams deploy tools such as SIEM (security information and event management) and inventory discovery and assessment solutions to achieve this level of granular visibility.

While these tools are necessary to implement zero trust, the visibility they provide has side benefits that improve network management control and efficiency. Having insight into the health status of every network resource enables preventative maintenance and speedy responses to issues that could affect performance or availability if left unchecked. Many zero-trust solutions also use automation tools, such as automatic device/app discovery or AI threat detection, to cut back on the time your administrators spend on tedious, day-to-day management and monitoring tasks.

2. Reduces attack radius

Many traditional cybersecurity methodologies focus almost entirely on prevention, but once an attacker breaches the network, teams lack the tools to find or stop them. Zero trust security assumes a breach is already occurring. It provides the tools and techniques needed to stop it, reducing the attack radius and limiting the damage caused to your organization.

Zero trust uses network micro-segmentation and precise security policies to create perimeters around individual resources, requiring users to continuously prove their identity and “trustworthiness” as they move around the network. Each checkpoint provides another opportunity for multi-factor authentication (MFA) or security monitoring tools to catch and lock out the account.

Zero trust security reduces the duration of attacks, which limits data exfiltration, downtime, and other business impacts.

3. Provides precise security coverage

Traditional security models create one large perimeter of controls and policies that must address every potential vulnerability on the network. This approach leads to a bloated patchwork of appliances and solutions that may not cover all bases, leaving gaps in your security that could expose critical vulnerabilities.

Conversely, zero trust security creates micro-perimeters around individual resources, allowing you to implement the exact policies and controls required to protect each component. Tools like next-generation firewalls (NGFWs) enable teams to micro-segment the network, create micro-perimeters, and enforce access controls. Zero trust identity and access management (IAM) solutions also provide a centralized place to create, deploy, manage, and monitor highly specific security policies to protect individual resources.

Zero trust security shrinks your perimeter to smaller network segments, allowing teams to apply the best security policies and controls to protect each micro-perimeter. As a result, you don’t have to worry about any weak points or gaps in your network security.

How to take advantage of zero trust security benefits

Zero trust security benefits organizations by increasing their overall network visibility, reducing the scope and impact of attacks, and enabling more precise security controls and access policies.

One important thing to consider is that you must apply zero trust to both production network resources and management interfaces on the control plane. The best practice is to move management interfaces to an isolated, out-of-band (OOB) network using Nodegrid OOB devices to help create an isolated management infrastructure (IMI) that’s micro-segmented with zero trust policies and controls. A zero-trust IMI prevents attackers from jumping from production resources to the control plane for “crown jewels” infrastructure, significantly improving your security posture.

Isolated Management Infrastructure

Additionally, achieving zero trust is easier with an open, flexible, vendor-neutral platform that integrates all your tools, features, and controls into one simplified interface. For example, the Nodegrid platform from ZPE Systems serves as a single security gateway with seamless integrations with third-party services like Okta and Palo Alto Panorama. Nodegrid allows you to take advantage of zero trust security benefits with a customized solution that supports your organization’s unique goals and requirements.

Want to learn more about how to simplify zero trust security with Nodegrid?

ZPE Systems can help your company realize these zero trust security benefits with our secure out-of-band management solutions and vendor-neutral platform. Schedule a free Nodegrid demo to learn more.

Watch Demo

Network Resilience: What is a Resilience System?

A digital web of interconnected network resilience concepts being selected by a business person in a suit.

Network resilience means being able to withstand or recover from adversity, service degradation, and complete outages with minimal business disruption. The longer business-critical services are down, or systems are breached, the greater the risk of significant financial, reputational, and legal consequences. A resilience system is a set of technologies that enable an organization to continue operating while teams work to repair failures and recover from cyberattacks. But what exactly is a resilience system, and what does it look like? This guide to network resilience defines resilience systems, provides example use cases, compares them to related technologies like backups and redundant systems, and describes the key components required to build them.

What is a resilience system?

A resilience system provides all the infrastructure, tools, and services necessary to continue operating, if in a degraded state, during major incidents. It also includes everything needed to recover data, rebuild systems, perform security testing, and continue delivering core business functionality. A resilience system is typically isolated from the production network, preventing cybercriminals from finding and compromising it and ensuring teams have continuous access even if the primary network goes down.

Resilience system use cases

Some examples of the challenges that resilience systems help overcome include:

1. Ransomware recovery

In a ransomware attack, cybercriminals infect systems with malware that spreads throughout the network and encrypts any data it encounters. Modern ransomware now uses packaged attacks that move at machine speed, instantly incapacitating entire networks. Organizations completely lose access to critical systems and data until they pay a ransom, often in untraceable cryptocurrency. Ransomware is an exceptionally tenacious form of malware and tends to reinfect backup data and rebuilt systems, significantly hampering recovery efforts and increasing the duration and cost of the attack. The best practice for resilience systems is to isolate them on an out-of-band (OOB) network, inaccessible to hackers who have breached the production in-band network. Doing so creates a safe, isolated recovery environment (IRE) where teams can restore critical data and systems without the risk of reinfection. The resilience system includes all the tools and hardware needed to restore critical business services and infrastructure. An IRE significantly accelerates ransomware recovery and minimizes downtime, so businesses can avoid paying ransoms and reduce the overall cost of attacks.

2. Network outages

Enterprise network architectures and supply chains are highly complex, with lots of moving parts that rely on external vendors to maintain availability. Just one of those vendors dropping the ball could take the entire organization offline, severely impacting network resilience. For example, in 2023, an expired cryptographic certificate caused Cisco’s Viptela SD-WAN appliances to fail on reboot, completely taking down affected networks until the issue was resolved. With a resilience system, Viptela customers could have potentially avoided this downtime by failing over to alternative network resources. For example, a resilience system with integrated cellular failover allows branches to continue connecting to and delivering critical business services while also providing a lifeline for remote teams to access and recover failed systems. A resilience system also provides observability and automatic notifications so teams are instantly alerted to issues like certificate expirations and can respond quickly to recover critical services.

3. Shift to remote work

Incidents like ransomware attacks and equipment failures happen frequently enough that companies can create detailed plans and proactively implement solutions to minimize their impact, but not all adverse events are so predictable. When the COVID-19 pandemic struck, the massive shift to remote work strained the network resources of most organizations. Instead of maintaining a limited number of branch offices, teams suddenly had to treat every employee as a new branch, leading to performance degradation and outages as they scrambled to reinforce the business’s remote capabilities. A resilience system gives teams the tools and resources they need to provision additional infrastructure, manage networking logic, deploy new security solutions, and more, even while the primary network is offline or under a heavy load. A resilience system is the key to quickly adjusting network performance and security to adapt to sudden changes like a transition to fully remote operations.

Do backups and redundancy equate to network resilience?

The short answer is no; backups and redundancy do not equate to network resilience, though they do contribute to making systems more resilient.

  • Backups are copies of data, configurations, and application code used to do a hot or cold restore when a production system fails. The underlying infrastructure must remain operational for teams to access and use backups, and unless additional resilience measures are taken, it’s easy for backups to become infected or compromised, severely hampering recovery efforts.
  • Redundancy involves duplicating critical systems, services, and applications as a failsafe in case the primaries go down. Organizations can “fail over” to the redundancies to continue critical business operations during outages. However, redundant systems are just as susceptible to failures and infections without additional resilience measures like out-of-band management and isolated management infrastructure.

Backups and redundancy are part of network resilience but alone are not enough to ensure business continuity. Resilience systems focus on maintaining the architecture of the production network while adding the ability to recover or adapt to adversity. The next section discusses all the tools and technologies that make up network resilience systems.

What does a resilience system look like?

There are four key components that go into a resilience system.

Key Components of a Resilience System

Alternative Networking

Full-stack routing and switching, Wi-Fi, VoIP, virtualization, software-defined network overlays for SDN & SD-WAN

Alternative Compute

Full-stack compute, containers, virtual machines, and any other resources needed to run applications and deliver services

Storage & Storage Recovery

Enough storage to recover systems and applications as well as support content delivery

Automation

Tools like zero-touch provisioning (ZTP) to facilitate speedy recovery while minimizing human error

Alternative networking and compute resources ensure the organization can failover in the event of a network failure or continue delivering services when production servers are unavailable. Teams also need enough storage to restore backup data, build new systems, and support the content delivery network (CDN). Automation solutions like zero-touch provisioning (ZTP), configuration management, and security validation tools accelerate the recovery process while mitigating the risk of human error. Combined, these components enable teams to reduce the frequency, severity, and duration of outages, improving overall network resilience.

Network resilience with ZPE Systems

A resilient network will continue delivering critical business services in the face of any challenge, whether from cybercriminals, supply chain issues, global events, or even plain human error. A resilience system is isolated from the production network to ensure security and availability, and it consists of all the tools and technologies needed to troubleshoot, recover, and deliver your most crucial data, applications, and infrastructure. The Nodegrid platform from ZPE Systems is the perfect foundation for a resilience system. Nodegrid is a vendor-neutral, out-of-band management solution capable of running your choice of third-party software. Nodegrid allows you to build a highly customizable IRE containing all the tools needed to safely recover from ransomware. You can even use Nodegrid to deliver services while the primary network or systems are down, making it your all-in-one network resilience multi-tool.

Want to ensure network resilience by accelerating ransomware recovery?

Minimize the business impact of ransomware with the help of our whitepaper, 3 Steps to Ransomware Recovery. Learn how to follow Gartner’s best practices to build an Isolated Recovery Environment

Download Whitepaper

Network Resilience Doesn’t Mean What it Did 20 Years Ago

Network resilience requirements have changed

Enterprise networks are like air. When they’re running smoothly, it’s easy to take them for granted, as business users and customers are able to go about their normal activities. But when customer service reps are suddenly cut off from their ticketing system, or family movie night turns into a game of “Is it my router, or the network?”, everyone notices. This is why network resilience is critical.

But, what exactly does resilience mean today? Let’s find out by looking at some recent real-world examples, the history of network architectures, and why network resilience doesn’t mean what it did 20 years ago.

Why does network resilience matter?

There’s no shortage of real-world examples showing why network resilience matters. The takeaway is that network resilience is directly tied to business, which means that it impacts revenue, costs, and risks. Here is a brief list of resilience-related incidents that occurred in 2023 alone:

  • FAA (Federal Aviation Administration) – An overworked contractor unintentionally deleted files, which delayed flights nationwide for an entire day.
  • Southwest Airlines – A firewall configuration change caused 16,000 flight cancellations and cost the company about $1 billion.
  • MOVEit FTP exploit – Thousands of global organizations fell victim to a MOVEit vulnerability, which allowed attackers to steal personal data for millions.
  • MGM Resorts – A human exploit and lack of recovery systems let an attack persist for weeks, causing millions in losses per day.
  • Ragnar Locker attacks – Several large organizations were locked out of IT systems for days, which slowed or halted customer operations worldwide.

What does network resilience mean?

Based on the examples above, it might seem that network resilience could mean different things. It might mean having backups of golden configs that you could easily restore in case of a mistake. It might mean beefing up your security and/or replacing outdated systems. It might mean having recovery processes in place.

So, which is it?

The answer is, it’s all of these and more.

Donald Firesmith (Carnegie Mellon) defines resilience this way: “A system is resilient if it continues to carry out its mission in the face of adversity (i.e., if it provides required capabilities despite excessive stresses that can cause disruptions).”

Network resilience means having a network that continues to serve its essential functions despite adversity. Adversity can stem from human error, system outages, cyberattacks, and even natural disasters that threaten to degrade or completely halt normal network operations. Achieving network resilience requires the ability to quickly address issues ranging from device failures and misconfigurations, to full-blown ISP outages and ransomware attacks.

The problem is, this is now much more difficult than it used to be.

How did network resilience become so complicated?

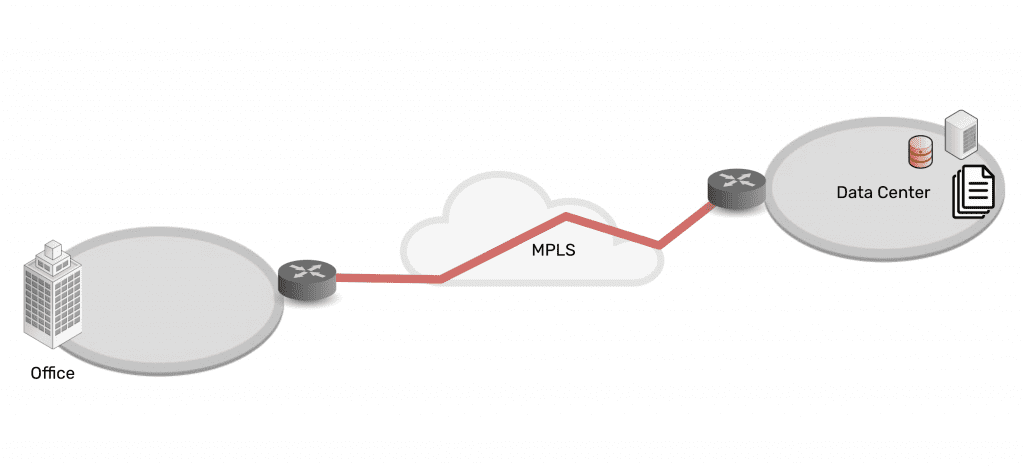
Twenty years ago, IT teams managed a centralized architecture. The data center was able to serve end-users and customers with the minimal services they needed. Being “constantly connected” wasn’t a concern for most people. For the business, achieving resilience was as simple as going on-site or remoting-in via serial console to fix issues at the data center.

Network architecture showing simplicity of data center connected via MPLS to branch office

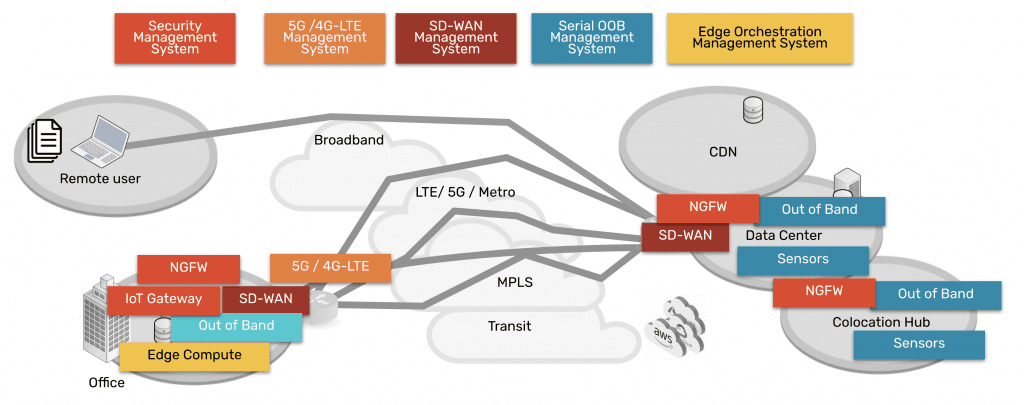
Then in the mid-2000s, the advent of the cloud changed everything. Infrastructure, data, and computing became decentralized into a distributed mix of on-prem and cloud solutions. Users could connect from anywhere, and on-demand services allowed people to be plugged in around-the-clock. Services for work, school, and entertainment could be delivered anytime, no matter where users were.

Network architecture showing complexity of data center, CDN, remote user, branch office, all connected via many paths

Behind the scenes, this explosion of architecture created three problems for achieving network resilience, which a simple serial could no longer fix:

Too Much Work

Infrastructure, data, and computing are widely distributed. Systems inevitably break and require work, but teams don’t have the staff to keep up.

Too Much Complexity

Pairing cloud and box-based stacks creates complex networks. Teams leave systems outdated, because they don’t want to break this delicate architecture.

Too Much Risk

Unpatched, outdated systems are prime targets for packaged attacks that move at machine speed. Defense requires recovery tools that teams don’t have.

Enabling businesses to be resilient in the modern age requires an approach that’s different than simply deploying a serial console for remote troubleshooting. Gen 1 and 2 serial consoles, which have dominated the market for 20 years, were designed to solve basic issues by offering limited remote access and some automation. The problem is, these still leave teams lacking the confidence to answer questions like:

  • “How can we guarantee access to fix stuff that breaks, without rolling trucks?”
  • “Can we automate change management, without fear of breaking the network?”
  • “Attacks are inevitable — How do we stop hackers from cutting off our access?”

Hyperscalers, Internet Service Providers, Big Tech, and even the military have a resilience model that they’ve proven over the last decade. Their approach involves fully isolating command and control from data and user environments. This allows them to not only gain low-level remote access to maintain and fix systems, but also to “defend the hill” and maintain control if systems are compromised or destroyed.

This approach uses something called Isolated Management Infrastructure (IMI).

Isolated Management Infrastructure is the best practice for network resilience

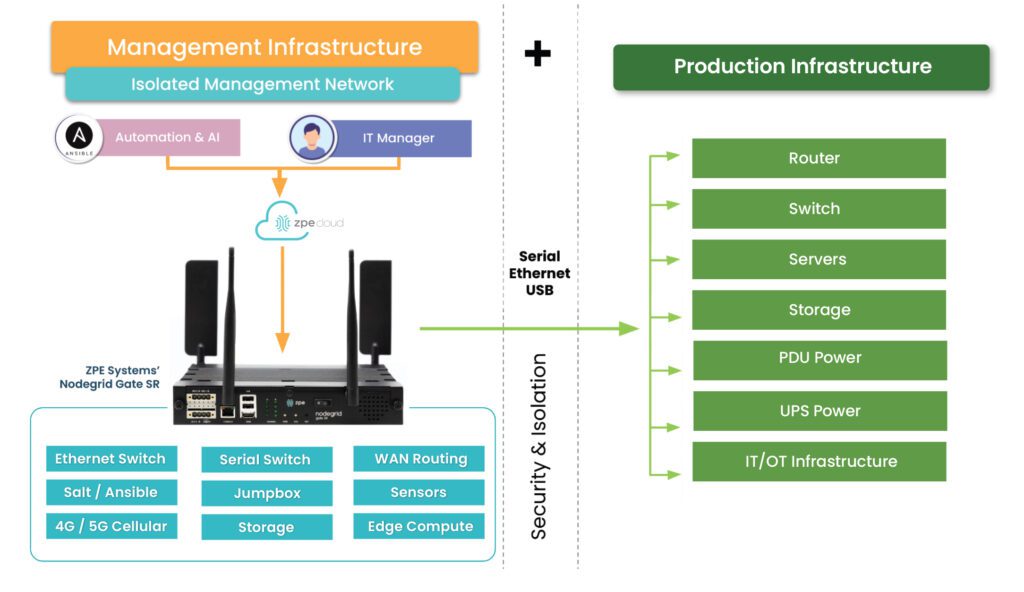
Isolated Management Infrastructure is the practice of creating a management network that is completely separate from the production network. Most IT teams are familiar with out-of-band management as this network; IMI, however, provides many capabilities that can’t be hosted on a traditional serial console or OOB network. And with increasing vulnerabilities, CISA issued a binding directive specifically calling for organizations to implement IMI.

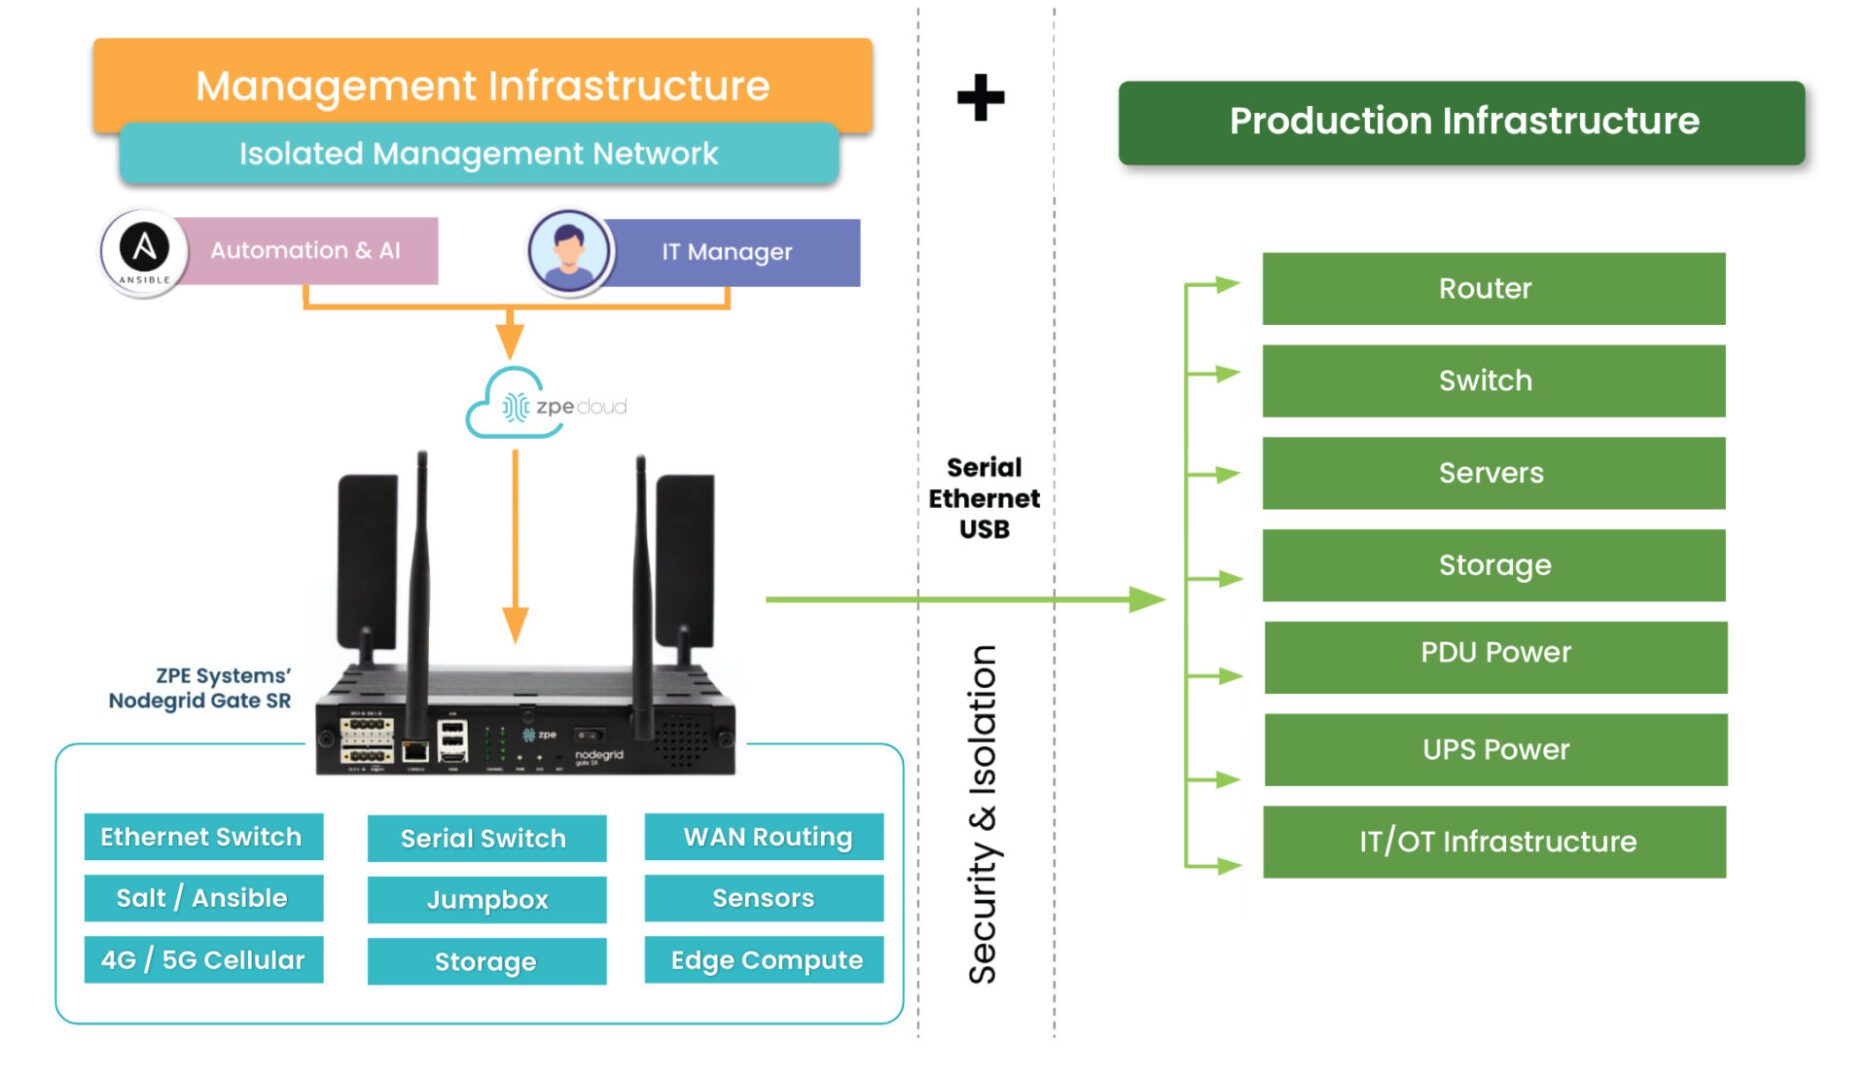
Isolated Management Infrastructure using Gen 3 serial consoles, like ZPE Systems’ Nodegrid devices, provides more than simple remote access and automation. Similar to a proper out-of-band network, IMI is completely isolated from production assets. This means there are no dependencies on production devices or connections, and management interfaces are not exposed to the internet or production gear. In the event of an outage or attack, teams retain management access, and this is just the beginning of the benefits of having IMI.

A network architecture diagram showing Isolated Management Infrastructure next to production infrastructure

IMI includes more than nine functions that are required for teams to fully service their production assets. These include:

  • Low-level access to all management interfaces, including serial, Ethernet, USB, IPMI, and others, to guarantee remote access to the entire environment
  • Open, edge-native automation to ensure services can continue operating in the event of outages or change errors
  • Computing, storage, and jumpbox capabilities that can natively host the apps and tools to deploy an IRE, to ensure fast, effective recovery from attacks

Get the guide to build IMI

ZPE Systems has worked alongside Big Tech to fulfill their requirements for IMI. In doing so, we created the Network Automation blueprint as a technical guide to help any organization build their own Isolated Management Infrastructure. Download the blueprint now to get started.

IT Infrastructure Management Best Practices

A small team uses IT infrastructure management best practices to manage an enterprise network

A single hour of downtime costs organizations more than $300,000 in lost business, making network and service reliability critical to revenue. The biggest challenge facing IT infrastructure teams is ensuring network resilience, which is the ability to continue operating and delivering services during equipment failures, ransomware attacks, and other emergencies. This guide discusses IT infrastructure management best practices for creating and maintaining more resilient enterprise networks.
.

What is IT infrastructure management? It’s a collection of all the workflows involved in deploying and maintaining an organization’s network infrastructure. 

IT infrastructure management best practices

The following IT infrastructure management best practices help improve network resilience while streamlining operations. Click the links on the left for a more detailed look at the technologies and processes involved with each.

Isolated Management Infrastructure (IMI)

• Protects management interfaces in case attackers hack the production network

• Ensures continuous access using OOB (out-of-band) management

• Provides a safe environment to fight through and recover from ransomware

Network and Infrastructure Automation

• Reduces the risk of human error in network configurations and workflows

• Enables faster deployments so new business sites generate revenue sooner

• Accelerates recovery by automating device provisioning and deployment

• Allows small IT infrastructure teams to effectively manage enterprise networks

Vendor-Neutral Platforms

• Reduces technical debt by allowing the use of familiar tools

• Extends OOB, automation, AIOps, etc. to legacy/mixed-vendor infrastructure

• Consolidates network infrastructure to reduce complexity and human error

• Eliminates device sprawl and the need to sacrifice features

AIOps

• Improves security detection to defend against novel attacks

• Provides insights and recommendations to improve network health for a better end-user experience

• Accelerates incident resolution with automatic triaging and root-cause analysis (RCA)

Isolated management infrastructure (IMI)

Management interfaces provide the crucial path to monitoring and controlling critical infrastructure, like servers and switches, as well as crown-jewel digital assets like intellectual property (IP). If management interfaces are exposed to the internet or rely on the production network, attackers can easily hijack your critical infrastructure, access valuable resources, and take down the entire network. This is why CISA released a binding directive that instructs organizations to move management interfaces to a separate network, a practice known as isolated management infrastructure (IMI).

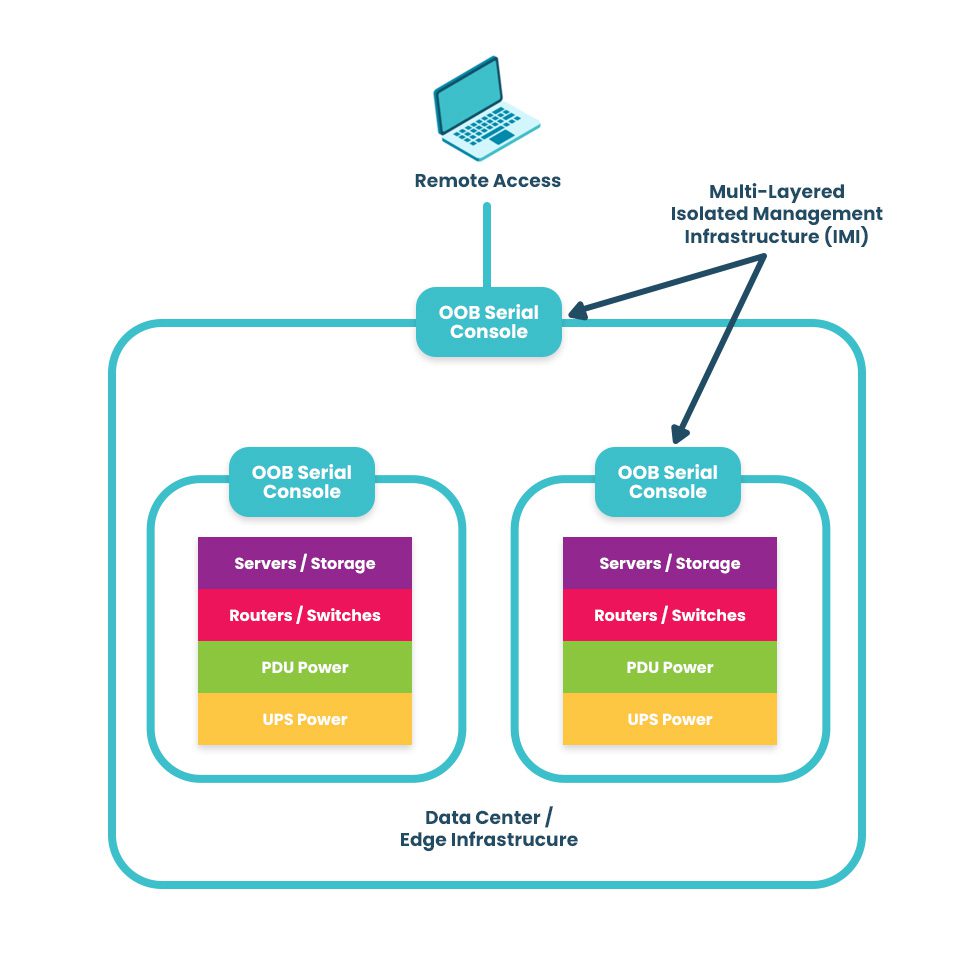
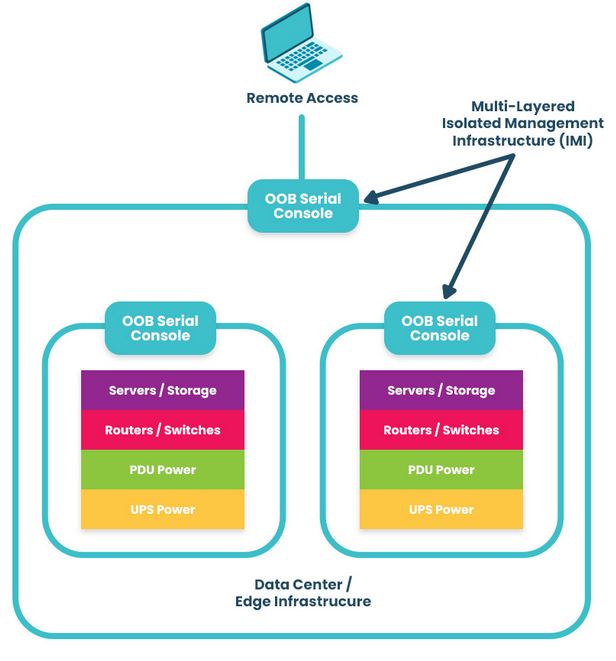
The best practice for building an IMI is to use Gen 3 out-of-band (OOB) serial consoles, which unify the management of all connected devices and ensure continuous remote access via alternative network interfaces (such as 4G/5G cellular). OOB management gives IT teams a lifeline to troubleshoot and recover remote infrastructure during equipment failures and outages on the production network. The key is to ensure that OOB serial consoles are fully isolated from production and can run the applications, tools, and services needed to fight through a ransomware attack or outage without taking critical infrastructure offline for extended periods. This essentially allows you to instantly create a virtual War Room for coordinated recovery efforts to get you back online in a matter of hours instead of days or weeks. A diagram showing a multi-layered isolated management infrastructure. An IMI using out-of-band serial consoles also provides a safe environment to recover from ransomware attacks. The pervasive nature of ransomware and its tendency to re-infect cleaned systems mean it can take companies between 1 and 6 months to fully recover from an attack, with costs and revenue losses mounting with every day of downtime. The best practice is to use OOB serial consoles to create an isolated recovery environment (IRE) where teams can restore and rebuild without risking reinfection.
.

Network and infrastructure automation

As enterprise network architectures grow more complex to support technologies like microservices applications, edge computing, and artificial intelligence, teams find it increasingly difficult to manually monitor and manage all the moving parts. Complexity increases the risk of configuration mistakes, which cause up to 35% of cybersecurity incidents. Network and infrastructure automation handles many tedious, repetitive tasks prone to human error, improving resilience and giving admins more time to focus on revenue-generating projects.

Additionally, automated device provisioning tools like zero-touch provisioning (ZTP) and configuration management tools like RedHat Ansible make it easier for teams to recover critical infrastructure after a failure or attack. Network and infrastructure automation help organizations reduce the duration of outages and allow small IT infrastructure teams to manage large enterprise networks effectively, improving resilience and reducing costs.

For an in-depth look at network and infrastructure automation, read the Best Network Automation Tools and What to Use Them For

Vendor-neutral platforms

Most enterprise networks bring together devices and solutions from many providers, and they often don’t interoperate easily. This box-based approach creates vendor lock-in and technical debt by preventing admins from using the tools or scripting languages they’re familiar with, and it makes a fragmented, complex architecture of management solutions that are difficult to operate efficiently. Organizations also end up compromising on features, ending up with a lot of stuff they don’t need and too little of what they do need.

A vendor-neutral IT infrastructure management platform allows teams to unify all their workflows and solutions. It integrates your administrators’ favorite tools to reduce technical debt and provides a centralized place to deploy, orchestrate, and monitor the entire network. It also extends technologies like OOB, automation, and AIOps to otherwise unsupported legacy and mixed-vendor solutions. Such a platform is revolutionary in the same way smartphones were – instead of needing a separate calculator, watch, pager, phone, etc., everything was combined in a single device. A vendor-neutral management platform allows you to run all the apps, services, and tools you need without buying a bunch of extra hardware. It’s a crucial IT infrastructure management best practice for resilience because it consolidates and unifies network architectures to reduce complexity and prevent human error.

Learn more about the benefits of a vendor-neutral IT infrastructure management platform by reading How To Ensure Network Scalability, Reliability, and Security With a Single Platform

AIOps

AIOps applies artificial intelligence technologies to IT operations to maximize resilience and efficiency. Some AIOps use cases include:

  • Security detection: AIOps security monitoring solutions are better at catching novel attacks (those using methods never encountered or documented before) than traditional, signature-based detection methods that rely on a database of known attack vectors.
  • Data analysis: AIOps can analyze all the gigabytes of logs generated by network infrastructure and provide health visualizations and recommendations for preventing potential issues or optimizing performance.
  • Root-cause analysis (RCA): Ingesting infrastructure logs allows AIOps to identify problems on the network, perform root-cause analysis to determine the source of the issues, and create & prioritize service incidents to accelerate remediation.

AIOps is often thought of as “intelligent automation” because, while most automation follows a predetermined script or playbook of actions, AIOps can make decisions on-the-fly in response to analyzed data. AIOps and automation work together to reduce management complexity and improve network resilience.

Want to find out more about using AIOps and automation to create a more resilient network? Read Using AIOps and Machine Learning To Manage Automated Network Infrastructure

IT infrastructure management best practices for maximum resilience

Network resilience is one of the top IT infrastructure management challenges facing modern enterprises. These IT infrastructure management best practices ensure resilience by isolating management infrastructure from attackers, reducing the risk of human error during configurations and other tedious workflows, breaking vendor lock-in to decrease network complexity, and applying artificial intelligence to the defense and maintenance of critical infrastructure.

Need help getting started with these practices and technologies? ZPE Systems can help simplify IT infrastructure management with the vendor-neutral Nodegrid platform. Nodegrid’s OOB serial consoles and integrated branch routers allow you to build an isolated management infrastructure that supports your choice of third-party solutions for automation, AIOps, and more.

Want to learn how to make IT infrastructure management easier with Nodegrid?

To learn more about implementing IT infrastructure management best practices for resilience with Nodegrid, download our Network Automation Blueprint. 

Request a Demo